
Walsh-hadamard transform


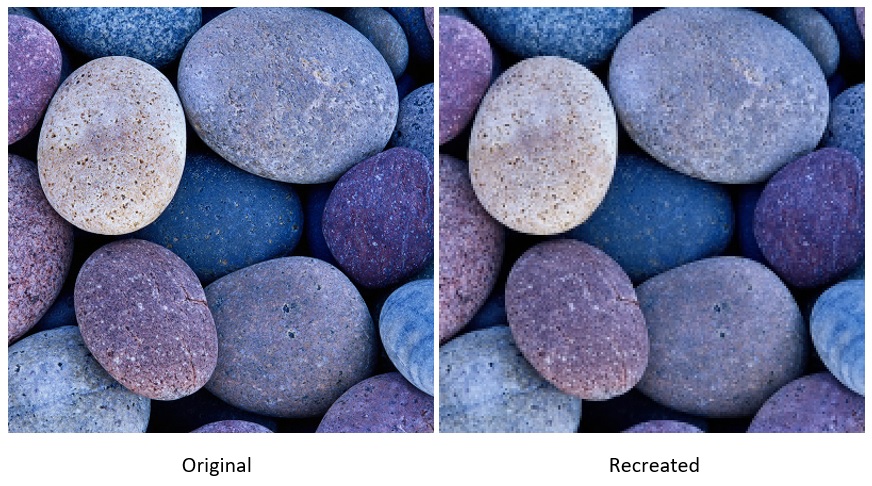
Compressing images with a Hadamard transform
Contents
- Description
- Contributing
- Acknowledgement
- Installation
- How to run
- Requirements
- Development commands
- Releasing
- File formats
Description
From Wikipedia: The Hadamard transform (also known as the Walsh–Hadamard transform, Hadamard–Rademacher–Walsh transform, Walsh transform, or Walsh–Fourier transform) is an example of a generalized class of Fourier transforms. It performs an orthogonal, symmetric, involutive, linear operation on 2m real numbers (or complex numbers, although the Hadamard matrices themselves are purely real).
The Hadamard transform can be regarded as being built out of size-2
discrete Fourier transforms (DFTs), and is in fact equivalent to a
multidimensional DFT of size 2 × 2 × ⋯ × 2 × 2. It decomposes an
arbitrary input vector into a superposition of Walsh functions.
The transform is named for the French mathematician Jacques Hadamard, the German-American mathematician Hans Rademacher, and the American mathematician Joseph L. Walsh.
The Hadamard transform is also used in data encryption, as well as many signal processing
and data compression algorithms, such as JPEG XR and MPEG-4 AVC. In video compression
applications, it is usually used in the form of the sum of absolute transformed differences.
It is also a crucial part of Grover's algorithm and Shor's algorithm in quantum computing.
Contributing
See CONTRIBUTING.md for the development setup, the checks CI runs, and the conventions this codebase follows. Participation is covered by the Code of Conduct.
Acknowledgement
This code is partially based on the solution from ktisha/python2012
Installation
Requires Python 3.10 or newer.
pip install walsh
or, with uv:
uv add walsh          # into a project
uv tool install walsh # just the command line tool
The example script additionally needs matplotlib and Pillow, which are the
demo extra: pip install "walsh[demo]".
Development
uv.lock is committed and CI installs from it with --locked, so a checkout
reproduces exactly the environment CI uses:
uv sync --group dev --all-extras
--group dev brings in pytest, ruff and mypy; --all-extras adds the demo
extra so examples/roundtrip.py runs too. Without uv:
pip install -e ".[demo]" -r requirements-dev.txt
How to run
Command line
walsh compress data/image.bmp data/transformed.cim
walsh extract  data/transformed.cim data/recreated.bmp
The format is taken from the filename suffix, so PPM works the same way, and a picture can be compressed from one format and restored as another:
walsh compress photo.ppm out.cim
walsh extract  out.cim restored.bmp     # PPM in, BMP out
walsh extract  out.cim restored.tif     # or TIFF out
walsh extract  out.cim restored.pam     # or PAM out
walsh extract  out.cim restored.npy     # or a bare NumPy array
walsh extract  out.cim restored.pkl     # or a pickle of rows of (r, g, b) tuples
Pickled pixels go in the same way, and a flat list of them, which does not carry its size, takes it from the command line:
walsh compress array.pkl  out.cim                            # a pickled NumPy array
walsh compress rows.pkl   out.cim                            # [[(r, g, b), ...], ...]
walsh compress pixels.pkl out.cim --width 400 --height 300   # [(r, g, b), ...]
A pickle is read through an allowlist and nothing in it is ever executed; see Pickled pixels.
compress accepts --packed-block-size (how many low-frequency coefficients
per axis to keep -- lower is smaller and lossier), --y-block-size,
--chroma-block-size, --coeff-removal, and --width with --height for
input that cannot say how large it is. Add -v/-vv for progress
logging, and see walsh compress -h for the full list.
Writes are atomic: output goes to a temporary file beside the destination and
replaces it only on success, so a failed run leaves an existing file untouched.
walsh also refuses to write over its own input, since both pipelines read the
whole image before writing and would otherwise replace the original with a
lossy reconstruction of itself.
The .cim container counts each channel's blocks in a 16-bit field, so at the
default 8-pixel luma block an image must be under about 4.2 megapixels. Larger
images are refused with a message naming the block size that would fit them:
--y-block-size 16 roughly quadruples the ceiling, at some cost in detail.
--coeff-removal is the second, independent lossy knob: spectral coefficients
smaller than the given magnitude are zeroed. It does not change the .cim
file's size, because the format stores a fixed count of int16 values whether
or not they are zero, but it makes the result far more compressible. On
data/earth.ppm:
--coeff-removal |
non-zero coefficients | gzipped .cim |
PSNR |
|---|---|---|---|
| (unset) | 48,121 / 60,000 | 59,404 B | 25.07 dB |
| 5 | 29,049 | 45,080 B | 25.06 dB |
| 25 | 14,769 | 27,924 B | 24.71 dB |
| 50 | 8,917 | 19,285 B | 23.85 dB |
That table was measured at the default block sizes, 8 for luma and 16 for
chroma, and the threshold is an absolute magnitude, so its effect depends
on them. The surviving low-frequency coefficients grow with the block edge,
and the same number prunes less at a larger one. The same --coeff-removal 25 on data/earth.ppm, with luma and chroma blocks set equal:
| block edge | non-zero coefficients | zeroed | gzipped .cim |
|---|---|---|---|
| 8 | 88,277 → 18,292 | 79.3% | 94,658 → 32,235 B |
| 16 | 24,060 → 7,041 | 70.7% | 29,190 → 13,105 B |
| 32 | 6,921 → 2,617 | 62.2% | 9,435 → 5,192 B |
| 64 | 2,134 → 1,045 | 51.0% | 3,048 → 2,147 B |
A threshold tuned against the first table and then combined with a larger
--y-block-size has quietly stopped doing most of its work; retune it. Note
also that it thresholds spectral coefficients, never the Hadamard matrix,
whose entries all share one magnitude (0.35 at edge 8): a value at that scale
is a no-op.
Reading the PSNR figures
PSNR is peak signal-to-noise ratio, the standard way to put a number on how much a lossy codec changed an image. It compares the reconstruction against the original pixel by pixel:
PSNR = 10 * log10(255**2 / MSE)
where MSE is the mean squared difference across every channel of every pixel,
and 255 is the largest value an 8-bit channel can hold. It is measured in
decibels, and higher is better: a perfect reconstruction has infinite PSNR,
and every 3 dB gained means the mean squared error was halved.
Because the scale is logarithmic, small-looking differences matter. Going from 23 dB to 25 dB is not an 8% improvement, it is roughly a 37% reduction in error power. Equally, the near-identical 25.07 and 25.06 in the table above mean the first step of coefficient removal cost essentially nothing.
Rough expectations for 8-bit images, though they vary by content:
| PSNR | Typically means |
|---|---|
| above 40 dB | differences invisible without pixel-peeping |
| 30-40 dB | good lossy compression, artefacts hard to spot |
| 25-30 dB | visible softening and blocking |
| below 25 dB | obvious degradation |
The figures here sit around 25 dB because the defaults are aggressive: each
8x8 luma block keeps 16 of its 64 coefficients and each 16x16 chroma block
keeps 16 of 256. Raise --packed-block-size for a gentler setting.
One caveat worth knowing: PSNR measures arithmetic difference, not perceived quality. It is reproducible and easy to compare, which is why it is quoted here, but two images with the same PSNR can look noticeably different — it under- weights structured artefacts like block edges, which the eye picks out readily. Treat it as a consistent yardstick for comparing settings of this codec rather than an absolute measure of how good an image looks.
Exit codes follow the usual convention: 0 on success, 1 when the input
cannot be processed (not a 24-bit BMP, truncated, unreadable), and 2 for a
usage error such as a missing file or an unknown option.
As a library
from walsh import Task

Task().with_action("compress").with_input("data/image.bmp").with_output("out.cim").run()
Task().with_action("extract").with_input("out.cim").with_output("back.bmp").run()
Other transforms
Task takes the block transform as a keyword, so another transform can reuse
the whole pipeline — the colour conversion, the padding, the crop to the
low-frequency corner, the container — with only the transform swapped. Three
ship with the package and are selected by name, in any case:
| Name | Transform | Notes |
|---|---|---|
"walsh" |
Walsh-Hadamard, sequency ordered | The default, and what the .cim format and the walsh command mean. Exact arithmetic: byte-identical output on every platform. |
"dct" |
DCT-II, the transform inside JPEG | Best quality per byte on natural pictures. |
"haar" |
Haar wavelet | Block edges must be powers of two, which Task requires anyway. |
from walsh import Task

Task(transform="dct").with_action("compress").with_input("data/earth.ppm").with_output(
    "dct.cim"
).run()
Task(transform="dct").with_action("extract").with_input("dct.cim").with_output("back.ppm").run()
An unknown name is a ValueError that lists the known ones. "dct" and
"haar" are ordinary floating-point matrix products, accurate to rounding;
only "walsh" carries the bit-exactness guarantee.
The
.cimdoes not record which transform wrote it. A file written with anything but the default must be extracted by aTaskgiven the same transform. Thewalshcommand never takes one, and will decode such a file without complaint into a degraded picture. This keyword is for experiments, not for files you hand to someone else.
examples/compare_transforms.py runs them over the Blue Marble sample. The
byte count depends on the geometry alone, so each row is a like-for-like
comparison of how much picture a transform packs into its first few
coefficients:
| Kept per axis | Bytes | Walsh-Hadamard | DCT-II | Haar | Hartley (custom) |
|---|---|---|---|---|---|
| 2 | 30,026 | 21.59 dB | 22.29 dB | 21.59 dB | 21.17 dB |
| 3 | 67,526 | 23.09 dB | 24.44 dB | 22.85 dB | 22.18 dB |
| 4 | 120,026 | 25.07 dB | 26.45 dB | 25.07 dB | 22.79 dB |
| 6 | 270,026 | 28.88 dB | 31.70 dB | 27.72 dB | 23.51 dB |
| 8 | 480,026 | 42.70 dB | 43.65 dB | 42.70 dB | 39.01 dB |
The DCT wins throughout, which is why JPEG uses it; Walsh-Hadamard needs no multiplications and is exact. Haar ties Walsh-Hadamard wherever the kept size is a power of two, and that is mathematics rather than coincidence: the first 2, 4 or 8 Walsh functions and the first 2, 4 or 8 Haar functions span the same piecewise-constant subspace, so the two projections are the same picture.
Writing your own
The last column of that table is not in the package. Anything that subclasses
Transform can be passed as an instance, and for a separable orthonormal
transform MatrixTransform needs only the matrix:
import numpy as np
from walsh import MatrixTransform, Task


class Hartley(MatrixTransform):
    """cas(2*pi*i*k/n) / sqrt(n), with cas = cos + sin."""

    def matrix(self, size):
        angle = 2 * np.pi * np.outer(np.arange(size), np.arange(size)) / size
        return (np.cos(angle) + np.sin(angle)) / np.sqrt(size)


Task(transform=Hartley()).with_action("compress").with_input("data/earth.ppm").with_output(
    "hartley.cim"
).run()
It trails the others for an instructive reason: the codec keeps the top-left
corner of each spectrum, which assumes rows rise in frequency, and a Hartley
matrix puts half of its low frequencies in its last rows. A transform that
is not a matrix product subclasses Transform directly and implements
transform and inverse_transform for one square block; Task calls
transform_stack and inverse_transform_stack, whose defaults loop over the
blocks, so override those when a whole (count, edge, edge) stack can go
through in one operation. with_coeff_removal is applied by the task, so it
works for any transform.
Examples
examples/roundtrip.py compresses the sample image, restores it, and plots
both images with their histograms side by side (needs the demo extra):
python examples/roundtrip.py
examples/compare_transforms.py prints the table above for any image, and
needs numpy only:
python examples/compare_transforms.py [image]
Requirements
The package needs numpy and click -- BMP parsing is done by hand with
struct, and click powers the command line interface. matplotlib and
Pillow are needed only by the example script, and are declared as the demo
extra. Versions are pinned in pyproject.toml;
requirements.txt, requirements-demo.txt and requirements-dev.txt mirror
them for plain pip install -r workflows, and tests/project/test_requirements_mirror.py
fails if the two ever disagree. On pip 25.1 or newer,
pip install -e ".[demo]" --group dev reads the same groups straight from
pyproject.toml and needs no mirror at all.
Development commands
uv run pytest                          # test suite
uv run pytest --cov --cov-report=term-missing   # with coverage
uv run ruff check .                    # lint
uv run ruff format .                   # format
uv run mypy                            # strict type check
uv build                               # sdist + wheel into dist/
CI runs exactly these on every pull request, plus the test suite against Python 3.10 through 3.14.
Coverage
Coverage is measured with branch coverage on, and CI enforces a floor of 90%
on every supported Python version. A pull request that drops below it fails
the test jobs, which are required checks on master — so the badge above
states what is actually guaranteed rather than a number that could drift.
Coverage is opt-in locally (--cov) so a plain pytest stays fast; CI always
passes it.
Releasing
The version in pyproject.toml is the single source of truth. To cut a
release, bump it, add the matching ## [x.y.z] section to CHANGELOG.md, and
merge to master. The release workflow then tags v<version>, creates a
GitHub Release with those notes, and publishes the sdist and wheel to
PyPI using Trusted Publishing — no API token
is stored in this repository.
Merges that do not change the version are a no-op, since PyPI permanently refuses to accept the same version twice.
File formats
Input and output
| Suffix | Format | Notes |
|---|---|---|
.bmp |
Windows bitmap | 24-bit, single plane, uncompressed. Top-down (negative height) files are understood. |
.ppm, .pnm |
Netpbm portable pixmap | P6 binary and P3 ASCII are read; P6 is written. Header comments are skipped and a maxval below 255 is rescaled. 16-bit samples are rejected. |
.npy |
NumPy array | The raw pixel matrix in NumPy's own container, for images that already live in an array. Read: uint8 of shape (height, width, 3) as RGB, (height, width) or (height, width, 1) as greyscale, and (height, width, 4) as RGBA only when fully opaque. Other dtypes, other channel counts, transparency and CMYK are rejected by name; pickled files are refused from the header and never loaded. Written as (height, width, 3) uint8, so numpy.load reads it back as is. Channel order is RGB; a BGR array, as OpenCV produces, is array[..., ::-1]. |
.pkl, .pickle |
Pickled pixels | A pickled NumPy array, rows of (r, g, b) pixels, or a flat list of them with a declared size. Read through an allowlist, so nothing in the file is ever executed; rows of (r, g, b) tuples are written. See Pickled pixels. |
.pam |
Netpbm portable arbitrary map | P7 with DEPTH 3, TUPLTYPE RGB (or none) and MAXVAL up to 255 is read and written; a lower maxval is rescaled. Header keys may come in any order, comment and blank lines are skipped. Greyscale, alpha, other tuple types and 16-bit samples are rejected by name. The writer's output is byte-identical to Netpbm's own pamtopam. |
.tif, .tiff |
Uncompressed baseline TIFF | Both byte orders and multi-strip files are read; little-endian single-strip is written. Only the uncompressed RGB 8-bit chunky profile is supported -- LZW, palette, CMYK, greyscale, 16-bit, planar and rotated files are rejected by name. |
Every reader presents the same in-memory view -- RGB pixels, top row first --
whatever the file itself stores. BMP is the awkward one on both counts, storing
blue-green-red samples in bottom-up rows, and BMPImage converts in each
direction. That shared contract is what makes cross-format conversion work.
Pickled pixels
pickle.load and numpy.load(allow_pickle=True) run the program a pickle
contains, with the power to import any module and call anything in it, so
opening an untrusted pickle is running untrusted code. This package never
does that. It reads the same files through an allowlist: lists, tuples, dicts,
numbers and bytes need no lookups at all, and the only names a file may refer
to are the handful NumPy's own pickles use to rebuild an array. Anything else
is refused by name before it is called:
$ walsh compress evil.pkl out.cim
Error: unsupported pickle: it refers to posix.system; only lists, tuples, integers and NumPy arrays are read, and nothing in a pickle is ever executed
What a .pkl or .pickle may hold:
| Content | Size comes from | Notes |
|---|---|---|
| A NumPy array | its shape | The .npy rules: uint8; (h, w, 3) RGB, (h, w) or (h, w, 1) greyscale, (h, w, 4) RGBA only when fully opaque. Every pickle protocol, and pickles written under NumPy 1 and NumPy 2 alike, whichever is installed. |
Rows of pixels, [[(r, g, b), ...], ...] |
its structure | |
{"width": w, "height": h, "pixels": [...]} |
the dict | Around a flat list, or around anything above, which must then agree. |
A flat list of pixels, [(r, g, b), ...] |
--width and --height, or Task.with_input_size(w, h) |
Top row first. It does not say how wide the picture is and nothing here guesses: 160,000 pixels could be 400x400 or 200x800. |
Lists and tuples are interchangeable at every level. Samples must be integers in 0-255, Python's or NumPy's; floats, booleans, out-of-range values and ragged rows are refused by name. A declared size is never silently dropped: input that carries its own size, in any format, must match it.
from walsh import Task

Task().with_input_size(400, 300).with_action("compress").with_input("pixels.pkl").with_output(
    "out.cim"
).run()
An object array saved by numpy.save, which only
numpy.load(allow_pickle=True) opens, is a pickle inside a .npy and is read
the same way. The writer produces rows of (r, g, b) tuples of plain int at
protocol 4: any Python loads that without NumPy, and its bytes do not depend on
which NumPy wrote it.
The .cim container
compress writes a .cim file: an atypical, project-specific container, so
most commercial tools will not be able to read it. It stores the image
dimensions, three block-layout descriptions (Y, Cb, Cr), and the retained
Walsh-Hadamard coefficients as little-endian int16.
Note.
.cimfiles written by 0.1.x are not compatible with 0.2.0. The in-memory pixel contract changed, so an old file extracted with 0.2.0 comes back with red and blue swapped and vertically flipped. Re-compress from the source image instead.
1 maintainer

Release files for walsh 0.4.16
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| walsh-0.4.16.tar.gz | 156.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| walsh-0.4.16-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 235.7 kB
Release files / walsh-0.4.16.tar.gz
| Download URL | walsh-0.4.16.tar.gz |
|---|---|
| Size | 156.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e4722b9d8e6844ef604cb44be16b70b21f686d95d496b36f96f0d8763bfc10e6
|
|
BLAKE2b-256 checksum How to use checksums |
6188157e6f38853af24183d1f26121d1016aa02769a253eab69dc0bf21901120
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 17, 2026.
Transparency logRelease files / walsh-0.4.16-py3-none-any.whl
| Download URL | walsh-0.4.16-py3-none-any.whl |
|---|---|
| Size | 78.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
403cd6426491dba89de2b9e43b97440b610f421fc2c93f167dcd1268b0c248b4
|
|
BLAKE2b-256 checksum How to use checksums |
e43f8f3bccaaa229d67a418bd5884028fb4f304136025452f1623fca310c41f9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 17, 2026.
Transparency log













