
This release is a pre-release and may not be stable for production use.
High performance client for Baseten.co
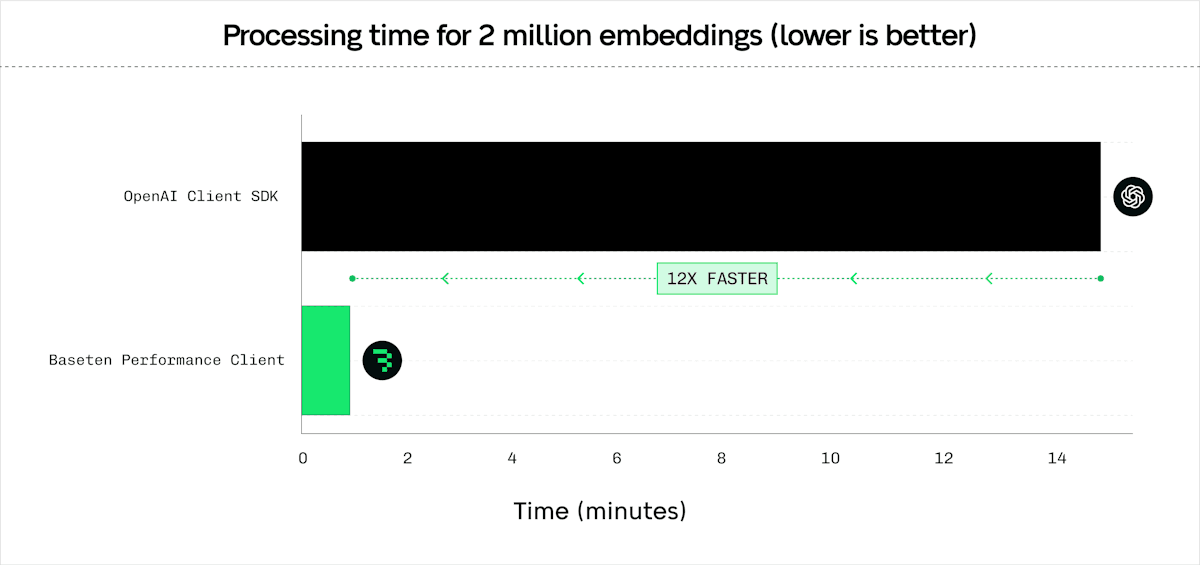
This library provides a high-performance Python client for Baseten.co endpoints including embeddings, reranking, and classification. It was built for massive concurrent post requests to any URL, also outside of baseten.co. PerformanceClient releases the GIL while performing requests in the Rust, and supports simultaneous sync and async usage. It was benchmarked with >1200 rps per client in our blog. PerformanceClient is built on top of pyo3, reqwest and tokio and is MIT licensed.
Installation
pip install baseten_performance_client
Usage
import os
import asyncio
from baseten_performance_client import PerformanceClient, OpenAIEmbeddingsResponse, RerankResponse, ClassificationResponse

api_key = os.environ.get("BASETEN_API_KEY")
base_url_embed = "https://model-yqv4yjjq.api.baseten.co/environments/production/sync"
# Also works with OpenAI or Mixedbread.
# base_url_embed = "https://api.openai.com" or "https://api.mixedbread.com"

# Basic client setup
client = PerformanceClient(base_url=base_url_embed, api_key=api_key)

# Advanced setup with HTTP version selection and connection pooling
from baseten_performance_client import HttpClientWrapper
http_wrapper = HttpClientWrapper(http_version=1)  # HTTP/1.1 (default)
advanced_client = PerformanceClient(
    base_url=base_url_embed,
    api_key=api_key,
    http_version=1,  # HTTP/1.1
    client_wrapper=http_wrapper  # Share connection pool
)
Embeddings
Synchronous Embedding
from baseten_performance_client import RequestProcessingPreference

texts = ["Hello world", "Example text", "Another sample"]
preference = RequestProcessingPreference(
    batch_size=16,
    max_concurrent_requests=32,
    timeout_s=360,
    max_chars_per_request=256000,  # Character limit per request
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360  # Total operation timeout
)
response = client.embed(
    input=texts,
    model="my_model",
    preference=preference
)

# Accessing embedding data
print(f"Model used: {response.model}")
print(f"Total tokens used: {response.usage.total_tokens}")
print(f"Total time: {response.total_time:.4f}s")
if response.individual_batch_request_times:
    for i, batch_time in enumerate(response.individual_batch_request_times):
        print(f"  Time for batch {i}: {batch_time:.4f}s")

for i, embedding_data in enumerate(response.data):
    print(f"Embedding for text {i} (original input index {embedding_data.index}):")
    # embedding_data.embedding can be List[float] or str (base64)
    if isinstance(embedding_data.embedding, list):
        print(f"  First 3 dimensions: {embedding_data.embedding[:3]}")
        print(f"  Length: {len(embedding_data.embedding)}")

# Using the numpy() method (requires numpy to be installed)
import numpy as np
numpy_array = response.numpy()
print("\nEmbeddings as NumPy array:")
print(f"  Shape: {numpy_array.shape}")
print(f"  Data type: {numpy_array.dtype}")
if numpy_array.shape[0] > 0:
    print(f"  First 3 dimensions of the first embedding: {numpy_array[0][:3]}")
Note: The embed method is versatile and can be used with any embeddings service, e.g. OpenAI API embeddings, not just for Baseten deployments.
Asynchronous Embedding
async def async_embed():
    from baseten_performance_client import RequestProcessingPreference

    texts = ["Async hello", "Async example"]
    preference = RequestProcessingPreference(
        batch_size=16,
        max_concurrent_requests=32,
        timeout_s=360,
        max_chars_per_request=256000,  # Character limit per request
        hedge_delay=0.5,  # Enable hedging with 0.5s delay
        total_timeout_s=360  # Total operation timeout
    )
    response = await client.async_embed(
        input=texts,
        model="my_model",
        preference=preference
    )
    print("Async embedding response:", response.data)

# To run:
# asyncio.run(async_embed())
Embedding Benchmarks
Comparison against pip install openai for /v1/embeddings. Tested with the ./scripts/compare_latency_openai.py with mini_batch_size of 128, and 4 server-side replicas. Results with OpenAI similar, OpenAI allows a max mini_batch_size of 2048.
| Number of inputs / embeddings | Number of Tasks | PerformanceClient (s) | AsyncOpenAI (s) | Speedup |
|---|---|---|---|---|
| 128 | 1 | 0.12 | 0.13 | 1.08× |
| 512 | 4 | 0.14 | 0.21 | 1.50× |
| 8 192 | 64 | 0.83 | 1.95 | 2.35× |
| 131 072 | 1 024 | 4.63 | 39.07 | 8.44× |
| 2 097 152 | 16 384 | 70.92 | 903.68 | 12.74× |
General Batch POST
The batch_post method is generic. It can be used to send POST requests to any URL, not limited to Baseten endpoints. The input and output can be any JSON item.
Synchronous Batch POST
from baseten_performance_client import RequestProcessingPreference

payload1 = {"model": "my_model", "input": ["Batch request sample 1"]}
payload2 = {"model": "my_model", "input": ["Batch request sample 2"]}
preference = RequestProcessingPreference(
    max_concurrent_requests=32,
    timeout_s=360,
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360,  # Total operation timeout
    extra_headers={"x-custom-header": "value"}  # Custom headers
)
response_obj = client.batch_post(
    url_path="/v1/embeddings", # Example path, adjust to your needs
    payloads=[payload1, payload2],
    preference=preference
)
print(f"Total time for batch POST: {response_obj.total_time:.4f}s")
for i, (resp_data, headers, time_taken) in enumerate(zip(response_obj.data, response_obj.response_headers, response_obj.individual_request_times)):
    print(f"Response {i+1}:")
    print(f"  Data: {resp_data}")
    print(f"  Headers: {headers}")
    print(f"  Time taken: {time_taken:.4f}s")
Asynchronous Batch POST
async def async_batch_post_example():
    from baseten_performance_client import RequestProcessingPreference

    payload1 = {"model": "my_model", "input": ["Async batch sample 1"]}
    payload2 = {"model": "my_model", "input": ["Async batch sample 2"]}
preference = RequestProcessingPreference(
    max_concurrent_requests=32,
    timeout_s=360,
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360,  # Total operation timeout
    extra_headers={"x-custom-header": "value"}  # Custom headers
)
    response_obj = await client.async_batch_post(
        url_path="/v1/embeddings",
        payloads=[payload1, payload2],
        preference=preference
    )
    print(f"Async total time for batch POST: {response_obj.total_time:.4f}s")
    for i, (resp_data, headers, time_taken) in enumerate(zip(response_obj.data, response_obj.response_headers, response_obj.individual_request_times)):
        print(f"Async Response {i+1}:")
        print(f"  Data: {resp_data}")
        print(f"  Headers: {headers}")
        print(f"  Time taken: {time_taken:.4f}s")

# To run:
# asyncio.run(async_batch_post_example())
Reranking
Reranking compatible with BEI or text-embeddings-inference.
Synchronous Reranking
from baseten_performance_client import RequestProcessingPreference

query = "What is the best framework?"
documents = ["Doc 1 text", "Doc 2 text", "Doc 3 text"]
preference = RequestProcessingPreference(
    batch_size=16,
    max_concurrent_requests=32,
    timeout_s=360,
    max_chars_per_request=256000,  # Character limit per request
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360  # Total operation timeout
)
rerank_response = client.rerank(
    query=query,
    texts=documents,
    model="rerank-model",  # Optional model specification
    return_text=True,
    preference=preference
)
for res in rerank_response.data:
    print(f"Index: {res.index} Score: {res.score}")
Asynchronous Reranking
async def async_rerank():
    from baseten_performance_client import RequestProcessingPreference

    query = "Async query sample"
    docs = ["Async doc1", "Async doc2"]
    preference = RequestProcessingPreference(
        batch_size=16,
        max_concurrent_requests=32,
        timeout_s=360,
        max_chars_per_request=256000,  # Character limit per request
        hedge_delay=0.5,  # Enable hedging with 0.5s delay
        total_timeout_s=360  # Total operation timeout
    )
    response = await client.async_rerank(
        query=query,
        texts=docs,
        model="rerank-model",  # Optional model specification
        return_text=True,
        preference=preference
    )
    for res in response.data:
        print(f"Async Index: {res.index} Score: {res.score}")

# To run:
# asyncio.run(async_rerank())
Classification
Predict (classification endpoint) compatible with BEI or text-embeddings-inference.
Synchronous Classification
from baseten_performance_client import RequestProcessingPreference

texts_to_classify = [
    "This is great!",
    "I did not like it.",
    "Neutral experience."
]
preference = RequestProcessingPreference(
    batch_size=16,
    max_concurrent_requests=32,
    timeout_s=360,
    max_chars_per_request=256000,  # Character limit per request
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360  # Total operation timeout
)
classify_response = client.classify(
    inputs=texts_to_classify,
    model="classification-model",  # Optional model specification
    preference=preference
)
for group in classify_response.data:
    for result in group:
        print(f"Label: {result.label}, Score: {result.score}")
Asynchronous Classification
async def async_classify():
    from baseten_performance_client import RequestProcessingPreference

    texts = ["Async positive", "Async negative"]
    preference = RequestProcessingPreference(
        batch_size=16,
        max_concurrent_requests=32,
        timeout_s=360,
        max_chars_per_request=256000,  # Character limit per request
        hedge_delay=0.5,  # Enable hedging with 0.5s delay
        total_timeout_s=360  # Total operation timeout
    )
    response = await client.async_classify(
        inputs=texts,
        model="classification-model",  # Optional model specification
        preference=preference
    )
    for group in response.data:
        for res in group:
            print(f"Async Label: {res.label}, Score: {res.score}")

# To run:
# asyncio.run(async_classify())
Advanced Features
RequestProcessingPreference
The RequestProcessingPreference class provides a unified way to configure all request processing parameters. This is the recommended approach for advanced configuration as it provides better type safety and clearer intent.
The framework defaults are 256 concurrent requests, a batch size of 8, and 8,000 characters per request. max_chars_per_request accepts values from 50 through 1,048,576.
from baseten_performance_client import RequestProcessingPreference

# Create a preference with custom settings
preference = RequestProcessingPreference(
    max_concurrent_requests=64,        # Parallel requests (default: 256)
    batch_size=32,                     # Items per batch (default: 8)
    timeout_s=30.0,                   # Per-request timeout (default: 3600.0)
    hedge_delay=0.5,                  # Hedging delay (default: None)
    hedge_budget_pct=0.15,            # Hedge budget percentage (default: 0.10)
    retry_budget_pct=0.08,            # Retry budget percentage (default: 0.05)
    max_retries=5,                    # Maximum HTTP retries (default: 5)
    initial_backoff_ms=250,           # Initial backoff in milliseconds (default: 125)
    total_timeout_s=300.0              # Total operation timeout (default: None)
)

# Use with any method
response = client.embed(
    input=["text1", "text2"],
    model="my_model",
    preference=preference
)

# Also works with async methods
response = await client.async_embed(
    input=["text1", "text2"],
    model="my_model",
    preference=preference
)
Property-based Configuration: You can also modify preferences after creation using property setters:
# Create preference and modify properties
preference = RequestProcessingPreference()
preference.max_concurrent_requests = 64        # Set parallel requests
preference.batch_size = 32                     # Set batch size
preference.timeout_s = 30.0                    # Set timeout
preference.hedge_delay = 0.5                   # Enable hedging
preference.hedge_budget_pct = 0.15            # Set hedge budget
preference.retry_budget_pct = 0.08            # Set retry budget
preference.max_retries = 3                     # Set max retries
preference.initial_backoff_ms = 250            # Set backoff

# Use with any method
response = client.embed(
    input=["text1", "text2"],
    model="my_model",
    preference=preference
)
Budget Percentages:
hedge_budget_pct: Percentage of total requests allocated for hedging (default: 10%)retry_budget_pct: Percentage of total requests allocated for retries (default: 5%)- Maximum allowed: 300% for both budgets
Retry Configuration:
- HTTP status-code retries are controlled by
max_retries, not byretry_budget_pct. - Retryable status codes by default:
408,409,429, and500through599. - Use
non_retryable_status_codes={529}to opt specific statuses out of the default retry policy. max_retries: Maximum HTTP status-code retries per request (default: 5, max: 6). Set to 0 to disable these retries.retry_budget_pct: Budget for timeout and network-error retry paths (default: 5%, max: 300%).initial_backoff_ms: Initial backoff duration in milliseconds (default: 125, range: 50-45000).- Backoff multiplies by 4 after each retry, caps at 45000ms, and adds 0-99ms jitter. With defaults, the retry sleeps are about 125ms, 500ms, 2000ms, 8000ms, and 32000ms; a sixth retry sleeps about 45000ms.
Request Hedging
The client supports request hedging for improved latency by sending duplicate requests after a specified delay:
# Enable hedging with 0.5 second delay
preference = RequestProcessingPreference(
    hedge_delay=0.5,  # Send hedge request after 0.5s
    max_chars_per_request=256000,
    total_timeout_s=360
)
response = client.embed(
    input=texts,
    model="my_model",
    preference=preference
)
Custom Headers
Use custom headers with batch_post:
preference = RequestProcessingPreference(
    extra_headers={
        "x-custom-header": "value",
        "authorization": "Bearer token"
    }
)
response = client.batch_post(
    url_path="/v1/embeddings",
    payloads=payloads,
    preference=preference
)
HTTP Version Selection
Choose between HTTP/1.1 and HTTP/2:
# HTTP/1.1 (default, better for high concurrency)
client_http1 = PerformanceClient(base_url, api_key, http_version=1)

# HTTP/2 (better for single requests)
client_http2 = PerformanceClient(base_url, api_key, http_version=2)
Connection Pooling
Share connection pools across multiple clients:
from baseten_performance_client import HttpClientWrapper

# Create shared wrapper
wrapper = HttpClientWrapper(http_version=1)

# Reuse across multiple clients
client1 = PerformanceClient(base_url="https://api1.example.com", client_wrapper=wrapper)
client2 = PerformanceClient(base_url="https://api2.example.com", client_wrapper=wrapper)
HTTP Proxy Support
Route all HTTP requests through a proxy (e.g., for connection pooling with Envoy):
from baseten_performance_client import HttpClientWrapper

# Create wrapper with HTTP proxy
wrapper = HttpClientWrapper(
    http_version=1,
    proxy="http://envoy-proxy.local:8080"
)

# Share the wrapper across multiple clients
client1 = PerformanceClient(
    base_url="https://api1.example.com",
    api_key="your_key",
    client_wrapper=wrapper
)
client2 = PerformanceClient(
    base_url="https://api2.example.com",
    api_key="your_key",
    client_wrapper=wrapper
)
# Both clients will use the same connection pool and proxy
You can also specify the proxy directly when creating a client:
client = PerformanceClient(
    base_url="https://api.example.com",
    api_key="your_key",
    proxy="http://envoy-proxy.local:8080"
)
Endpoint Pool and Health Checks
Route traffic across reusable endpoints with deterministic weighted routing. Each Endpoint
owns its own health worker, so the same endpoint object can be shared across many pools
without duplicate probes:
from baseten_performance_client import Endpoint, EndpointPool, HttpClientWrapper, PerformanceClient

health_wrapper = HttpClientWrapper(http_version=1)
endpoint_a = Endpoint(
    base_url="https://model-AAAA.api.baseten.co/environments/production/sync",
    api_key="your_key",
    client_wrapper=health_wrapper,
    deployment_health_path="/health",
    deployment_timeout_is_no_vote=False,
)
endpoint_b = Endpoint(
    base_url="https://model-BBBB.api.baseten.co/environments/production/sync",
    api_key="your_key",
    client_wrapper=health_wrapper,
    deployment_health_path="/health",
    deployment_timeout_is_no_vote=False,
)

endpoint_pool = EndpointPool(
    endpoints=[endpoint_a, endpoint_b],
    endpoint_weights=[0.8, 0.2],  # deterministic weighted routing
)

client = PerformanceClient(
    base_url="https://model-AAAA.api.baseten.co/environments/production/sync",
    api_key="your_key",
    endpoint_pool=endpoint_pool,
)
Health semantics:
- Weights are deterministic weighted routing, not weighted round robin.
- Each configured health check is retried up to
health_check_retries, and one successful retry is enough for that check. - If an endpoint has
deep_health_urlconfigured, both the shallow deployment health path and the deep health URL are evaluated. health_fail_on_first=Trueshort-circuits on the first hard failing check within an endpoint refresh cycle.
Error Handling
The client can raise several types of errors. Here's how to handle common ones:
requests.exceptions.HTTPError: This error is raised for HTTP issues, such as authentication failures (e.g., 403 Forbidden if the API key is wrong), server errors (e.g., 5xx), or if the endpoint is not found (404). You can inspecte.response.status_codeande.response.text(ore.response.json()if the body is JSON) for more details.ValueError: This error can occur due to invalid input parameters (e.g., an emptyinputlist forembed, invalidbatch_sizeormax_concurrent_requestsvalues). It can also be raised byresponse.numpy()if embeddings are not float vectors or have inconsistent dimensions.
Here's an example demonstrating how to catch these errors for the embed method:
import requests
from baseten_performance_client import RequestProcessingPreference

# client = PerformanceClient(base_url="your_baseten_url", api_key="your_baseten_api_key")

texts_to_embed = ["Hello world", "Another text example"]
try:
    preference = RequestProcessingPreference(
        batch_size=2,
        max_concurrent_requests=4,
        timeout_s=60 # Timeout in seconds
    )
    response = client.embed(
        input=texts_to_embed,
        model="your_embedding_model", # Replace with your actual model name
        preference=preference
    )
    # Process successful response
    print(f"Model used: {response.model}")
    print(f"Total tokens: {response.usage.total_tokens}")
    for item in response.data:
        embedding_preview = item.embedding[:3] if isinstance(item.embedding, list) else "Base64 Data"
        print(f"Index {item.index}, Embedding (first 3 dims or type): {embedding_preview}")

except requests.exceptions.HTTPError as e:
    print(f"An HTTP error occurred: {e}, code {e.args[0]}")
For asynchronous methods (async_embed, async_rerank, async_classify, async_batch_post), the same exceptions will be raised by the await call and can be caught using a try...except block within an async def function.
Development
# Install prerequisites
sudo apt-get install patchelf
# Install cargo if not already installed.

# Set up a Python virtual environment
python -m venv .venv
source .venv/bin/activate

# Install development dependencies
pip install maturin[patchelf] pytest requests numpy

# Build and install the Rust extension in development mode
maturin develop
cargo fmt
# Run tests
pytest tests
Contributions
Feel free to contribute to this repo, tag @michaelfeil for review.
License
MIT License
3 maintainers


Release files for baseten-performance-client 0.1.15rc1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| baseten_performance_client-0.1.15rc1.tar.gz | 119.4 kB | Details |
Built distributions (wheels)
Total release size: 118.0 MB
Release files / baseten_performance_client-0.1.15rc1.tar.gz
| Download URL | baseten_performance_client-0.1.15rc1.tar.gz |
|---|---|
| Size | 119.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
320e8e617ceefc30c8093b6ca444622a7835fb78206071e87ec0ffe0c9ddb371
|
|
BLAKE2b-256 checksum How to use checksums |
88633ca2e55f275fea6b58fe8564ec519f7ed7c21a6cfb974c0742339b230f65
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_x86_64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_x86_64.whl |
|---|---|
| Size | 6.3 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ x86-64 |
|
SHA-256 checksum How to use checksums |
e987db20f8eb43d385e1fb1b18ca3247217437dafa8ac9bb06e3190bdfe952ff
|
|
BLAKE2b-256 checksum How to use checksums |
14e86722ec781ec07616e3837b107e37c0c69625e16527413765062e660648f5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_i686.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_i686.whl |
|---|---|
| Size | 6.1 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ x86-32 |
|
SHA-256 checksum How to use checksums |
9e4c421f9302357667ed23e57c40640a0cbae6ead5832e373a6cb9ccf6ff1a8d
|
|
BLAKE2b-256 checksum How to use checksums |
eab99a220ed7e3fc86e1bb8b3c66398293e75ce8acb087e469f84a41c3c2b9e1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_armv7l.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_armv7l.whl |
|---|---|
| Size | 5.6 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ ARMv7l |
|
SHA-256 checksum How to use checksums |
93ff3e93e2499d4aee787d84853aff5b15bc7c3dddd424904dca3334c48b2dfc
|
|
BLAKE2b-256 checksum How to use checksums |
b0873de34a5a443193e2baa356f3b4358d71e99d02c813e3035e0dfc89f9316b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_aarch64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-musllinux_1_2_aarch64.whl |
|---|---|
| Size | 6.6 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ ARM64 |
|
SHA-256 checksum How to use checksums |
2ad303683c8c472ffaceef3d68ad7f2814c83316b15c504d94b3c976ad6de04c
|
|
BLAKE2b-256 checksum How to use checksums |
f231c6c86ecaa38175dc73ae2f3c8706cb52c69c227b69c2bb85182af7d91919
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 5.9 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
26dc6de1e4285a9b71fa37cf8045a3163d92c2c28496b768cba0a9ad3b9270ac
|
|
BLAKE2b-256 checksum How to use checksums |
3d7b5e69dc0681255cbd1843f406e99a5b8d7c5e8e1c8dfa6865ddc5a1e65079
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl |
|---|---|
| Size | 6.6 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux glibc 2.17+ PowerPC 64-le |
|
SHA-256 checksum How to use checksums |
31573bfcc42d757c95e8a9030e37c8a57cf340d74e9ba21a610120bbeed79a97
|
|
BLAKE2b-256 checksum How to use checksums |
c1b6fe23983df12ac17cfcd5563856a9753920df9e92c38a4f4db7879795eff4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-manylinux_2_17_i686.manylinux2014_i686.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-manylinux_2_17_i686.manylinux2014_i686.whl |
|---|---|
| Size | 6.1 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux glibc 2.17+ x86-32 |
|
SHA-256 checksum How to use checksums |
dd036703c6f0fcb24ed0db81b4761116f0c544c8c6a06aa5e3e00f203fc9f42a
|
|
BLAKE2b-256 checksum How to use checksums |
ae5677bf729e04cb4008c98c56ba9e13f1da172174cdcd50141145cdbbb338c7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-macosx_11_0_arm64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-macosx_11_0_arm64.whl |
|---|---|
| Size | 3.5 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
94877b21a2fd5d88124374f2c1dd34ea28d8400a8d2abc554015cabea4e985ef
|
|
BLAKE2b-256 checksum How to use checksums |
ba9ba74cf37e8e1a97fc26c87934647b344749cd419ebd719a52a8b9438f684f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp313-cp313t-macosx_10_12_x86_64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp313-cp313t-macosx_10_12_x86_64.whl |
|---|---|
| Size | 3.6 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
17ce7f66d4ab5abcd12daa27cf88d265b496538b547149a0991ec9e60d647247
|
|
BLAKE2b-256 checksum How to use checksums |
e50eec9355770002aa2fd81df89aa4aaf8e1268b543430bbe82ce7cd828ed53b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-win_amd64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-win_amd64.whl |
|---|---|
| Size | 3.5 MB |
| Tags | CPython 3.8 Windows x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
eb024698bdc25c68dd6b2adb07763da2dd319c82d7b0ae2872fc37a6da15edd0
|
|
BLAKE2b-256 checksum How to use checksums |
20bf89099207dd05ade18702e4e2cedb263c5b6c8078673e354cdb5f5cbeaa75
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_x86_64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_x86_64.whl |
|---|---|
| Size | 6.5 MB |
| Tags | CPython 3.8 Linux musl 1.2+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
f549dbb3afb46bf31f667b0c909f122ccfa1e6fc6b9fdc20de2a8f261f6429af
|
|
BLAKE2b-256 checksum How to use checksums |
8e2bd2b4bc2ef25c89c59ee0ddec6c3956dfa47a9737d393778c129d995ef3da
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_i686.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_i686.whl |
|---|---|
| Size | 6.3 MB |
| Tags | CPython 3.8 Linux musl 1.2+ x86-32 abi3 |
|
SHA-256 checksum How to use checksums |
3712e6756f1c00bdb01b5d40e200c44c82da8623ee01b3caac457f1fb1203dd5
|
|
BLAKE2b-256 checksum How to use checksums |
eb7b3034f52b8746ff8af0428b6b4251454bdeecf346a91cb7730ce99bde9e95
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_armv7l.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_armv7l.whl |
|---|---|
| Size | 5.8 MB |
| Tags | CPython 3.8 Linux musl 1.2+ ARMv7l abi3 |
|
SHA-256 checksum How to use checksums |
4d64c63c483081b3ae1dd8541fe17dfbd10948cd7908b91294019cba37c0e0a6
|
|
BLAKE2b-256 checksum How to use checksums |
d6825a5043a09e37c281012f79d7c09eaca88dd85c335e7904e4149679fee6a9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_aarch64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-musllinux_1_2_aarch64.whl |
|---|---|
| Size | 6.8 MB |
| Tags | CPython 3.8 Linux musl 1.2+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
e36498fd78a3e342c55dbe69b330c777c3de2eb110526afe2cbf2b33d3237d01
|
|
BLAKE2b-256 checksum How to use checksums |
80565a79dca27ee714eb8e59c4ff51d7dde3a8132e4609a51fa5d63ec33b7fd0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_28_armv7l.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_28_armv7l.whl |
|---|---|
| Size | 5.6 MB |
| Tags | CPython 3.8 Linux glibc 2.28+ ARMv7l abi3 |
|
SHA-256 checksum How to use checksums |
4056ed15c23f7a2956a10a8e588a1cc68b5aaaf81a488c1248f431552b23c7b2
|
|
BLAKE2b-256 checksum How to use checksums |
6e7d9b956949f034759b74ca209532306753594aaadeca57b537a394f434de18
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_28_aarch64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_28_aarch64.whl |
|---|---|
| Size | 6.5 MB |
| Tags | CPython 3.8 Linux glibc 2.28+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
2548646d115091c4c62b7bc0532994bb5148772aa020d898c43143b3db068e06
|
|
BLAKE2b-256 checksum How to use checksums |
ca1b1b2c2140143bb33751340d03320ea6e64a8d7c3977e48312862a8721be72
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 6.1 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
66c5d01ae5a96e5667fa159ce06d606784c7c647f2191d42b124ad4d51ffa090
|
|
BLAKE2b-256 checksum How to use checksums |
1ba3fe6fd75b0e0aa7ba39b7c98c7381709add8860a97d83a1c60a815f30d108
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl |
|---|---|
| Size | 6.7 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ PowerPC 64-le abi3 |
|
SHA-256 checksum How to use checksums |
bef82e121e503851a5a83edcb453d2213f28c70ecfa785a143f6301862df50e2
|
|
BLAKE2b-256 checksum How to use checksums |
9fa6f91e144715440b65de9e8eb36251c3d9c4a722370e82126c62e6f9203167
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_17_i686.manylinux2014_i686.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-manylinux_2_17_i686.manylinux2014_i686.whl |
|---|---|
| Size | 6.3 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ x86-32 abi3 |
|
SHA-256 checksum How to use checksums |
d8b830db7095fff867f0db40eae0df706d5c68df8fccecfc04c3356160957186
|
|
BLAKE2b-256 checksum How to use checksums |
9c0fa79d76fc0f3a558d80ebf6bb77ccdaed9958dba097de1df6a46874adfb78
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-macosx_11_0_arm64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 3.6 MB |
| Tags | CPython 3.8 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
00fc507e266c81634e31da54533a98a07aceb0705be8ccae3621a8d2ff48f945
|
|
BLAKE2b-256 checksum How to use checksums |
192503e09085510697840fdbeb79bf0f5c37e16c7014c0e9f249b8787dc64a3f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|
Release files / baseten_performance_client-0.1.15rc1-cp38-abi3-macosx_10_12_x86_64.whl
| Download URL | baseten_performance_client-0.1.15rc1-cp38-abi3-macosx_10_12_x86_64.whl |
|---|---|
| Size | 3.7 MB |
| Tags | CPython 3.8 abi3 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
d4211e9c8301c60ad5475eb439ff5e7cc40a9fd300e03e3507213f41d271bfa3
|
|
BLAKE2b-256 checksum How to use checksums |
4467da8e55681f15bac847ef11dc3cf205f672bae4f1b093e1847085ca7570ac
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.15.0
|














