
boolean-algebra-engine


Coding agents: machine-readable docs are in
llms.txt(summary) andllms-full.txt(full API reference).
Your AI agent's decision rules might contradict each other. LLMs can't reliably catch that. This engine can — provably, in under 10ms.
AI agents with decision logic — loan approval, compliance checks, access control, policy enforcement — run on boolean rules written by humans. Nobody verifies those rules don't conflict before the agent acts on them. This engine does.
The benchmark shows why you need it: even a 70B model gets ~20% of boolean logic questions wrong. You can't ask an LLM if your rules conflict and trust the answer. You need a deterministic layer that computes it.
90 tests passing · <10ms evaluation · zero dependencies · exhaustive enumeration, not sampling
Quick start
pip install boolean-algebra-engine
from boolean_algebra_engine import evaluate, synthesize

# Does a contradiction exist?
table, _ = evaluate("A.!A")
print(table.satisfiable)   # False — always a contradiction

# Can two rules both be true simultaneously?
table, _ = evaluate("(A.B).(!A)")
print(table.satisfiable)   # False — A and !A can't both hold

# Full truth table
table, _ = evaluate("A.(B+C)")
print(table.variables)     # ['A', 'B', 'C']
print(table.minterms)      # [5, 6, 7]
print(table.satisfiable)   # True

# Simplify to minimal form
minimal, _ = synthesize(table)
print(minimal)             # A.C+A.B
One-liner check:
python -c "from boolean_algebra_engine import evaluate; t,_ = evaluate('A.!A'); print(t.satisfiable)"
# False
Optional extras
pip install "boolean-algebra-engine[cli]"          # CLI / REPL
pip install "boolean-algebra-engine[mcp]"          # MCP server (Claude Desktop)
pip install "boolean-algebra-engine[api]"          # REST API
pip install "boolean-algebra-engine[nl-anthropic]" # NL layer via Anthropic
pip install "boolean-algebra-engine[nl-openai]"    # NL layer via OpenAI
The problem
Six rules. Three variables. Written by four people over six months.
A fintech AI agent auto-approves or rejects loan applications based on these rules — nobody ever verified them together. The engine checks all input combinations for every rule, in every combination:
# pip install boolean-algebra-engine[mcp]
from boolean_algebra_engine.mcp.server import check_prompt_logic

result = check_prompt_logic([
    "A.B",  # approve: good credit AND income verified
    "!A",   # reject:  bad credit
    "C",    # approve: collateral exists
    "!C",   # reject:  no collateral
])

print(result["summary"])
# {'total': 4, 'contradictions': 0, 'tautologies': 0,
#  'equivalent_pairs': 0, 'conflicting_pairs': 2}

print([(p["rule1"], p["rule2"]) for p in result["pairwise"] if p["always_conflict"]])
# [('A.B', '!A'), ('C', '!C')]
What it found:
A.Band!Aconflict — good credit approval and bad credit rejection fire simultaneously whenA=1. The agent picks a winner arbitrarily.Cand!Cconflict — collateral approval and no-collateral rejection are mutually exclusive by definition. Both rules can never apply at the same time.
Nobody caught these by reading the rules. The engine caught them by checking every combination.
The benchmark
Every model tested hallucinates on boolean logic — but in different ways depending on size and architecture.
| Model | Size | Hallucination | Pattern |
|---|---|---|---|
| tinyllama | 1.1B | 50% | always says "yes" — never reasoning |
| llama3.2:3b | 3B | 50% | always says "no" — never reasoning |
| gemma3:4b | 4B | 35% | reasoning per case, but wrong 1 in 3 |
| qwen3-32b | 32B | 17% | reasoning, consistent ~17% baseline |
| llama-3.3-70b | 70B | 20% | reasoning, but over-cautious — misses 40% of compatible pairs |
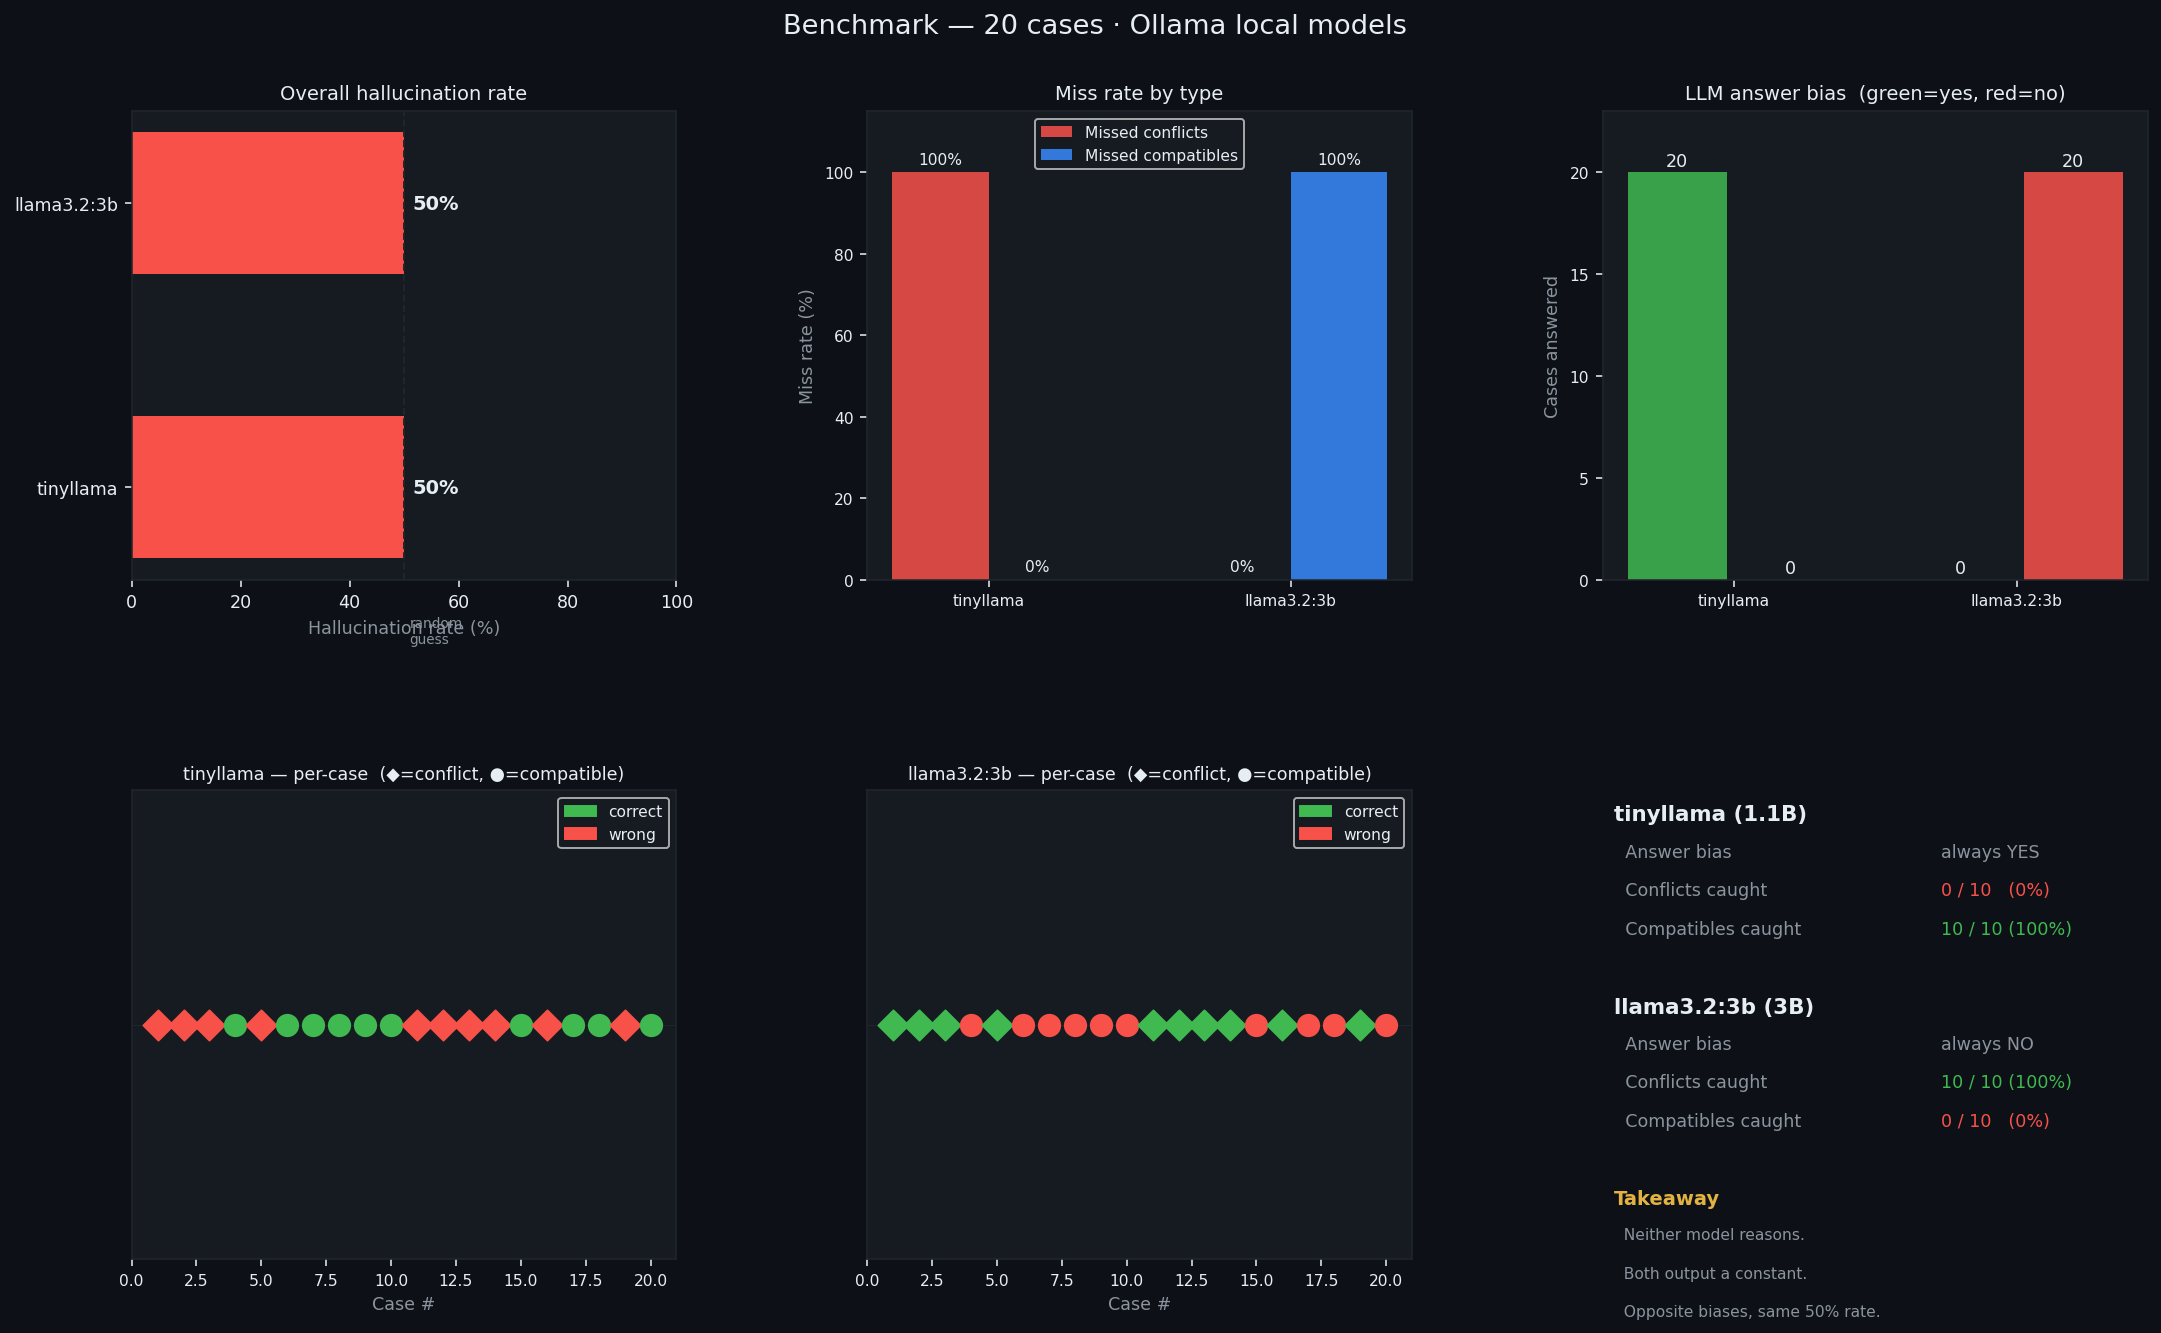
The small models aren't reasoning at all — they picked a default and stuck to it. The larger models reason but still hallucinate. llama-3.3-70b scores 20% but makes only one type of error: it assumes rules conflict when they don't (0% missed conflicts, 40% missed compatibles).
Variable curve — does complexity make it worse?
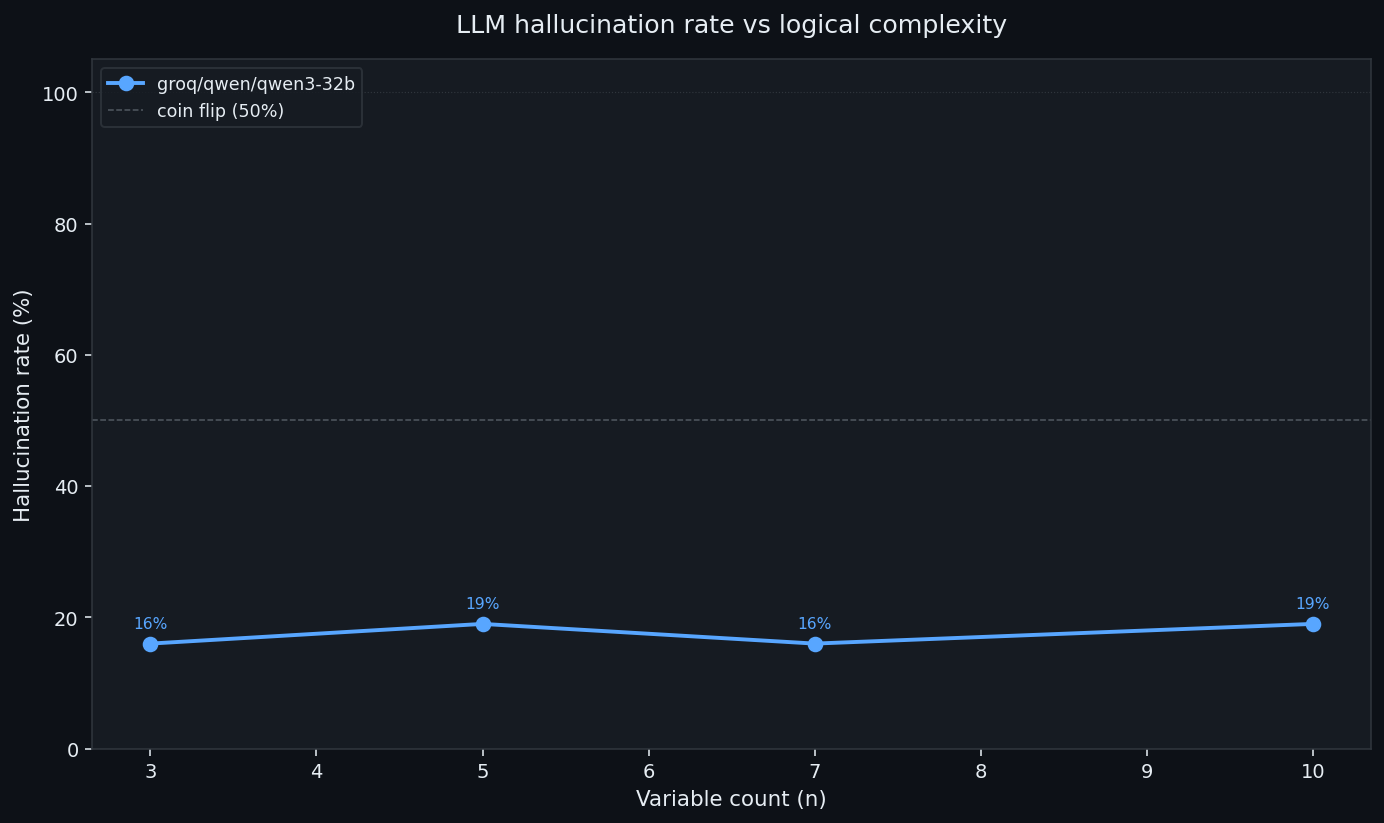
qwen3-32b was run across variable counts from 3 to 10 (8 to 1,024 truth table rows), 100 cases each. The hallucination rate stayed flat at 16–19% throughout. Complexity doesn't degrade it — the errors are a consistent baseline, not caused by harder logic.
| variables (n) | truth table rows | hallucination rate |
|---|---|---|
| 3 | 8 | 16% |
| 5 | 32 | 19% |
| 7 | 128 | 16% |
| 10 | 1,024 | 19% |
Full benchmark results
Methodology: generate pairs of boolean expressions where the correct answer (satisfiable or not) is known exactly. Ask the LLM. Compare. No ambiguity, no human labeling, no interpretation. The engine is the oracle — ground truth is computed by exhaustive enumeration, not guessed. Every LLM disagreement is a provable hallucination.
python3 benchmark.py --provider ollama --model tinyllama --cases 20
python3 benchmark.py --provider ollama --model llama3.2:3b --cases 20
python3 benchmark.py --provider ollama --model gemma3:4b --cases 20
tinyllama — 1.1B
correct: 10/20  ·  hallucination rate: 50.0%
missed conflicts: 10/10 (100%)  ·  missed compatibles: 0/10 (0%)
pattern: always outputs "yes" — no case-by-case reasoning
llama3.2:3b — 3B
correct: 10/20  ·  hallucination rate: 50.0%
missed conflicts: 0/10 (0%)  ·  missed compatibles: 10/10 (100%)
pattern: always outputs "no" — opposite default, same reasoning failure
gemma3:4b — 4B
correct: 13/20  ·  hallucination rate: 35.0%
missed conflicts: 4/10 (40%)  ·  missed compatibles: 3/10 (30%)
pattern: engages with each case individually — but wrong 1 in 3
qwen3-32b — 32B
correct: ~83/100  ·  hallucination rate: ~17%
flat across 3–10 variables — errors are a consistent baseline, not complexity-driven
llama-3.3-70b — 70B
correct: ~80/100  ·  hallucination rate: ~20%
missed conflicts: 0%  ·  missed compatibles: ~40%
pattern: over-cautious — never flags a conflict that isn't there, but misses 2 in 5 compatible pairs
The engine column is ground truth. Every mismatch with llm is a provable hallucination — not an opinion.
Core API
from boolean_algebra_engine import evaluate, synthesize

# Forward: expression → truth table
table, _ = evaluate("A.(B+C)")
print(table.variables)    # ['A', 'B', 'C']
print(table.minterms)     # [5, 6, 7]
print(table.satisfiable)  # True

# Inverse: truth table → minimal expression
minimal, _ = synthesize(table)
print(minimal)            # A.C+A.B

# Equivalence and satisfiability (via MCP server functions — no HTTP, direct call)
# pip install boolean-algebra-engine[mcp]
from boolean_algebra_engine.mcp.server import equivalent, satisfiable

print(equivalent("A.(B+C)", "A.B+A.C")["equivalent"])  # True — distributive law
print(satisfiable("A.!A")["satisfiable"])               # False — contradiction
The core module has zero external dependencies. Import it into any Python project.
MCP — Claude calls the engine
Wire the engine into Claude Desktop and Claude stops predicting boolean logic. It computes it.
{
  "mcpServers": {
    "boolean-algebra-engine": {
      "command": "python",
      "args": ["-m", "boolean_algebra_engine.mcp.server"]
    }
  }
}
Five tools Claude can call mid-conversation:
evaluate— expression → truth tablesimplify— expression → minimal formequivalent— are two expressions identical?satisfiable— does any input make this true?check_prompt_logic— audit a full rule set for contradictions, tautologies, conflicts, duplicates
NL Layer
The LLM translates. The engine decides. The logic is always exact.
Most tools that accept plain English rules pass them to an LLM and trust whatever comes back. That works for summarisation. It doesn't work for logic — the benchmark in this repo proves it, with hallucination rates from 17% to 50% across every model tested.
The NL layer takes a different approach. It uses the LLM for the one thing it's actually good at: mapping human language to symbols. Once the sentence becomes an expression, the LLM is done. The engine takes over, evaluates every possible input combination, and returns a result that is provably correct.
How it works
Take this sentence:
"access granted if the user is an admin, or if they're verified and not suspended"
"access granted if admin, or verified and not suspended"
        │
        ▼  LLM — maps words to variables, returns an expression
   A+(V.!S)
        │
        ▼  core engine — evaluates every input combination
   truth table: 8 rows · 6 rows where output = 1
   minimal form: A+V.!S
   satisfiable: yes  ·  tautology: no  ·  contradiction: no
        │
        ▼  LLM — turns the result back into plain English
   "Access is granted in 6 of 8 cases. A suspended verified
    user is always denied, regardless of admin status."
The LLM is involved twice — both times doing something fuzzy (language), never something exact (logic).
Try it in 5 minutes
The fastest path is Ollama — runs locally, no API key, free.
# 1. Install Ollama
curl -fsSL https://ollama.com/install.sh | sh

# 2. Pull a model
ollama pull deepseek-r1:latest   # 5.2 GB, best quality
# ollama pull deepseek-r1:1.5b  # 1.1 GB, for low-memory machines

# 3. Install the package
pip install boolean-algebra-engine
from boolean_algebra_engine.nl.nl import ask

result = ask("alarm on if door open or window open, but not if system disabled")

print(result.expression)   # (D+W).!S
print(result.minimal)      # D.!S+W.!S
print(result.satisfiable)  # True
print(result.variables)    # {'D': 'door is open', 'W': 'window is open', 'S': 'system is disabled'}
print(result.explanation)  # plain English summary
The provider is auto-detected: if Ollama is running, it is used automatically. No configuration needed.
Or via the CLI:
boolcalc ask "alarm on if door open or window open, but not if system disabled"
boolcalc check-rules "access if admin" "access if verified" "no access if suspended"
Choosing a provider
| Provider | Cost | Setup |
|---|---|---|
| Ollama | Free | Install Ollama, pull a model |
| Anthropic | API usage | export ANTHROPIC_API_KEY=... |
| OpenAI | API usage | export OPENAI_API_KEY=... |
| OpenAI-compatible | Varies | Groq, Together, LM Studio, vLLM |
pip install "boolean-algebra-engine[nl-anthropic]"
export ANTHROPIC_API_KEY=sk-ant-...
from boolean_algebra_engine.nl.nl import ask, AnthropicProvider, OpenAIProvider, OpenAICompatProvider, OllamaProvider

# Anthropic
result = ask("...", provider=AnthropicProvider())
result = ask("...", provider=AnthropicProvider(model="claude-opus-4-7"))

# OpenAI
result = ask("...", provider=OpenAIProvider())
result = ask("...", provider=OpenAIProvider(model="gpt-4-turbo"))

# OpenAI-compatible (Groq, Together, LM Studio, vLLM)
result = ask("...", provider=OpenAICompatProvider(
    api_key="your-key",
    base_url="https://api.groq.com/openai/v1",
    model="llama3-8b-8192",
))

# Ollama with specific model or remote host
result = ask("...", provider=OllamaProvider(model="deepseek-r1:1.5b"))
result = ask("...", provider=OllamaProvider(base_url="http://192.168.1.10:11434"))
Bring your own model
Any model that can receive a system prompt and a user message can be plugged in:
from boolean_algebra_engine.nl.nl import ask, Provider

class MyProvider(Provider):
    def complete(self, system: str, user: str, max_tokens: int = 512) -> str:
        response = my_llm.generate(system_prompt=system, user_message=user, max_tokens=max_tokens)
        return response.text

result = ask("access granted if admin or verified user", provider=MyProvider())
complete() is called twice per ask() — once to parse the sentence (expects JSON back), once to explain the result (expects plain text).
What you get back
Every ask() call returns an NLResult:
@dataclass
class NLResult:
    input_sentence: str
    expression:     str          # boolean expression the LLM parsed from your sentence
    variables:      dict[str, str]  # {'A': 'user is admin', ...}
    minimal:        str          # Quine-McCluskey simplified form
    satisfiable:    bool
    tautology:      bool
    contradiction:  bool
    minterms:       list[int]    # row indices where output = 1
    maxterms:       list[int]    # row indices where output = 0
    explanation:    str          # plain English summary from the LLM
    rows:           list[dict]   # full truth table
Operators
| Symbol | Operation | Precedence |
|---|---|---|
! |
NOT | 4 (highest) |
. |
AND | 3 |
^ |
XOR | 2 |
+ |
OR | 1 (lowest) |
Variables: uppercase A–Z. Parentheses override precedence. Up to 26 variables, arbitrary nesting.
Common mistake: &&, ||, ~ are not valid — use ., +, !.
Interfaces
| Interface | How |
|---|---|
| Python library | from boolean_algebra_engine import evaluate — embed in any project |
| CLI / REPL | boolcalc "A.B+!A.C" — instant truth table in terminal |
| MCP server | Claude Desktop plugin — plug and play |
| REST API | POST /check-rules — callable from any language or stack |
| NL layer | Plain English → expression → verified result (Anthropic, OpenAI, Ollama, any OpenAI-compat) |
vs SymPy and boolean.py
SymPy (sympy.logic) is more powerful for pure boolean mathematics — its DPLL-based satisfiable() scales better beyond 15 variables, and simplify_logic() covers similar minimization ground. If you're doing symbolic mathematics, use SymPy.
boolean.py handles expression parsing and symbolic simplification cleanly. If you need to manipulate boolean expressions as objects, it's the right tool.
This engine is different in three ways:
-
Zero-dependency core. SymPy pulls in numpy, mpmath, and the full symbolic stack. The core module is plain Python — no install side-effects, embeds anywhere.
-
Built for AI pipelines, not mathematics.
check_prompt_logicaudits a set of rules for pairwise conflicts — the kind of check you run on a system prompt or a business rule engine before an agent acts on it. Neither SymPy nor boolean.py has this concept. -
The integration layer. MCP server for Claude Desktop, NL layer for plain English input, REST API, benchmark against LLMs — none of this exists in math-focused libraries because it's not a math problem. It's an AI reliability problem.
If you want to do boolean algebra, SymPy is the answer. If you want to verify that your AI agent's rules don't contradict each other, this is built for that.
Credibility
The engine does not sample, approximate, or predict. It evaluates every possible input combination:
- Satisfiable — an actual row where output = 1 was found
- Contradiction — every row was checked, all were 0
- Equivalent — output columns compared row-by-row across the full truth table
- Conflict — conjunction of both rules evaluated for every input, always returned 0
No black box, no model weights, no probability — just arithmetic. This is a stronger correctness claim than any probabilistic tool can make.
90 tests across unit, integration, edge cases, and round-trips. All passing.
For bugs and feature requests: open an issue.
1 maintainer

Metadata
1 maintainer
Release files for boolean-algebra-engine 0.3.21
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| boolean_algebra_engine-0.3.21.tar.gz | 54.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| boolean_algebra_engine-0.3.21-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 103.0 kB
Release files / boolean_algebra_engine-0.3.21.tar.gz
| Download URL | boolean_algebra_engine-0.3.21.tar.gz |
|---|---|
| Size | 54.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7295e84bdc539c17b9ff3b126deb30f5b6951b34eff21cafe1ab362ec9636917
|
|
BLAKE2b-256 checksum How to use checksums |
2d1039770979c896e5e64adc899ca5247c560b6662c591e957af94c54749d82b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 8, 2026.
Transparency logRelease files / boolean_algebra_engine-0.3.21-py3-none-any.whl
| Download URL | boolean_algebra_engine-0.3.21-py3-none-any.whl |
|---|---|
| Size | 48.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2c943115eda4c0aa614986618813b59109fe20c222e87dd4cc424c64683c5ff4
|
|
BLAKE2b-256 checksum How to use checksums |
7dd0537c57f3ce06e703a2e17ed90874cad764070bb41afe1f35ded6c085ed08
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 8, 2026.
Transparency log













