

Documentation | Tutorials | Discussions
Calkit makes it easy to create single-button reproducible research projects. Instead of a loosely related collection of files split across multiple systems or apps, "integrated" via manual steps, your project becomes a version-controlled, self-contained "calculation kit" tying together literature review, planning, data collection, analysis, and writing, so you, your collaborators, and your readers can verify the full chain from raw data to research article with a single command. This enables faster, more confident, and more frequent iteration, which in turn produces higher quality results. It also makes it easy to check the work of an AI agent, i.e., that the outputs it produced as evidence to answer research questions came from a transparent, deterministic pipeline, not hallucinations.
Calkit also makes it natural to keep all stages of a research project together in the same repository, providing full context to both humans and AI agents. This is important because the stages are tightly coupled. A change in a dataset requires reanalyzing, which creates a change in a figure, which creates a change in a research article. Coupled components belong close together and connected, and cross-stage iteration is enabled by integration.
Software teams learned the importance of integration long ago, unifying design, development, testing, deployment, and infrastructure in the same repo, often within the same team, with automation across the entire lifecycle. Research can benefit in similar ways.
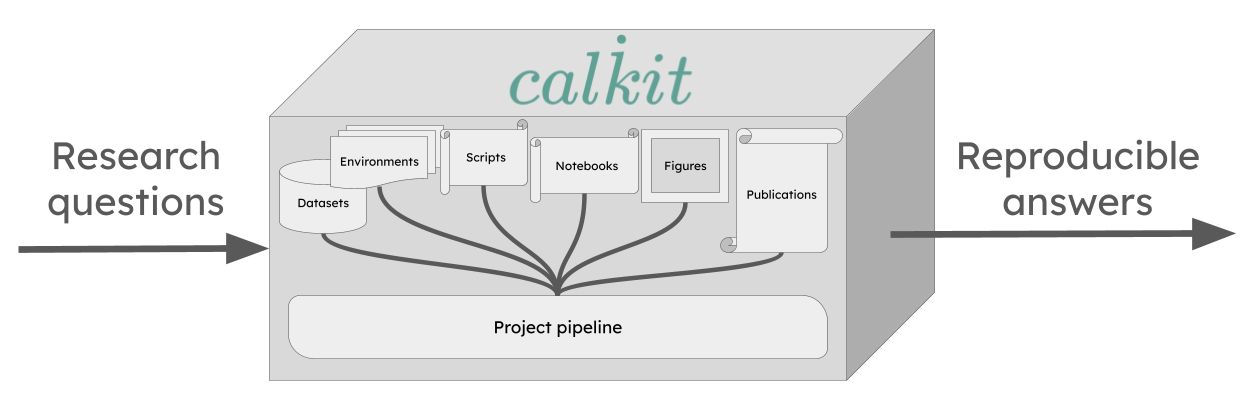
Why Calkit?
The tools to create single-button reproducible research projects already exist, e.g., version control with Git, environment management with uv, Make for a build system or pipeline, and LaTeX for document compilation. If you and your team can work effectively with a system like that, there's no need for any additional complexity.
However, these practices are still not common, resulting in most compendiums failing to reproduce. Many still silo the code away from the data, and the analysis from the writing. Many are instead "multi-button" and irreproducible because their stages are not connected and important setup or execution information is omitted.
There are additional challenges:
- Computationally expensive steps may need to be run on a high-performance computing (HPC) cluster. Automating the transfer of data to and from there requires additional work, and it becomes important to use a content-aware pipeline system, otherwise steps are inefficiently repeated or mistakenly skipped.
- Large data files need to be kept in version control along with the rest. A typical solution may involve siloing data files away on a shared cloud or physical hard drive, requiring custom syncing scripts to avoid manual uploads and downloads.
Again, the tools to solve these problems do exist: Snakemake, Nextflow, or DVC for pipelines; Git LFS, git-annex, or DVC for data version control, but they all require significant setup and training. At this point, you're looking at half a dozen subsystems to integrate and upskill the team to use, essentially requiring many to become de facto software engineers to contribute. What happens in reality is that the costs are deemed too high and the benefit too low, so workflows remain manual and fragmented, and many team members are not able to contribute to their full potential.
Calkit solves these by providing a fully integrated experience built from the open source components that would typically comprise such a workflow. Everything is connected right out of the box, with a command line interface (CLI), web app, and more to reduce friction for every task and team member involved. The integration is transparent without lock-in, so the underlying software engineering-oriented tools can be used directly by team members more comfortable with them, and others can contribute at a higher level while maintaining single-button reproducibility and frictionless, seamless iteration.
Additionally, the Calkit project information format,
saved in calkit.yaml,
gives a full picture of the project:
its research questions, artifacts
generated as evidence to answer them,
and a way to fully verify everything back to its origin.
There's no mystery about where a certain figure or table came from,
and whether or not it's stale with respect to its input data,
which is a critical feature to have when using generative AI.
Features
- A simplified version control interface that unifies Git and DVC (Data Version Control), so everything can be kept in the same project repository. This way, code doesn't need to be siloed away from other important artifacts like datasets, models, figures, or article PDFs, allowing you to work on all parts of a project without hopping around to different tools.
- Computational environment management with support for many languages and environment managers: Conda, Docker, uv, Julia, Renv, and more. No need to create and update environments on your own. Calkit will handle them as needed.
- An environment-aware build system or pipeline with
a simple declarative syntax and
output caching so you don't need to think about which steps or stages
need to be rerun after changing any part of the project.
Simply call
calkit run. Compose your pipeline from many different kinds of stages, including simple scripts, commands, Jupyter Notebooks, LaTeX, and more. - A complementary self-hostable and GitHub-integrated hub web app to facilitate backup, collaboration, and sharing throughout the entire research lifecycle.
- Overleaf integration, so analysis, visualization, and writing can all stay in sync (no more manual uploads!).
- Support for running on high performance computing (HPC) systems that use PBS or SLURM schedulers.
- Support for automated running with GitHub Actions.
- Extensions for doing all of the above graphically in JupyterLab and VS Code.
- A browser extension for collecting references directly to BibTeX (optionally synced with Zotero), viewing DVC-stored files on GitHub, and syncing figures and results with Overleaf directly in Chrome, Microsoft Edge, and more.
Installation
On Linux, macOS, or Windows Git Bash, install Calkit and uv (if not already installed) with:
curl -LsSf install.calkit.org | sh
Or with Windows Command Prompt or PowerShell:
powershell -ExecutionPolicy ByPass -c "irm install-ps1.calkit.org | iex"
If you already have uv installed, install Calkit with:
uv tool install calkit-python
You can also install with your system Python:
pip install calkit-python
To effectively use Calkit, you'll want to ensure Git is installed and properly configured. You may also want to install Docker, since that is the default method by which LaTeX environments are created. If you want to use a Calkit hub for collaboration and backup as a DVC remote, you can connect to the hub with:
calkit hub login
If you use AI agents like Claude, Copilot, or Codex, see AI tools to learn how to install agent skills for working with Calkit.
Use without installing
If you want to use Calkit without installing it,
you can use uv's uvx command to run it directly:
uvx ck9 --help
Nix
Calkit ships a flake at the root of its repo, so Nix users can pull the CLI into their environments alongside their other tools.
Run it ad hoc without installing:
nix run github:calkit/calkit -- --help
Drop into a shell that has calkit, git, and uv on PATH:
nix shell github:calkit/calkit
Add it to your own flake.nix as an input:
{
  inputs.calkit.url = "github:calkit/calkit";
  inputs.nixpkgs.url = "github:NixOS/nixpkgs/nixos-unstable";

  outputs = { self, nixpkgs, calkit }: {
    devShells.x86_64-linux.default =
      nixpkgs.legacyPackages.x86_64-linux.mkShell {
        packages = [ calkit.packages.x86_64-linux.default ];
      };
  };
}
Then nix develop will give you a shell with the Calkit CLI ready to
use. To pin a specific Calkit release inside the shell, set the
CALKIT_VERSION environment variable (e.g. CALKIT_VERSION=0.41.0)
before invoking calkit.
The flake is currently a thin wrapper around uvx --from calkit-python calkit. It depends on uv from nixpkgs and fetches the published
wheel from PyPI on first use. This trades a fully Nix-native build for
zero version-drift maintenance, and avoids the macOS docx2pdf /
appscript and JupyterLab labextension build issues that block a pure
nixpkgs derivation today. If you want a fully nixpkgs-native build,
see the community calkit-nix
flake.
Nix isn't supported natively on Windows; run Calkit inside WSL2 and use the flake there.
Running against a specific version
If a project requires a Calkit version other than the one you have
installed, use the top-level --use-version flag to re-invoke the CLI
under that release without changing your installation:
calkit --use-version 0.38 run
This re-execs the CLI via uvx --from calkit-python@<version> calkit,
so it requires uv on PATH.
You can also declare a minimum version in calkit.yaml;
see
Pinning the Calkit CLI version.
Calkit Assistant
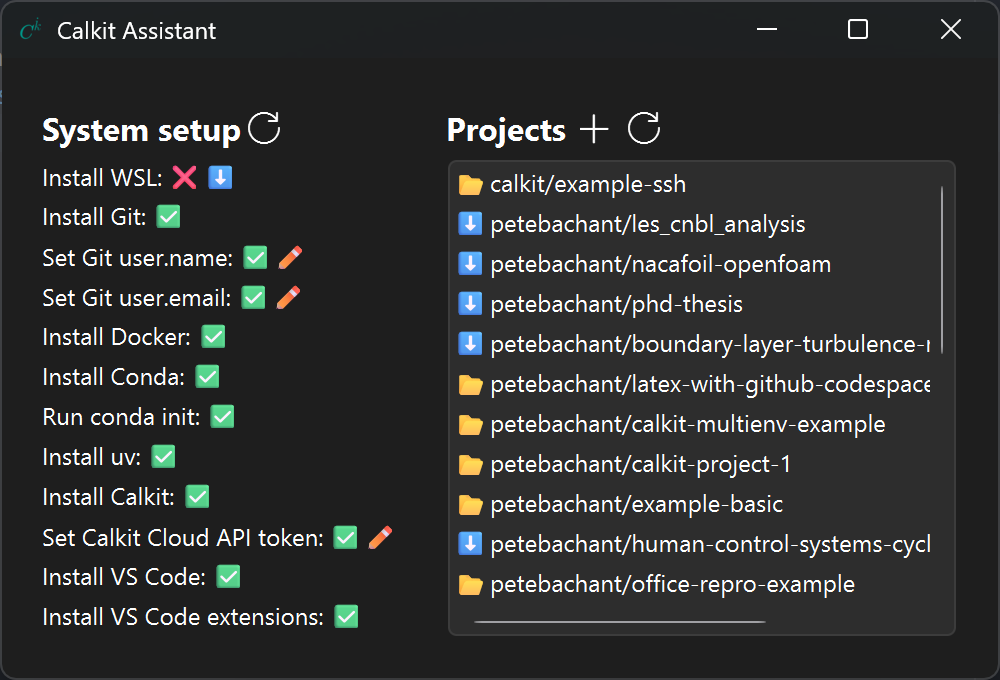
For Windows users, the Calkit Assistant app is the easiest way to get everything set up and ready to work in VS Code, which can then be used as the primary app for working on all scientific or analytical computing projects. Download the executable from the latest assistant release.
Quickstart
From an existing project
If you want to use Calkit with an existing project,
navigate into its working directory and use the xr command to start
executing and recording your scripts, notebooks, LaTeX files, etc.,
as reproducible pipeline stages.
For example:
calkit xr scripts/analyze.py

calkit xr notebooks/plot.ipynb

calkit xr paper/main.tex
Calkit will attempt to detect environments, inputs, and outputs and
save them in calkit.yaml.
If successful,
you'll be able to run the full pipeline with:
calkit run
Next, make a change to e.g., a script and look at the output of
calkit status.
You'll see that the pipeline has a stage that is out-of-date:
---------------------------- Pipeline ----------------------------
Stale stages:
        analyze:
          stale outputs:
            data/results.csv
          modified inputs:
            scripts/analyze.py
This can be fixed with another call to calkit run.
You can save (add and commit) all changes with:
calkit save -am "Add to pipeline"
Fresh from a Calkit project template
Create a new project from the
calkit/example-basic
template with:
calkit new project my-research \
    --title "My research" \
    --template calkit/example-basic \
    --hub
Note the --hub flag requires a hub connection
to be set up, but can be omitted if the project doesn't need to be backed up to
the hub or shared with collaborators.
Hub integration can also be set up later.
Next, move into the project folder and run the pipeline,
which consists of several stages defined in calkit.yaml:
cd my-research
calkit run
Next, make some edits to a script or LaTeX file and run calkit status to
see what stages are out-of-date.
For example:
---------------------------- Pipeline ----------------------------
Stale stages:
        build-paper:
          stale outputs:
            paper/paper.pdf
          modified inputs:
            paper/paper.tex
Execute calkit run again to bring everything up-to-date.
To back up or save the project, call:
calkit save -am "Run pipeline"
With an AI coding agent
Simply tell the AI agent:
Turn this folder into a Calkit project
or
Create me a new Calkit project for investigating...
Get involved
We welcome all kinds of contributions! See CONTRIBUTING.md to learn how to get involved.
Acknowledgements
Calkit is supported by the Caltech Schmidt Academy of Software Engineering.


1 maintainer

Release files for calkit-python 0.47.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| calkit_python-0.47.7.tar.gz | 25.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| calkit_python-0.47.7-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 26.6 MB
Release files / calkit_python-0.47.7.tar.gz
| Download URL | calkit_python-0.47.7.tar.gz |
|---|---|
| Size | 25.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cd591afc03a87d80252c23a7cf5fd17527c473f5a34341dee4749c094313423e
|
|
BLAKE2b-256 checksum How to use checksums |
262786bcbad032d483720675196beeb1e34f0f6983f6159930f979cb1c0b5c47
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / calkit_python-0.47.7-py3-none-any.whl
| Download URL | calkit_python-0.47.7-py3-none-any.whl |
|---|---|
| Size | 1.1 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
413d73bf775ebb212ea6666ca9c2e95319e3dff9166901b34c39574a33d20887
|
|
BLAKE2b-256 checksum How to use checksums |
7c9e361ad515eaf195283b0ea1267706fb40b839af78abfa6faba9b4b9f08eb6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













