
Check documents before they reach an LLM, offline.

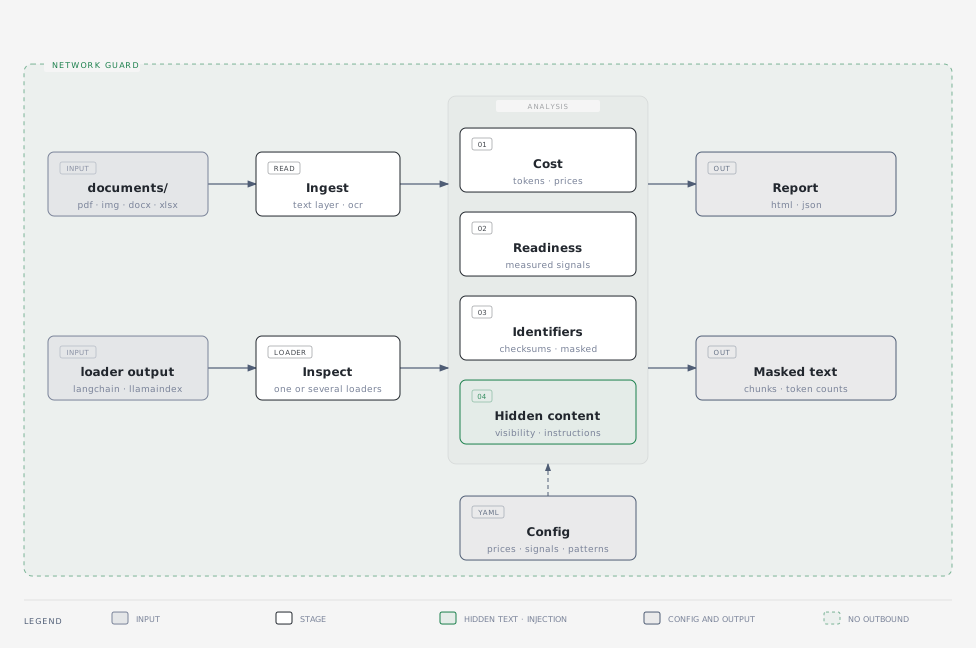
complydoc inspects documents, and the output of document loaders, before they are sent to an LLM. It measures what processing them will cost, how reliably text can be read off each page, which personal and financial identifiers they contain, and whether anything hidden in a file is addressed to a model.
Quickstart
uv tool install complydoc
complydoc audit ./documents
import complydoc as cd

report = cd.full_audit("./documents")
print(report.overall.score)
cd.write_html(report, "report.html")
Output from a LangChain or LlamaIndex loader, or several loaders over a folder:
from langchain_community.document_loaders import PDFPlumberLoader, PyPDFLoader

report = cd.inspect_documents(PyPDFLoader("contract.pdf"))

report = cd.compare_loaders(
    {"pypdf": PyPDFLoader, "pdfplumber": PDFPlumberLoader, "docling": cd.parsers.docling()},
    paths="./contracts",
    facts=["Payment is due within thirty days"],
)
report.to_pandas("loaders")
Works with LangChain,
LlamaIndex,
Unstructured,
Docling,
LlamaParse and
Azure AI Document Intelligence,
and with any loader that has a load method or is a callable. Reports tag each loader with the
framework and library it comes from.
The same from the command line, for CI:
complydoc routing ./documents
complydoc compare-loaders loaders.yaml
complydoc chunks ./documents --splitter "langchain_text_splitters:RecursiveCharacterTextSplitter chunk_size=800"
complydoc diff baseline.json .complydoc/complydoc.json
complydoc check ./documents --policy policy.yaml --markdown summary.md --sarif results.sarif
complydoc clean ./documents --out clean/
check holds a folder to rules written in YAML and exits non-zero when they fail, with a
summary for a pull request comment and SARIF for code scanning. On GitHub, the repository
is also an action that does all three:
- uses: complydoc/complydoc@v0.4.11
  with:
    path: documents
    policy: policy.yaml
See GitHub Action for the
inputs, permissions and code scanning. clean writes safe copies:
the identifiers masked, the metadata removed, and PDFs rasterised on request.
A parser can hang on a malformed file: --timeout 120 gives each document a deadline and
lists the ones it stopped.
Optional extras
A plain install reads documents, prices them, measures extraction readiness, finds identifiers by pattern and checks for hidden content. It does not read scans or find names, and every report says so. Those are optional because they are large:
| Extra | Size | What it adds | Without it |
|---|---|---|---|
ocr |
~80 MB | Reads scans and images | Pages with no text layer are reported as unread |
multilingual-names |
~2 GB | Finds people and companies in European languages | Names are not scanned for, unless ner is installed |
ner |
~50 MB | Finds names with spaCy's small English model | Names are not scanned for, unless multilingual-names is installed |
typesafe |
small | Judges passages that read as instructions to a model, with a hosted service | Instructions are found by pattern alone |
assistant |
small | complydoc assist, which drafts quick wins from a finished report with a hosted chat model |
Quick wins are the ones the report computes on its own |
uv tool install "complydoc[ocr,multilingual-names]"
"$(uv tool dir)/complydoc/bin/python" -c "from transformers import pipeline; \
    pipeline('token-classification', model='Babelscape/wikineural-multilingual-ner')"
The second command downloads the name model once, into the Hugging Face cache. Nothing is
downloaded while a scan runs, so the model has to be fetched before it can be used. With
pip, install "complydoc[ocr,multilingual-names]" and run the same line with your own
python. The ner extra needs its model too, en_core_web_sm. complydoc doctor prints
the command for whatever is missing.
Names are the part worth understanding before choosing. The multilingual model is the better reader; spaCy's small English one misses names in other languages and mistakes field labels for companies. Neither is a checksum, so both miss some names: Detection accuracy publishes the measured numbers for each.
Two extras change where your documents go, and nothing else in complydoc leaves the
machine. typesafe sends the passages it judges to a hosted service. assistant powers
complydoc assist, which sends a finished report to a hosted chat model: its findings,
signals, loaders and costs, with the page pictures and the page text held back. Both are
off unless the caller passes allow_network=True, both name the host before they run, and
the guard blocks everything else.
complydoc doctor shows what is installed, and complydoc benchmark prints what detection
finds and what it wrongly flags against a labelled corpus that ships with the package.
What it reports
- Formats: PDF, scans and images, Word, Excel, PowerPoint, HTML, Markdown, plain text
and email (
.eml). - Token cost: text and vision tokens per document, priced across models and three extraction paths (text layer, OCR, vision).
- Page routing: the path each page needs — its text layer, local OCR or a vision model — with the reason, priced as a mix against sending everything one way, and written as a manifest an ingestion job can read.
- Extraction readiness: measured signals such as text layer coverage, tables, columns, rotation, scan resolution, garbled characters, glyph codes and repeated headers.
- Identifiers: personal and financial identifiers from Europe, the Americas, India and Australia,
checksum-validated where a checksum exists, masked in every output, the page text
included, unless
--revealis passed. - Hidden content and prompt injection: text a reader does not see and a model does (white or invisible text, hidden formatting, Unicode tag characters), and passages that read as instructions to a model.
- Loader inspection and comparison: what a loader extracted, the metadata it attached, the network connections it attempted, and where several loaders disagree, over a single input or a folder, with failures, load time and estimated parser cost per loader.
- Expected facts: whether passages you expect appear in each loader's text, as exact or fuzzy matches.
- Parser presets: Docling, Unstructured, LlamaParse and Azure Document Intelligence;
hosted parsers run only with
allow_network=True. - Tables: every part of a report as a pandas DataFrame, and a summary in Jupyter.
- Python API: scanning and masking strings, chunk inspection, baselines with diffs and assertions for tests, streaming audits, cached loader output, and pipeline steps for LangChain and LlamaIndex.
- Masked text: the documents' text with identifiers covered, chunked and counted in tokens.
- Safe copies: the same document with its identifiers masked and its metadata removed, for text, Markdown, HTML, email and Office files. A PDF copy has its metadata stripped and can be rasterised, which leaves no text layer to read.
- Measured accuracy: what identifier detection finds and what it wrongly flags, scored against a labelled corpus that ships with the package and published with the numbers.
How it works
- Offline: outbound sockets and DNS lookups are blocked for the whole run, and each report records that the guard was armed.
- Unmeasured values: a signal that cannot be measured is reported as unmeasured and left out of scores.
- Evidence tiers: every finding states how it was established, whether by checksum, corroboration, pattern or model.
- Configurable: prices, signal weights and detection patterns are YAML files, and name detection can use your own spaCy models, per language, or any other model as a detector.
- One report: a self-contained HTML file and a JSON file with a versioned schema,
safe to share: identifiers are masked throughout and pages are drawn as wireframes.
--page-imagesembeds a picture of each page instead, and says that it shows them.
Resources
- Documentation: guides and design notes
- Command line reference
- Python API reference
- Playground: runnable command line and Python examples, with a CI workflow
- Report JSON
- Changelog
- Contributing
License
MIT
1 maintainer

Release files for complydoc 0.4.11
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| complydoc-0.4.11.tar.gz | 4.1 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| complydoc-0.4.11-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 7.3 MB
Release files / complydoc-0.4.11.tar.gz
| Download URL | complydoc-0.4.11.tar.gz |
|---|---|
| Size | 4.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
75cd0b58f50bbf34af3bbc98eb68239cb9ff1ddf48fbcf1ef2df7d8ccb26879a
|
|
BLAKE2b-256 checksum How to use checksums |
ba282d8298657b765f8aed84ab1158f2a6803a485b76e1d9b095247a774c7df1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 17, 2026.
Transparency logRelease files / complydoc-0.4.11-py3-none-any.whl
| Download URL | complydoc-0.4.11-py3-none-any.whl |
|---|---|
| Size | 3.1 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e031dc44d79513b294c64462fb00b1b8ac814d7a4cc4563a4d35702ccb174dc7
|
|
BLAKE2b-256 checksum How to use checksums |
6f064068a0966ceff2923e20eb7929daa86629e12c6b156d7abddd6e6ded3d06
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 17, 2026.
Transparency log













