
Coralsnake


Conventional genomics tools are built around DNA — a linear, double-stranded
reference where each locus lines up 1:1 with the sequence — and often lack
explicit consideration of RNA's structural properties: an abundance
hierarchy (ribosomal rRNA is orders of magnitude more abundant than
mRNA), strand orientation (sense vs. antisense), and splicing (mRNAs
are assembled from exons, so a transcript does not line up with its genomic
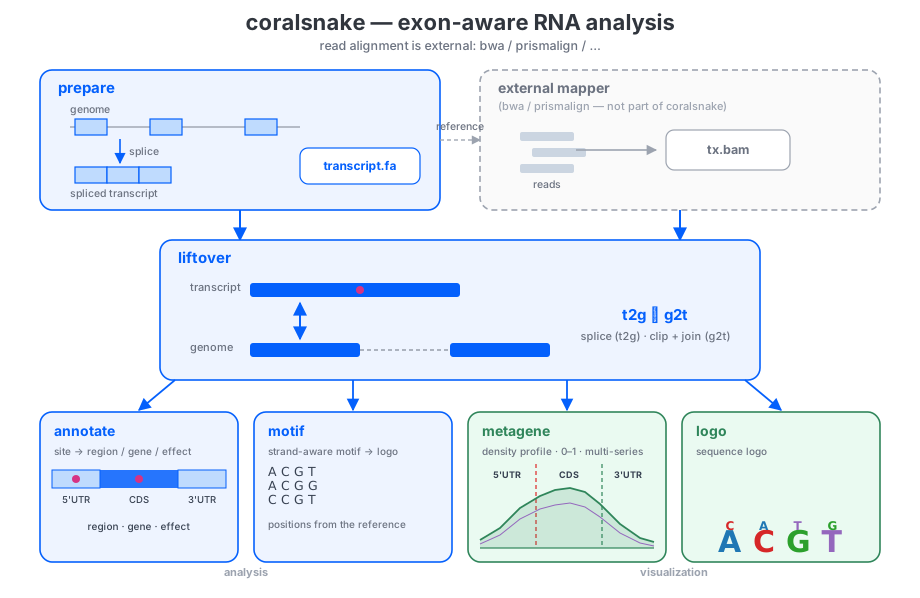
locus). Coralsnake is an exon-aware RNA analysis pipeline built around
exactly these properties: it cleans and normalizes the reference inputs
(refine), turns a GTF/GFF into spliced transcript references (prepare),
splices and joins reads between transcript and genome coordinates in both
directions (liftover), and runs the analyses you do on the results —
annotate places sites/variants on the RNA hierarchy (5'UTR / CDS / 3'UTR /
intronic / intergenic) and calls the variant effect, metagene profiles how
sites distribute across 5'UTR / CDS / 3'UTR, motif fetches the strand-aware
reference motif around each site, and logo renders a DNA/RNA sequence logo.
Installation
Requires Python ≥ 3.12.
pip install coralsnake
The visualization commands (metagene plot, sequence logo) need the lightweight
plot extra, which only pulls in matplotlib when you need it:
pip install "coralsnake[plot]"
Commands
| Command | What it does |
|---|---|
refine |
Clean/normalize the genome FASTA + GTF before prepare (rename seqnames, normalize names/biotypes, flag canonical transcripts). |
prepare |
Extract the spliced primary transcript reference from GTF/GFF. |
liftover |
Splice/join reads between genome/transcript BAMs (-d t2g default, -d g2t inverts). |
annotate |
Unified site/variant annotation: region on the RNA hierarchy + gene/transcript + variant effect. |
qc |
RNA-seq QC from a genome-aligned BAM + GTF: mapping stats + exonic/intronic/intergenic rates + gene counts/TPM (rnaseqc-style). |
metagene |
Exon-aware metagene profiling across 5'UTR/CDS/3'UTR (profile plot needs coralsnake[plot]). |
motif |
Strand-aware genomic motif fetch around variant sites. |
coordinate |
Map chromosome names between coordinate systems (UCSC↔Ensembl). |
group |
Group genes and build a consensus sequence. |
logo |
Plot a DNA/RNA sequence logo, or export its score matrix via --matrix (plotting needs coralsnake[plot]). |
annotateis the single annotation tool — one command, one schema, two input modes:--reference-gtf(region + gene/transcript, and the full variant effect when given a genome FASTA + ref/alt) or--annotation <table>(fast precomputed-table site labeling).
Quick example
A typical end-to-end run (read alignment is done by any external mapper, e.g.
bwa / prismalign):
# 0. (Optional) Clean/normalize the FASTA + GTF first (rename seqnames,
#    normalize names/biotypes, flag the canonical transcript). When you run
#    this, feed outdir/ref.annotation.gtf / outdir/ref.genome.fasta into the
#    steps below instead of annotation.gtf / genome.fa.
coralsnake refine -f genome.fa -g annotation.gtf -o outdir -n ref

# 1. Build the spliced transcript reference: FASTA to align to (-s) and the
#    annotation table (-o) used by liftover and annotate
coralsnake prepare -g annotation.gtf -f genome.fa \
                   -s transcript.fa -o annotation.tsv --with-codon

# 2. Align reads to transcript.fa with an external mapper  →  tx.bam

# 3. Splice the transcript-aligned BAM back to genome coordinates
coralsnake liftover -d t2g -i tx.bam -o genome.bam -a annotation.tsv -f genome.fai

# 4. Annotate sites to genes/transcripts (RNA hierarchy + variant effect)
coralsnake annotate -i sites.tsv -o annotated.tsv \
                    --reference-gtf annotation.gtf \
                    --reference-transcript genome.fa -s -a

# 5. Exon-aware metagene profile across 5'UTR / CDS / 3'UTR
coralsnake metagene -i sites.tsv -g annotation.gtf -o profile.tsv -p profile.png
Subcommands
refine — reference cleaning (pre-prepare)
Clean and normalize a genome FASTA and/or GTF before building the spliced
reference: seqname renaming/filtering, gene/transcript name and type
normalization, missing gene/transcript/exon row creation, overlapping-exon
merge, canonical-transcript flagging, and coordinate checks. Codon and UTR
features are preserved, so the output stays usable for metagene and
annotate. Indexing uses pysam — no external samtools/bgzip/tabix.
The GTF side is built on the shared coralsnake.genemodel.GeneModel object —
the same read/serialize layer prepare uses — so a refined GTF is a drop-in
replacement for the input: both GENCODE-style (*_type) and Ensembl-style
(*_biotype) biotype attributes are written, and the selected canonical
transcript is tagged Ensembl_canonical so prepare's ranking picks the
transcript refine selected.
coralsnake refine -f genome.fa -g annotation.gtf -o outdir -n hg38 \
                  -m chrom_map.tsv -c canonical.tsv
-f/--fasta-file— the genome FASTA to clean: seqnames are renamed/filtered, headers rewritten as>new_name old_name, and a.fai+.genome.sizesindex is rebuilt with pysam.-g/--gtf-file— the GTF to normalize (the GeneModel pipeline above).-o/--outdir— output directory (default./).-n/--name— output name prefix (default: the outdir's basename).-m/--rename-mapper— TSV mapping old seqname → new seqname.-p/--seqname-pattern— keep only seqnames matching this regex.-c/--canonical-transcripts— TSV of canonical transcript IDs (1st column).- At least one of
-f/-gis required. Pass both to keep the FASTA and the annotation seqnames in sync — the same-m/-papply to both. Outputs land under<outdir>/<name>.{genome.fasta,annotation.gtf}(+.gz,.fai,.genome.sizes, tabix index), plus.skip.gtf(genes that failed checks) and.gene_features_summary.txt.
prepare — spliced transcript reference
Build the spliced transcript reference from a GTF/GFF and a genome FASTA. Two outputs:
-s/--seq-file— the spliced transcript FASTA, the target that reads are aligned to (requires-f).-o/--output-file— the annotation table (TSV: gene/transcript, chrom, strand, spliced exon spans, plus optional codon/genename/biotype/txpos columns), consumed byliftover -a,liftover --table, andannotate --annotation.
coralsnake prepare -g annotation.gtf -f genome.fa \
                   -s transcript.fa -o annotation.tsv \
                   --with-codon --with-genename --filter-biotype protein_coding
liftover — splice-aware BAM conversion
prepare builds the transcript reference; liftover round-trips a BAM between
transcript and genome coordinates, splicing reads at exon boundaries. -a
takes the prepare annotation table; -f (a .fai) is required for t2g:
coralsnake liftover -d t2g(default) — transcript BAM → genome BAM (splices reads at exon boundaries, inserts introns).coralsnake liftover -d g2t— genome BAM → transcript BAM (clips to exons, joins spliced reads contiguously on the transcript).--tablemode converts a tab-separated sites table (instead of a BAM):t2greads a gene column + 1-based transcript position and appendsGenomeChrom/GenomePos;g2treads chrom/position/strand and appendsGene/GenePos.
annotate — exon-aware annotation
Label a site (chrom,pos,strand) with gene/transcript/position + region
(5'UTR/CDS/3'UTR/intronic/intergenic); add a genome FASTA + ref/alt to get the
full variant effect (codon/AA + mut_type). Fast precomputed-table mode via
--annotation <table>.
coralsnake annotate -i sites.tsv -o out.tsv --reference-gtf annotation.gtf -c 1,2,3
coralsnake annotate -i variants.tsv -o effects.tsv \
                    --reference-gtf annotation.gtf \
                    --reference-transcript genome.fa -s -a
# or fast table mode, with the `prepare` annotation table (-o output)
coralsnake annotate -i sites.tsv -o out.tsv --annotation annotation.tsv
metagene — exon-aware metagene profiling
Built on the high-performance polars + ruranges stack. Computes the
distribution of sites relative to gene regions (5'UTR, CDS, 3'UTR) and can emit
binned statistics and a publication-ready profile plot. The -p profile plot
needs the plot extra; the tabular outputs (-o, -s, --export-profile)
work without it. --export-profile FILE writes the machine-readable profile
matrix TSV (feature_type, feature_midpoint, count_*) for downstream tools.
# Using a built-in reference (GRCh38) or a custom GTF:
coralsnake metagene -i sites.tsv.gz -r GRCh38 -H -m 1,2,3 -w 5 \
                    -o output.tsv -s scores.tsv -p plot.png

coralsnake metagene -i sites.bed -g custom.gtf.gz -m 1,2,3 -w 5 \
                    -o output.tsv -s scores.tsv -p plot.png
Manage the built-in references (groups human / mouse are supported;
reference list shows sizes — the metagene --list/--download/--export-*
flags are deprecated aliases):
coralsnake reference list
coralsnake reference download GRCh38        # or: human / mouse / all
One reference download serves every tool — the tools accept the reference
by name and reuse the cached parquet (auto-downloading it if missing);
reference export converts it to text views for external tools:
coralsnake metagene -i sites.tsv -r GRCh38 ...              # uses the parquet directly
coralsnake annotate -i sites.tsv -g GRCh38 -f GRCh38 ...    # cached GTF + linked genome
coralsnake liftover -i tx.bam -o genome.bam -a GRCh38 -f GRCh38 --sort
coralsnake motif -i sites.tsv -f GRCh38 ...
coralsnake reference export GRCh38 --table ref_table.tsv --gtf ref.gtf  # explicit text views
Genome FASTAs are too large to ship in the release, so they are linked:
reference genome <ref> (or reference download <ref> --with-genome)
streams the verified upstream genome (Ensembl/UCSC), decompresses and
indexes it under ~/.cache/coralsnake/genomes/, and cross-checks the FASTA
headers against the reference's contig names.
The reference parquets are served from this repo's fixed data release and
cached in ~/.cache/coralsnake/; rebuild or update them with
scripts/build_references.py
(see scripts/README.md).
Python API — the functions are importable from the flat modules:
from coralsnake.io import load_sites, load_reference
from coralsnake.gtf import load_gtf
from coralsnake.annotation import map_to_transcripts, normalize_positions
from coralsnake.map_to_local import map_to_local
from coralsnake.plotting import plot_profile

sites = load_sites("sites.tsv.gz", with_header=True, meta_col_index=[0, 1, 2])
ref = load_reference("GRCh38")   # or load_gtf("custom.gtf.gz")
annotated = map_to_transcripts(sites, ref)
gene_bins, gene_stats, gene_splits = normalize_positions(
    annotated, split_strategy="median", bin_number=100
)
plot_profile(gene_bins, gene_splits, "metagene_plot.png")

# Map global coordinates to local transcript coordinates (strand-aware):
local = map_to_local(sites, ref, ref_id_col="transcript_id")
qc — RNA-seq quality control
Run the core RNA-seq QC metrics from a genome-aligned BAM + a gene annotation
(ported to lean on coralsnake's GeneModel + ruranges overlap + pysam):
mapping statistics, the exonic / intronic / intergenic / ambiguous / intragenic
read rates, base mismatch, high-quality rates, rRNA rate, sense rates, gene read
counts, TPM, genes detected, 3′ bias, and fragment-size statistics — the last
two derived from the GTF exons + reads, so no BED file is needed.
coralsnake qc -i sample.bam -g GRCh38 -o qc/ -s sample1
# or a custom annotation:
coralsnake qc -i sample.bam -g annotation.gtf -o qc/ -u --stranded RF
-i/--bam— coordinate-sorted SAM/BAM/CRAM.-g/--gtf— gene annotation GTF/GFF, or a built-in reference name (e.g.GRCh38) for the cached GTF.-o/--outdir— output directory;-s/--samplesets the sample name (default: the BAM filename).-u/--unpaired— single-end library (do not require proper pairs).-q/--mapping-quality,--base-mismatch,-d/--detection-threshold— high-quality / detection thresholds (defaults: 255 / 6 / 5, as rnaseqc).--stranded RF|FR— restrict features to the read's strand (strand-specific libraries).--bias-offset/--bias-window/--bias-gene-length— 3′ bias windows (defaults 150 / 100 / 600 bp).--fragment-samples— max fragment-size samples (default 1 000 000).--no-counts— skip the gene/exon count tables.
It writes {sample}.metrics.tsv (Statistic, Value) plus, by default,
{sample}.gene_reads.tsv, {sample}.gene_tpm.tsv, {sample}.exon_reads.tsv,
and — when pairs/mates are present — {sample}.fragmentSizes.txt.
from coralsnake.rnaseqc import run_rnaseqc

metrics = run_rnaseqc("sample.bam", "annotation.gtf", "qc/", sample="s1")
Metrics follow the standard RNA-seq QC definitions. Not ported here: per-gene/per-exon base coverage + CV and GC content (need a FASTA), and the legacy counting rules. 3′ bias and fragment-size statistics are computed from the GTF exons + reads (no BED required).
motif & coordinate
motif— fetch the strand-aware genomic sequence around each site, padded withN(-n left,rightfor asymmetric padding).coordinate— rename chromosome names between reference coordinate systems (built-in UCSC↔Ensembl mappings for hg38/mm39, or a custom-mTSV).
Both migrated from the standalone variant package with unchanged naming and
output format.
# Motif fetch (strand-aware, padded with N)
coralsnake motif -i sites.tsv -o motifs.tsv -f genome.fa -n 2,3 -w

# Chromosome-name mapping (UCSC ↔ Ensembl)
coralsnake coordinate -i sites.tsv -o mapped.tsv -M U2E
from coralsnake.motif import get_motif
from coralsnake.coordinate import run_coordinate
from coralsnake.annotate import run_annotate
group — gene clustering & consensus
Group related genes and build a consensus sequence:
coralsnake group -f genes.fa -g genes.gtf -o grouped.tsv \
                 --output-consensus consensus.fa --threads 8
logo — sequence logo
Builds a DNA/RNA sequence logo from a set of motif sequences. The scoring
engine is pure numpy; only the figure renderer needs matplotlib (plot
extra). --matrix FILE exports the position × base score matrix as TSV
(rows = motif positions, columns = A C G T U + any other symbol present) —
pure numpy, so it works without the plot extra, and the figure is optional
when a matrix is requested.
coralsnake logo -m ACGT -m ACGG -m CCGT -o logo.png
# or with per-motif weights from a file (seq\tcount)
coralsnake logo -i motifs.tsv -o logo.svg
# or export just the position x base score matrix as TSV (no plotting needed)
coralsnake logo -i motifs.tsv --matrix logo_scores.tsv
from coralsnake import Mlogo

m = Mlogo(motifs=["ACGT", "ACGG", "CCGT"], to2bit=True)
m.plot(ax)  # requires matplotlib (plot extra)
Performance
The core is built on the vectorized polars + ruranges stack, using Rust-backed
ruranges primitives instead of slow per-group Python applies:
map_to_transcriptspicks the best transcript per gene with a vectorized sort +group_by().first()(wasgroup_by().map_groups()python apply) — ~20× faster on realistic inputs.map_to_localusesruranges.numpy.group_cumsumfor strand-aware cumulative transcript offsets (was a hand-rolledmap_groupsapply) — ~7× faster.Mlogo(sequence logo) builds its score matrix with vectorizednumpy(bincount+ codepoint lookup) — ~1.5× faster and fixes a0·log2(0)NaN edge case.
Documentation
- Architecture & Design — package layout and design decisions.
- Full docs site: https://coralsnake.yech.science/ (see
docs/).
Mapping is out of scope. Nucleotide-conversion (two-color / three-color) mapping is not part of coralsnake any more: it lives in the dedicated
prismalignpackage (pluggable backends: bwamem, minimap2/mappy, pure-Python), on top of the lightweightbwamemBWA-MEM binding.
1 maintainer

Metadata
1 maintainer
Release files for coralsnake 0.2.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| coralsnake-0.2.6.tar.gz | 168.7 kB | Details |
Built distributions (wheels)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| coralsnake-0.2.6-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl | CPython 3.13 | CPython 3.13 | Linux glibc 2.17+ x86-64 | Details |
| coralsnake-0.2.6-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl | CPython 3.12 | CPython 3.12 | Linux glibc 2.17+ x86-64 | Details |
Total release size: 460.2 kB
Release files / coralsnake-0.2.6.tar.gz
| Download URL | coralsnake-0.2.6.tar.gz |
|---|---|
| Size | 168.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
45e75d62abcd7645b7b5ff86e21119938526c84103a97dc4ad754a7d7d30fc29
|
|
BLAKE2b-256 checksum How to use checksums |
8511eda7da033d2fc62a2eb0ce68c25a4172bc3856b7b8af3d14a7795cff419a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / coralsnake-0.2.6-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | coralsnake-0.2.6-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 145.7 kB |
| Tags | CPython 3.13 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
aa8eae954c6895f6cbb0f971b068926b822a6f97a43e1b2944dabfe7a68123a3
|
|
BLAKE2b-256 checksum How to use checksums |
66d1b695e95132df176ee77acf7e8e4d4da15499394535917a90eb331597d369
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / coralsnake-0.2.6-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | coralsnake-0.2.6-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 145.7 kB |
| Tags | CPython 3.12 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
ef80850ff15f340c08810d86260957949c691ef1babcd94b2bbc97970063526a
|
|
BLAKE2b-256 checksum How to use checksums |
a2a9d6cd15c4f945a08417476718ae525201b28485e5e4bee3bdd59fe45442bc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|














