
CostOpt — Developer-Native LLM Cost Intelligence ⚡
Drop-in wrapper for OpenAI, Anthropic & Gemini clients that adds automatic caching, smart model routing, circuit breaker protection, and a real-time observability dashboard — all 100% local.
Stop waiting for a $500 monthly cloud bill to figure out where your LLM budget went.



⚡ Overview
The Problem
Generative AI applications frequently overspend by:
- Executing Duplicate Requests: Re-querying upstream APIs for exact or near-identical prompts.
- Over-provisioning Models: Routing simple classification, extraction, or short summarization queries to expensive flagship models (e.g.,
gpt-4o,claude-3-5-sonnet) when lower-cost models (gpt-4o-mini,claude-3-haiku,llama3,deepseek-r1) satisfy accuracy requirements. - Lack of Cost Visibility: Difficulty tracking net savings, model breakdown, or request-level optimization decisions.
The CostOpt Solution
CostOpt acts as a transparent, drop-in SDK interceptor and decision engine that:
- Serves exact-match prompt hits in <1ms p50 (SHA-256 hash lookup); fuzzy near-duplicate hits in ~7ms p50 (bounded to 50 most recent entries) — both at $0.00 cost via a local SQLite cache.
- Analyzes request intent and complexity to automatically route simple tasks to cost-effective models.
- Enforces quality guardrails and automatic outage failovers.
- Records unified FinOps telemetry displayed on a real-time web console.
🔌 1-Line Zero-Churn Integration
# ─── BEFORE (Standard OpenAI Client) ────────────────────────────────────────
from openai import OpenAI
client = OpenAI()

# ─── AFTER (With CostOpt — zero other changes needed) ───────────────────────
from openai import OpenAI
from costopt import CostOpt

client = CostOpt(OpenAI())  # 👈 Intercepts transparently

# Your API calls are 100% identical — CostOpt automatically analyzes, caches, & routes:
response = client.chat.completions.create(
    model="gpt-4o",
    messages=[{"role": "user", "content": "Classify customer feedback: Great product!"}]
)
print(response.choices[0].message.content)
⚡ Core Features
| Feature | Description |
|---|---|
| 🗄️ Multi-Tier Prompt Cache | Tier 1 exact SHA-256 hash matching (<15ms, $0.00) + Tier 2 local TF-IDF cosine vector similarity matching. Includes parameter hashing (temperature, tools, response_format, seed). Enforces 100% exact cache safety whenever function tools or structured JSON outputs are present. |
| 🤖 Agent-Aware Attribution | Track spend, tokens, and circuit-breaking per agent node using thread-safe context scoping (with costopt.scope(agent="Researcher") or @costopt.track(agent="Writer")). Automatically filters out library frames (LangChain, CrewAI, AutoGen). |
| ⚡ Native Prefix Caching | Automatically tracks provider prompt caching (OpenAI prompt_tokens_details.cached_tokens, Anthropic cache_read_input_tokens) and applies 50%–90% discounts directly into pricing telemetry. |
| 🎯 Routing Strategy Profiles | Support for fidelity_first (preserves flagship models for complex reasoning & creative workflows; zero quality compromise), balanced (default), and aggressive (cost-optimized). |
| 🧠 Intelligent Decision Engine | Classifies prompts into 7 task categories (simple_classification, extraction, summarization, coding, reasoning, creative_generation, general_chat) with confidence scoring. |
| 🔀 Policy-Aware Model Router | Rule-based keyword and task-complexity routing — simple tasks auto-rerouted to efficient models (gpt-4o ➔ gpt-4o-mini / deepseek-r1). |
| 🛡️ Agent-Aware Circuit Breaker | Detects call velocity loops keyed on (agent, step) or file/line location and trips CostOptCircuitBreakerError to prevent runaway agent bills. |
| 🔄 Outage Failover | Auto-retries fallback models on 429/503 errors (gpt-4o ➔ claude-3-5-sonnet ➔ llama3). |
| 📊 Observability & FinOps Console | Premium dark-mode dashboard (#050505 canvas, fixed left sidebar, bento grid layout) for Overview, Spend, Optimizations, Requests, and Policies. |
| 🔍 Decision Intelligence Traces | Step-by-step visual trace flow explaining every request analysis, cache evaluation, and routing decision. |
| 🖥️ VS Code Extension | Inline CodeLens cost per request, call counts, hover panels, and status bar metrics directly inside VS Code. |
| 🔒 100% Local & Private | Stored in local SQLite (costopt_telemetry.db, costopt_cache.db). Zero data leaves your machine. |
🏗️ Architecture

💡 Interactive Canvas: Click the diagram above or open
docs/images/costopt-architecture.htmlto interactively explore the Signal Flow canvas with guided tour views (01 Request Interception,02 Intelligent Decision Engine,03 Observability & FinOps), filter by component layers, and inspect real-time routing paths.
🚦 Optimization Decision Flow
Every request is evaluated by the centralized DecisionEngine and assigned one of four execution outcomes:
| Decision | Condition | Execution Path |
|---|---|---|
CACHE |
Prompt matches an existing exact or semantic entry in costopt_cache.db. |
Returned locally in <15ms ($0.00 cost). |
REROUTE |
Cache miss; task is low/medium complexity, confidence >= 0.70, and a cheaper capable model exists. | Routed to cost-effective target model (e.g., gpt-4o ➔ gpt-4o-mini). |
DIRECT |
Cache miss; high-complexity reasoning/coding task or low confidence (<0.70). | Executed using original requested model for maximum accuracy. |
FALLBACK |
Primary model endpoint fails or circuit breaker indicates outage. | Auto-failed over to secondary fallback model. |
🚀 Quickstart Guide
Step 1 — Install Python SDK
pip install costopt
Step 2 — Wrap your LLM client
from openai import OpenAI
from costopt import CostOpt, scope, track

client = CostOpt(OpenAI())

# Standard call (transparent cost routing & exact caching):
response = client.chat.completions.create(
    model="gpt-4o",
    messages=[{"role": "user", "content": "Classify sentiment: This product is outstanding!"}]
)
print(response.choices[0].message.content)

# Multi-Agent Attribution (LangGraph, CrewAI, AutoGen):
with scope(agent="MarketResearcher", run_id="workflow-01"):
    client.chat.completions.create(
        model="gpt-4o",
        messages=[{"role": "user", "content": "Analyze competitor landscape"}]
    )
Step 3 — Launch the Observability Dashboard
costopt dashboard
# Or run via Python module:
python -m costopt.main dashboard
Open http://127.0.0.1:8400 in your browser.
📊 Observability Dashboard
The web console features a modern dark-mode aesthetic (#050505 canvas, translucent borders, ambient glows, fixed left sidebar shell, and bento grid layout) across 5 primary navigation tabs:
1. Overview
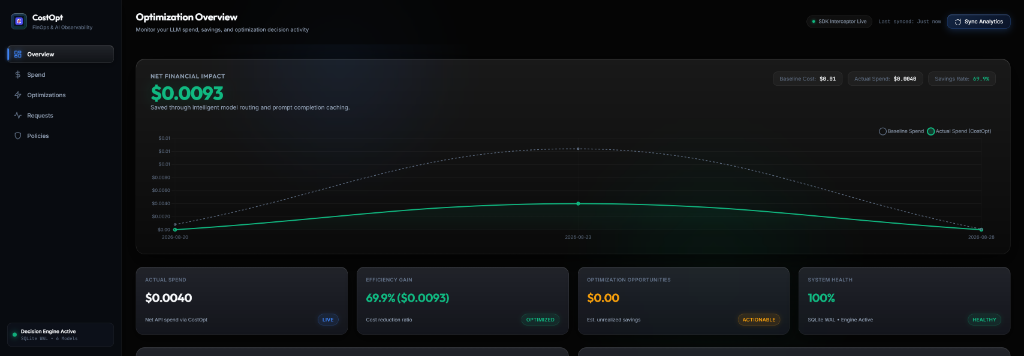
Net Financial Impact Hero Glass Card (dynamic total savings), smooth spend trend area chart, bento metrics grid (Actual Spend, Efficiency Gain, Optimization Opportunities, Cache Hit Rate — live % of calls served from local cache, color-coded green/yellow/blue), top recommendation card, and live telemetry feed.
2. Spend Analytics
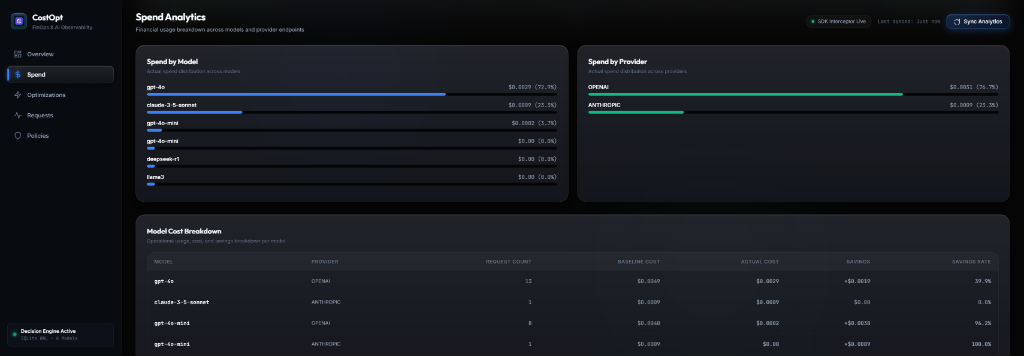
Actual LLM spend hero card with baseline comparison, spend by model/provider bento distribution cards, and sortable model cost breakdown table.
3. Optimizations Engine
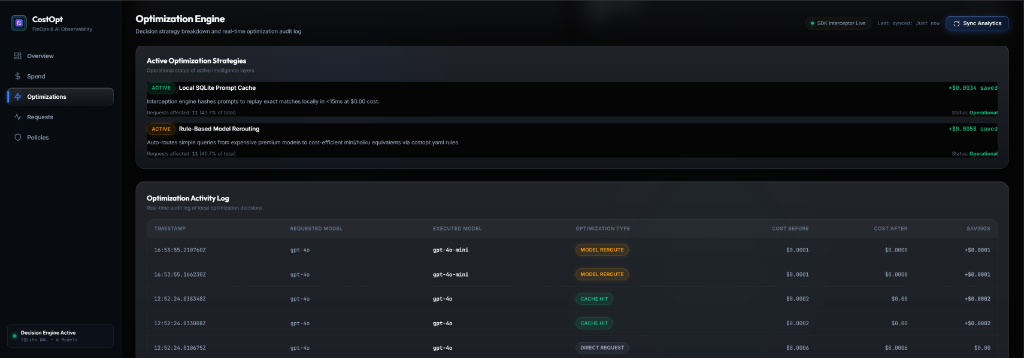
Active optimization strategy status cards (Local SQLite Cache, Rule-Based Model Rerouting), total net savings per strategy, and real-time optimization decision activity log.
4. Requests Explorer & Decision Intelligence Trace
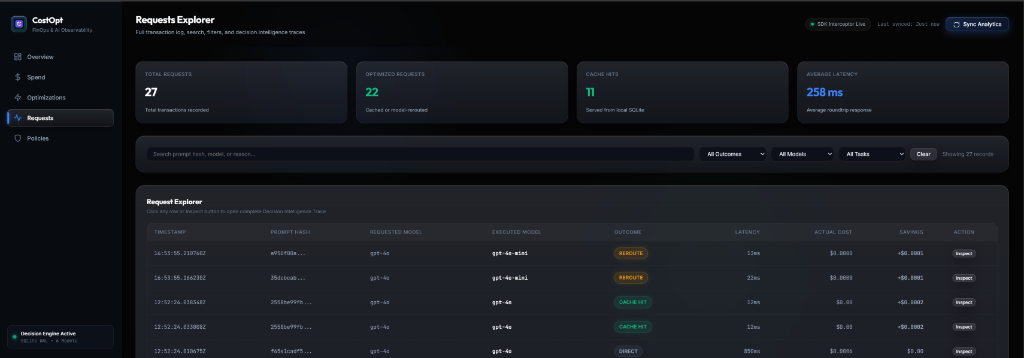
Request explorer transaction log table with prompt search, outcome filter badges (
CACHE HIT,REROUTE,DIRECT), and Request Inspection Drawer displaying step-by-step Decision Intelligence Traces.
5. Policies Configuration
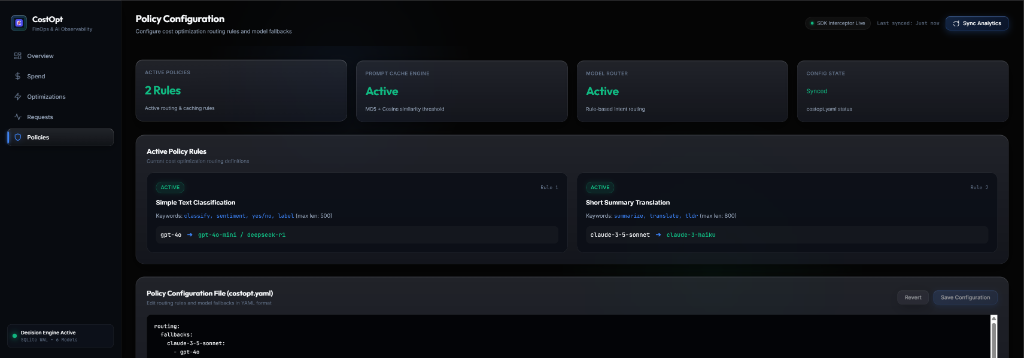
Active policy rules visual cards (
Requested Model ➔ Target Model), model routing map, livecostopt.yamlpolicy editor with unsaved state detection, save/revert options, and cache/telemetry management.
🌐 Multi-Provider Support
CostOpt supports wrapping OpenAI, Anthropic, and Google Gemini clients:
# OpenAI
from openai import OpenAI
from costopt import CostOpt

client = CostOpt(OpenAI(), provider="openai")

# Anthropic
import anthropic
from costopt import CostOpt

client = CostOpt(anthropic.Anthropic(), provider="anthropic")

# Google Gemini (via OpenAI-compatible API)
from openai import OpenAI
from costopt import CostOpt

client = CostOpt(
    OpenAI(api_key="...", base_url="https://generativelanguage.googleapis.com/v1beta/openai/"),
    provider="google"
)
Supported pricing catalogs: OpenAI, Anthropic, Google Gemini, HuggingFace, Ollama (local, $0.00).
📦 Integration with Popular Frameworks
LangChain:
from langchain_openai import ChatOpenAI
from costopt import CostOpt
from openai import OpenAI

llm = ChatOpenAI(client=CostOpt(OpenAI()).client)
LlamaIndex:
from llama_index.llms.openai import OpenAI as LlamaOpenAI
from costopt import CostOpt
from openai import OpenAI

llm = LlamaOpenAI(client=CostOpt(OpenAI()).client)
FastAPI:
from fastapi import FastAPI
from openai import OpenAI
from costopt import CostOpt

app = FastAPI()
ai_client = CostOpt(OpenAI())
🔧 Configuration Guide (costopt.yaml)
CostOpt reads a costopt.yaml file from your working directory at startup. If no file is found, a commented template is auto-generated for you.
The config has two jobs:
- Routing Rules — fire before the API call to proactively reroute to a cheaper model
- Fallback Chains — fire after an API failure to automatically retry on a different model
Full Config Structure
routing:
  strategy: "balanced"             # Strategy profile: "fidelity_first" | "balanced" | "aggressive"
  fallbacks:
    <your-primary-model>:
      - <fallback-model-1>
      - <fallback-model-2>

  rules:
    - name: "Human-readable label shown in dashboard"
      keywords: ["word1", "word2"]   # trigger if ANY keyword found in prompt
      max_prompt_length: 500         # only trigger for short prompts (chars)
      original_model: "gpt-4o"      # only apply if THIS model was requested
      target_model: "gpt-4o-mini"   # reroute to this cheaper model instead

alerts:
  enabled: false
  daily_budget_usd: 10.00
  monthly_budget_usd: 50.00
  cooldown_minutes: 60
  slack_webhook_url: ""
Routing Strategy Profiles
You can select a strategy in costopt.yaml or directly in code via CostOpt(client, strategy="fidelity_first"):
fidelity_first: Prioritizes response quality and accuracy. Preserves requested flagship models (gpt-4o,claude-3-5-sonnet) for reasoning, coding, analysis, and creative tasks. Rerouting is only applied to trivial/simple tasks.balanced(Default): Automatically routes tasks to the most cost-effective model capable of handling the detected task complexity.aggressive: Maximizes cost savings by routing to low-cost models wherever possible.
Note: All fields in
rulesare optional. A rule with nooriginal_modelmatches any model. A rule with nokeywordsmatches any prompt within the length limit.
Provider Examples
Pick the providers you are using and copy the relevant fallback chains.
OpenAI
routing:
  fallbacks:
    gpt-4o:
      - gpt-4o-mini       # 10x cheaper, same provider
    gpt-4o-mini:
      - gpt-4o            # escalate up if mini can't handle it
    gpt-4:
      - gpt-4o
      - gpt-4o-mini

  rules:
    - name: "Route short/simple tasks to mini"
      keywords: ["classify", "yes/no", "sentiment", "label", "extract", "summarize"]
      max_prompt_length: 800
      original_model: "gpt-4o"
      target_model: "gpt-4o-mini"
Anthropic (Claude)
routing:
  fallbacks:
    claude-3-5-sonnet:
      - claude-3-haiku    # 5x cheaper
    claude-3-opus:
      - claude-3-5-sonnet
      - claude-3-haiku
    claude-3-haiku:
      - claude-3-5-sonnet # escalate if needed

  rules:
    - name: "Simple tasks — sonnet to haiku"
      keywords: ["classify", "extract", "translate", "summarize"]
      max_prompt_length: 600
      original_model: "claude-3-5-sonnet"
      target_model: "claude-3-haiku"
Google Gemini
routing:
  fallbacks:
    gemini-1.5-pro:
      - gemini-1.5-flash  # much cheaper
    gemini-1.5-flash:
      - gemini-1.5-pro    # escalate on failure

  rules:
    - name: "Extraction tasks — pro to flash"
      keywords: ["extract", "list", "bullet", "summarize", "tldr"]
      max_prompt_length: 1000
      original_model: "gemini-1.5-pro"
      target_model: "gemini-1.5-flash"
Ollama (Local / $0.00)
routing:
  fallbacks:
    llama3:
      - mistral           # another local model
      - gpt-4o-mini       # cloud fallback if local fails
    qwen2.5:0.5b:
      - llama3
    mistral:
      - llama3
      - gpt-4o-mini
Cross-Provider (Mixed Stack)
# If your primary cloud model fails, fall back to a different provider entirely:
routing:
  fallbacks:
    gpt-4o:
      - claude-3-5-sonnet   # cross-provider failover
      - gemini-1.5-flash
      - llama3              # local zero-cost last resort
    claude-3-5-sonnet:
      - gpt-4o
      - gemini-1.5-flash
    gemini-1.5-flash:
      - gpt-4o-mini
      - llama3
🚨 Outage Scenario Walkthrough
Here is what happens when OpenAI hits a rate limit during a production spike:
Your app calls:  client.chat.completions.create(model="gpt-4o", ...)
         │
         ▼
CostOpt intercepts → checks cache → MISS
         │
         ▼
Calls gpt-4o  ──►  429 Rate Limit Error
         │
         ▼
Reads fallbacks for "gpt-4o" from costopt.yaml:
  1st: claude-3-5-sonnet  →  ✅ success — response returned
         │
         ▼
Logs to telemetry: model_requested=gpt-4o, model_used=claude-3-5-sonnet
Dashboard shows: FALLBACK decision, $0 wasted on the failed call
Your code sees zero errors. The exception is swallowed by CostOpt's retry loop and the next available model responds transparently.
To set this up, add to your costopt.yaml:
routing:
  fallbacks:
    gpt-4o:
      - claude-3-5-sonnet   # cross-provider, catches OpenAI outages
      - gemini-1.5-flash    # Google backup
      - llama3              # local offline last resort
Routing Rules: When Do They Fire?
Rules fire proactively — before the API call, the moment CostOpt intercepts your request.
| Field | Behavior |
|---|---|
original_model |
Only apply this rule if the caller requested exactly this model |
keywords |
Rule triggers if any one keyword appears anywhere in the prompt text |
max_prompt_length |
Rule only triggers if the combined prompt is shorter than this (in characters) |
target_model |
The cheaper model to call instead |
All three conditions must pass for the rule to fire. If no rule matches, the original model is used.
Resetting Telemetry & Cache
costopt export                          # export all telemetry to CSV (auto-named)
costopt export --last 7                 # last 7 days only
costopt export --format json            # JSON instead of CSV
costopt export --output report.csv      # custom output filename
costopt reset-all                       # wipe both telemetry logs + prompt cache
costopt clear-telemetry                 # wipe only the activity log
costopt clear-cache                     # wipe only the prompt cache
Or via the dashboard at Settings → Policies tab → Reset buttons.
🖥️ VS Code Extension
Prerequisites: The extension requires the CostOpt Python package installed separately. Install it first:
pip install costoptThen start the local server with
costopt dashboard --port 8400before using the extension features.
Install the CostOpt extension from the VS Code Marketplace or Open VSX Registry.
Features:
- 📍 CodeLens Inlines — cost per request, avg tokens, call count directly above
client.chat.completions.create()lines - 💬 Hover Panels — full cost breakdown + MD5 hash + cache status on hover
- 📈 Sidebar Views — Spend Forecast, Feature Attribution, Cost Drift Warnings
- 📌 Status Bar —
CostOpt: $8.42 todaylive in VS Code bottom bar
🧪 Testing
Run the automated Pytest test suite:
python -m pytest tests/ -v
Test Status: All 27 test cases pass cleanly (100% pass rate).
❓ FAQ
Q: Does CostOpt send my prompts or data to external servers?
No. 100% local. All telemetry, cache, and pricing data is stored in local SQLite files (
costopt_telemetry.db,costopt_cache.db). Zero data leaves your machine.
Q: Does it add latency to my LLM calls?
No. Prompt hashing and cache checks take under 1ms. Telemetry is written asynchronously in a background thread.
Q: What does a cache hit cost?
$0.00. Cached responses are replayed locally in under 15ms without hitting paid provider APIs.
Q: Does it work with LangChain / LlamaIndex / FastAPI?
Yes. Pass the wrapped client (
CostOpt(OpenAI()).client) into any framework that accepts a raw OpenAI client object.
Q: How does fuzzy/semantic cache matching work?
CostOpt uses TF-IDF word and character n-gram cosine vector similarity. Pass
similarity_threshold(e.g.,0.90) to theCostOpt()constructor to enable near-duplicate matching — prompts that are 90%+ similar will return the cached response without an API call.
Q: How do I reset all telemetry to start fresh?
Click Reset Telemetry Analytics on the Policies tab in the dashboard console.
📄 License
This project is licensed under the MIT License. See LICENSE for details.
Built for developers who want to ship fast and spend smart. 100% open source.
1 maintainer

Metadata
1 maintainer
Release files for costopt 0.2.17
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| costopt-0.2.17.tar.gz | 415.4 kB | Without provenance | Details for costopt-0.2.17.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| costopt-0.2.17-py3-none-any.whl | Python 3 | none | any | Details for costopt-0.2.17-py3-none-any.whl |
Total release size: 477.0 kB
Release files / costopt-0.2.17.tar.gz
| Download URL | costopt-0.2.17.tar.gz |
|---|---|
| Size | 415.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6e729d485ee2e4a31f0095390eef0975f2bc563d0186b783a23f8a5fe406c57e
|
|
BLAKE2b-256 checksum How to use checksums |
d9cb6cc7e1dcb75d8fe37c056d0506ccbc679cdbeabfce504c5fffa1a7c35c6e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.3
|
Release files / costopt-0.2.17-py3-none-any.whl
| Download URL | costopt-0.2.17-py3-none-any.whl |
|---|---|
| Size | 61.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a22868cde9677c1e63a7295cf5924915fab76666a43a4c83f0847fad06810318
|
|
BLAKE2b-256 checksum How to use checksums |
1a984ca94e6f2d607879527888e1cb60c6eebac4076c886ef36756ab30056eaf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.3
|
Security for costopt 0.2.17
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














