
This release is a pre-release and may not be stable for production use.
 FactBlock: agent memory for decisions



A temporal causal knowledge graph that remembers when and why for your AI.
Your data is full of claims: facts, opinions, predictions, promises. FactBlock extracts them, keeps when they were said and when you learned them, links what caused what, and never overwrites what changed. Your agent recalls them as of any moment, so it decides on what was knowable then, not on hindsight.
pip install --pre factblock                           # alpha: --pre until 1.0
factblock sample brain/                               # six dated claims, a reversal, three verdicts
factblock scan brain/ --as-of 2024-05-01              # what was known that day, and what was hidden
factblock recall brain/ "interest rates" --as-of 2024-05-01   # the blocks about something, as of that day
factblock why brain/ c3 --as-of 2024-10-01            # the causal chain behind a block
factblock resolve brain/ belief:fed:direction --as-of 2024-10-01
factblock extract transcript.txt --observed-at 2024-03-20 --speaker "Jim Cramer" --backfill -o brain/   # your model key, or --provider fake
$ factblock why brain/ c3 --as-of 2024-10-01
subject: c3  2024-06-20  Housing demand falls as mortgages track yields
    cause (CAUSES): c2  2024-04-10  Bond yields rise after the rate hike
        cause (CAUSES): c1  2024-03-20  The Fed raises interest rates
            successor (SUPERSEDES): c4  2024-09-18  The Fed cuts interest rates
as of 2024-10-01  hidden: nothing  backfilled: 4 rows in 3 batches
Run the same command --as-of 2024-05-01 and the chain stops at c2, because c3 was not known yet. Add --json to any read for the machine form.
import factblock
print(factblock.context("brain/", "interest rates", as_of="2024-10-01"))
# - 2024-09-18: The Fed cuts interest rates
# - 2024-03-20: The Fed raises interest rates (learned 2024-04-15)
#   replaced 2024-09-18 by: The Fed cuts interest rates
#   verdict: true (decided 2024-05-01 by process:tckg-resolver)
# - 2024-04-10: Bond yields rise after the rate hike (learned 2024-04-15)
# (as of 2024-10-01; 1 later block hidden)
That string goes into your agent's prompt. The old claim is still there, marked as replaced, with the verdict it had as of that day; ask as_of="2025-01-01" and the verdict reads false, because it was re-resolved in December. A date filter would show both claims side by side with nothing to say which one stands. examples/support-agent runs five support questions both ways: a date filter puts a stale answer into the prompt on all five, FactBlock on none. factblock.recall(...) returns the same blocks as dicts with a certificate, and factblock.scan(...) returns everything visible as pyarrow tables.
brain/ is a folder of plain files. Commit it to git, query it with DuckDB, hand it to another agent, or sync it with a hosted ledger. Nothing here needs a server.
What comes out
Two years of one public figure's statements, as files. samples/cramer is Jim Cramer on CNBC, 2024-09 to 2026-09: 2,091 blocks, 1,169 links he drew between them, 779 priced calls scored at their horizon. Every block links to the recording and the timestamp.
$ factblock scan samples/cramer --as-of 2025-01-01 | head -1
as of 2025-01-01  hidden: 1775 nodes, 1025 edges, 753 resolutions  not in force: 15 nodes  backfilled: 471 rows in 52 batches

$ factblock why samples/cramer 1b77a1a885470207 --as-of 2026-09-10
subject: 1b77a1a885470207  2025-07-17  The current data center buildout is the largest construction boom since World War II.
    effect (CAUSES): c43aac6a842836bf  2025-07-17  Lead contractors such as ABB and Legrand are receiving strong data center orders.
        effect (CAUSES): 041ef1dfd5dbb6df  2025-07-17  Companies involved in the data center buildout, such as Eaton and Parker-Hannifin, are receiving a large number of new orders.
            effect (CAUSES): 2751ba237ecd5415  2025-07-17  Parker-Hannifin is a good stock to own.
            effect (CAUSES): 7d3af08ba4f4f027  2025-07-17  Eaton is a good stock to own.
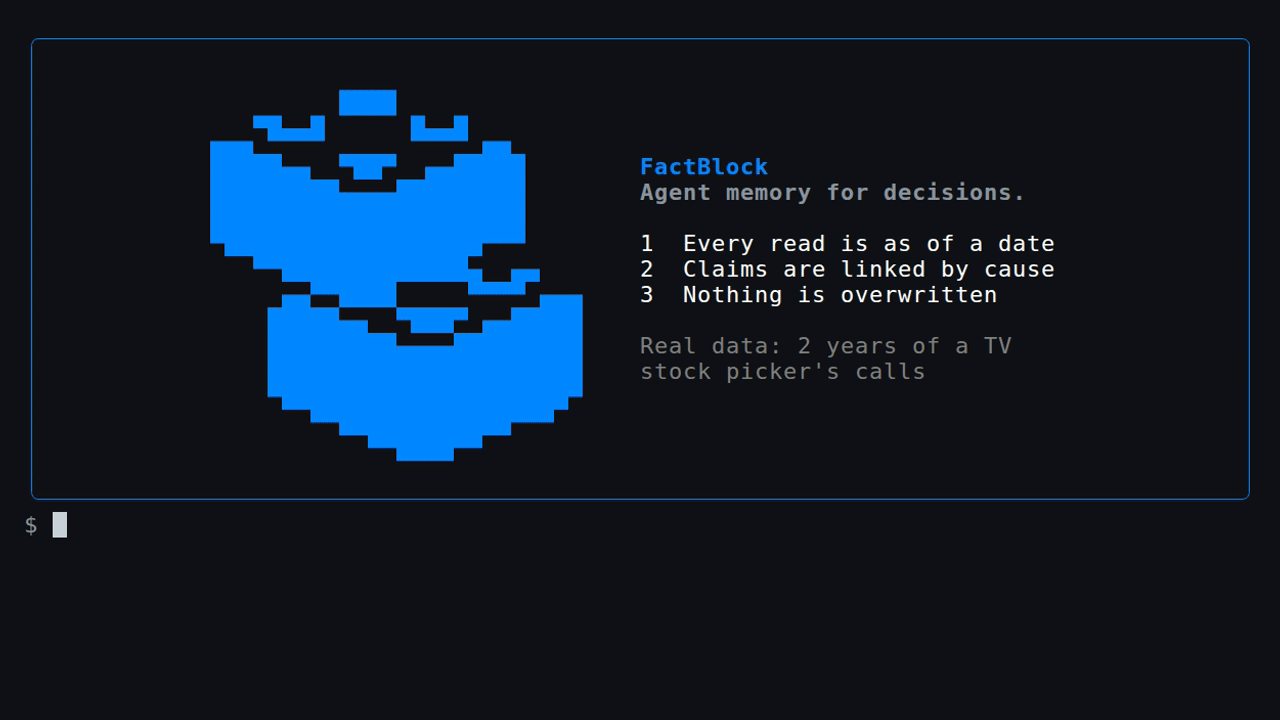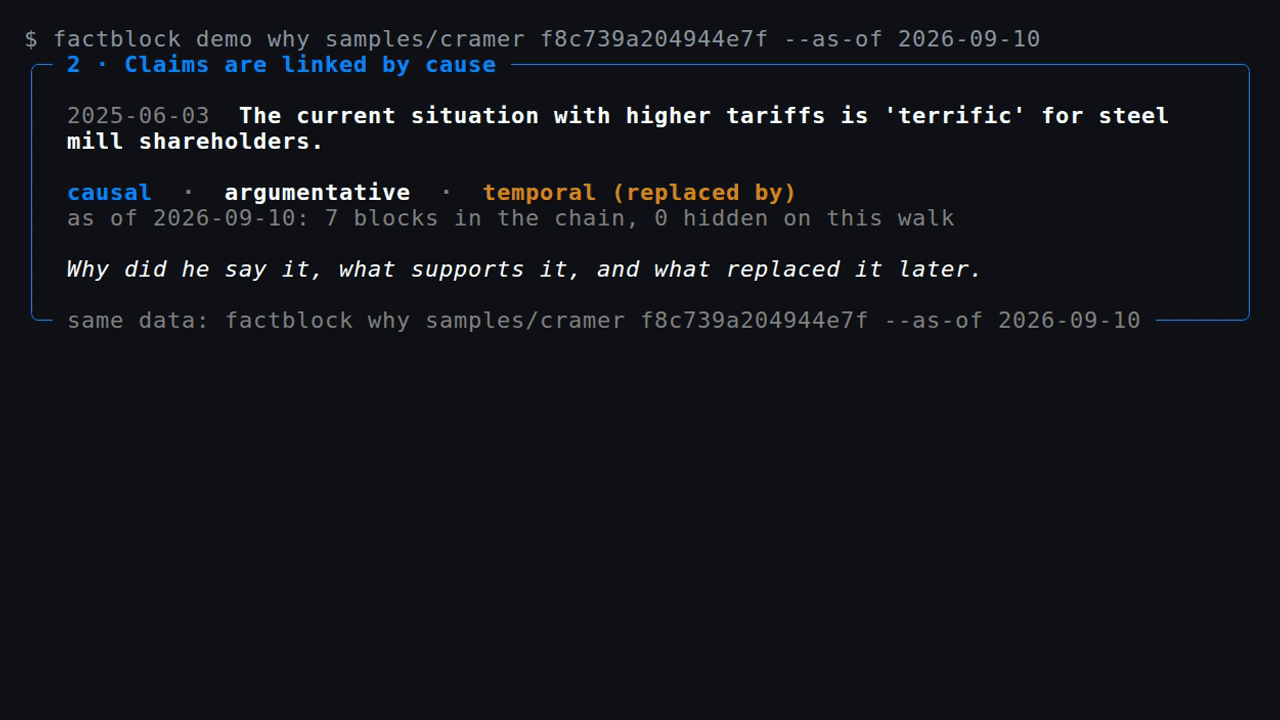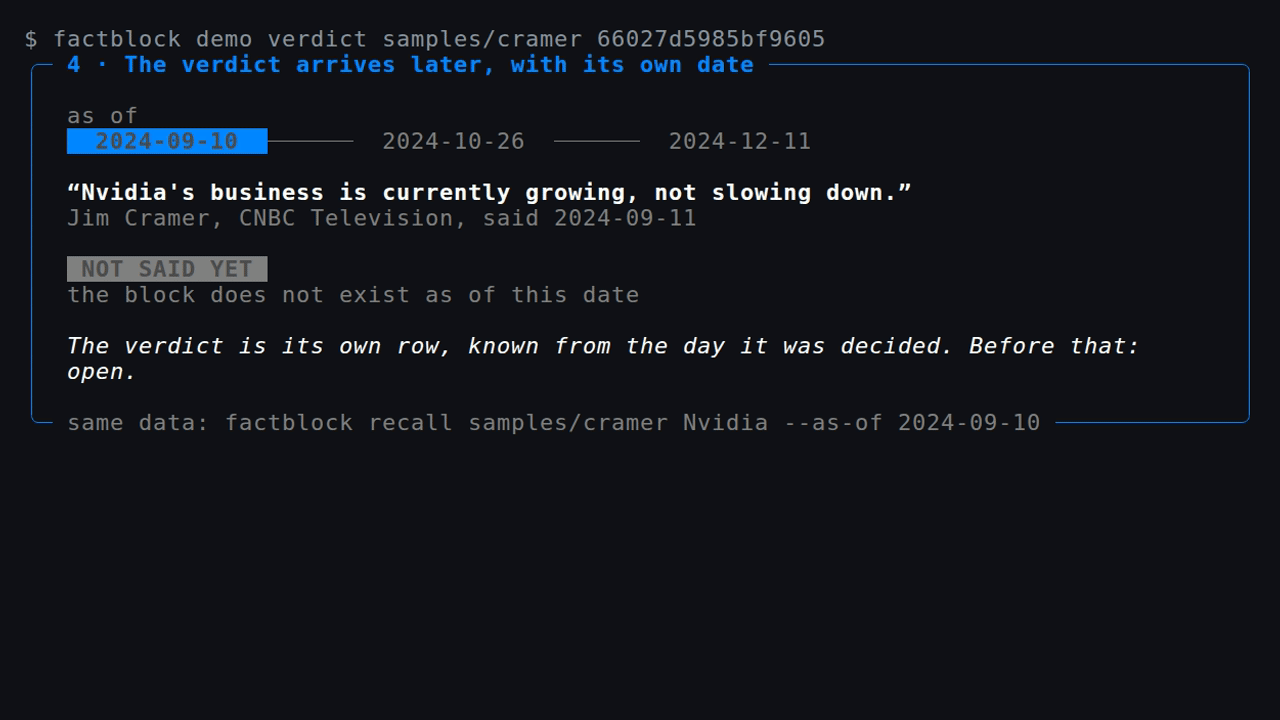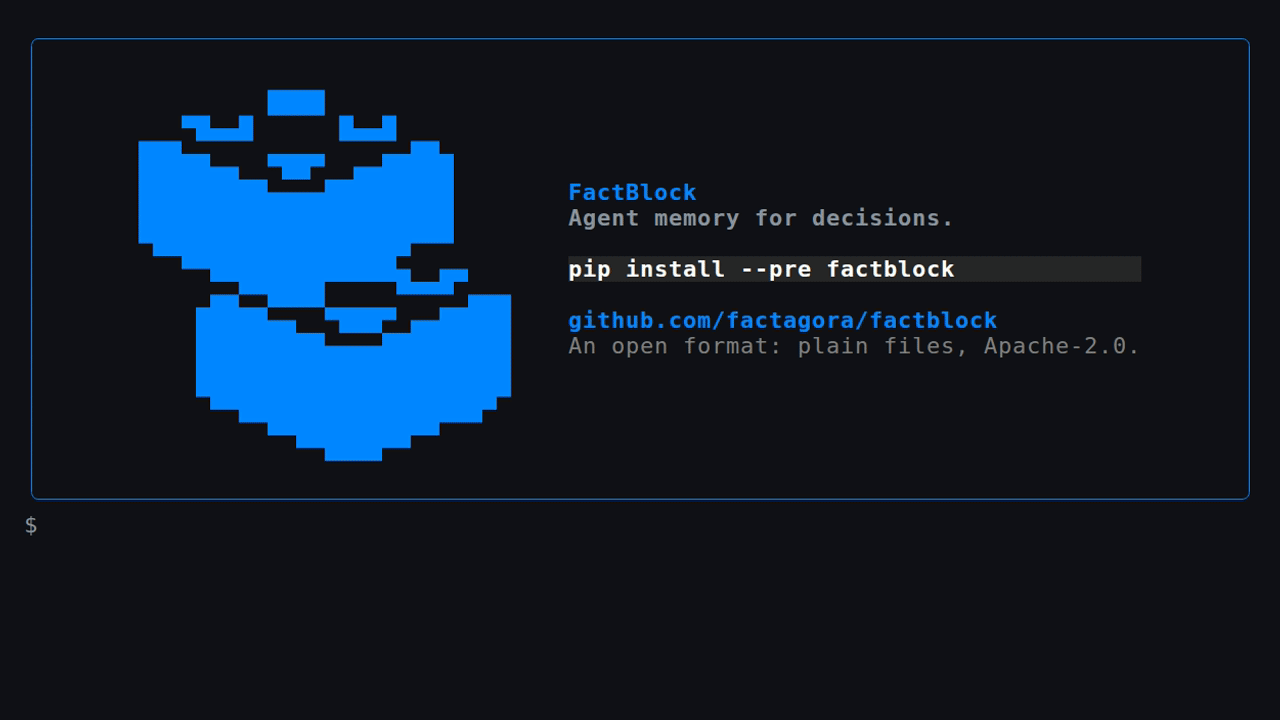
A call and its verdict carry separate clocks, so the same read gives different answers on different days:
66027d5985bf9605  prediction  2024-09-11  Nvidia's business is currently growing, not slowing down.   NVDA, up
  verdict: came_true   decided 2024-12-10   NVDA +23.3% over 90 days   known 2024-12-10
As of 2024-11-01 the call is open. As of 2024-12-10 it came true. As of 2024-09-10 it does not exist yet. to-claimreview samples/cramer --as-of 2025-06-01 writes the 197 verdicts known by then as schema.org JSON-LD.
Every block carries two clocks: asserted_at, when it was said (--observed-at for extract), and known_at, when your system learned it. By default that is now, so a 2024 transcript extracted today is hidden from a 2024 read; --backfill declares it known when it was said, which is what you want for material from the past. --provider fake splits sentences without a model, enough to see the files; gemini and openai do the real extraction with your key. Every edge carries a type with a family (causal, argumentative, temporal) and the speaker's own confidence. Nothing is a chunk, nothing is a bare triple; the unit is a dated statement someone made.
When
Memory that cannot answer "what did I know on that date" leaks the future into every evaluation and every backtest. FactBlock reads are always as of an instant:
import factblock
r = factblock.scan("brain/", as_of="2024-05-01")
r.nodes                 # pyarrow.Table: only blocks known by 2024-05-01
r.certificate           # {'as_of': ..., 'masked': {'node': 4, 'edge': 2}, 'backfill': {'batches': 1, 'rows': 3}}
The certificate says how many rows were hidden because they were learned later, and which rows were backfilled from the past under a declared batch. An answer with masking is a correct answer for that instant, and it says so.
A statement that gets corrected or reversed is not overwritten. The new block points at the old one with SUPERSEDES, both keep their intervals, and a read as of a date in between still sees the old one. That is how "when did they change their mind" stays answerable.
Why
Edges are the speaker's reasoning, not co-occurrence: CAUSES, CONTRIBUTING_FACTOR, TRIGGERS, PREVENTS, SUPPORTS, CONTRADICTS, CONCURRENT_SIGNAL, SUPERSEDES. why walks them from a block to the given depth, as of an instant, and names the role at every hop (cause, effect, successor, contradiction), so the chain never includes a reason that was not yet known.
Declared facts make conflicts explicit. Declare belief:fed:direction with a policy (latest_valid, latest_observed, source_priority, strict) and resolve returns one value or the reason there is none: no_data, not_yet, no_value_at, unresolved_conflict. It never guesses.
Claims it is good at
| Kind | Example | What you can ask that other memories cannot |
|---|---|---|
| Prediction | "Yields keep climbing this year" (podcast, 2024-03-20) | What did this person believe on 2024-03-20? Did it come true? When did they say the opposite? |
| Stance | CEO: "No price increase this year" (Jan), "An increase is unavoidable" (Jul) | How did the company's position move? What did we know in May? |
| Fact that gets corrected | "Q2 revenue was $4.1B", restated to $3.9B six weeks later | resolve as of August gives $4.1B, as of October $3.9B, as of July no_data |
| Commitment | Sales: "We ship SSO by end of Q3" (to customer A) | Which promises to A are past due and unresolved? Recall them before the support agent answers |
| Your AI's own assertions | Assistant: "Your plan includes 10 seats" (to user B) | Which of last month's assertions are now false? Where did each one come from? |
The common thread: a claim has a speaker, a time, a reason, and a later verdict. RAG keeps chunks, entity graphs keep triples, chat memories keep summaries. None of them keep that.
Use it with your AI
Recall as context. recall ranks the visible blocks about a query (keywords over statement, quote and speaker) and context turns them into prompt lines, with as_of set to the decision time (now, or a past instant for a backtest). scan returns everything visible as Arrow tables when you want to build your own.
Analytics. to-parquet writes the Parquet profile. DuckDB reads it with no Python through duckdb/factblock.sql: factblock_nodes(bundle, as_of), factblock_edges, factblock_certificate. Spark and Databricks read the same files.
From an existing graph. factblock/adapters/graphiti.py turns a Graphiti graph into a bundle; the store's own timestamps become declared backfill batches, because a store that stamped time itself is a witness.
Speak the standards. to-claimreview writes the verdicts visible as of an instant as schema.org ClaimReview JSON-LD; to-okf writes the blocks as an Open Knowledge Format bundle (markdown with frontmatter) that catalogs and agents read; from-factcheck brings published fact-checks in (Google's Fact Check Tools API shape) as dated claims with dated verdicts, every row under a batch declared at its review date. None of them is the storage format; they are doors.
Check your evals. leak takes a question set with dates ({asked_at, evidence: [block ids]} per line) and reports how many answers depend on blocks learned after the question's date, naming each block and when it became known. It exits non-zero on a leak, so it fits in CI. On StreamingQA (36,378 dated questions about dated news), a recall that ignores time rests on a block learned after the question for 80% of questions; the same recall as of the question date leaks nothing and says how much it hid. If your memory benchmark never reports this number, it is measuring hindsight.
For coding agents
The whole API in one block. It runs as is; tests/test_readme_agents.py keeps it that way.
pip install --pre factblock
factblock sample brain/          # or: factblock extract notes.txt --observed-at 2024-03-20 -o brain/ --provider gemini
import factblock
print(factblock.context("brain/", "interest rates", as_of="2024-10-01"))   # prompt lines, as known that day
r = factblock.recall("brain/", "interest rates", as_of="2024-10-01")       # same, as dicts
c1 = next(i for i in r["items"] if i["id"] == "c1")
print(c1["superseded_by"]["statement"], c1["verdict"]["outcome"])          # what replaced it, how it was settled
Three rules: every read takes as_of (no default); a change is a new block plus SUPERSEDES, never an edit; never set known_at yourself (extract and write_bundle declare a batch). Claude Code users can copy .claude/skills/factblock into their project; other agents read llms.txt.
| If you know | In FactBlock |
|---|---|
Mem0 m.add(messages, user_id=...) |
factblock extract or extract(text, observed_at=...) + write_bundle(..., append=True); the user is a space |
Mem0 m.search(query, user_id=...) |
recall(bundle, query, as_of=...) or context(...) for the prompt |
Graphiti edge valid_at / invalid_at |
valid_from / valid_to on the block, plus known_at: when you learned it |
Graphiti expired_at (an edge closed later) |
the old block stays; a new block SUPERSEDES it, known from that moment |
| A vector store with a date filter | recall(as_of=...) also hides what was learned later, keeps what was replaced (marked), and attaches verdicts |
Same files, hosted
A folder is one writer's memory. factagora.ai is where a brain/ meets other people's. Upload it and it comes back with more rows, never changed rows: verdicts on predictions whose horizon has passed (mechanical ones from prices and published figures, judgment calls from the community, each with evidence), links to what other people claimed about the same thing (SUPPORTS, CONTRADICTS), entities resolved across worldviews. Every added row carries its own known_at, stamped by the server rather than by you, so a verdict is as replayable as the claim it judges: as of last June, the prediction was still open.
It also gives what a folder cannot: one ledger shared by many agents and users, natural-language writes at scale, and an MCP address per worldview, so a user plugs one into Claude or Cursor and reaches nothing else. Browse public worldviews there, or ask one a question as of a date. GET /v1/export hands the folder back at any instant. The format is the contract; you can leave with your files.
factblock sync brain/ <url> --space <space> moves rows both ways by identity: what only the folder has goes up, what only the ledger has comes down, nothing is changed in place. A row's known_at travels as the batch that attests it, so the ledger learns a 2024 transcript as known in 2024, not today, and the folder learns a verdict at the instant the ledger stamped it. Run it again and it is a no-op. --pull-only into a folder that does not exist yet clones a space. The token is $TCKG_TOKEN or --token.
Bring your own store. sync talks to a store through two methods, pull(as_of) and push(manifest, nodes, edges) (factblock/sync.py, the Store protocol). TckgStore is the one for tckg over HTTP; tests/test_sync.py has a forty-line in-memory one that shows the single rule a store has to keep: declare the bundle's batches as your own backfill batches, never adopt an imported row as learned now. A SQLite, Neo4j, or warehouse store is the same two methods.
The same ledger runs closed for companies at app.factagora.com: your support logs, your sales promises, your own assistant's assertions, as claims with verdicts, inside your tenant.
The format
SPEC.md is short. Five invariants (present, attested, unique, typed, declared), a JSONL profile and a Parquet profile, read semantics, and the conformance checks validate runs (eleven of them). Projections to OKF and ClaimReview are described, and to-claimreview writes the verdicts visible as of an instant as schema.org JSON-LD, so a bundle can feed systems that speak those.
Format, not platform. Apache-2.0. tckg is one writer of this format; nothing here requires it. Contributions are welcome under the DCO: see CONTRIBUTING.md.
Status
1.0-draft.1. Works today: extract (providers gemini, openai, and fake for offline runs; the claims profile is three files under factblock/profiles/claims that any language can run), validate, scan, recall, why, leak, resolve, to-parquet, sync with a tckg ledger or a store of your own, to-claimreview, to-okf, from-factcheck, the DuckDB macros, the Graphiti adapter, and the tckg export. Extraction quality on real transcripts is being measured separately; the rules are the ones a dated-claims pipeline has run on hundreds of videos. Next: a PyPI release. The format reaches 1.0.0 when a reader or writer maintained outside this repository exists; until then minor versions may change fields and the manifest's factblock_version says which one a bundle speaks.
uv sync --extra gemini                                 # or --extra openai; the fake provider needs nothing
export GEMINI_API_KEY=...                              # or GOOGLE_GENAI_USE_VERTEXAI=1 GOOGLE_CLOUD_PROJECT=... for Vertex
echo "The Fed will keep raising rates this year. That means bond yields keep climbing." \
  | uv run python -m factblock extract - --observed-at 2024-03-20 --speaker "Jim Cramer" --backfill -o brain/
uv run python -m factblock scan brain/ --as-of 2024-05-01
uv sync
uv run python -m factblock validate samples/rates
uv run python -m factblock scan samples/rates --as-of 2024-08-01
uv run python -m factblock why samples/rates c3 --as-of 2024-10-01 --json
uv run python -m factblock leak samples/rates samples/rates-questions.jsonl
uv run python -m factblock resolve samples/rates belief:fed:direction --as-of 2024-10-01
uv run python tests/test_rates.py && uv run python tests/test_why.py && uv run python tests/test_recall.py && uv run python tests/test_leak.py && uv run python tests/test_sync.py && uv run python tests/test_claimreview.py && uv run python tests/test_okf.py && uv run python tests/test_factcheck.py && uv run python tests/test_graphiti_adapter.py && uv run python tests/test_duckdb.py
1 maintainer

Metadata
1 maintainer
Release files for factblock 1.0.0a2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| factblock-1.0.0a2.tar.gz | 919.0 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| factblock-1.0.0a2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 976.0 kB
Release files / factblock-1.0.0a2.tar.gz
| Download URL | factblock-1.0.0a2.tar.gz |
|---|---|
| Size | 919.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9071b937b8e6b1502383fb6d0034aa9e0118095db4555c345bf07de5994a73aa
|
|
BLAKE2b-256 checksum How to use checksums |
ec78d9f376c444d844bc0b98eba908f74fa995683e037e25a94b8d4be7613dde
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logRelease files / factblock-1.0.0a2-py3-none-any.whl
| Download URL | factblock-1.0.0a2-py3-none-any.whl |
|---|---|
| Size | 57.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
27cd7774019ec5d6d64c15c2caf1ab3a4524663eb029b208a76381adb49bab5a
|
|
BLAKE2b-256 checksum How to use checksums |
3541a31bc1996c16fab9f286e02f727e4dd9cf7cd5da53cf8666d08679785fe8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logSecurity for factblock 1.0.0a2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for factblock-1.0.0a2.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














