
⚡Flash-ANSR:
Fast Amortized Neural Symbolic Regression


Flash-ANSR is a library for amortized neural symbolic regression: load a pretrained model, call fit(X, y), and recover a symbolic expression for your tabular data, or train your own model. It is built for fast, ready-to-use inference.
Publications
- Saegert & Köthe 2026, Breaking the Simplification Bottleneck in Amortized Neural Symbolic Regression (ICML 2026) https://arxiv.org/abs/2602.08885
Usage
Requires Python >= 3.12.
pip install flash-ansr
flash_ansr install psaegert/flash-ansr-v25.0-T8-20M   # the reference checkpoint (see "Models")
import numpy as np
import torch
from flash_ansr import FlashANSR, SoftmaxSamplingConfig, get_path

device = "cuda" if torch.cuda.is_available() else "cpu"

# The estimator's policy is fixed at construction: the sampler, the refiner, the ranking, the compute.
model = FlashANSR.load(
  directory=get_path("models", "psaegert/flash-ansr-v25.0-T8-20M"),
  generation_config=SoftmaxSamplingConfig(draws=1024),  # the search budget: expressions drawn per problem
  ranking="mdl",                                        # the two-part code: (n/2) log2 FVU + description length in bits (default)
  compute={"device": device},
)

# Define data: a small synthetic example, y = 2 * x + sin(3 * x)
X = np.linspace(-5, 5, 100).reshape(-1, 1)
y = 2 * X[:, 0] + np.sin(3 * X[:, 0])

# One call: draw candidates, fit their constants, rank them
result = model.fit(X, y)

print(result.best.expression_infix)   # the answer
print(model.get_expression())         # the same, read back from the estimator
y_pred = model.predict(X)             # evaluate the answer on new data
The result. fit returns a FitResult and keeps it as model.result_: the score-sorted refined candidates (each a Candidate with its expression, constants, fvu, score, mdl, log_prob, ...), the full ledger (every draw, classified FIT_OK / FIT_FAILED / INVALID), the ranking that ordered them and the generation / refinement times. Everything else is a view of it:
result.predict(X, rank=3)                                   # evaluate the candidate at rank 3
result.get_expression(rank=3, precision=3)                  # render it, constants rounded for display
result.to_dataframe()                                       # one row per refined candidate
result.rerank("weighted", weights={"n_nodes": 0.05})        # a NEW result under another ranking, no refit
result.save("result.pkl")                                   # plain data: no model objects inside
FitResult.load("result.pkl", engine=model.simplipy_engine)  # ... and back, evaluable again
The call. Everything that changes with the problem is an argument of fit: draws= overrides the budget for this call, seed= makes the draw and the refinement reproducible, complexity= hints the target complexity, on_empty="raise" raises ConvergenceError instead of returning an empty result when nothing fitted, variable_names= names the columns. Everything else is policy and lives on the estimator.
Flash-ANSR + PySR. flash_ansr.hybrid.HybridRegressor lets Flash-ANSR's best candidates seed PySR's evolutionary search, prices PySR's hall of fame the way Flash-ANSR prices its own candidates, and lets Flash-ANSR's ranking pick from the combined pool (pip install flash-ansr[pysr]; see the guide):
from flash_ansr.hybrid import HybridRegressor

hybrid = HybridRegressor(model)     # by default 1024 draws, then 64 PySR iterations: both stages take the same time
result = hybrid.fit(X, y)           # a FitResult of the combined pool; result.best.source says where the answer came from
Explore more in the Demo Notebook.
Train your own: see the training guide.
Models
The v25.0-T8 series: one recipe and one data prior at three sizes. Pick by the hardware you have; every one of them runs the examples above unchanged.
| Checkpoint | Parameters | Training | Notes |
|---|---|---|---|
psaegert/flash-ansr-v25.0-T8-3M |
3.5M | 1.5M steps, batch 128, configs/v25.0-T8-3M |
the smallest; comfortable on a CPU |
psaegert/flash-ansr-v25.0-T8-20M |
23.7M | 1.5M steps, batch 128, configs/v25.0-T8-20M |
the reference checkpoint for this release |
psaegert/flash-ansr-v25.0-T8-120M |
123.6M | 1.5M steps, batch 128, configs/v25.0-T8-120M |
the largest; a GPU is advisable |
flash_ansr install psaegert/flash-ansr-v25.0-T8-20M
Every catalog that srbf evaluates on is held out of the training data by canonical form (6,660 expressions across 29 catalogs).
Inference speed
Several inference-speed features are enabled by default and designed to be quality-neutral, so the quickstart above already runs in the fast regime. The speed-relevant settings are the compute group of the generation config:
| Setting | Default | What it does |
|---|---|---|
use_cache |
True |
KV-cache decoding |
batch_size |
'auto' |
budget-adaptive batching (pass an int to override) |
static_decode |
None |
static decoding, auto-enabled for capable models (set True/False to force) |
from flash_ansr import SoftmaxSamplingConfig

config = SoftmaxSamplingConfig(
  draws=1024,          # number of candidate expressions to draw per problem (fit(draws=) overrides it)
  use_cache=True,      # KV cache (default)
  batch_size='auto',   # budget-adaptive chunking (default)
  static_decode=None,  # auto for capable models (default)
)
Constant refinement runs in parallel; control it via compute={"workers": N, "persistent_pool": True} on FlashANSR.load. By default (workers=None) the pool uses every available CPU core, which oversubscribes shared machines; pass an explicit integer to cap it (0 disables multiprocessing).
To opt out of these defaults:
SoftmaxSamplingConfig(draws=1024, use_cache=False, batch_size=128, static_decode=False)
Candidate ranking. Three modes, one sort:
ranking="mdl"(default; the two-part code(n/2) * log2(FVU) + bits: the data coded under the candidate's residual variance plus the refined expression's description length,nthe support size, so more data buys more complexity;{"mode": "mdl", "mdl_strength": 1e-2}fixes the per-bit weight instead),{"mode": "weighted", "weights": {...}}(weights overn_nodes,n_constants,n_constant_placeholders,n_typed_literals,mdl,neg_log_prob) and{"mode": "pareto", "metrics": [...], "tie_break": ...}(the non-dominated front over the metrics). Each knob belongs to one mode and raises under another. A fitted result can be re-ordered under any ranking without refitting:result.rerank(...).
Overview
SRSD/FastSRB Results
Results on the SRSD/FastSRB benchmark [Matsubara et al. 2022], [Martinek 2025] Left: Validation Numeric Recovery Rate (vNRR) as a function of inference time (log scale). FLASH-ANSR models (shades of blue) scale monotonically with compute, with the 120M model partially surpassing the PySR baseline (red). Baselines NeSymReS [Biggio et al. 2021] and E2E [Kamienny et al. 2022] fail to generalize to the benchmark. Right: Expression Length Ratio (predicted vs ground truth) versus compute. We observe a parsimony inversion: while PySR [Cranmer 2023] increases complexity to minimize error over time, FLASH-ANSR converges toward simpler, more canonical expressions as the sampling budget increases. Shaded regions denote 95% confidence intervals. |
Training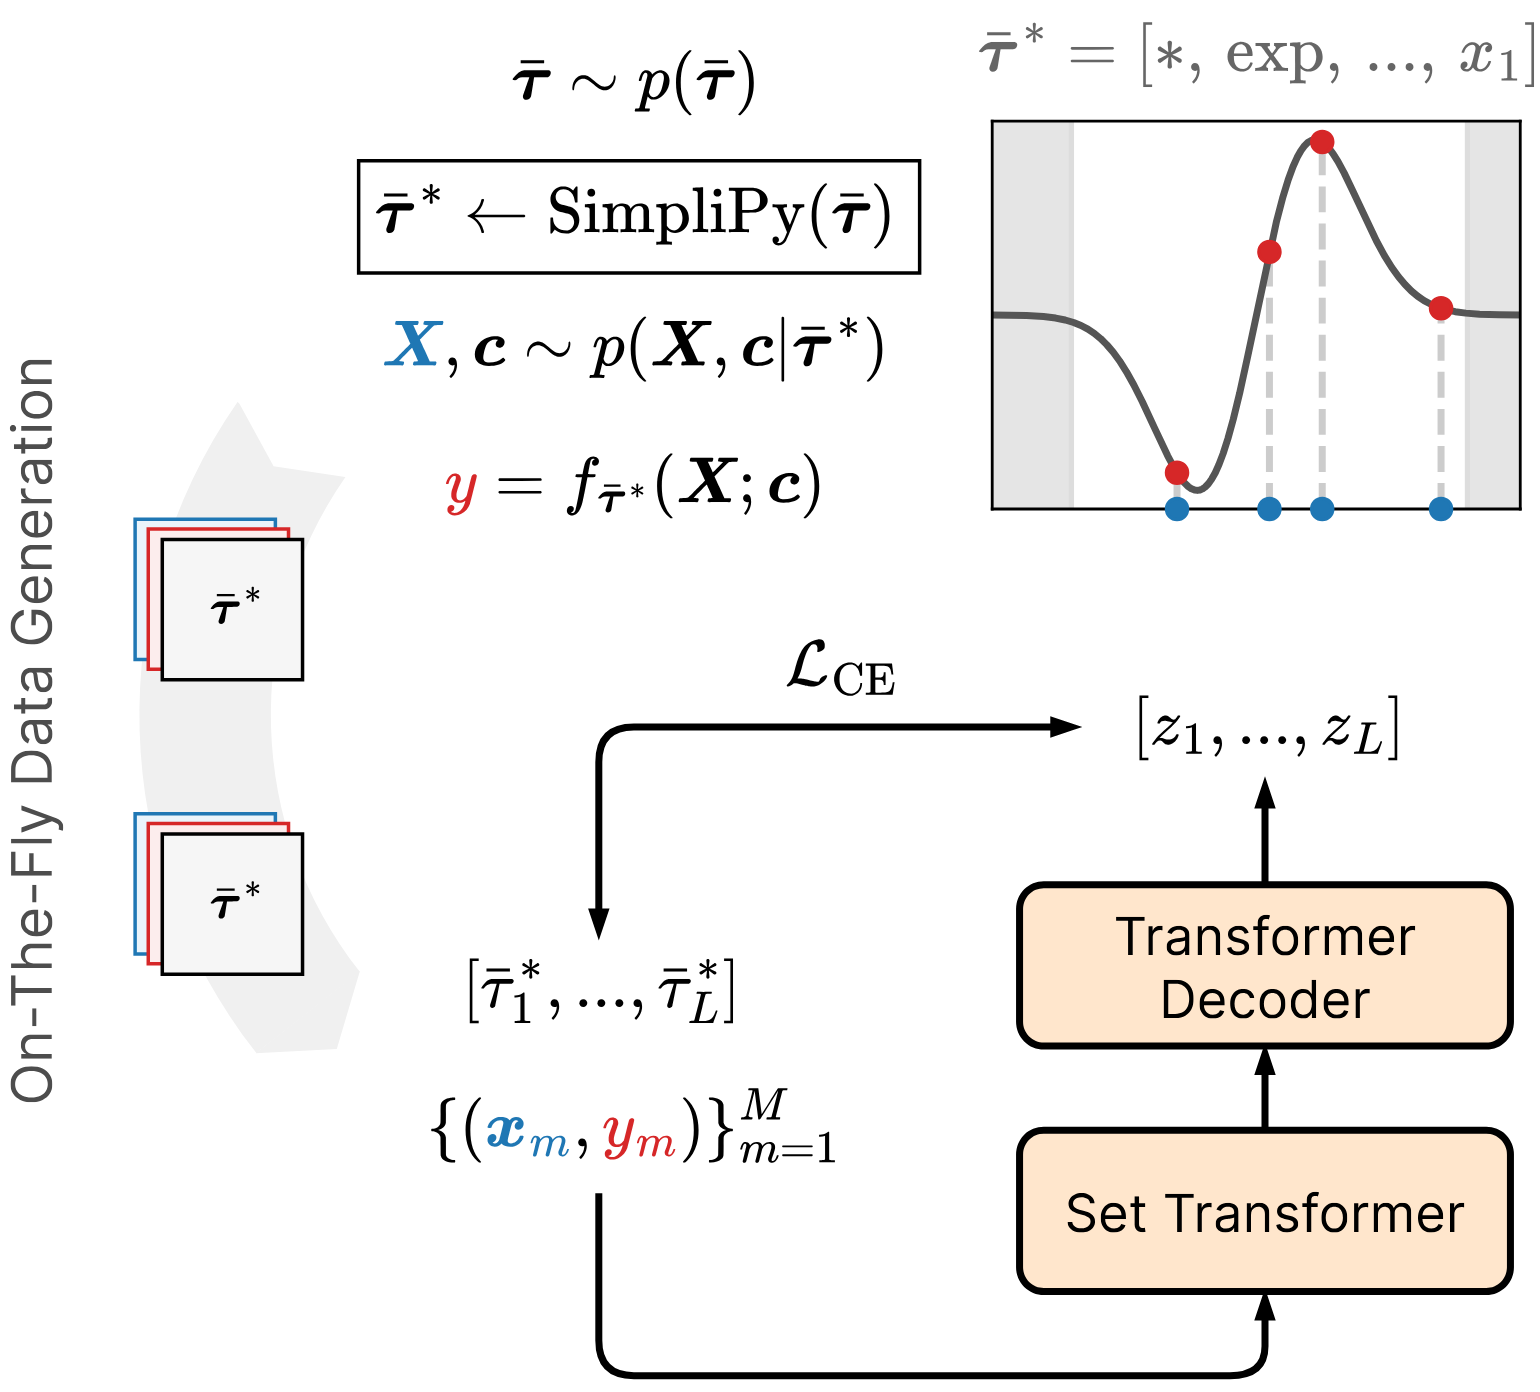
The Flash-ANSR training pipeline. Following the established standard encoder-decoder paradigm, our framework integrates SimpliPy (top center) into the loop for synchronous simplification of on-the-fly generated training expressions. |
Architecture
Flash-ANSR model architecture. The Set Transformer [Lee et al. 2019] encoder ingests a variable-sized set of input-output pairs and produces a fixed-size latent representation via Induced Set Attention Blocks (ISAB) and Set Attention Blocks (SAB). The Transformer decoder [Vaswani et al. 2017], [Xiong et al. 2020] autoregressively generates a symbolic expression token-by-token, attending to the encoded dataset at each step. |
Related projects
- SimpliPy: the expression simplification engine integrated into the Flash-ANSR training loop.
- symbolic-data: the model-agnostic symbolic-regression data layer (catalogs,
ProblemSource, holdouts) that feeds Flash-ANSR training. It is an unconditional runtime dependency and the backbone of the training loop. - srbf: the companion symbolic-regression evaluation and benchmarking framework (engine, model adapters, benchmarks, metrics), developed alongside Flash-ANSR.
Citation
@inproceedings{saegert2026breakingsimplificationbottleneckamortized,
  title   = {Breaking the Simplification Bottleneck in Amortized Neural Symbolic Regression},
  author  = {Paul Saegert and Ullrich Köthe},
  booktitle = {Proceedings of the 43rd International Conference on Machine Learning (ICML)},
  year    = {2026},
  eprint  = {2602.08885},
  archivePrefix =  {arXiv},
  primaryClass  = {cs.LG},
  url     = {https://arxiv.org/abs/2602.08885},
}

% Optionally
@mastersthesis{flash-ansr2024-thesis,
  author  = {Paul Saegert},
  title   = {Flash Amortized Neural Symbolic Regression},
  school  = {Heidelberg University},
  year    = {2025},
  url     = {https://github.com/psaegert/flash-ansr-thesis}
}
@software{flash-ansr2024,
  author  = {Paul Saegert},
  title   = {Flash Amortized Neural Symbolic Regression},
  year    = {2024},
  publisher   = {GitHub},
  version = {0.14.0},
  url     = {https://github.com/psaegert/flash-ansr}
}
1 maintainer

Metadata
1 maintainer
Release files for flash-ansr 0.19.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| flash_ansr-0.19.1.tar.gz | 392.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| flash_ansr-0.19.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 696.2 kB
Release files / flash_ansr-0.19.1.tar.gz
| Download URL | flash_ansr-0.19.1.tar.gz |
|---|---|
| Size | 392.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
743caf6b08e1df8da9bcff0a746c7c4a1ba47244e50ff9f331fb5d839ce09941
|
|
BLAKE2b-256 checksum How to use checksums |
f191145e450e8b9b3d70eb922febe61ab8c7b116287195adfc5fa15da13785cc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 29, 2026.
Transparency logRelease files / flash_ansr-0.19.1-py3-none-any.whl
| Download URL | flash_ansr-0.19.1-py3-none-any.whl |
|---|---|
| Size | 303.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
59c37475b8cef373479560a81750723e60fe7098885783bc3bc04213e9b9ba69
|
|
BLAKE2b-256 checksum How to use checksums |
7df93bf6996456018b3e13a808a7346e62078e979421a685423f8b6664bc2841
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 29, 2026.
Transparency log













