
fusedtok


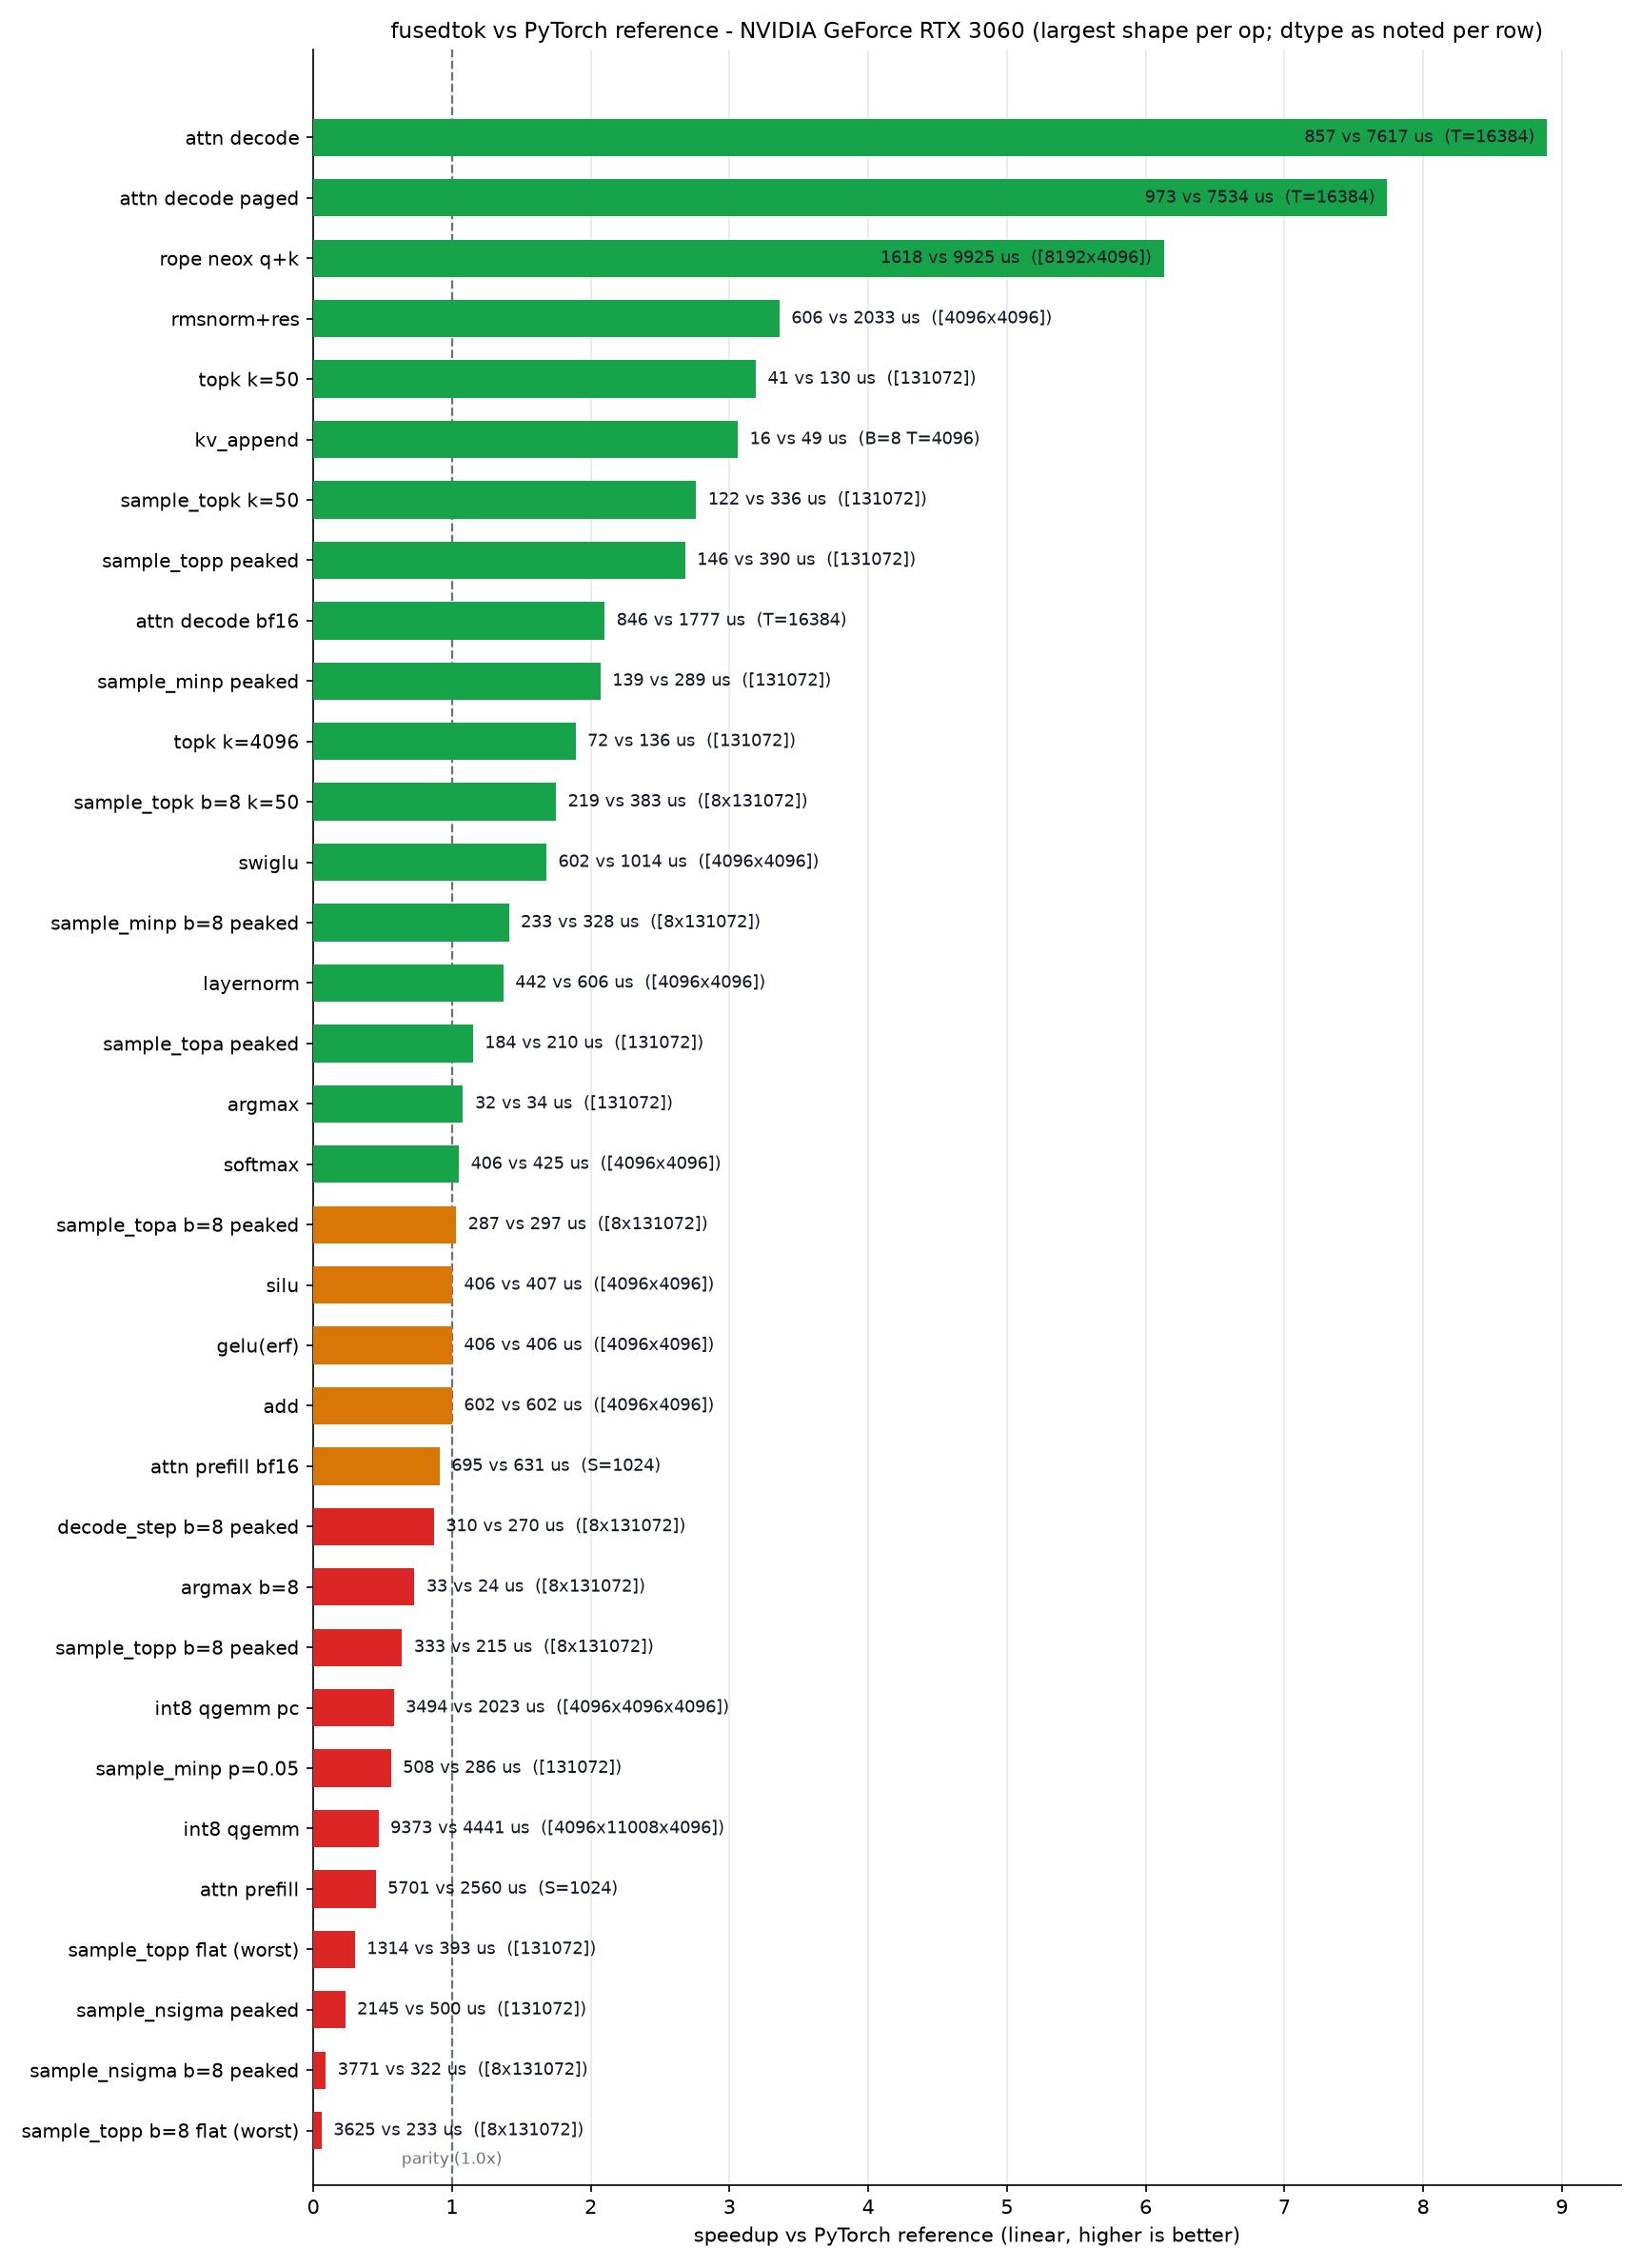
Fused CUDA kernels for LLM inference - RMSNorm / RoPE / SwiGLU / attention decode and friends, with zero-copy torch tensor support: up to 8.9x faster than PyTorch SDPA (attention decode, RTX 3060, see Benchmarks).
中文文档请看 README_zh.md | English below.
Why
LLM inference frameworks launch many small, memory-bound operators per token. Each launch
round-trips through global memory. fusedtok fuses them into single kernels to cut memory
traffic and launch overhead.
Operators
44 operators + helpers (fusedtok.__all__; 34 were frozen at 1.0, the
rest arrived in minor releases - see "API stability" below). axpy is
the hello-world demo op kept from
the v0.x skeleton - functional, but not a performance feature.
| Status | Kernel | Notes |
|---|---|---|
| ✅ | RMSNorm (+residual) | LLaMA/Qwen style, fused residual add |
| ✅ | LayerNorm | with affine |
| ✅ | RoPE | interleaved and NeoX layouts, kv-cache pos_offset |
| ✅ | SwiGLU | fused MLP activation |
| ✅ | Softmax (row-wise) | numerically stable |
| ✅ | SiLU / GeLU / GeLU-tanh / ReLU / Tanh / Sigmoid | elementwise |
| ✅ | add / mul | elementwise binary (fused add+residual pattern) |
| ✅ | top-k / top-p (nucleus) | arrival-ticket radix + early-exit compaction, replayed from a cached CUDA graph; deterministic ties (parity-to-winning across the whole k range on both test GPUs) |
| ✅ | argmax / temperature | greedy decoding helpers |
| ✅ | sample_topp | fused nucleus sampling: softmax -> top-p -> seeded draw, global-mass threshold |
| ✅ | sample_topk | fused top-k sampling: softmax -> top-k -> renormalize within the window -> seeded draw (1.8-2.1x vs the topk+multinomial composite @131k) |
| ✅ | sample_minp | fused min-p sampling (v1.3): keep every token with p >= min_p * p_max -> renormalize -> seeded draw - a value threshold, so no global-mass reduction; adaptive nucleus by construction |
| ✅ | sample_eta / sample_eta_batched | fused eta-cutoff sampling (v1.6, Hewitt 2022): keep every token with p >= eta * min(1, exp(-H)) - the threshold derives from the distribution's own entropy; adaptive by construction |
| ✅ | sample_typical / sample_typical_batched | fused locally typical sampling (v1.6, Meister 2022): keep the smallest set whose mass reaches typical, ordered by surprise-vs-entropy closeness - a contiguous band of the value-sorted window |
| ✅ | sample_topp/minp/topk_batched | batched sampling (v1.4): one call, [rows, vocab] logits in, one seeded token per row out - every row runs the single-row pipeline verbatim; the batched call is 4-6x faster in wall time than looping per row on submission-bound hosts, and sits at native batched-multinomial level on peaked decode logits |
| ✅ | repetition penalty | CTRL-style, applied to sampled token ids |
| ✅ | logit_penalties | the HF penalty trio in one call (v1.6.1): CTRL repetition scale, then presence, then count-weighted frequency shifts - once per distinct id, duplicates never stack; bit-exact across CPU and GPU |
| ✅ | logit_penalties_batched | the same trio for a whole [rows, vocab] batch (v1.7): ragged per-row histories (decode_step_batched's id layout), each row bit-identical to the single-row op |
| ✅ | decode_step | the whole decode step fused: penalty -> temperature -> nucleus sample, one call, one readback |
| ✅ | decode_step_batched | the fused decode step for a whole batch (v1.5): per-row ragged histories through per-row penalty bitmaps, one seeded token per row - every row runs the single-row decode_step pipeline up to the documented ulp boundary |
| ✅ | quantize_int8 / dequantize_int8 / qadd_int8 | symmetric per-tensor INT8, fused dequant-add-requant |
| ✅ | qgemm | INT8 matmul, int32-exact: cp.async double-buffered pipelined IMMA GEMM with runtime tile tuning (64x64 / 128x128) + warp-per-row GEMV (M=1 decode; 2x vs fp16 projection) |
| ✅ | qgemm_perchannel | the W8A8 layout real INT8 inference uses: per-output-channel weight scales fused into the same kernel's epilogue at zero cost |
| ✅ | attention_decode | single-token causal attention with GQA over a contiguous kv-cache: online softmax, flash-decoding split over long caches, per-sequence lengths; float32 / bfloat16 / float16 storage (half-precision cache = half the decode bytes, softmax stays float32) |
| ✅ | kv_append | the cache-write side of the contiguous decode loop (v1.3): one fresh token's k/v rows per sequence scattered in place into the cache at row lens[b] (one tiny kernel, f32/bf16/fp16) |
| ✅ | attention_decode_paged | the v1.2 headline: the same decode attention over a vLLM-style block-pool kv-cache [Nb, Hkv, P, D] walked through a per-sequence block table - fragmentation-free cache memory; any valid table honored, f32/bf16/fp16 storage, ~1.09-1.14x the contiguous op (7.89x / 4.28x vs SDPA on the pre-expanded-heads reference) |
| ✅ | kv_append_paged | the cache-write side of the paged loop: one fresh token's k/v rows per sequence scattered in place into the pool at position lens[b] (one tiny kernel, f32/bf16/fp16) |
| ✅ | attention_prefill | fresh-sequence attention over S query rows (causal / bidirectional), float32 / bf16 / fp16 storage; convenience path - heavyweight prefill stays SDPA/flash territory (honest ~0.45x f32) |
| ✅ | axpy | a*x + b - the v0.x hello-world demo op, kept for API compatibility |
Install
pip install fusedtok
Prebuilt wheels on PyPI (built with CUDA 12.4): Linux x86_64 (manylinux, cp310-cp313) and Windows x86_64 (cp311-cp313). On other platforms or Python versions pip builds from source automatically:
git clone https://github.com/Hai-Wenxiang/fusedtok.git
cd fusedtok
pip install .
Requirements:
- an NVIDIA GPU of the RTX 30 series (Ampere) or newer - e.g. RTX 3060/3090, RTX 4080, RTX 5090, A100, H100
- CUDA Toolkit >= 12.0
- A C++17 compiler (MSVC on Windows, GCC/Clang on Linux); Python 3.10+
What is "compute capability"? (click to expand)
Compute capability is NVIDIA's version number for a GPU architecture generation - not a performance score. CUDA code must be compiled for a specific architecture to run on it. The wheel builds native cubins for compute capability 8.0 (A100) and 8.6 (RTX 30) plus a compute_86 PTX fallback, so Ampere runs natively and newer architectures (RTX 40/50, ...) JIT the PTX with their driver.
| Compute capability | Architecture | Example GPUs |
|---|---|---|
| 7.5 | Turing | GTX 16xx, RTX 20xx (not supported) |
| 8.0 / 8.6 | Ampere | A100, RTX 30xx |
| 8.9 | Ada | RTX 40xx (via PTX) |
| 9.0 | Hopper | H100 (via PTX) |
| 12.0 | Blackwell | RTX 50xx (via PTX) |
Check yours: run nvidia-smi to see your GPU model, then look it up at
https://developer.nvidia.com/cuda-gpus
Usage
numpy in / numpy out, or torch in / torch out - including zero-copy CUDA:
kernels read and write torch device buffers directly via data_ptr(), with
no staging copies and no host synchronization.
import numpy as np
import torch
import fusedtok

x = np.random.randn(4, 1024).astype(np.float32)
w = np.random.rand(1024).astype(np.float32)

# CPU reference implementation (ground truth, runs anywhere)
y = fusedtok.rmsnorm(x, w, eps=1e-6)

# staged CUDA: copies to GPU, runs kernel, copies back
y = fusedtok.rmsnorm(x, w, cuda=True)

# zero-copy CUDA with torch tensors: kernels run in torch's own buffers,
# stream-ordered with other torch operations
xt, wt = torch.from_numpy(x).cuda(), torch.from_numpy(w).cuda()
yt = fusedtok.rmsnorm(xt, wt)          # -> CUDA torch tensor

# RoPE with kv-cache position offset, NeoX (LLaMA-HF) layout
q = torch.randn(1, 4096, device="cuda")          # new token only
q_rot, k_rot = fusedtok.rope(q, k=None, pos_offset=1023, neox=True)

# attention over a GQA kv-cache: one call per decode step, no score
# materialization, variable-length batches share one cache tensor
out = fusedtok.attention_decode(
    q_heads,                                    # [B, Hq, D] new token
    k_cache, v_cache,                           # [B, Hkv, T, D]
    lens=torch.tensor([1023, 512], dtype=torch.int32, device="cuda"))
# grow a contiguous cache: append each new token's rows, then decode
fusedtok.kv_append(k_cache, v_cache, k_new, v_new, lens)
out = fusedtok.attention_decode(q_heads, k_cache, v_cache, lens + 1)
# ...or over a paged (vLLM-style block-pool) cache: pools [Nb, Hkv, P, D]
# + a per-sequence block table; append each new token, then decode
fusedtok.kv_append_paged(k_pool, v_pool, block_table, k_new, v_new, lens)
out = fusedtok.attention_decode_paged(q_heads, k_pool, v_pool,
                                      block_table, lens + 1)
# fresh-sequence prefill (causal by default; convenience path)
ctx = fusedtok.attention_prefill(q_all, k_all, v_all, causal=True)

# sampling side: the whole decode step in one fused call
token = fusedtok.decode_step(logits, sampled_ids, penalty=1.1,
                             p=0.9, temperature=0.8, seed=step)
# or step by step:
logits = fusedtok.repetition_penalty(logits, sampled_ids, penalty=1.1)
token = fusedtok.sample_topp(logits, p=0.9, temperature=0.8, seed=step)
# top-k sampling variant (renormalizes within the k survivors)
token = fusedtok.sample_topk(logits, k=50, temperature=0.8, seed=step)
# concurrent decode: [rows, vocab] in, one token per row out (default
# seeds are 0..B-1, so identical rows still draw independently)
tokens = fusedtok.sample_topp_batched(batch_logits, p=0.9,
                                      temperature=0.8)
# ...with per-row repetition penalties: ragged histories, one flat
# array + offsets is the serving-fast form
tokens = fusedtok.decode_step_batched(batch_logits, flat_ids,
                                      penalty=1.1, p=0.9,
                                      ids_offsets=offsets)
A minimal per-token sampling loop:
import torch, fusedtok as ft

h = torch.zeros(1, 4096, device="cuda")            # decoder state
w = torch.load("rms_weight.pt").cuda()             # float32 weights
generated = []
for step in range(256):
    h = ft.rmsnorm(h, w, residual=h)               # fused add + norm
    q = ft.rope(q, k=None, pos_offset=step, neox=True)
    logits = model_output(h)                       # your model
    tok = ft.decode_step(logits, generated, penalty=1.1,
                         p=0.9, temperature=0.8, seed=step)
    generated.append(int(tok))
Every function accepts float32 numpy arrays or torch tensors (other dtypes are converted with a copy) and returns float32 outputs of the same family. CUDA torch tensors may be bfloat16 on every operator that moves tensor data (elementwise / norms / RoPE / attention), and the attention operators additionally take float16 - kernels compute in float32 and convert at the load/store boundary (norm weights are upcast to float32 automatically; sampling/selection ops stay float32). CUDA torch tensors select the zero-copy path automatically.
See examples/demo.py for a runnable tour of every operator, and the
usage guide for the topic-structured manual - one page per theme:
quickstart, the execution model (paths / dtypes / streams / CUDA
graphs), attention, the sampling contract, the INT8 workflow, how to
read the benchmarks, and an FAQ with a glossary. Also available in
中文.
Correctness
Every kernel ships with a CPU reference implementation and element-wise parity tests (pytest). Tests run on machines without a GPU (CUDA cases skip automatically).
API stability
1.0 froze the public surface at 34 names; new operators arrive in
minor releases (44 as of v1.7), and every name in fusedtok.__all__
keeps its signature across the 1.x series.
Type stubs (__init__.pyi, PEP 561 py.typed) ship with the package.
Breaking changes require a new major version and a deprecation window.
Determinism promises: selection ties resolve to the earliest index;
sampling is deterministic per seed.
Benchmarks
RTX 3060 (sm_86), float32, zero-copy torch tensors, CUDA-event timing over
3 independent rounds (means below; per-round values in the JSON), vs
the equivalent PyTorch reference (composite eager expressions; attention
references use pre-expanded heads - repeat_interleave outside the
timed region). Largest shape per op; full data:
docs/benchmarks/benchmark_rtx3060.json, reproduce with python benchmarks/bench.py:
| Op | Shape | fusedtok | PyTorch reference | Speedup |
|---|---|---|---|---|
| attention_decode (GQA) | T=16384, D=128 | 859 µs | 7614 µs (SDPA) | 8.86x |
| attention_decode_paged (GQA) | T=16384, D=128, P=16 | 986 µs | 7610 µs (SDPA) | 7.72x |
| RoPE NeoX (q+k) | [8192×4096] | 1617 µs | 9914 µs | 6.13x |
| kv_append (contiguous cache write) | B=8, T=4096 | 13 µs | 45 µs (advanced indexing) | 3.43x |
| RMSNorm (+residual) | [4096×4096] | 605 µs | 2032 µs | 3.36x |
| sample_topp p=0.9 (peaked) | [131072] | 143 µs | 361 µs (sort+mask+multinomial) | 2.52x |
| attention_decode bf16 | T=16384, D=128 | 850 µs | 1793 µs (SDPA bf16) | 2.11x |
| sample_minp p=0.05 (peaked) | [131072] | 143 µs | 188 µs (mask+multinomial) | 1.32x |
| SwiGLU | [4096×4096] | 601 µs | 1009 µs | 1.68x |
| sample_topk k=50 | [131072] | 146 µs | 245 µs (topk+multinomial) | 1.68x |
| top-k (k=50) | [131072] | 77 µs | 117 µs (CUB) | 1.53x |
| LayerNorm | [4096×4096] | 441 µs | 606 µs | 1.37x |
| top-k (k=4096, mid-k) | [131072] | 107 µs | 113 µs | 1.05x (honest) |
| Softmax | [4096×4096] | 405 µs | 425 µs | 1.05x |
| SiLU / GeLU / add | [4096×4096] | ~405-602 µs | ~406-602 µs | ~1.0x |
| argmax | [131072] | 44 µs | 34 µs | 0.76x (event-timed, noisy on WDDM; across-run spread 0.76-1.86x - see below) |
| int8 qgemm pc (W8A8) | [4096×4096×4096] | 3492 µs (39.4 TOPS) | 2015 µs (cuBLASLt + broadcast) | 0.58x (honest) |
| int8 qgemm (IMMA) | [4096×11008×4096] | 9459 µs (39.0 TOPS) | 4363 µs (cuBLASLt) | 0.46x (honest) |
| attention_prefill (causal) | S=1024, D=128 | 5727 µs | 2570 µs (SDPA flash) | 0.45x (honest) |
| sample_minp p=0.05 (wide nucleus) | [131072] | 482 µs | 189 µs | 0.39x (honest: one widening retry plus a 32-64k sort; the torch boolean-mask composite never sorts - see the peaked min-p row for min-p's win scenario) |
| sample_topp p=0.9 (flat worst case) | [131072] | 1330 µs | 342 µs | 0.26x (honest, see below) |
Batched samplers (v1.4) and batched decode steps (v1.5) - one call for
the whole [8, 131072] batch, referenced against torch's native
batched draw (softmax + multinomial over the 2-D tensor; the decode
row adds the gather-penalty; per-round values in the JSON):
| Op | Shape | fusedtok | PyTorch reference | Speedup |
|---|---|---|---|---|
| sample_topk_batched k=50 | [8×131072] | 192 µs | 260 µs (topk+multinomial) | 1.35x |
| sample_minp_batched p=0.05 | [8×131072] | 227 µs | 293 µs (mask+multinomial) | 1.29x |
| sample_topp_batched p=0.9 | [8×131072] | 261 µs | 213 µs (multinomial) | 0.82x (reference-side WDDM swing; see below) |
| decode_step_batched (penalty 1.3, ~64-token histories) | [8×131072] | 310 µs | 268 µs (penalize+softmax+multinomial) | 0.86x (but 5.2x vs looping the single row, wall time - see below) |
| sample_topp_batched (flat worst case) | [8×131072] | 3536 µs | 218 µs | 0.06x (honest, same caveat as the single row) |
Row-wise kernels (norms, softmax) autotune their thread-block size per shape at first call (v0.4.1); the table reflects the tuned choices.
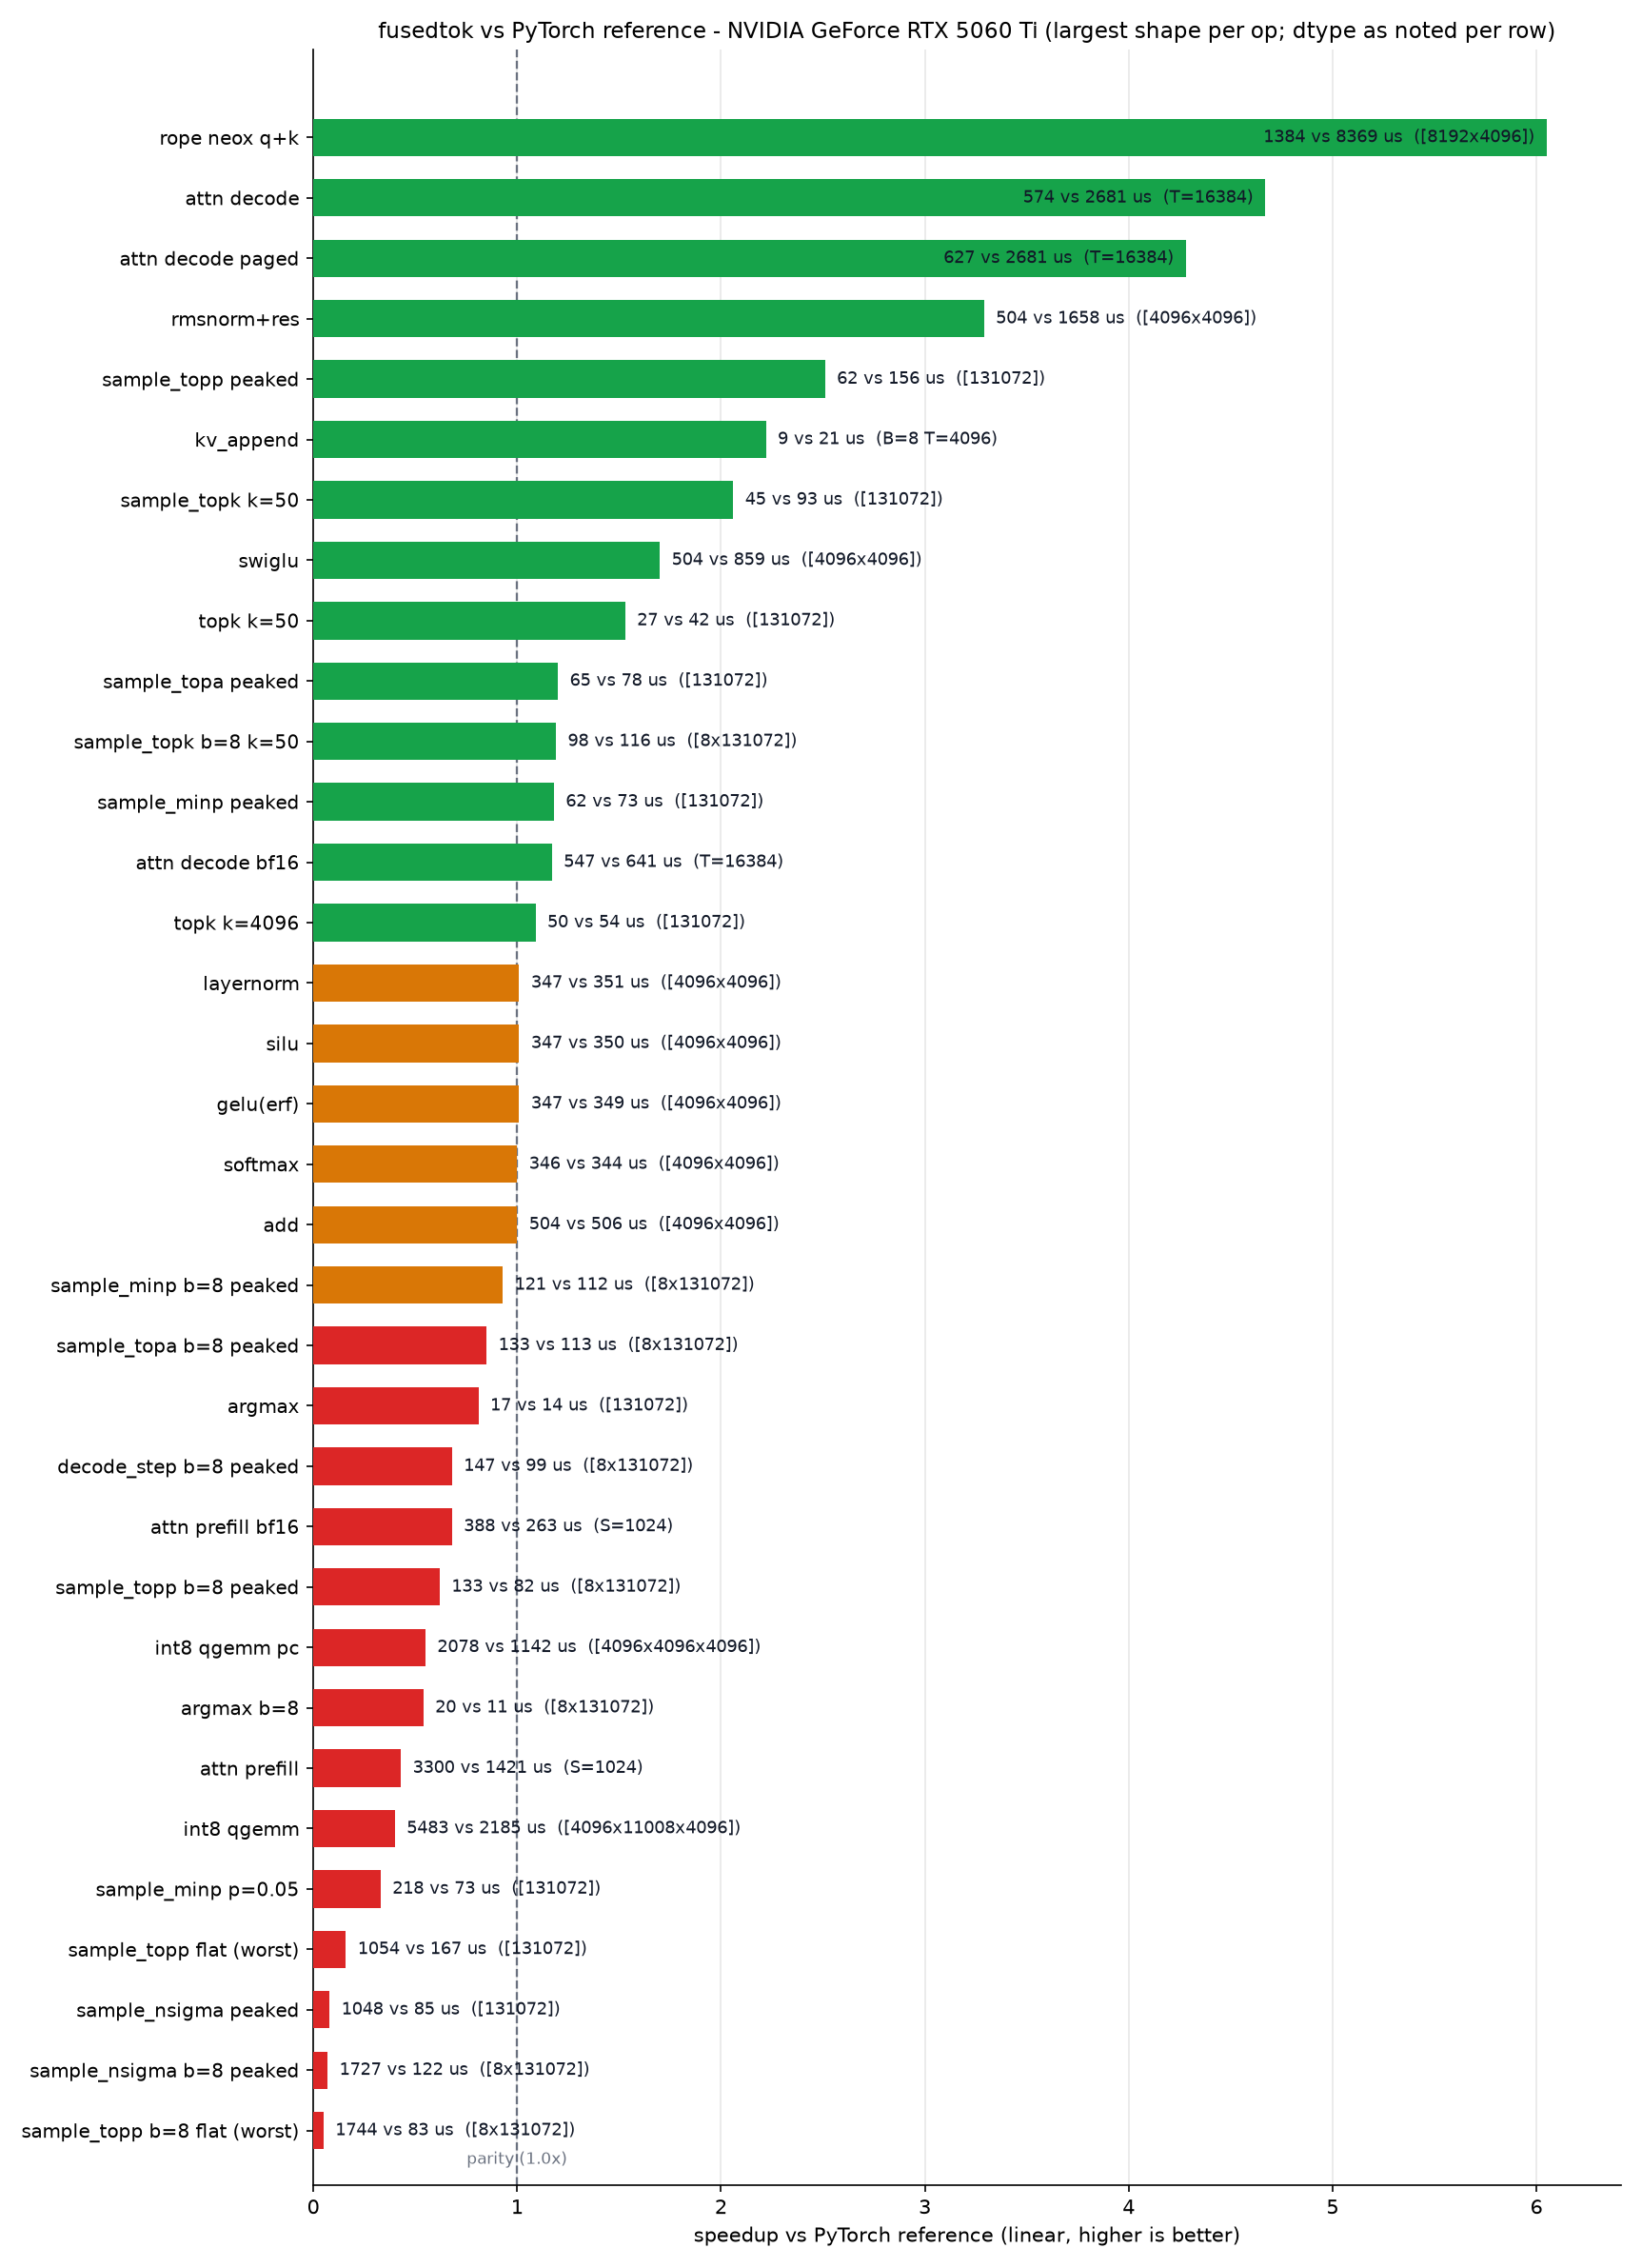
RTX 5060 Ti (Blackwell, sm_120) - same suite, largest shape per op
(full data: docs/benchmarks/benchmark_rtx5060ti.json):
| Op | Shape | fusedtok | PyTorch reference | Speedup |
|---|---|---|---|---|
| RoPE NeoX (q+k) | [8192×4096] | 1384 µs | 8371 µs | 6.05x |
| attention_decode (GQA) | T=16384, D=128 | 574 µs | 2681 µs (SDPA) | 4.67x |
| attention_decode_paged (GQA) | T=16384, D=128, P=16 | 626 µs | 2680 µs (SDPA) | 4.28x |
| RMSNorm (+residual) | [4096×4096] | 504 µs | 1657 µs | 3.29x |
| sample_topp p=0.9 (peaked) | [131072] | 62 µs | 155 µs (sort+mask+multinomial) | 2.49x |
| kv_append (contiguous cache write) | B=8, T=4096 | 9 µs | 21 µs (advanced indexing) | 2.20x |
| sample_topk k=50 | [131072] | 45 µs | 92 µs (topk+multinomial) | 2.03x |
| SwiGLU | [4096×4096] | 504 µs | 859 µs | 1.70x |
| top-k (k=50) | [131072] | 27 µs | 41 µs (CUB) | 1.51x |
| attention_decode bf16 | T=16384, D=128 | 546 µs | 641 µs (SDPA bf16) | 1.17x |
| sample_minp p=0.05 (peaked) | [131072] | 62 µs | 72 µs (mask+multinomial) | 1.17x |
| top-k (k=4096, mid-k) | [131072] | 50 µs | 54 µs (CUB) | 1.09x |
| LayerNorm / Softmax | [4096×4096] | ~346 µs | ~344-350 µs | ~1.0x |
| argmax | [131072] | 17 µs | 14 µs | 0.79x (event-timed, noisy; wall probe 0.96x) |
| int8 qgemm pc (W8A8) | [4096×4096×4096] | 2077 µs (66.2 TOPS) | 1142 µs (cuBLASLt + broadcast) | 0.55x (honest) |
| attention_prefill (causal) | S=1024, D=128 | 3296 µs | 1420 µs (SDPA flash) | 0.43x (honest) |
| int8 qgemm (IMMA) | [4096×11008×4096] | 5482 µs (67.4 TOPS) | 2188 µs (cuBLASLt) | 0.40x (honest) |
| sample_minp p=0.05 (wide nucleus) | [131072] | 264 µs | 72 µs | 0.27x (honest: same wide-nucleus caveat as the 3060 row) |
| sample_topp p=0.9 (flat worst case) | [131072] | 1078 µs | 164 µs | 0.15x (honest, see below) |
Batched samplers (v1.4) and batched decode steps (v1.5) on the same
[8, 131072] shapes:
| Op | Shape | fusedtok | PyTorch reference | Speedup |
|---|---|---|---|---|
| sample_topk_batched k=50 | [8×131072] | 97 µs | 114 µs (topk+multinomial) | 1.18x |
| sample_minp_batched p=0.05 | [8×131072] | 120 µs | 112 µs (mask+multinomial) | 0.94x (parity) |
| sample_topp_batched p=0.9 | [8×131072] | 132 µs | 83 µs (multinomial) | 0.63x |
| decode_step_batched (penalty 1.3, ~64-token histories) | [8×131072] | 146 µs | 99 µs (penalize+softmax+multinomial) | 0.68x (but 4.5x vs looping the single row, wall time - see below) |
| sample_topp_batched (flat worst case) | [8×131072] | 1763 µs | 83 µs | 0.05x (honest) |
On smaller shapes the Blackwell card shows bigger wins (softmax 1.7x, RMSNorm 3.1x at 256 rows, attention decode 3.78x at T=4096 running ~187 GB/s) - the launch-overhead share shrinks as shapes grow; full sweep in the JSON.
The PyPI wheel ships sm_80/sm_86 cubins plus a compute_86 PTX fallback - verified to JIT and run correctly on Blackwell (sm_120) drivers.
Fusions win big (RoPE / RMSNorm / SwiGLU) because eager mode round-trips intermediate tensors through global memory. The v0.4 selection pipeline (arrival-ticket radix rounds + early-exit compaction, replayed from a cached CUDA graph) beats torch's CUB radix select at small k on both GPUs; the v1.0 retune (in-block-sort threshold and sort chunk both dropped 2048 -> 1024 - a single block bitonic-sorting 2048 keys was the whole mid-k regression) brings the mid-k window to parity-or-winning as well. The fused samplers win against the eager composites when the logits look like real decode output (sample_topp peaked: 2.52x / 2.49x; sample_topk: 1.68x / 2.03x; the composites themselves swing run-to-run on WDDM - per-round values in the JSON). On a flat distribution sample_topp is honestly 0.15x on a 5060 Ti and 0.27x on a 3060 (the fusedtok side is stable; the reference's rounds carry WDDM noise) - the nucleus then spans ~90% of the vocabulary and the pipeline must effectively order the whole thing. v1.2 cut that worst case ~8.5x (18.2ms -> 2.2ms at n=131072 on a 3060) with three token-preserving changes - an adaptive window jump driven by a p*total mass bound, a full-vocabulary fast path that skips the selection stages, and a batched-load serial sampling walk (the strictly sequential float adds are the CPU-parity determinism contract; only the loads got pipelined); v1.3 cut it another ~1.6x (2.2ms -> 1.4ms on a 3060, 1.6ms -> 1.0ms on a 5060 Ti) by having the first walk record prefix-sum checkpoints that the inverse-CDF walk binary-searches - still bit-identical tokens - but torch's fully parallel sort still owns that regime. sample_minp (v1.3) wins on peaked logits and honestly loses the wide-nucleus row (0.27-0.39x: one widening retry plus a 32-64k sort; the torch boolean-mask composite never sorts) - v1.4 gave min-p the same adaptive jump top-p has had since v1.2 (a sufficient bound from the one-time global total: wide-nucleus rows skip the ladder's intermediate stops, 28-30% faster on that row, tokens bit-identical).
The v1.4 batched samplers put the whole [rows, vocab] batch through
one call: every row runs the single-row pipeline verbatim (per-row
parity, including the widening loop with per-row finish tracking), so
the speedup over the per-row loop is pure batching - 4-6x in wall
time at B=8 on submission-bound hosts (3060: topp 1340 -> 274 µs,
minp 1399 -> 237 µs; 5060 Ti: 3.9x / 4.3x). On peaked logits the
batched calls sit at torch's native batched-multinomial level
(the batched min-p and top-k calls win on this benchmark:
1.29x/1.51x and 0.94x/1.17x on the two GPUs), and the flat worst case
keeps the singles' honest caveat one tier lower (0.05-0.06x). v1.5
extends batching to the whole decode step: decode_step_batched runs
per-row repetition penalties through per-row vocab bitmaps inside the
same pipeline - on wall-time probes at B=8 it is 5.2x over looping
decode_step on peaked rows on a 3060 (1676 -> 321 µs; torch's
native penalize+softmax+multinomial composite: 266 µs) and 4.5x on a
5060 Ti (646 -> 145 µs), and 3.1x on mid-tail rows (3060).
attention_decode wins big at decode (one launch streams the GQA cache
once, while SDPA pays head expansion or small-query inefficiency);
attention_decode_paged (v1.2) pays only ~1.09-1.14x for the
block-table indirection of the fragmentation-free vLLM-style cache
layout, with bit-identical output on matching slice schedules;
attention_prefill is the honest convenience path at ~0.45x of SDPA's
flash backend - no tensor cores by design, so heavyweight prefill stays
with SDPA/FlashAttention. kv_append (v1.3) writes one token's k/v rows
into the contiguous cache in a single launch (a multi-x win over the
advanced-indexing scatter whose exact factor tracks that reference's
WDDM swing; a tiny launch-bound op - parity-level cost per decode
step). The INT8 decode GEMV moves half the bytes of
an fp16 projection and runs at full memory bandwidth (2x); the pipelined
IMMA GEMM (v1.0 rework: cp.async double-buffered slabs, runtime-tuned
64x64 / 128x128 tiles) reaches ~38 TOPS on a 3060 and ~67 TOPS on a
5060 Ti - 2x-4x the v0.4 kernel - but cuBLASLt (torch._int_mm) still
holds a ~2.1-2.5x lead on the per-tensor rows (its tiles pipeline
deeper and its epilogue is tuned per-arch); the W8A8 rows' gap is only
~1.7-1.8x. For now qgemm is the exact / graph-capturable /
zero-copy INT8 path, not the fastest one; honest numbers, a
CUTLASS-class schedule stays future work. The per-channel variant
(qgemm_perchannel, the W8A8 layout INT8 inference actually uses)
fuses the per-output-channel scale multiply into the same epilogue at
zero kernel cost - the composite torch reference pays for that
broadcast separately, which is where its 0.55-0.58x comes from.
All sampling rows above have measured fixed logits since 1.1.1 (the bench seeds torch's RNG); since v1.2 the peaked row spikes +20 and the flat row uses near-uniform logits - both regimes are now deterministically what their labels say (the v1.1 peaked row sat on the coverage boundary at n=131072 and flipped regimes per seed). The argmax rows are event-timed over a host-synchronized call and swing on WDDM (0.73-1.24x across runs); wall-clock probes with the sync excluded from the timed loop measure 1.12x (3060) / 0.96x (5060 Ti) - v1.2 removed one CUDA submission and one allocation per call.
Development
See CONTRIBUTING.md for the full guide (test rules, error contract, determinism invariants). Quick start:
# Windows: run inside a VS developer prompt (vcvars64)
cmake -S . -B build -G Ninja -DCMAKE_BUILD_TYPE=Release
cmake --build build
# from repo root: PYTHONPATH picks up the built module, conftest.py adds python/
$env:PYTHONPATH = "$PWD/build"        # Windows
PYTHONPATH=$PWD/build                 # Linux
python -m pytest tests -q
python benchmarks/bench.py            # GPU benchmark + chart
Both Windows and Linux are supported: Windows builds through MSVC via nvcc, and CI builds and runs the CPU test suite on every push.
Roadmap
-
v0.2 (released): bf16 zero-copy, radix-select top-k/top-p, fused nucleus sampling, single-read softmax, CUDA-graph verified
-
v0.3 (released): chunk-merge selection sort + parallel nucleus count, bf16x4/x8 vectorized elementwise, INT8 quantize/dequantize utilities
-
v0.4 (released): arrival-ticket selection pipeline (no cooperative launch, early-exit compaction, cached CUDA graphs), stream-aware launchers everywhere (real CUDA-graph capture), INT8 compute path (IMMA qgemm + decode GEMV), fused decode_step sampling
-
v0.4.1 (released): runtime block-size autotuning for the row-wise kernels (norms/softmax pick 128..1024 threads per shape at first call)
-
v0.5 (released): attention - GQA decode attention over a contiguous kv-cache (flash-decoding split over long caches, per-sequence lengths) and a tiled prefill path (honest ~0.45x of SDPA flash - the convenience path); single-chart-per-GPU benchmarks; Windows wheels in the PyPI publish pipeline
-
1.0 (released): pipelined tensor-core INT8 GEMM (cp.async double-buffering, runtime tile tuning; 17 -> 39 TOPS on a 3060) with per-channel weight scales (W8A8), fused top-k sampling (2.1x vs the topk+multinomial composite), top-k mid-range-k parity, text hygiene gate, wheel matrix expansion (Linux cp310-313, Windows cp311-313), API freeze
-
1.1 (released): half-precision attention -
attention_decode/attention_prefillaccept bfloat16 and float16 caches (float32 compute, half the decode bytes); parallel exp precompute halves the flat-distribution sampling worst case with bit-identical tokens -
1.2 (released): paged kv-cache attention -
attention_decode_pagedover a vLLM-style block pool[Nb, Hkv, P, D]+ per-sequence block tables (~1.09-1.14x the contiguous op, any valid table honored) andkv_append_paged(the in-place cache-write side); flat-distribution sampling worst case cut ~8.5x (adaptive widening jump + full-vocab fast path + batched-load serial walk, tokens bit-identical); argmax launch diet (one submission and one allocation less per call) -
1.2.1 (released): audit-driven hardening - selection workspace overflow past 131072-token vocabularies fixed (Qwen-scale vocabs), host-side lens/table/id validation with a documented device-tensor trust boundary (CUDA-graph capture works with
lensnow), empty- input and dtype/contiguity guards on the zero-copy paths, honest benchmark bandwidth (four rows were over-billed 1.5x), warning-clean builds (MSVC /W3 + GCC -Wall -Wextra), and the documentation restructured into topic pages with a natural-sounding Chinese rewrite -
1.3 (released):
sample_minp(min-p sampling - value-threshold nucleus relative to p_max, no global-mass reduction, adaptive by construction) andkv_append(the contiguous cache-write side); the sampling serial walk gains checkpoint bisection (walk 1 records prefix sums, walk 2 binary-searches them - flat worst case cut another ~1.6x, tokens bit-identical); zero-copy helpers reject CPU operands (a host pointer in a kernel poisons the CUDA context) -
1.3.1 (released): audit-driven hardening - staged-path lens/block-table value validation closed (bad values used to become silent GPU out-of-bounds writes) plus integer-input hardening; two latent sampling-walk bugs fixed (stride>=2 checkpoint double-count, adaptive widening reading the wrong workspace word - mid-tail ~28% faster with bit-identical tokens); softmax tuner capped to keep sanitizer gates clean; kernel/launcher cleanup; benchmark tables fully regenerated
-
1.4 (released): batched sampling -
sample_topp/minp/topk_batchedsample a whole[rows, vocab]batch in one call (per-row parity with the singles, one seed per row, rows finish at their own window sizes); min-p gains the adaptive widening jump (a sufficient bound from the one-time global total - wide-nucleus rows skip the ladder's intermediate stops, tokens bit-identical) -
1.4.1 (released): audit-driven hardening - staged-path batched shape validation closed (rows/n used to be trusted against the buffer), shared widen-bound helpers and a batched-sequencer cleanup, lazy per-row totals for both widen modes, stream-scoped syncs; benchmark tables regenerated with the shipping version stamp and the documentation overhauled (stale numbers, stiff phrasing, glossary and FAQ additions)
-
1.5 (released): a batched
decode_step- per-row ragged histories through per-row penalty bitmaps, the whole penalize -> scale -> sample chain in one call. The other 1.5 candidate (per-row window sizes inside one batched attempt, so a wide row no longer lifts the uniform window) was implemented three ways, measured as a net loss or parity at B=8/B=32 on an RTX 3060 (the serial inverse-CDF walk dominates each attempt round and the merge ladder carries a per-launch floor that window-bucketing multiplies), and was dropped with the numbers in the changelog - revisit if the walk goes parallel -
1.5.1 (released): audit-driven hardening - the int8 GEMV silently dropped the head of every row its alignment gate rejected (k % 4 != 0); the kv_append staged bindings and the rope / temperature raw launchers validate what their siblings already did; scalar-fallback kernels index in 64-bit; both docs languages resynced to the 1.5.0 JSONs with the stiff phrasing rewrites
-
1.5.2 (released): audit-driven hardening, round three - the batched radix rounds now apply the row's repetition penalty (the unpenalized selection prefix mis-composed decode_step_batched's window under penalty != 1); the kv_append_paged span is computed in 64-bit; duplicate penalty ids can no longer diverge between the CPU and GPU paths; rope grids, launcher guards and the batched CPU references got the same checks their siblings have
-
1.7 (released):
logit_penalties_batched- the penalty trio for a whole[rows, vocab]batch with ragged per-row histories, each row bit-identical to the single-row op; the batched histograms ride a capture-safe cached workspace with a workspace-free borrowed-output fallback, and both apply kernels force separate roundings so the FFMA fusion cannot split CPU and GPU by an ulp (43 -> 44 public names) -
1.6 (released): entropy-adaptive sampling -
sample_eta(eta cutoff, Hewitt 2022: keep every token withp_i >= eta * min(1, exp(-H)), a value-threshold prefix like min-p, reusing min-p's adaptive widening bound) andsample_typical(locally typical, Meister 2022: the smallest set whose mass reachestypical, ordered by|surprise - H|- a contiguous band of the value-sorted window, no analytic widening bound so the honest x8 ladder), each single-row and batched (38 -> 42 public names) -
1.6.1 (released):
logit_penalties- the HF penalty trio (CTRL repetition scale, presence shift, count-weighted frequency shift) in one call, once per distinct id, duplicates never stack, bit-exact across CPU and GPU - plus audit-driven hardening: the spurious "typical nucleus not covered" throw attypical = 1.0, the batched typical trust-boundary gap, and the eta widening bound's unit mismatch (42 -> 43 public names) -
future candidates (unscheduled): bf16/fp16 tensor-core prefill (rewrite-level), a CUTLASS-class INT8 GEMM schedule (the current qgemm is the exact/graph-capturable/zero-copy path, not the fastest one), 16-bit radix keys (changes the determinism contract)
Community
- Contributing guide - setup, rules of the road, PR process
- Code of conduct
- Security policy
- Changelog
License
MIT - see LICENSE. Third-party notices: NOTICES.md.
1 maintainer

Metadata
1 maintainer
Release files for fusedtok 1.7.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| fusedtok-1.7.0.tar.gz | 798.0 kB | Details |
Built distributions (wheels)
| File | Reset | |||
|---|---|---|---|---|
| fusedtok-1.7.0-cp313-cp313-win_amd64.whl | CPython 3.13 | CPython 3.13 | Windows x86-64 | Details |
| fusedtok-1.7.0-cp313-cp313-manylinux_2_34_x86_64.whl | CPython 3.13 | CPython 3.13 | Linux glibc 2.34+ x86-64 | Details |
| fusedtok-1.7.0-cp312-cp312-win_amd64.whl | CPython 3.12 | CPython 3.12 | Windows x86-64 | Details |
| fusedtok-1.7.0-cp312-cp312-manylinux_2_34_x86_64.whl | CPython 3.12 | CPython 3.12 | Linux glibc 2.34+ x86-64 | Details |
| fusedtok-1.7.0-cp311-cp311-win_amd64.whl | CPython 3.11 | CPython 3.11 | Windows x86-64 | Details |
| fusedtok-1.7.0-cp311-cp311-manylinux_2_34_x86_64.whl | CPython 3.11 | CPython 3.11 | Linux glibc 2.34+ x86-64 | Details |
| fusedtok-1.7.0-cp310-cp310-manylinux_2_34_x86_64.whl | CPython 3.10 | CPython 3.10 | Linux glibc 2.34+ x86-64 | Details |
Total release size: 17.7 MB
Release files / fusedtok-1.7.0.tar.gz
| Download URL | fusedtok-1.7.0.tar.gz |
|---|---|
| Size | 798.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
52d0bce6bba372824f31e4b6bbec44bf234ae2b1f3c3d15d9375f9bc72a4dd3b
|
|
BLAKE2b-256 checksum How to use checksums |
83f4e0cdb50ba1badf7f541a8dd4f89fc95cfdec300683e6e9501755b3037b72
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / fusedtok-1.7.0-cp313-cp313-win_amd64.whl
| Download URL | fusedtok-1.7.0-cp313-cp313-win_amd64.whl |
|---|---|
| Size | 2.3 MB |
| Tags | CPython 3.13 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
18af317ea0e7980fbddc6cd12ecb527fb0e8d73ae2686b810b75499f3863a107
|
|
BLAKE2b-256 checksum How to use checksums |
8cbf3b5ddc2b8517f925f1f42e41e88cf425ef5b7667f128e668d8bb6b99185d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / fusedtok-1.7.0-cp313-cp313-manylinux_2_34_x86_64.whl
| Download URL | fusedtok-1.7.0-cp313-cp313-manylinux_2_34_x86_64.whl |
|---|---|
| Size | 2.5 MB |
| Tags | CPython 3.13 Linux glibc 2.34+ x86-64 |
|
SHA-256 checksum How to use checksums |
6de30358687e7e65ca709498113c5965385d716463501f13838c3573c375f4f9
|
|
BLAKE2b-256 checksum How to use checksums |
630984dfbe50ccbe87eea09b9f233f7297f08b1a15109454f61e8840bd4ef7cc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / fusedtok-1.7.0-cp312-cp312-win_amd64.whl
| Download URL | fusedtok-1.7.0-cp312-cp312-win_amd64.whl |
|---|---|
| Size | 2.3 MB |
| Tags | CPython 3.12 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
bb42a8498b7ec72e8acd8454858f6d5a404a2ed4ad47a89de338eb9405df6626
|
|
BLAKE2b-256 checksum How to use checksums |
21fe93615fb98c948bf47ab3a902ff33e1a92640c7e04c4c93754fd05eeadf47
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / fusedtok-1.7.0-cp312-cp312-manylinux_2_34_x86_64.whl
| Download URL | fusedtok-1.7.0-cp312-cp312-manylinux_2_34_x86_64.whl |
|---|---|
| Size | 2.5 MB |
| Tags | CPython 3.12 Linux glibc 2.34+ x86-64 |
|
SHA-256 checksum How to use checksums |
5168e8f514ae67018ec15f2039081db21e37e16f09311b95d82cf62c3aa5eb75
|
|
BLAKE2b-256 checksum How to use checksums |
9b6e28301dc83b2147603d6c53eb11426f1da6a0bca382ca2a323c8e07cc546c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / fusedtok-1.7.0-cp311-cp311-win_amd64.whl
| Download URL | fusedtok-1.7.0-cp311-cp311-win_amd64.whl |
|---|---|
| Size | 2.3 MB |
| Tags | CPython 3.11 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
73e1fabcea865568a7826a3954e61c13adb72ce149580d94eb0d266fee6e1041
|
|
BLAKE2b-256 checksum How to use checksums |
12c3dcc2545df637c35df86a9470ecf372f666ae33d22d00cd1b04ca396285b6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / fusedtok-1.7.0-cp311-cp311-manylinux_2_34_x86_64.whl
| Download URL | fusedtok-1.7.0-cp311-cp311-manylinux_2_34_x86_64.whl |
|---|---|
| Size | 2.5 MB |
| Tags | CPython 3.11 Linux glibc 2.34+ x86-64 |
|
SHA-256 checksum How to use checksums |
affe5d50c77c49139c2d1827a0a81f685f6bd4d46b5ea57b63a579e3b59a5083
|
|
BLAKE2b-256 checksum How to use checksums |
3281237a1a7b75b16a1091c9b53f503a07be91e319bc2b89b360650a834cd8b4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency logRelease files / fusedtok-1.7.0-cp310-cp310-manylinux_2_34_x86_64.whl
| Download URL | fusedtok-1.7.0-cp310-cp310-manylinux_2_34_x86_64.whl |
|---|---|
| Size | 2.5 MB |
| Tags | CPython 3.10 Linux glibc 2.34+ x86-64 |
|
SHA-256 checksum How to use checksums |
8d8058d051a2d63e5aa330f450d4fa69aa2d0e99184b7357d97a3be449afbbbb
|
|
BLAKE2b-256 checksum How to use checksums |
4a6d6771757dcbd7991c25fe73f1a3ba20f897e443f769e8421c663a922bfdcd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 7, 2026.
Transparency log













