
Gram Newton-Schulz: A Fast, Hardware-Aware Newton-Schulz Algorithm for Muon
Authors: Jack Zhang, Noah Amsel, Berlin Chen, Tri Dao
Blogpost: https://dao-ailab.github.io/blog/2026/gram-newton-schulz/
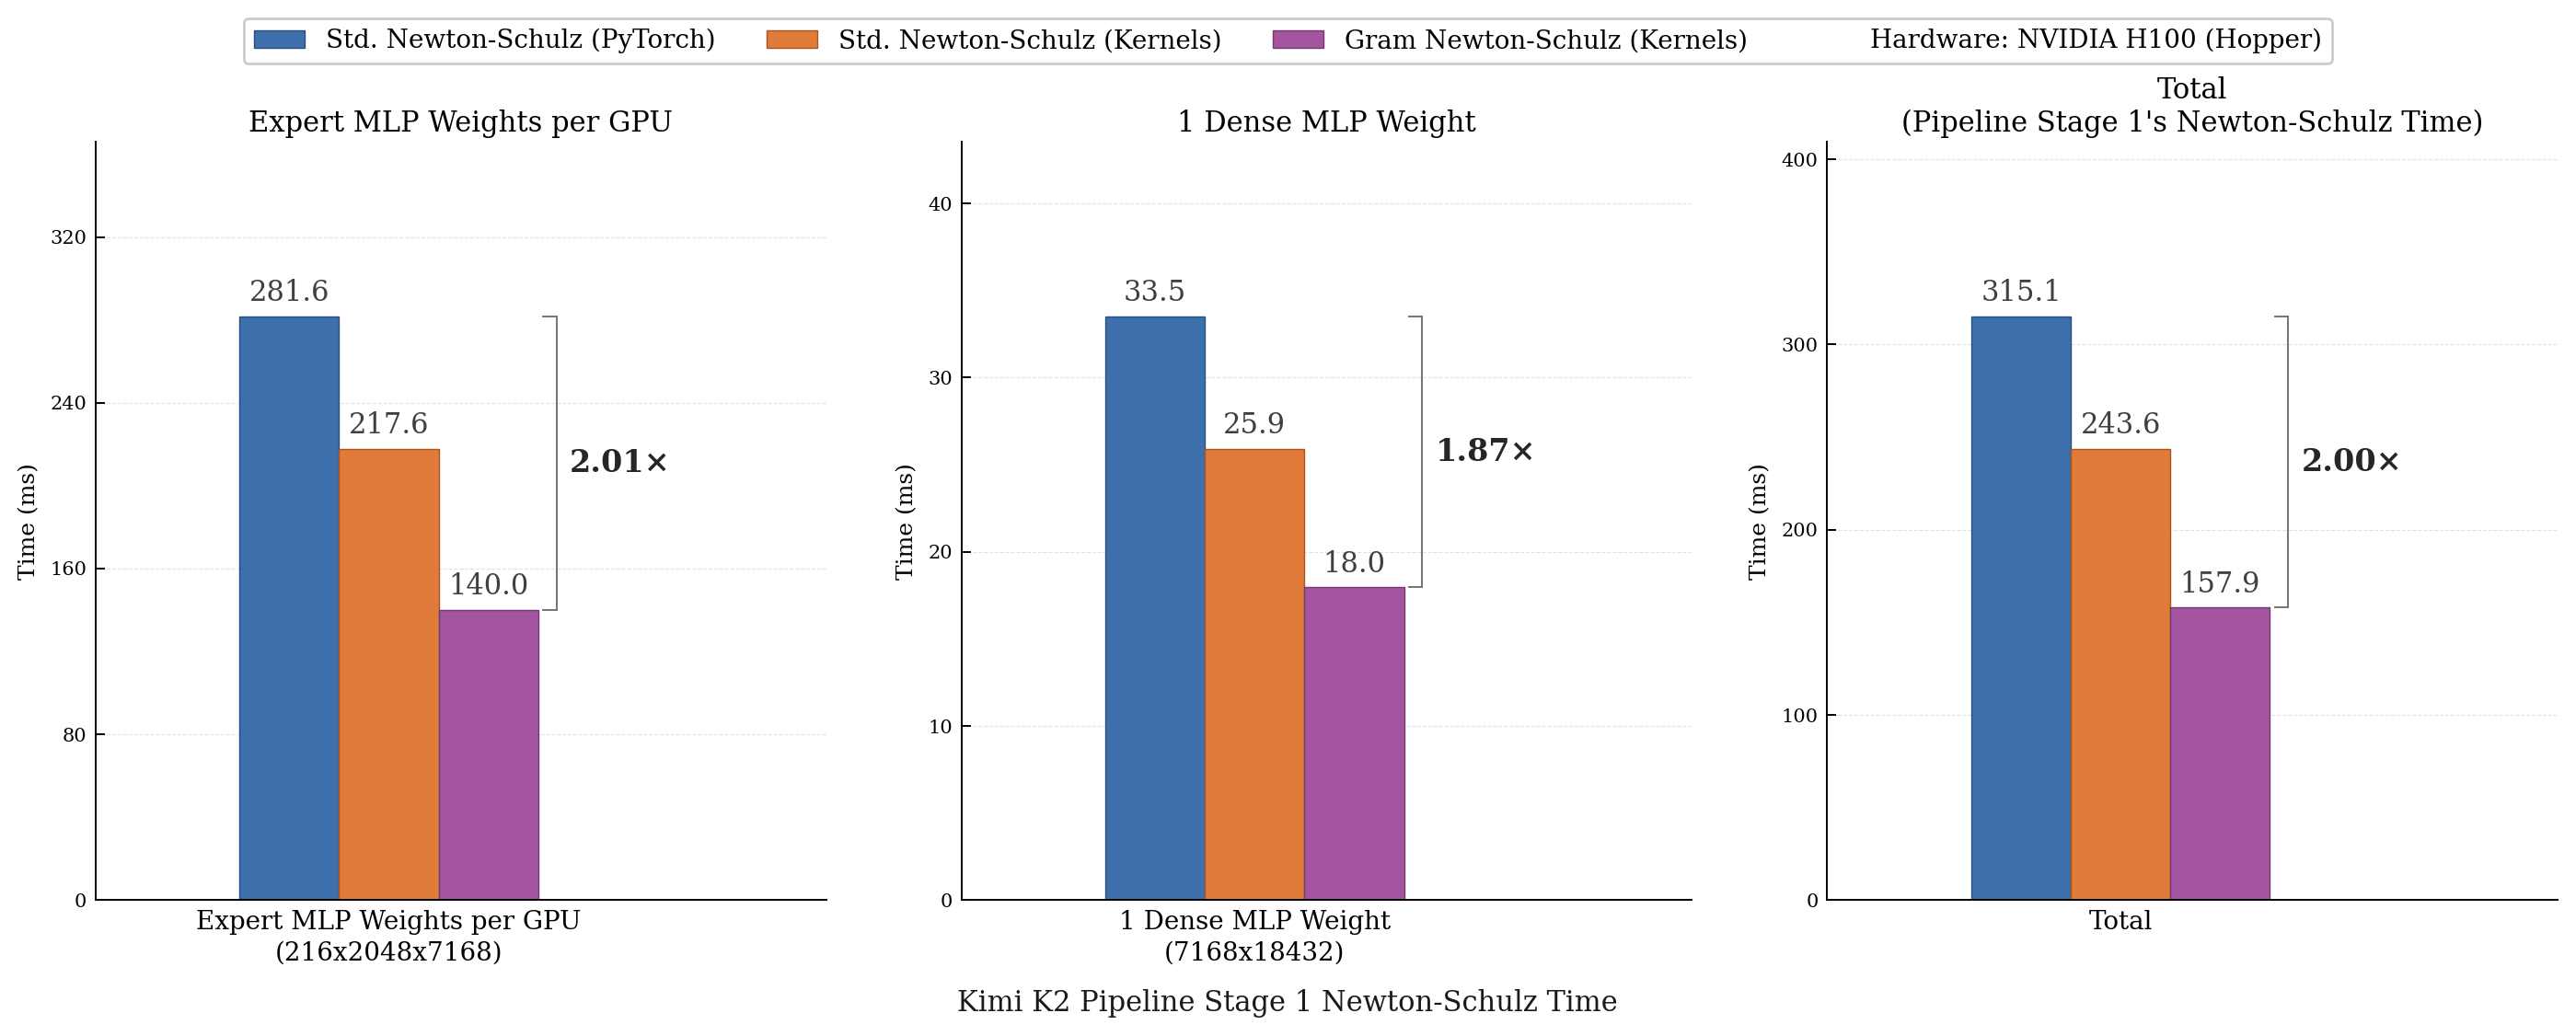
Achieve up to 2x faster Newton-Schulz with Gram Newton-Schulz and symmetric CuTeDSL GEMM kernels!
What you're probably here for:
- Gram Newton-Schulz: https://github.com/Dao-AILab/gram-newton-schulz/blob/main/gram_newton_schulz/gram_newton_schulz.py
- Gram Newton-Schulz Restart Autotune: https://github.com/Dao-AILab/gram-newton-schulz/blob/main/gram_newton_schulz/restart_autotune.py
- Symmetric GEMMs for Hopper and Blackwell in CuTeDSL: https://github.com/Dao-AILab/quack/blob/main/quack/gemm_symmetric.py
About
Gram Newton-Schulz is a hardware-aware algorithm for polar decomposition that is mathematically equivalent to and faster than Newton-Schulz. Polar decomposition is most commonly used in Muon, and Gram Newton-Schulz serves as a direct drop-in for standard Newton-Schulz with no training accuracy tradeoff.
Instead of iterating on the expensive $X \in \mathbb{R}^{n \times m}$ matrix, Gram Newton-Schulz iterates on the small, square, symmetric Gram matrix $XX^\top \in \mathbb{R}^{n \times n}$, lowering FLOPs and enabling more symmetric GEMM kernels.
Gram Newton-Schulz
Input: $X \in \mathbb{R}^{n \times m}$ with $n \leq m$, coefficients ${(a_t, b_t, c_t)}_{t=1}^5$
- $X \gets X / (\|X\|_{F} + \epsilon)$ // Normalize sing vals to $[0, 1]$. $\epsilon = 10^{-7}$
- $X \gets \texttt{float16}(X)$ // Cast to half precision for speed
- If $m < n$: $X \gets X^\top$ // Trick to make $XX^\top$ cheaper
- $R_0 \gets XX^\top$
- $Q_0 \gets I$
- For $t = 1, \ldots, 5$:
- If $t = 3$: // Restart to stabilize
- $X \gets Q_2 X$
- $R_2 \gets XX^\top$
- $Q_2 \gets I$
- $Z_t \gets b_t R_{t-1} + c_t R_{t-1}^2$
- $Q_t \gets Q_{t-1} Z_t + a_t Q_{t-1}$
- $RZ_t \gets R_{t-1} Z_t + a_t R_{t-1}$
- $R_t \gets Z_t (RZ_t) + a_t (RZ_t)$
- $X \gets Q_4 X$
- If $m < n$: $X \gets X^\top$ // Undo trick
- Return $X$
Installation
Requirements:
- NVIDIA Hopper (H100) or Blackwell (B200/B300) GPU
- PyTorch 2.7.1+
- CUDA 12.9+
Install PyTorch first, then install from PyPI with pip install gram-newton-schulz --no-build-isolation or from source:
pip install . --no-build-isolation
--no-build-isolation is required so that pip uses your existing CUDA-enabled PyTorch instead of installing torch-cpu in an isolated build environment.
This will install:
- gram-newton-schulz (this package)
- nvidia-cutlass-dsl 4.5.2
- quack-kernels 0.5.0
Usage
WARNING: torch.compile is known to sometimes have issues with Blackwell, TORCH_COMPILE_DISABLE=1 to disable torch.compile.
Gram Newton-Schulz
from gram_newton_schulz import GramNewtonSchulz, POLAR_EXPRESS_COEFFICIENTS

gram_NS = GramNewtonSchulz(
            ns_coefficients=POLAR_EXPRESS_COEFFICIENTS,
            gram_newton_schulz_reset_iterations=[2]
        )
result = gram_NS(X)
GramNewtonSchulz is a callable function that is initialized with ns_coefficients (List of List of floats) and a list of gram_newton_schulz_reset_iterations immediately after which to restart Gram Newton-Schulz's iterative loop (List of ints) for stability. For example, [2] means a restart occurs after the 2nd iteration and [2,4] means a restart occurs after the 2nd iteration and then after the 4th.
To find the best num-restarts restart location(s) for a set of coefficients, run
python -m gram_newton_schulz.autotune_restarts --num-restarts 1 --coefs "4.0848,-6.8946,2.9270;3.9505,-6.3029,2.6377;3.7418,-5.5913,2.3037;2.8769,-3.1427,1.2046;2.8366,-3.0525,1.2012"
For 5 steps of Newton-Schulz, we recommend num-restarts = 1 for maximum speed while maintaining numerical stability. However, users who experience numerical instability or use more than 5 steps should consider using more restarts.
Muon
The Muon class supports an auxiliary scalar optimizer that updates all non-Muon parameters, custom functions that split model weights for orthogonalization, and Gram Newton-Schulz with autotuned restart locations.
import torch
from torch.optim import AdamW
from gram_newton_schulz import Muon, YOU_COEFFICIENTS

qkv_params = []
regular_2d_params = []
scalar_params = []

for name, param in model.named_parameters():
    if 'qkv_weight' in name:
      qkv_params.append(param)
    elif param.ndim >= 2:
      regular_2d_params.append(param)
    else:
      scalar_params.append(param)

scalar_optimizer = AdamW(
    scalar_params,
    lr=1e-3,
    betas=(0.9, 0.95),
    weight_decay=0.1,
)

def qkv_split_fn(param: torch.Tensor):
    """
    Split Wqkv into [Wq, Wk, Wv].

    Assumes param has shape (3*hidden_dim, hidden_dim) where the first dimension
    is concatenated [Q, K, V] weights.
    """
    hidden_dim = param.size(1)
    Wq = param[:hidden_dim, :]
    Wk = param[hidden_dim:2*hidden_dim, :]
    Wv = param[2*hidden_dim:, :]
    return [Wq, Wk, Wv]

def qkv_recombine_fn(splits):
    """Recombine [Wq, Wk, Wv] back into Wqkv."""
    return torch.cat(splits, dim=0)

muon_param_groups = []

muon_param_groups.append({
    'params': qkv_params,
    'param_split_fn': qkv_split_fn,
    'param_recombine_fn': qkv_recombine_fn,
    'lr': 3e-3,
    'weight_decay': 0.1,
    'momentum': 0.95,
})

muon_param_groups.append({
    'params': regular_2d_params,
    'lr': 3e-3,
    'weight_decay': 0.1,
    'momentum': 0.95,
})

optimizer = Muon(
    params=muon_param_groups,
    scalar_optimizer=scalar_optimizer,
    lr=3e-3,
    weight_decay=0.1,
    momentum=0.95,
    nesterov=True,
    adjust_lr='rms_norm',
    ns_algorithm='gram_newton_schulz',
    ns_use_kernels=True,
    ns_coefficients=YOU_COEFFICIENTS,
    gram_newton_schulz_num_restarts=1,
)
See example.py for a full training example.
Citation
If you use this codebase, or otherwise find our work valuable, please cite Gram Newton-Schulz:
@misc{GramNewtonSchulz,
  title   = {Gram Newton-Schulz},
  author  = {Jack Zhang and Noah Amsel and Berlin Chen and Tri Dao},
  year    = {2026},
  url     = {https://dao-ailab.github.io/blog/2026/gram-newton-schulz/}
}
1 maintainer

Metadata
1 maintainer
Release files for gram-newton-schulz 0.1.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| gram_newton_schulz-0.1.6.tar.gz | 18.3 kB | Without provenance | Details for gram_newton_schulz-0.1.6.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| gram_newton_schulz-0.1.6-py3-none-any.whl | Python 3 | none | any | Details for gram_newton_schulz-0.1.6-py3-none-any.whl |
Total release size: 37.5 kB
Release files / gram_newton_schulz-0.1.6.tar.gz
| Download URL | gram_newton_schulz-0.1.6.tar.gz |
|---|---|
| Size | 18.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6e13ab3000845968c78ef7b5be882c2eba4b3f36eedc74ca3f2e38acdecce21b
|
|
BLAKE2b-256 checksum How to use checksums |
5fd55a6863847b504aac78ea7f0501fd2d25c766d452e2ab4d94f7a714c17823
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.10.20
|
Release files / gram_newton_schulz-0.1.6-py3-none-any.whl
| Download URL | gram_newton_schulz-0.1.6-py3-none-any.whl |
|---|---|
| Size | 19.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5608c834bb0989d640eb1608bd2a9f1a4a908c46c9887847de98fa383b759c1c
|
|
BLAKE2b-256 checksum How to use checksums |
a6625de8e75b44e7f7980b140fdaf145880e3232a97a1a14d0fc0dc264dd70cc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.10.20
|
Security for gram-newton-schulz 0.1.6
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














