
hdfe-stream
Regression with several high-dimensional fixed effects, on data that does not
fit in memory: linear (feols_stream), and Poisson, logit and probit
(fepois_stream, feglm_stream).
from hdfe_stream import feols_stream

fit = feols_stream(
    "log_earn ~ age_squared + age_cubed | worker_id + firm_id + year",
    "data/*.parquet",              # a Parquet path or glob, never fully loaded
    workdir="scratch",             # where intermediates go: disk, not memory
    vcov={"CRV1": "worker_id"},
)
fit.summary()
Formulas follow pyfixest/fixest syntax and are parsed by pyfixest's own parser, so the syntax, the coefficient names and the results all match. The difference is where the work happens: rows are streamed off disk in batches and never held as a design matrix.
The data can be a Parquet path or glob, a Polars LazyFrame, or a Polars DataFrame. Using file paths or LazyFrames keeps memory usage to a minimum, but using DataFrames works well for smaller data and for trying things out.
When to use this, and when not to
Use pyfixest. It is the better tool whenever your data fits in memory:
mature, broader in scope, more inference options, and no scratch directory to
think about. If a pandas DataFrame of your data fits comfortably in RAM, stop
reading.
Use this when it doesn't. The case it was built for is a matched employer–employee panel — tens of millions of rows, millions of worker effects, an AKM variance decomposition — on a machine or a secure enclave where the data is larger than the memory you are allowed. Concretely, reach for it when:
- the data does not fit in memory, or fits so tightly that nothing else does;
- you have one very high-cardinality dimension (workers, patients, students) whose groups each touch only a few levels of the others;
- you want worker-specific slopes as well as intercepts (
worker_id[t]), which multiplies the parameter count by the number of slopes; - the design is wide: hundreds of covariates, such as a categorical expanded into fine indicators or many interactions. An in-memory library needs rows × covariates in memory before it starts; this needs one batch of rows × covariates at a time, with any number of fixed effects, including one or none (see many covariates);
- you need a hard, predictable memory ceiling — a shared cluster, or a job that must not be the one that gets killed.
You are trading memory for disk, and you need scratch space: about five times
the size of your Parquet input while the fit runs, and only the result files
once it finishes. See benchmarks for what that buys. Point
workdir= at it, or set the HDFE_STREAM_WORKDIR environment variable once
(for example to a cluster's scratch filesystem) and leave workdir out; a
workdir passed to a call takes precedence, and with neither, the system
temporary directory is used.
How it works, in one paragraph
One fixed-effect dimension — normally the largest — is streamed: it
is never represented as a vector in memory. Every other dimension is held as a
vector sized by its number of levels, not rows. Rows are read in batches,
hash-partitioned into buckets by the streamed dimension, sorted one bucket at a
time, and reduced to a table of cells (one per combination of fixed-effect
levels). The reduced normal equations for the non-streamed dimensions are then
solved by conjugate gradient, and the streamed effects are recovered group by
group in a final pass that writes residuals and fixed effects straight to
Parquet. So memory scales with firms × years, not with workers × rows, and that
asymmetry is the whole design. The covariates travel with the rows: what is
held at once is one bucket or batch of rows × covariates, never all of them,
which is why a wide design fits where an in-memory one does not. Full detail is in
hdfe_stream/__init__.py.
Install
pip install hdfe-stream[formula] # formula syntax needs pyfixest
polars, numpy, numba, pyarrow and scipy are required. The extras:
| extra | what it adds |
|---|---|
formula |
feols_stream formula syntax and pyfixest reporting (pyfixest, formulaic, pandas) |
within |
the solver="within" backend |
amg |
algebraic multigrid preconditioning (precond="amg") for hard geometries |
all |
all of the above |
test |
the test suite |
On Python 3.15, pyfixest 0.60 (for the formula extra) has no wheels yet. It
builds from source with a Rust toolchain and
PYO3_USE_ABI3_FORWARD_COMPATIBILITY=1 set; everything else installs from
wheels.
Without formula you still get StreamingHDFE, the lower-level interface that
takes column names or Polars expressions instead of a formula string.
Features
Fixed effects. Any number of dimensions, including one (a within regression,
y ~ x | worker_id) and none (OLS with an intercept, y ~ x). Interactions
with ^ (firm_id^year). Varying slopes on the streamed dimension in fixest
syntax (worker_id[t], worker_id[t, t2]). Connected components of the
worker–firm graph are computed and reported. The degrees-of-freedom correction
either removes the redundant fixed-effect levels it can identify
(fe_dof="exact", the default) or follows pyfixest's convention
(fe_dof="pyfixest"). "exact" counts the connected components of each pair of
fixed-effect dimensions and uses the pair with the most, plus one redundant
level for each further dimension. With two fixed effects this is the exact
number of identified parameters. With more it is an upper bound, so standard
errors are conservative. For clustered standard errors, fixed effects nested
within the clusters are dropped from the count as in pyfixest, and a pair of two
nested fixed effects is not used. Singleton observations, those alone in their
level of some fixed effect, are dropped as in pyfixest, repeating until none is
left (fixef_rm="singleton", the default; fixef_rm="none" keeps them).
Finding them costs a few extra passes over the fixed-effect columns and memory
for the singleton levels, not for the rows.
Connected sets. Worker and firm effects are only comparable within a
connected set: firms linked, directly or through other firms, by workers who
moved between them. connected_components(data, "worker_id + firm_id") finds
the connected components of the graph of two fixed effects (either may be an
interaction, firm_id^year) by union-find over the rows as they stream, and
returns small tables, one per dimension, giving each level its component.
Components are numbered by size, so component == 0 is the largest.
.largest() is the largest connected set and .label() every row with
its component, both lazily.
min_degree first removes levels with too few distinct partners in the other
dimension (distinct firms for a worker, distinct workers for a firm),
repeating until none is left, then finds the components of what remains.
min_degree=(2, 1) keeps movers only: workers seen at two or more firms, and
the firms they were seen at. min_degree=2 also removes firms with a single
worker, and repeats, since removing a firm can leave a worker with one firm and
removing a worker can leave a firm with one worker, until every worker left
was seen at two or more firms and every firm employed two or more of them (the
network's "2-core").
leave_one_out=True instead prunes to the leave-one-out connected set that
KSS estimation needs (and leave_out_kss applies), so it can be found ahead of
time: the largest connected set, without workers observed only once, and
without any worker whose departure would split the network into pieces,
removed repeatedly until none is left. It differs from min_degree=2. It keeps
stayers with at least two observations, which min_degree=2 removes, and it
removes movers that min_degree=2 keeps. Every mover and firm it keeps,
min_degree=2 keeps too, and on the movers and firms the two coincide only
when no single mover holds the network together.
In a fit, min_degree= prunes first, then connected="largest" keeps the
largest connected set or connected="leave_one_out" the leave-one-out
connected set, all on the first two fixed effects listed unless
connected_fe= names another pair, and all before singletons are dropped, so
the fit equals one on data restricted beforehand. sample() labels the rows
they drop "min_degree", "disconnected" and "leave_one_out". The
component column of fixef() for the first non-streamed dimension is
numbered the same way, by rows in the estimation sample. With three or more
fixed effects, connectedness of one pair is necessary for identification but
not sufficient.
Covariates. Transformations (I(age**2), log(x)), categoricals (C(x),
string columns), interactions (:, *), event-study terms
(i(year, treat, ref=2009)). Terms spanned by the fixed effects are dropped
exactly as pyfixest drops them. Every term compiles to a Polars expression, so
the design is built while the data streams, one bucket at a time: a categorical
expanded into hundreds of indicators is carried through the partitioning as the
one column it comes from.
Standard errors. iid, heteroskedasticity-robust (hetero/HC1), and CRV1
clustered on any column, any ^ interaction, or several dimensions at once
(multi-way Cameron–Gelbach–Miller, any number of ways). Ask for several at fit
time with cluster= and switch between them afterwards with with_vcov() —
they are all computed in the one residual pass. CRV3, the cluster jackknife
(vcov={"CRV3": var}), for OLS when every fixed effect is nested within the
clusters or there are none; see limitations.
Estimators. OLS, weighted least squares (weights=, analytic or frequency),
and 2SLS (y ~ exog | fe | endog ~ instruments) with a first-stage F. Poisson
(fepois_stream, with an offset) and logit and probit (feglm_stream), with
weights; see below.
Multiple models. Several outcomes (y1 + y2 ~ ...), stepwise covariate sets
(sw(), csw()) and stepwise fixed-effect sets. Models sharing a fixed-effect
set share one pass over the data and one solve.
Leave-out variance components. The Kline–Saggio–Sølvsten bias correction for
the AKM decomposition, via leave_out_kss — including the leave-one-out
connected set, Johnson–Lindenstrauss leverages, weights, standard errors with
95% intervals (se=True), KSS's weak-identification diagnostic saying whether
those intervals are justified, and the interval that stays valid when they are
not. See below and
docs/kss.md.
Output. Coefficients as a Polars DataFrame (tidy()); the model-level
information of summary() (observations, fixed-effect counts, fit statistics,
solver) as JSON with summary_json(), optionally written to a file with
summary_json("fit.json") (summary_dict() returns the same as a dict);
residuals and
per-row fixed effects as lazy Polars scans, so aggregates like a variance
decomposition run as a streaming pass; estimated effects per dimension via
fixef(). to_pyfixest() converts a result into a pyfixest model for
pf.etable, pf.summary, pf.coefplot and pf.iplot, and hdfe_stream.etable
mixes streaming and in-memory models in one table.
Matching results to the source. The residual file is in the estimator's
order, not the source's, so every row carries row_id, its position in the
source before any row was dropped (row_id= renames the column).
fit.resid() joins back onto the source on it, and fit.sample() returns the
source, lazily, with row_id, in_sample and dropped_because (null for rows
used; otherwise "missing", "min_degree", "disconnected",
"leave_one_out", "singleton" or "separation"), for looking at
the data net of what the fit dropped:
rows = fit.sample().join(fit.resid().select("row_id", "resid"), on="row_id", how="left")
Nothing is stored per row for this: the frame is the source plus the small
tables of dropped levels, and row_id adds a few bytes per row to the working
and residual files. It relies on the source reading back in the same order,
which a file, a glob or a DataFrame does and a LazyFrame does only if its plan
does (not after a group_by, an unordered join or a random sample). For a model list,
multi.sample() returns {formula: frame}; models fitted on the same fixed
effects share one sample.
Operations. Progress, warnings and summaries to a logging logger as they
happen. Each fit works in its own run directory; intermediates are deleted as
soon as they are no longer needed, everything is removed if the fit fails, and
hdfe_stream.cleanup() sweeps up after killed jobs.
Benchmarks
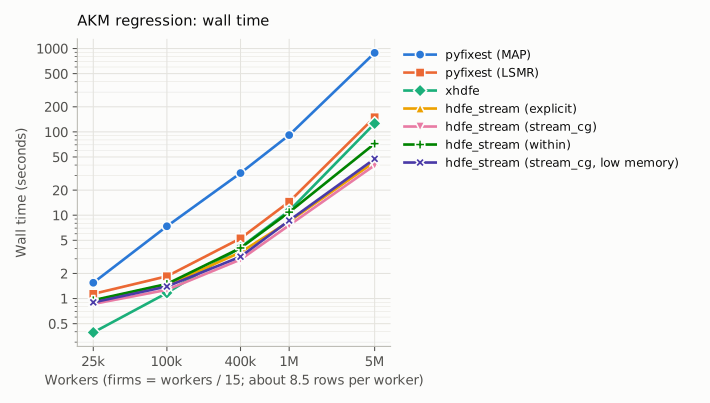
A standard three-way AKM specification,
log_earn ~ age_squared + age_cubed | worker_id + firm_id + year, clustered by
worker, on the simulated panel that ships with the library. It is compared with
pyfixest, under both of its
demeaners, and with xhdfe, on its
CPU backend. Sizes run from 25,000 to 5,000,000 workers, with firms = workers /
15 at every size and about 8.5 rows per worker, so the largest panel has 42.5
million rows. Every configuration agrees with every other on the coefficients
to within 3e-10, so these are measurements of equally good answers. Reproduce
with:
pip install -e ".[benchmark]"      # xhdfe installs separately: see benchmarks/README.md
python benchmarks/akm_benchmark.py
python benchmarks/plot_benchmarks.py
The numbers behind the figures are in
benchmarks/results/akm.csv, and
benchmarks/README.md says how each is measured. In
brief: wall time includes reading the data, because pyfixest and xhdfe need it in
memory before they can start and hdfe_stream reads it itself — that difference is
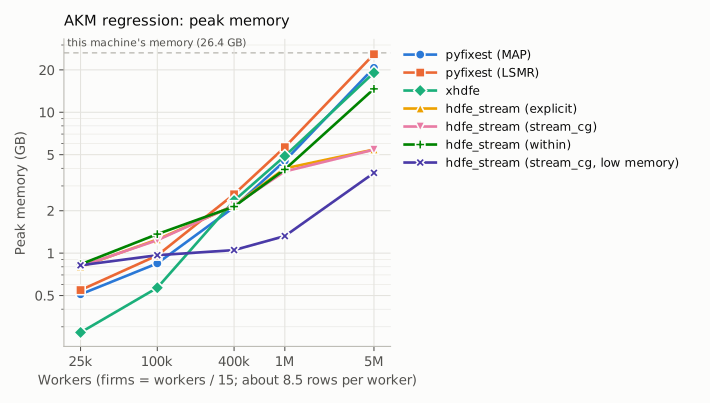
the comparison, not an artifact. Peak memory is VmHWM for the whole process,
including about 0.5 GB of imports. Each configuration runs in its own process.
At 5 million workers:
| configuration | wall time | peak memory | peak disk |
|---|---|---|---|
| pyfixest (MAP, its default) | 1,960 s | 20.7 GB | — |
| pyfixest (LSMR) | 138 s | 25.3 GB | — |
| xhdfe | 238 s | 19.0 GB | — |
hdfe_stream (explicit, its default) |
52 s | 4.1 GB | 4.1 GB |
hdfe_stream (stream_cg) |
54 s | 4.0 GB | 4.1 GB |
hdfe_stream (stream_cg, low memory) |
60 s | 3.2 GB | 4.3 GB |
Reading the figures
Memory is the point. At 5 million workers the in-memory libraries peak at
19–25 GB: pyfixest's LSMR run needed almost all of this machine's 26 GB.
hdfe_stream peaks at 4.1 GB with its defaults and 3.2 GB with the batch and
bucket sizes turned down ("low memory": rows_per_bucket=250_000,
batch_rows=200_000), for about 16% more time and the same answer. What it
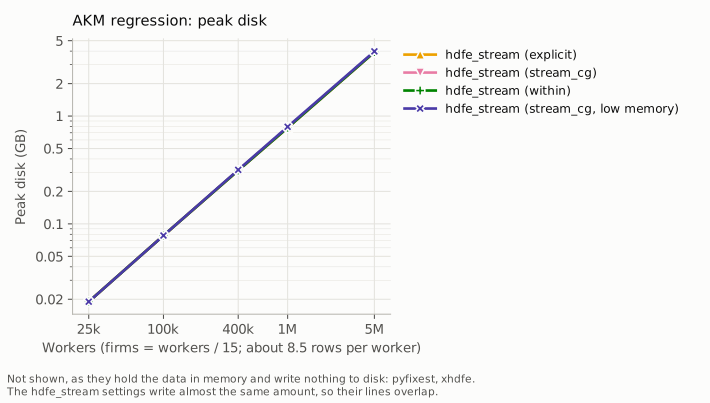
spends instead is disk: about 97 bytes per row, 4.1 GB at 42.5 million rows, freed
when the fit finishes. The in-memory libraries' peak grows in proportion to the
data. hdfe_stream's low-memory setting grows far more slowly: 0.9 GB at 25,000
workers, 1.4 GB at a million, 3.2 GB at five million.
It is not slower for it. From about a million workers up, hdfe_stream is the fastest configuration measured, and at 400,000 it is within half a second of xhdfe (4.1 s against 3.7 s). At 5 million workers it takes 52 s against pyfixest's 138 s (LSMR) or 1,960 s (MAP) and xhdfe's 238 s. With AKM panel data, reducing rows to worker-firm cells before solving more than pays for the disk traffic. The simulated panel has about 8.5 rows per worker and one cell per row, which suits this approach; a specification where the cell table is no smaller than the data, and the fixed effects are less local, may do worse.
Below about 400,000 workers, the in-memory libraries use less memory. Running any hdfe_stream fit costs about 0.9 GB, most of it importing polars, numba and scipy and starting Polars' streaming engine and numba's thread pools. On small data that floor dominates: at 25,000 workers xhdfe peaks at 0.29 GB and pyfixest at about 0.5 GB. This is the concrete version of "use pyfixest (or xhdfe) if your data fits".
The default pyfixest demeaner is not the one to compare against.
MapDemeaner (alternating projections) is 6 to 14 times slower than
LsmrDemeaner from 400,000 workers up, since many worker effects are the case alternating
projections struggles with. If you are comparing, compare against LSMR.
hdfe_stream's within solver uses more memory at scale: 14.9 GB at 5
million workers, where stream_cg and explicit stay near 4 GB. Prefer
those when memory is the constraint.
Many covariates
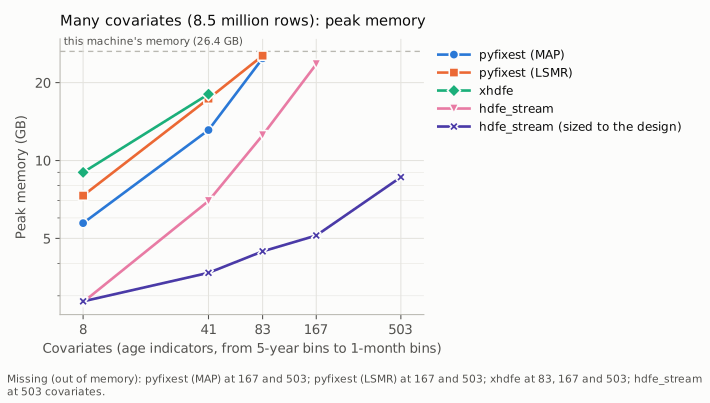
The same kind of comparison, holding the data fixed and varying its width: the
million-worker panel (8.5 million rows, 66,665 firms) with age entered as
indicators, log_earn ~ i(age_bin) | worker_id + firm_id, clustered by worker,
in bins from five years wide (8 indicators) down to one month (503). hdfe_stream
runs at its defaults and "sized to the design", with bucket, batch and row-group
sizes scaled down as the design widens (the rule is below). The numbers are in
benchmarks/results/covariates.csv; every
configuration that finished agrees with every other to within 1e-8.
python benchmarks/covariates_benchmark.py
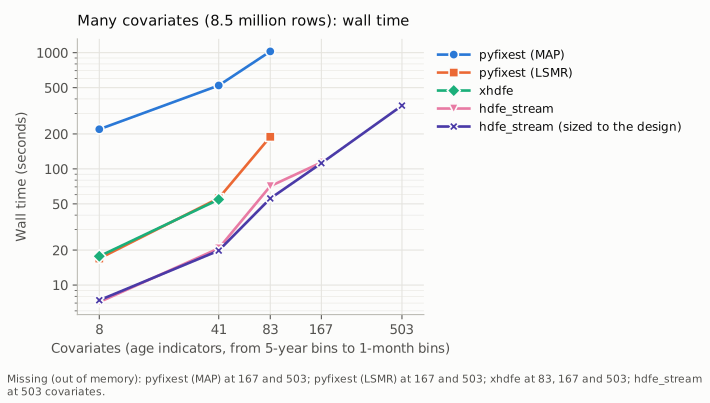
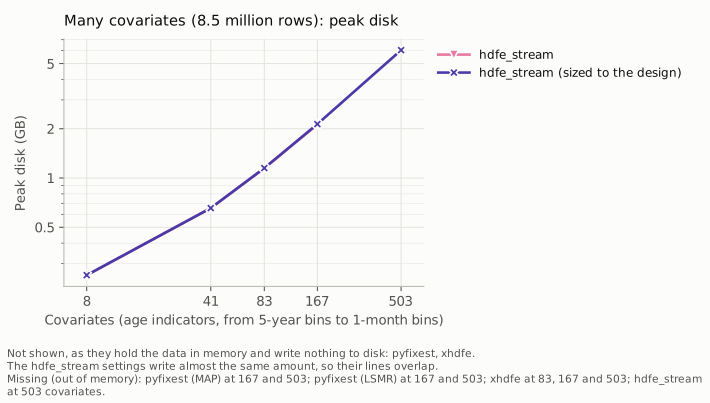
Wall time and peak memory ("—": ran out of this machine's 26 GB):
| covariates | pyfixest (MAP) | pyfixest (LSMR) | xhdfe | hdfe_stream | hdfe_stream, sized |
|---|---|---|---|---|---|
| 8 | 132 s, 5.7 GB | 16 s, 7.3 GB | 15 s, 9.1 GB | 7 s, 3.2 GB | 7 s, 3.0 GB |
| 41 | 520 s, 13.8 GB | 62 s, 18.2 GB | 60 s, 18.2 GB | 22 s, 6.9 GB | 20 s, 3.7 GB |
| 83 | 976 s, 25.2 GB | 156 s, 25.8 GB | 125 s, 26.0 GB | 58 s, 12.4 GB | 44 s, 4.9 GB |
| 167 | — | — | — | 127 s, 23.0 GB | 81 s, 5.1 GB |
| 503 | — | — | — | — | 329 s, 8.6 GB |
The in-memory libraries run out first. Their peak grows with rows × covariates. At 8.5 million rows all three were within about 1 GB of this machine's 26 GB at 83 indicators, and out of memory at 167. hdfe_stream sized to the design goes from 3.0 GB at 8 indicators to 5.1 GB at 167 and 8.6 GB at 503. Of that last figure, about 4.9 GB is the memory-mapped cell table: file pages the kernel can drop under pressure. The memory the fit itself allocated peaked at 4.6 GB (a separate profile, reading the process's anonymous and file-backed pages apart).
Size the batches to the design. At its defaults hdfe_stream holds a whole
bucket of up to 20 million rows, with every covariate, while it sorts; that is
fine for a handful of covariates and not for hundreds (23.0 GB at 167, out of
memory at 503). Every step that holds rows holds all the covariates, so scale
rows_per_bucket, batch_rows and row_group_size down with the width. The
benchmark aims at about 1 GB of design per bucket and 250 MB per batch and row
group, never above the defaults:
per_row = 8 * (k + 4)                   # k covariates, plus outcome and ids
batch = min(2_000_000, int(250e6 // per_row))
fit = feols_stream(fml, data, rows_per_bucket=min(20_000_000, int(1e9 // per_row)),
                   batch_rows=batch, row_group_size=min(500_000, batch))
Time grows with the square of the width. The cross-products cost k × k per row; they are formed chunk by chunk as BLAS matrix products, and 503 indicators take 5½ minutes where 167 take under 1½. hdfe_stream is the fastest configuration at every width measured.
Timings on this machine are noisy where memory is tight. Each point is one run. Repeated runs of the default configuration at 83 indicators, which holds 12.4 GB, took between 53 and 83 s; the sized configuration varied by about 15%. The differences between libraries above are far larger than that.
Disk grows with the width too, since the working copy of the rows carries every covariate: 0.3 GB at 8 indicators, 5.5 GB at 503.
How the design is built matters. A formula term such as i(age_bin) is
carried through the partitioning as the one column it is computed from, and the
indicators are built one bucket at a time. That works for any expression whose
value on a row depends on that row alone, which formula terms always do. With
the low-level StreamingHDFE, an expression that needs the whole column
(pl.col("x") - pl.col("x").mean(), a window, a shift) is detected and the design
is built before partitioning instead, with a warning: the estimates are the
same, the memory is not. Define such a column in the input LazyFrame to avoid
it. result.diagnostics["design_evaluated"] says which happened.
examples/wide_designs.py puts this together.
Trading memory for time
Same data, same solver, same answer — only how much is in flight at once:
python benchmarks/akm_benchmark.py --memory-sweep 1000000
8,500,353 rows, 1,000,000 worker effects
rows_per_bucket |
batch_rows |
wall time | peak memory | peak disk |
|---|---|---|---|---|
| 20,000,000 (default) | 2,000,000 | 11.2 s | 2,341 MB | 818 MB |
| 1,000,000 | 500,000 | 11.0 s | 1,849 MB | 821 MB |
| 250,000 | 200,000 | 11.6 s | 1,384 MB | 863 MB |
| 100,000 | 100,000 | 11.6 s | 1,555 MB | 876 MB |
The saving comes from the first two steps down; below that, the peak rises
again. The defaults are tuned for a
machine with room to spare; if memory is the binding constraint, set
rows_per_bucket to something near what you can afford and leave the rest
alone (with many covariates, scale batch_rows and row_group_size down too;
see many covariates). rhs_block bounds the other big
array (levels × variables), and
max_s_gb caps the explicit reduced matrix, above which solver="auto" falls
back to stream_cg by itself.
Leave-out estimation has a memory knob of its own, scratch_mb; see
docs/kss.md.
Measured on an Intel Core Ultra 7 258V, 8 cores, 26 GB RAM, Linux (WSL2); Python 3.14.8, polars 2.0.0, numpy 2.5.3, numba 0.68.0, scipy 1.18.1, pyfixest 0.60.0, xhdfe 2.28.1 (CPU backend). In the regression benchmarks hdfe_stream was measured on 2026-10-07 and pyfixest and xhdfe on 2026-10-06; the GLM and KSS benchmarks were measured on 2026-10-07 and 2026-10-08. The exact versions are in benchmarks/results/machine.json. Numba kernels are compiled on first use and cached to disk; the benchmark runs a warm-up fit so compilation is not charged to any configuration.
Choosing a solver
solver |
what it does | when |
|---|---|---|
"auto" (default) |
explicit, falling back to stream_cg if the reduced matrix would exceed max_s_gb |
leave it alone |
"explicit" |
builds the reduced matrix once and solves it in memory | fastest when it fits; its size depends on how levels co-occur, not on rows |
"stream_cg" |
applies the reduced matrix by streaming the cell table each iteration | when the reduced matrix is the thing that does not fit |
"within" |
hands the reduced system to within-py |
an alternative; no varying-slopes support |
The streamed dimension is chosen for you: an explicit stream= if given, else
the dimension carrying varying slopes, else the highest approximate cardinality.
result.diagnostics["stream"] says which and why.
Examples
Runnable, on simulated data, no setup — see examples/:
quickstart.py |
fit a model and read the results |
akm_variance.py |
the variance decomposition, in a streaming pass |
formulas.py |
the formula syntax, end to end |
weights_and_iv.py |
weights and 2SLS |
fewer_fixed_effects.py |
one fixed effect, or none |
glm.py |
Poisson with an offset, logit and probit, separation, and the incidental parameter bias |
wide_designs.py |
hundreds of covariates, and sizing the batches to them |
varying_slopes.py |
worker-specific trends, and the low-level interface |
out_of_core.py |
memory, disk, solvers, logging |
reporting.py |
tables and plots via pyfixest |
connected_sets.py |
connected components, min_degree pruning and the leave-one-out connected set, compared |
leave_out_kss.py |
the KSS bias correction, checked against the effects the data was built from |
Simulated data
hdfe_stream.simulate ships with the package, so you can try the library, or
check your own code, against data whose answer you know:
from hdfe_stream.simulate import simulate_akm

simulate_akm(n_workers=1_000_000).write_parquet("sim.parquet")
simulate_akm draws worker and firm effects explicitly and positively assorted,
with enough mobility to connect the firms into one component. simulate_rich
adds categoricals, non-fixed-effect cluster variables, weights, an IV block and
missing values; simulate_trends adds worker-specific time trends. All are
deterministic given a seed.
Poisson, logit and probit
from hdfe_stream import fepois_stream, feglm_stream

pois = fepois_stream("visits ~ x | worker_id + firm_id + year", "data/*.parquet",
                     offset="log_exposure", workdir="scratch")
logit = feglm_stream("promoted ~ x | firm_id + year", "data/*.parquet", "logit",
                     workdir="scratch")
These are fitted by iteratively reweighted least squares, each step a weighted version of the linear regression above. Pass 0 sorts the rows once. Each step then reads them once, rebuilding every row's linear predictor from the current coefficients, and solves the reduced system, starting from the previous step's solution.
Nothing row-sized is rewritten between steps, so the disk needed is about what OLS needs. A fit takes a few times as long as OLS on the same data, since it usually needs 6 to 10 steps. Benchmarks against pyfixest, over the AKM benchmark's panel sizes and over the number of covariates, are in docs/glm.md.
Fixed-effect levels whose effect would be infinite are dropped first: all-zero outcomes for Poisson, constant ones for logit and probit. Estimates, standard errors and deviance match pyfixest to about 1e-12. The few places where they deliberately differ are frequency weights, which here mean repeated rows, and logit and probit levels whose outcome is all 1, which are dropped. Both are described in docs/glm.md, along with the options and results.
Leave-out variance components (KSS)
The plug-in AKM decomposition is biased: worker and firm effects are estimated
with error, which inflates their variances and attenuates their covariance.
leave_out_kss applies the bias correction of
Kline, Saggio and Sølvsten (2020), streaming
like the rest of the package:
from hdfe_stream import leave_out_kss

lo = leave_out_kss("log_earn ~ age_squared | worker_id + firm_id",
                   "data/*.parquet", workdir="scratch", se=True)
print(lo.summary())
It follows Saggio's reference implementation,
LeaveOutTwoWay. It prunes to the
leave-one-out connected set (which connected_components(..., leave_one_out=True) finds on its own, ahead of time), leaves out a
worker–firm match by default, and approximates leverages by random projection. It supports weights, standard
errors, and KSS's weak-identification diagnostic and q = 1 interval.
docs/kss.md covers the options, the standard errors and their measured coverage, weak identification, validation, reproducibility, and performance against xhdfe: at 5 million workers, 4.8 GB of memory against xhdfe's 20 GB, with standard errors in 49 minutes where xhdfe's did not finish in three hours. docs/kss_methodological_differences.md lists every way this implementation differs from LeaveOutTwoWay, VarianceComponentsHDFE.jl, xhdfe and pytwoway, with the motivation and measured effect of each.
Reproducibility
Everything in a fit is deterministic: the same data and the same options give the same numbers, with no random component anywhere — to floating-point rounding. Repeated fits normally agree bit for bit, but aggregation runs in parallel, and once, under heavy CPU load from another process, two identical fits differed in the last digit. Treat agreement to about 1e-12 as the guarantee, not bitwise identity.
The exception is leave-out estimation, which uses random projection and random draws. Its results are reproducible from the seed but not deterministic; docs/kss.md says exactly what they depend on and what to report in a paper.
Correctness
The test suite checks every feature against pyfixest on simulated data —
coefficients, standard errors under each vcov, residuals, fixed effects, fit
statistics, the sample kept after dropping missing values, and the exact set of
coefficient names and dropped collinear terms. Varying slopes have no pyfixest
equivalent, so they are checked against a brute-force regression with explicit
worker-by-slope dummies; three-way clustering is checked against an
inclusion–exclusion sum built from pyfixest's own score matrix. Poisson, logit
and probit are checked against pyfixest's fepois and feglm, and their
frequency weights against pyfixest on the data with each row repeated.
pip install -e ".[test]"
pytest
Limitations
- Varying slopes only on the streamed dimension, and only one dimension may carry them.
- CRV3 only with nested fixed effects. The cluster jackknife is computed by downdating the fit, which is exact when every fixed effect is nested within the clusters (worker effects clustered by worker, firm × year effects by firm) or there are none. With fixed effects that are not nested, as in an AKM model clustered by worker, the jackknife has to re-estimate the fixed effects once per cluster, and the fit refuses; use CRV1, or pyfixest, which refits. CRV3 is also one-way and OLS only (pyfixest has no IV CRV3 either). No CRV2 and no wild bootstrap.
- Poisson, logit and probit: no CRV3, IV, varying slopes or leave-out
estimation; no detection of separation by the covariates (pyfixest's
"ir"check), only by the fixed effects; and no correction for the incidental parameter bias of logit and probit with fixed effects estimated from few observations, as in pyfixest and fixest. During the iterations the streamed dimension's effects are held in memory, one float per group per coefficient set. See docs/glm.md. - A converted result cannot recompute its own vcov, because it holds no
data. Ask for what you need at fit time via
cluster=. - Formula support pins a pyfixest range (
>=0.50,<0.61), because it uses pyfixest's internal formula modules.StreamingHDFEhas no such dependency. - Needs scratch disk, roughly the size of your data during the fit. Leave-out estimation adds to that: it memory-maps its row-sized accumulators rather than holding them, which is what keeps it inside a bounded memory footprint, at about 90 bytes per row of scratch while it runs.
- Wide designs need the batch sizes scaled down (see many covariates): the defaults hold a whole bucket of rows with every covariate. And the cross-products cost k × k per row, so time grows with the square of the number of covariates.
- Leave-out estimation handles one outcome at a time, and its standard errors omit the split-sample refinement of KSS §4.2 (so they are conservative, as their Lemma 5 provides for). Under weak identification it supplies the q = 1 interval, not KSS's q > 1 generalization. Leaving out a match, as it does by default, var(alpha) has no standard error and the covariance no q = 1 interval. See docs/kss.md.
- Column names starting with
__hdfe_are reserved for the estimator's own columns, and a source that has one is refused. Any other name is safe.
1 maintainer

Metadata
1 maintainer
Release files for hdfe-stream 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| hdfe_stream-0.3.0.tar.gz | 394.4 kB | With provenance | Details for hdfe_stream-0.3.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| hdfe_stream-0.3.0-py3-none-any.whl | Python 3 | none | any | Details for hdfe_stream-0.3.0-py3-none-any.whl |
Total release size: 582.1 kB
Release files / hdfe_stream-0.3.0.tar.gz
| Download URL | hdfe_stream-0.3.0.tar.gz |
|---|---|
| Size | 394.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
71efe439dc36230837582c32b363b6648980254e3a559c50aa8980e1710433e4
|
|
BLAKE2b-256 checksum How to use checksums |
22d91f9228e55479dde915d7e868ad0e212e8e1bbce5f6eafb47e06cab63e963
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency logRelease files / hdfe_stream-0.3.0-py3-none-any.whl
| Download URL | hdfe_stream-0.3.0-py3-none-any.whl |
|---|---|
| Size | 187.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ca0a8525e6675823d03f2933e9f0a8cbc75df7a878127f2cc89e06b97edb0ebe
|
|
BLAKE2b-256 checksum How to use checksums |
d572a0c44b0fcef33dbc9e690b30b9e00dafa4ab6f1e3d607f64f2d3f6371eb0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency logSecurity for hdfe-stream 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for hdfe_stream-0.3.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














