
hdfe-stream
Regression with several high-dimensional fixed effects, on data that does not
fit in memory: linear (feols_stream), and Poisson, logit and probit
(fepois_stream, feglm_stream), with the Kline–Saggio–Sølvsten bias
correction for AKM variance decompositions (leave_out_kss).
from hdfe_stream import feols_stream

fit = feols_stream(
    "log_earn ~ age_squared + age_cubed | worker_id + firm_id + year",
    "data/*.parquet",              # a Parquet path or glob, never fully loaded
    workdir="scratch",             # where intermediates go: disk, not memory
    vcov={"CRV1": "worker_id"},
)
fit.summary()
Formulas follow pyfixest/fixest syntax and are parsed by pyfixest's own parser, so the syntax, the coefficient names and the results all match. The difference is where the work happens: rows are streamed off disk in batches and never held as a design matrix.
The data can be a Parquet path or glob, a Polars LazyFrame, or a Polars DataFrame. Using file paths or LazyFrames keeps memory usage to a minimum, but using DataFrames works well for smaller data and for trying things out.
Documentation: leetucker.github.io/hdfe-stream, with examples, the KSS bias correction, benchmarks and the function reference.
Features
- Any number of fixed effects,
including one or none,
and interactions (
firm_id^year) - pyfixest formula syntax: transformations, categoricals, interactions, event studies
- Several models in one call, sharing passes over the data
- Standard errors: iid, robust, multi-way clustered, and one-way CRV3
- Weighted least squares and 2SLS
- Poisson, logit and probit
- Varying slopes in fixed effects
(
worker_id[t]), on the streamed dimension only - Wide designs, with hundreds of covariates
- Connected components,
the largest connected set, and
min_degreepruning - AKM variance decompositions, in a streaming pass
- KSS leave-out variance components, with standard errors and weak-identification diagnostics
- The sample, row by row: which rows were dropped and why, and residuals joined back to the source
- Regression tables and plots through pyfixest
- Memory and disk controls, a choice of solvers, and logging
- Simulated panels with known effects, for testing
When to use this, and when not to
Use pyfixest. It is the better tool whenever your data fits in memory:
mature, broader in scope, more inference options, and no scratch directory to
think about. If a pandas DataFrame of your data fits comfortably in RAM, stop
reading.
Use this when it doesn't. The case it was built for is a matched employer–employee panel — tens of millions of rows, millions of worker effects, an AKM variance decomposition — on a machine or a secure enclave where the data is larger than the memory you are allowed. Concretely, reach for it when:
- the data does not fit in memory, or fits so tightly that nothing else does;
- you have one very high-cardinality dimension (workers, patients, students) whose groups each touch only a few levels of the others;
- you want worker-specific slopes as well as intercepts (
worker_id[t]), which multiplies the parameter count by the number of slopes; - the design is wide: hundreds of covariates, such as a categorical expanded into fine indicators or many interactions. An in-memory library needs rows × covariates in memory before it starts; this needs one batch of rows × covariates at a time, with any number of fixed effects, including one or none (see many covariates);
- you need a hard, predictable memory ceiling — a shared cluster, or a job that must not be the one that gets killed.
You are trading memory for disk, and you need scratch space: about five times
the size of your Parquet input while the fit runs, and only the result files
once it finishes. See performance for what that buys. Point
workdir= at it, or set the HDFE_STREAM_WORKDIR environment variable once
(for example to a cluster's scratch filesystem) and leave workdir out; a
workdir passed to a call takes precedence, and with neither, the system
temporary directory is used.
How it works, in one paragraph
One fixed-effect dimension — normally the largest — is streamed: it
is never represented as a vector in memory. Every other dimension is held as a
vector sized by its number of levels, not rows. Rows are read in batches,
hash-partitioned into buckets by the streamed dimension, sorted one bucket at a
time, and reduced to a table of cells (one per combination of fixed-effect
levels). The reduced normal equations for the non-streamed dimensions are then
solved by conjugate gradient, and the streamed effects are recovered group by
group in a final pass that writes residuals and fixed effects straight to
Parquet. So memory scales with firms × years, not with workers × rows, and that
asymmetry is the whole design. The covariates travel with the rows: what is
held at once is one bucket or batch of rows × covariates, never all of them,
which is why a wide design fits where an in-memory one does not. Full detail is in
hdfe_stream/__init__.py.
Install
pip install hdfe-stream[formula] # formula syntax needs pyfixest
polars, numpy, numba, pyarrow and scipy are required. The extras:
| extra | what it adds |
|---|---|
formula |
feols_stream formula syntax and pyfixest reporting (pyfixest, formulaic, pandas) |
within |
the solver="within" backend |
amg |
algebraic multigrid preconditioning (precond="amg") for hard geometries |
all |
all of the above |
test |
the test suite |
docs |
building the documentation (Sphinx) |
On Python 3.15, pyfixest 0.60 (for the formula extra) has no wheels yet. It
builds from source with a Rust toolchain and
PYO3_USE_ABI3_FORWARD_COMPATIBILITY=1 set; everything else installs from
wheels.
Without formula you still get StreamingHDFE, the lower-level interface that
takes column names or Polars expressions instead of a formula string.
Performance
The standard three-way AKM regression,
log_earn ~ age_squared + age_cubed | worker_id + firm_id + year, clustered by
worker, on a simulated panel of 5 million workers and 42.5 million rows,
against pyfixest and
xhdfe. Every configuration agrees on
the coefficients to within 3e-10.
| configuration | wall time | peak memory | peak disk |
|---|---|---|---|
| pyfixest (MAP, its default) | 1,960 s | 20.7 GB | — |
| pyfixest (LSMR) | 138 s | 25.3 GB | — |
| xhdfe | 238 s | 19.0 GB | — |
hdfe_stream (explicit, its default) |
52 s | 4.1 GB | 4.1 GB |
hdfe_stream (stream_cg) |
54 s | 4.0 GB | 4.1 GB |
hdfe_stream (stream_cg, low memory) |
60 s | 3.2 GB | 4.3 GB |
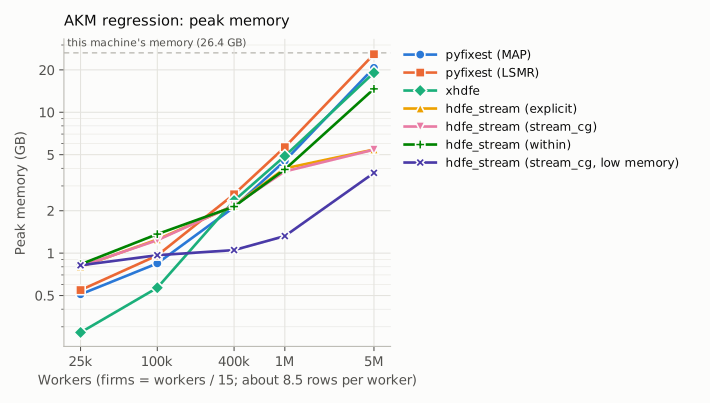
On small data the in-memory libraries use less memory: an hdfe_stream process costs about 0.9 GB before it has done anything. The benchmarks cover every size from 212,000 rows up, designs with up to 503 covariates, Poisson and logit, and the KSS decomposition, with how each was measured.
Documentation
- Examples: one page per feature, on simulated data that ships with the package: formulas and standard errors, weights and IV, Poisson and logit, wide designs, varying slopes, connected sets, running out of core, and reporting.
- Leave-out variance components: the Kline–Saggio–Sølvsten bias correction for the AKM decomposition, its standard errors and weak-identification diagnostic, and every way it differs from the reference implementations.
- Benchmarks: time, memory and disk against pyfixest and xhdfe.
- Function reference: every option.
- Limitations: what it does not do.
- Changelog.
The scripts behind the examples are in examples/, and the
benchmarks in benchmarks/.
1 maintainer

Metadata
1 maintainer
Release files for hdfe-stream 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| hdfe_stream-0.4.0.tar.gz | 442.1 kB | With provenance | Details for hdfe_stream-0.4.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| hdfe_stream-0.4.0-py3-none-any.whl | Python 3 | none | any | Details for hdfe_stream-0.4.0-py3-none-any.whl |
Total release size: 644.3 kB
Release files / hdfe_stream-0.4.0.tar.gz
| Download URL | hdfe_stream-0.4.0.tar.gz |
|---|---|
| Size | 442.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
87f74f3f9f3a5494133d9bba7f3f0b8a46ad227cb1a567b42cb8926f59c3edf4
|
|
BLAKE2b-256 checksum How to use checksums |
ef72d108f1df0be7a07494bd576236a8f23af32ba0c0f8dd379e9fcb3ff7753b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency logRelease files / hdfe_stream-0.4.0-py3-none-any.whl
| Download URL | hdfe_stream-0.4.0-py3-none-any.whl |
|---|---|
| Size | 202.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d8294b8c5b565bf91920c205d287ebba47a417aaaecebf3f6a1bd339e96d8300
|
|
BLAKE2b-256 checksum How to use checksums |
cc7dce0fe3b92cbf90414909f366cc687425a9bdc9aa7f24b561da0403d7a181
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency logSecurity for hdfe-stream 0.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for hdfe_stream-0.4.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














