
Hearthwork
Website and docs: billymrx1.github.io/hearthwork
Hearthwork runs a local AI model on your own computer and connects your coding agent to it, from one menu. The model runs on your GPU and RAM; the agent is Claude Code, Codex, OpenCode, Qwen Code or Aider. Hearthwork sets itself up for your hardware, tells you honestly whether your computer is good enough, and handles the small incompatibilities that otherwise break agents on local models.
Works on Windows, macOS and Linux. Needs Python 3.9+ and the agent(s) you want to use; no extra Python packages.
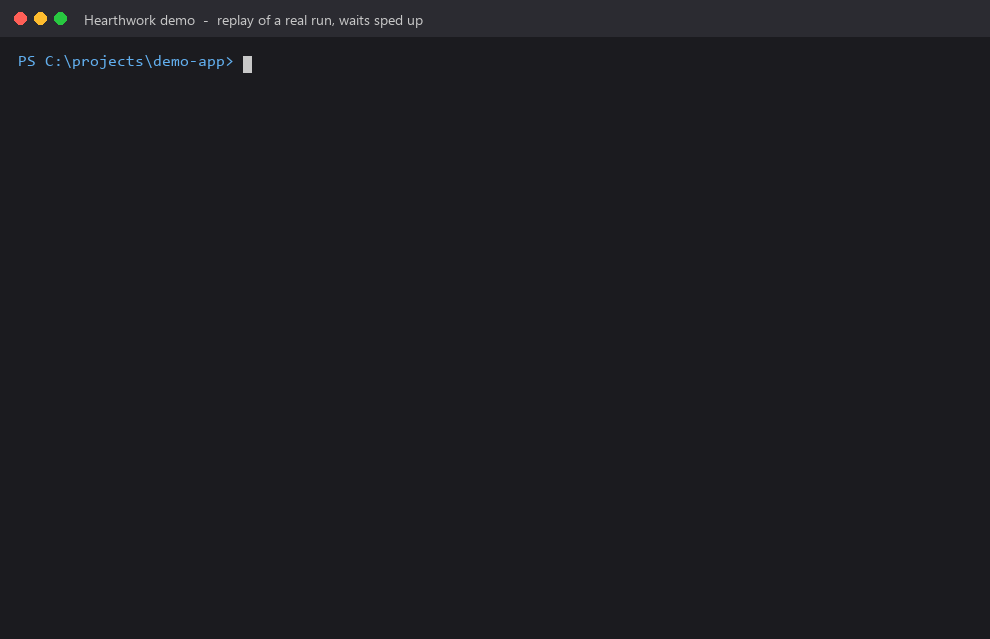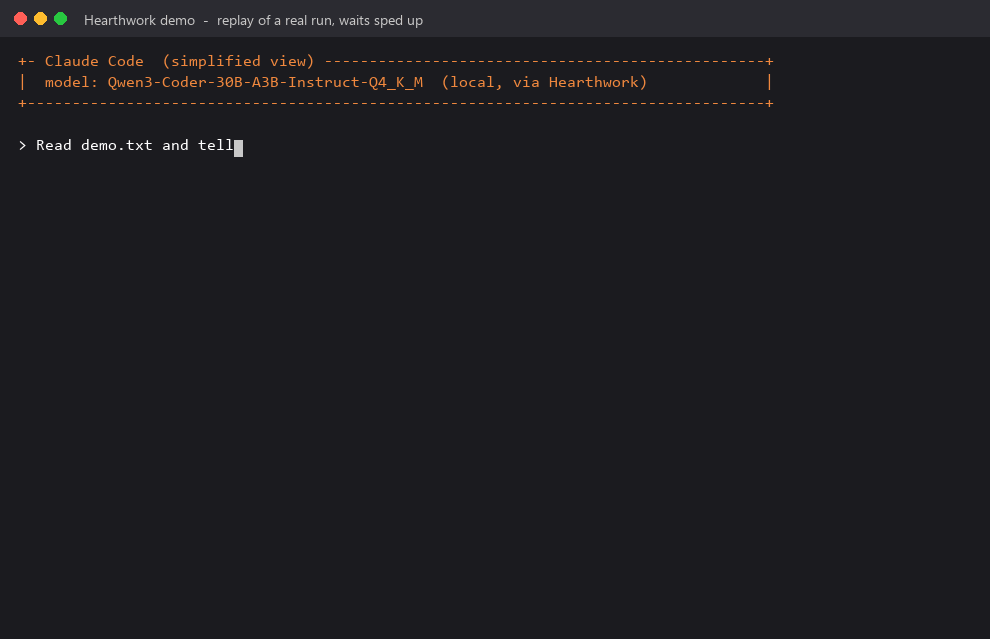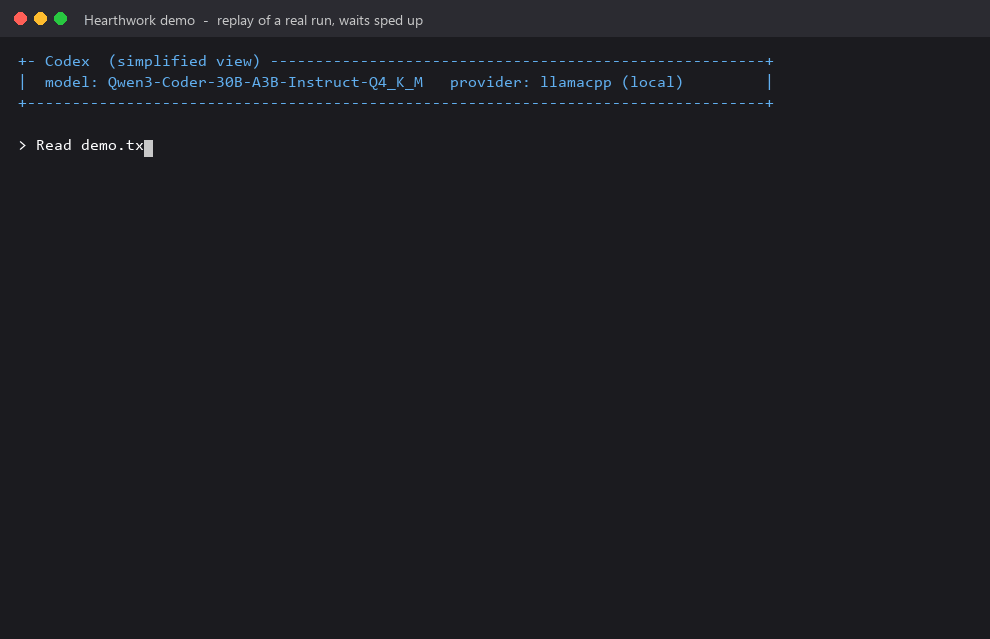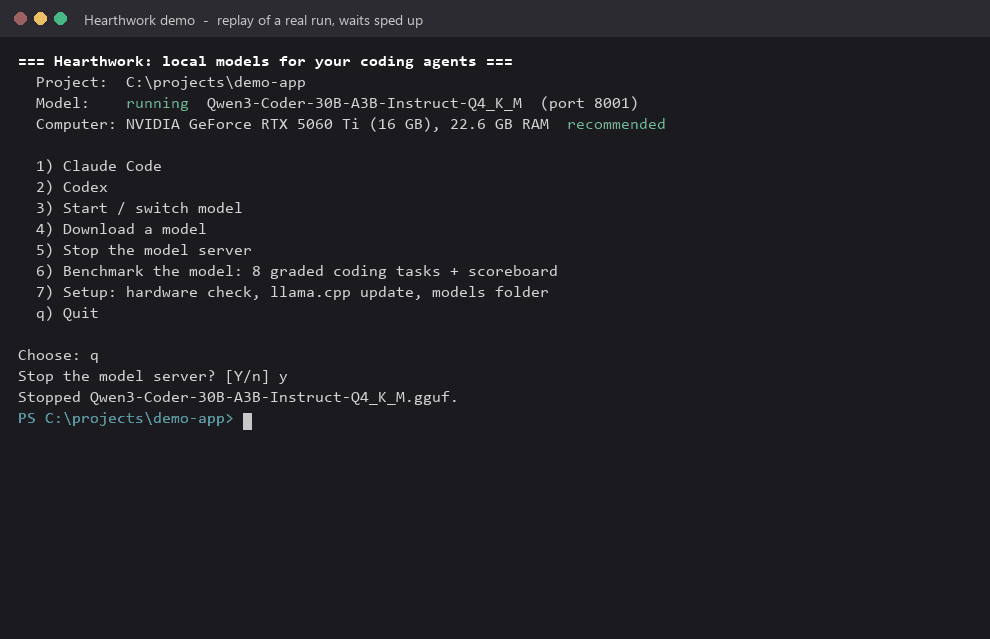
A replay of a real run. Waits are sped up, the agent screens are simplified, and paths are shortened.
Quick start
uvx hearthwork check          # 1. is this computer suited, and which models fit? (installs nothing)
uv tool install hearthwork    # 2. install (or: pipx install hearthwork)
hearthwork model unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF   # 3. download a model that fits
cd my-project
hearthwork claude             # 4. run an agent on the local model (also: codex, opencode, qwen, aider)
The first run sets things up for you (hardware check, llama.cpp, models folder). Run hearthwork alone for a menu with the same choices.
What you get
- Honest hardware check and model recommendations computed from this computer's specs (Choosing a model).
- Five agents, one way to run each (Using agents).
- One host per computer that owns the model and a single request queue for every client, cleans requests up and repairs tool calls (How it works).
- Share the model with other computers, at home or through Tailscale (Using the model from another computer).
- OpenAI and Anthropic compatible API for any other tool (API mode).
- Local agents as subagents for other agents, by command or MCP (Local agents as subagents).
- Resource budgets so the model leaves room for your other work (Resource budgets and presets).
- Verified setup profiles you can save, export and re-check (Setup profiles).
- Model switching, idle unload and automatic recovery (Model switching and idle unload, Recovery).
- Diagnostics that tell you which layer is at fault (Diagnostics).
- A benchmark of your own setup (Benchmark).
Install and update
uv tool install hearthwork
or pipx install hearthwork. The latest code from GitHub: uv tool install git+https://github.com/BillyMRX1/hearthwork.
This gives you one command, hearthwork.
- Update:
hearthwork update(oruv tool upgrade hearthwork). - Version and data folder:
hearthwork --version. - Setup again:
hearthwork setup(--update-llamagets the newest llama.cpp,--resetstarts from scratch).
Upgrading from the clone version. Earlier versions ran from a cloned folder with .bat/.sh scripts; those are gone. On first run Hearthwork offers to import an old setup it finds, or run hearthwork setup --import <old folder>. It copies your settings, llama.cpp, prompt caches and benchmark results and leaves the old folder as it is.
First-run setup
hearthwork (or hearthwork start) runs setup automatically when nothing is configured. It:
- Checks the computer: OS, CPU, RAM and GPU (NVIDIA, AMD, Intel, Apple) with its memory. For AMD/Intel it reads the GPU's own memory, so integrated graphics are not mistaken for a real GPU.
- Judges whether a local model is worth it here and says why (see Choosing a model).
- Gets llama.cpp: one already in
bin/or on PATH, otherwise the newest official build that matches the hardware: CUDA for NVIDIA (13 or 12, chosen from the driver), ROCm for AMD RDNA2 or newer (otherwise Vulkan), Vulkan or SYCL for Intel, Metal on macOS, CPU if there is no GPU. Builds live side by side inbin/<runtime>-b<build>/(seehearthwork runtime); a new build is smoke-tested before use and the previous one is kept forhearthwork runtime rollback. - Asks for the models folder. It finds LM Studio's folder and offers it, so both tools share the same files.
- Picks settings for this hardware: context
auto, prompt batch size, VRAM headroom and an 8-bit KV cache. - Saves everything to
config.jsonin the data folder.
Choosing a model
hearthwork check [--json] # or, without installing: uvx hearthwork check
It shows the hardware, a verdict, the installed agents, and the best version of each suggested coding model that fits (sizes live from Hugging Face). Recommendations are computed from this computer's specs, not from a fixed list.
| Verdict | Meaning |
|---|---|
| Recommended | A GPU with 12 GB or more and enough GPU memory + RAM for a good coding model, or a Mac with 32 GB or more. |
| Limited | A smaller GPU or tight memory. Expect slower replies, or a smaller, weaker version of the model. Setup asks before continuing. |
| Not recommended | No GPU, integrated graphics only, or very little memory. Nothing is downloaded unless you agree. |
The thresholds are estimates; your own numbers come from hearthwork bench.
Requirements for a model: any GGUF model works if it supports tool calling (agents read, edit and run things through tools) and fits. Mixture-of-experts (MoE) models stay fast even partly in RAM; dense models slow down a lot once they spill out of GPU memory.
Downloading:
hearthwork model unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF                    # a repo: lists files, you pick one
hearthwork model https://huggingface.co/<org>/<repo>                           # same, as a link
hearthwork model https://huggingface.co/<org>/<repo>/blob/main/<file>.gguf    # one file
- The repo list shows each file's size, smallest first, and whether it fits: in GPU memory (fastest), GPU + RAM (slower; fine for MoE), or too big.
- Files go to
<models folder>/<org>/<repo>/(LM Studio's layout). Multi-part models download all parts, and interrupted downloads resume when you run the command again. - Gated or private repos: set
HF_TOKEN.
Context. With context: auto Hearthwork reads the model file (trained context, layers, KV heads, attention layout) and, with your GPU memory and RAM, works out a range for each model, e.g. 128K (auto; range 64K-256K, model max 256K): a minimum of 64K (agents' own prompts are large), a recommended size (what auto starts with, at most 128K) and a maximum that fits GPU memory + RAM. hearthwork context [model] [N|auto] shows the range or saves a size for a model (96K, 98304). Precedence: start --context > saved for the model > server.context in config.json > auto.
Custom chat templates. If a model's template is broken in some other way, put a fixed copy at templates/<model file name without .gguf>.jinja in the data folder.
Using agents
| Agent | Command | Install | API |
|---|---|---|---|
| Claude Code | hearthwork claude |
https://code.claude.com | Anthropic Messages |
| Codex | hearthwork codex |
npm i -g @openai/codex |
OpenAI Responses |
| OpenCode | hearthwork opencode |
npm i -g opencode-ai |
OpenAI Chat Completions |
| Qwen Code | hearthwork qwen |
npm i -g @qwen-code/qwen-code |
OpenAI Chat Completions |
| Aider | hearthwork aider |
uv tool install --python 3.12 aider-chat |
OpenAI Chat Completions |
- Run
hearthwork <agent>from the project you want it to work on. A model is started first if none is running. Extra arguments go to the agent, e.g.hearthwork codex exec "...",hearthwork aider --message "...". hearthwork agentslists which are installed (with version), the API each uses, how Hearthwork connects it, and the install command of the missing ones.--dry-run(first argument) prints the exact command, the environment variables Hearthwork sets (keys masked) and the files it generates, and starts nothing:hearthwork opencode --dry-run,hearthwork task --agent qwen --dry-run "fix the failing test". Aider has a--dry-runof its own, which still works after another argument.- Your own config is never edited. Each agent gets environment variables, command-line flags or a generated file in the data folder (for example Codex gets
-coverrides, OpenCode getsOPENCODE_CONFIG_CONTENT, Qwen Code gets a settings file throughQWEN_CODE_SYSTEM_SETTINGS_PATH). Agents still write their own history where they always do. - Each agent is told the real context window and output limit of the running (or shared) model.
- Quirks: Aider is not an agent loop (it edits files from a reply format and cannot read or run anything on its own, so
taskswitches its shell commands off) and keeps its own git behaviour. Qwen Code runs a background memory extraction that makes extra requests. Install Aider with Python 3.12:aider-chatfails to buildscipyon 3.13+ on Windows. - Not supported yet: Goose, Crush, Kilo Code CLI, OpenHands, Hermes. A clean, non-invasive way to point each at a custom endpoint was not verified, so they are left out rather than guessed.
hearthwork api --showgives setup snippets for tools without a launcher. - Adding an agent means adding one entry to
HARNESSESinsrc/hearthwork/harnesses.py; the menu,agents,task, MCP andbenchpick it up.
Claude Code settings. hearthwork claude writes claude-settings-<model>.json in the data folder and starts Claude Code with --settings pointing at it; your ~/.claude/settings.json is not changed and plain claude stays your normal cloud Claude. It sets permissions.defaultMode: "default" (ask before risky actions; in auto mode the local model would check every command first, which is slow and can time out) and a status line such as local · <model> · 64K. If ~/.claude/settings-hearthwork.json exists it is merged on top (HEARTHWORK_CLAUDE_OVERRIDES points to another file). --max-output N caps each reply (default 4096 tokens).
Short commands.
hearthwork alias add ccl claude     # `ccl` now runs `hearthwork claude`
hearthwork alias list
hearthwork alias remove ccl
A launcher (ccl.cmd on Windows, a shell script elsewhere) is created next to the hearthwork command. Names of existing commands are refused, and only launchers Hearthwork created can be removed.
How it works
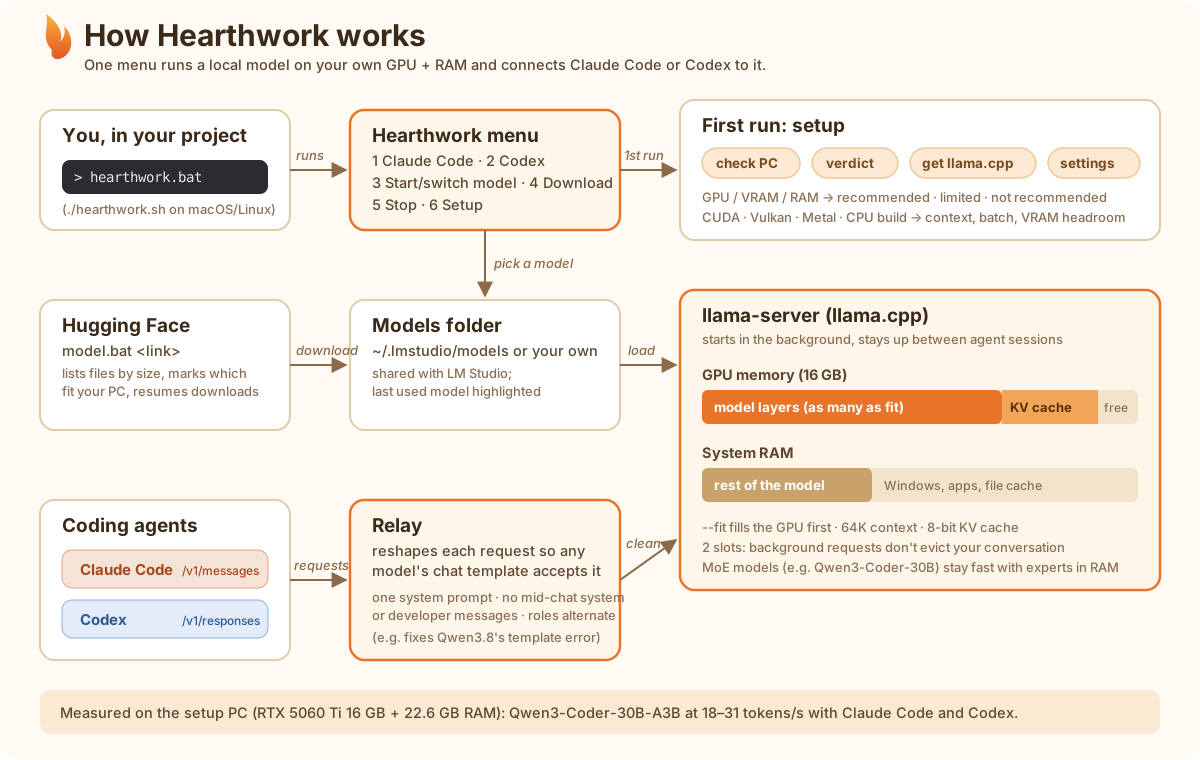
One host per computer. hearthwork start (or any command that needs the model) starts the Hearthwork host in the background. It owns llama-server and the single relay and request queue that every client goes through: agents, task/MCP, hearthwork api and hearthwork share. It listens on 127.0.0.1:8470; each agent session identifies itself with a token like local-claude-ab12. The model keeps running between agent sessions and nothing opens a window. A model started by an older Hearthwork is adopted, not restarted.
- Queue. The host runs at most as many requests at once as the model has slots (2 by default); the rest wait in one first-come queue (16 waiting, 10 minutes at most). When it is full the caller gets an overload error in its own API format (Anthropic
overloaded_error, HTTP 529; OpenAI-style 503 withRetry-After). A caller that disconnects leaves the queue, or its upstream request is closed. - Request cleanup. Strict chat templates reject a second system message, unknown roles, or two user messages in a row, and agents send them. The relay reshapes requests for all three APIs so any model's template accepts them. It also keeps the prompt prefix stable (for example it removes Claude Code's per-session billing-header line and token counter) so llama.cpp can reuse its cache.
HEARTHWORK_RELAY_DUMP=<folder>writes every request before and after cleanup, for debugging. - Tool-call repair. Some models write a tool call as plain text in a format the chat template does not parse. When a request offered tools and the reply holds no structured call, the relay looks for one in the text and rewrites the reply into the API's own form (Anthropic
tool_use, OpenAItool_calls, Responsesfunction_call), streaming or not. Formats tried: Mistral[TOOL_CALLS],[Calling tool: f({...})],<tool_call>{json}</tool_call>,<function=name>..., XML-style tags, pythonicf(a=1)and raw JSON. A call is accepted only when the tool exists in the request and its arguments fit the schema's required keys and basic types; otherwise the reply is untouched. Streams are delayed only when the text starts to look like a call. Each repair is logged and shown byhearthwork doctor. Turn it off withHEARTHWORK_TOOL_REPAIR=0. - Context sizing. The context is computed per model and computer (see Choosing a model). A prompt that does not fit gets a clear error in the API's own format, with the command to raise the context; requests are never truncated.
- GPU first. llama.cpp's
--fitputs as much of the model on the GPU as fits, keeping some free for the desktop, and runs the rest from RAM, on every start. Prompt batch is 4096 on GPUs with 12 GB or more, with 2 slots so background requests do not evict the conversation's cache. - Faster first messages. Each agent's processed system prompt is saved to
cache/slots/when a session ends or the server stops, and restored when the server starts. - Settings live in the
serversection ofconfig.json;hearthwork setuprecalculates them.hearthwork start --model Xand--context Noverride a single run.
Commands
| Command | What it does |
|---|---|
hearthwork |
The menu. |
hearthwork claude|codex|opencode|qwen|aider [args] |
Run that agent on the local model. Add --dry-run first to show what would run. |
hearthwork agents |
Supported agents: installed, version, API, how each connects. |
hearthwork task "TASK" |
One coding task for another agent to delegate (no terminal needed). |
hearthwork mcp [install claude|codex|print] |
MCP server so any agent can use the local model as a subagent. |
hearthwork start [--model X] [--context N] [--force] [--over-budget] |
Start the model under the host, or switch it. |
hearthwork stop [--force] |
Save the prompt cache, then stop the model and the host. |
hearthwork serve [--model X] |
Run the host in this terminal with its log; Ctrl+C stops it. |
hearthwork idle [30|off] |
Unload the model after N idle minutes (off by default). |
hearthwork budget [show|use dedicated|balanced|work|set ...|reset] |
Resource budget. |
hearthwork context [model] [N|auto] |
Context range per model; save a size for a model. |
hearthwork status [--json] |
Host, model, context, slots, requests per client, budget, switch, idle and recovery state. |
hearthwork logs [--server] [-f] |
The host's log; --server shows llama-server's output. |
hearthwork doctor [--agent X] [--quick] [--json] |
Compatibility check; says which layer is at fault. |
hearthwork diagnose [--last N | --since 30m] [--client X] [--json] [--export FILE] |
What limited your sessions, from measured numbers. |
hearthwork check [--json] |
Is this computer suited, and which models fit. |
hearthwork model <link> |
Download a GGUF model from Hugging Face. |
hearthwork profile save|list|show|check|apply|export|import |
Verified setup profiles. |
hearthwork share [--port N] [--allow-public] [--tailscale] |
Share the running model with other computers. |
hearthwork connect [host[:port]] |
Use the model of a computer that is sharing. |
hearthwork disconnect |
Back to local models. |
hearthwork devices [remove <name>] |
Trusted devices; remove revokes one. |
hearthwork api [--port N] [--show] |
OpenAI + Anthropic compatible endpoint on this computer. |
hearthwork alias add|list|remove |
Short commands for agents. |
hearthwork bench [--agent X] [--all] [--warmup] [--show] |
Graded coding tasks through an agent, with a scoreboard. |
hearthwork runtime [install <name>|use <name>|update|rollback] |
llama.cpp engines (CUDA, ROCm, Vulkan, SYCL, Metal, CPU) side by side. |
hearthwork setup [--update-llama] [--reset] [--import FOLDER] |
Hardware check, llama.cpp download/update, models folder. |
hearthwork update |
Update Hearthwork itself. |
hearthwork --version |
Version and data folder. |
Using the model from another computer
Run the model on one computer (say, a PC with a GPU) and use any supported agent from another one. Both need Hearthwork; the second needs no model, llama.cpp or setup.
hearthwork share           # on the computer with the model; leave it running
hearthwork connect         # on the other computer: finds it, then asks for the PIN shown on the first
hearthwork claude          # now uses the other computer's model (same for every agent, the menu, bench)
hearthwork disconnect      # back to local models
- Pairing.
connectasks to pair and the host shows a 6-digit PIN to type on the other computer. The PIN works for 2 minutes, 3 wrong tries end the request, and too many wrong PINs lock pairing for 10 minutes. The host then gives the computer a long random key (it keeps only a hash), so later connections need no PIN. - Devices.
hearthwork deviceslists trusted computers;hearthwork devices remove <name>revokes one at once. - Same cleanup. Requests are cleaned up on the host, so the other computer needs no model-specific setup. It uses whatever model the host runs and cannot start, stop or switch it.
- Windows host. The firewall may ask to allow Python; allow it on private networks. Sharing is refused while a network is marked Public (mark it Private, or pass
--allow-public). - Discovery uses UDP port 8485 and sharing uses port 8484. If discovery fails, run
hearthwork connect <ip>[:8484]. - Limits. On a home network the traffic is plain HTTP (not encrypted), so use it on networks you trust only.
From anywhere with Tailscale
Tailscale is a WireGuard-based private network between your own devices. It is optional; without it nothing changes. Install it and sign in on both computers, then:
hearthwork share --tailscale   # on the model computer
hearthwork connect             # on the other one: lists LAN hosts and Tailscale peers "(tailscale)"
- Host:
shareprints the Tailscale address and MagicDNS name. With--tailscalethe host accepts only Tailscale and local computers (plus your local network when no network is Public). - Client:
connectalso asks every online Tailscale peer, so no address is needed. Pairing stores every address of the host; each run tries the LAN first, then Tailscale, so the same key works at home and away.hearthwork statusshows the route. - Security: Tailscale traffic is encrypted end to end and only devices of your tailnet can reach the host. The PIN and device keys still apply, since a tailnet can be shared with other people.
API mode
hearthwork api is one local endpoint that speaks both the OpenAI and the Anthropic API, for tools Hearthwork has no launcher for (the official SDKs, Continue, your own scripts). It uses the same request cleanup as the launchers.
hearthwork api                      # leave it running; Ctrl+C stops it
hearthwork api --show               # copy-paste setup for each tool
- OpenAI: base URL
http://127.0.0.1:8080/v1(chat/completions,responses,completions,models, andembeddingsif the model supports it). Anthropic: base URLhttp://127.0.0.1:8080(v1/messages,v1/messages/count_tokens). Streaming works. - This computer only (127.0.0.1). For other devices use
hearthwork share.--port Nchanges the port;--api-key KEYrequires a key (Authorization: Bearerorx-api-key), otherwise any program on this computer can use the model. - Model: if none is running, the last used one is started.
/v1/modelslists the running model first, then every local model. Any model name in a request uses the running model. --allow-switch: a request whose"model"matches another local model file switches to it through the host (see Model switching). Off by default, because it interrupts everything else using the model.- Replies to
/v1/responseswithoutmax_output_tokensare capped at 8192 tokens; other endpoints use your values unchanged. --showprints setup for the OpenAI and Anthropic Python SDKs, curl, environment variables, Aider, OpenCode, Continue and Cursor (Cursor may not work with localhost).
Local agents as subagents
Any agent harness (cloud Claude Code, Codex, Cursor, OpenCode, ...) can hand a coding task to a local agent running on the local model (or on the computer you hearthwork connect to) and get the result back.
1. The task command, from the other agent's shell tool:
hearthwork task [--agent claude|codex|opencode|aider|qwen] [--allow "pytest *"]... [--cwd DIR] [--timeout 900] [--json] [--dry-run] "TASK"
echo "TASK" | hearthwork task -        # "-" reads the task from stdin: no shell quoting problems
It starts the model if none is running, runs the agent non-interactively, and prints a report on stdout: agent, model, host, duration, status, files created/modified/deleted, and the agent's final message. Progress goes to stderr. Exit code 0 is success, 124 a timeout (the agent and its children are killed), 1 an agent error.
| Agent | What it may do in a task |
|---|---|
| Claude Code, OpenCode, Qwen Code | Read, search and edit files, and run only commands matching an --allow pattern (--allow "python *"). Everything else is denied. |
| Codex | Runs in its workspace-write sandbox: edits inside the folder and runs commands there. --allow has no effect. |
| Aider | Only edits files; shell commands are switched off. |
2. The MCP server, so the other agent gets tools instead of a shell command:
hearthwork mcp install claude   # claude mcp add --scope user hearthwork -- <path to hearthwork> mcp
hearthwork mcp install codex    # codex mcp add hearthwork -- <path to hearthwork> mcp
hearthwork mcp install print    # JSON for Cursor, OpenCode, Claude Desktop
Tools: local_task_start (returns an id) and local_task_result (waits up to 55 s per call), local_task (blocking) and local_model_status. Prefer start + result: some clients, Codex among them, cancel an MCP tool call after about 60 s. For the blocking local_task in Codex, set tool_timeout_sec = 900 under [mcp_servers.hearthwork] in ~/.codex/config.toml.
Tips: give small, precise tasks (file names, interfaces, the test command) and review the result, as the local model is usually weaker than the agent calling it. Parallel tasks are limited by the model's slots; give them different files.
Resource budgets and presets
hearthwork budget shows, per resource, three separate things:
| Column | Meaning |
|---|---|
| Configured | The budget you or a preset set. |
| Estimated | The need of the running model: weights + KV cache for its context + about 1.5 GB runtime. |
| Measured | What is used now: llama-server's RAM from the OS, GPU memory from nvidia-smi when available, else "unavailable". |
hearthwork status ends with the same table.
| Preset | Command | Effect |
|---|---|---|
| dedicated | budget use dedicated |
Keeps 0.5 GB of VRAM free for other programs; gives the AI the most. |
| balanced (default) | budget use balanced |
The setup's own settings. |
| work | budget use work |
For gaming or work: keeps about 5 GB of VRAM free, 1 slot, half the CPU threads, unloads after 15 idle minutes. |
| custom | budget set vram=10GB ram=12GB slots=1 threads=8 idle=20m |
Your own numbers on top of the current preset. budget reset returns to balanced. |
- What is enforced. Slots (
-np), threads (-t) and idle unload are flags or host settings. The VRAM budget becomes llama.cpp's--fit-target(best effort). The OS cannot cap RAM, so Hearthwork estimates the need before every start or switch and compares it with the budget and the RAM free now (the model being replaced counts as free). The default budget only warns about RAM; presets and an explicitram=are binding. --over-budgetvs--force. An impossible start is refused with the numbers and options (smaller quantization, an explicit smaller context, another preset); the context is never shrunk silently.hearthwork start --over-budgetstarts anyway.--forceis separate: it interrupts running requests.- Changing the budget while a model runs restarts it through the host's switch path.
statusshowspending: ...when the saved settings differ from the running server;hearthwork startapplies them when nothing is running. On unified memory (Apple silicon) memory is counted once.
Setup profiles
A profile captures a setup that works, together with the proof: model identity (file, size, fingerprint of the first 16 MB, quantization, architecture, chat template), runtime and llama.cpp build, installed agent versions, effective server settings (context, KV type, slots, batch, fit target, any budget preset), a hardware summary, and the latest Doctor and benchmark results. Profiles live in profiles/ in the data folder.
hearthwork profile save [NAME] [--doctor]  # default name "default"; runs doctor --quick if no report from the last 24 h
hearthwork profile list | show NAME
hearthwork profile check [NAME] [--run]    # --run re-runs Doctor; a pass makes the profile verified again
hearthwork profile apply NAME              # model, context/slots/batch/KV and runtime build; Doctor validates afterwards
hearthwork profile apply previous          # the settings from before the last apply
hearthwork profile export NAME FILE        # no credentials, no device keys, paths replaced by placeholders
hearthwork profile import FILE             # stored as unverified; lists exactly what differs on this computer
| Status | When |
|---|---|
| verified | Doctor said "works" for every recorded agent. |
| needs recheck | The llama.cpp build, an agent version, the chat template or the model file changed. Run profile check --run. |
| unverified | Imported, or never checked. |
hearthwork status shows profile: NAME (verified|needs recheck|unverified). apply saves your current settings as the previous profile first and restores them automatically if validation fails. Agent versions are only reported, never changed.
Model switching and idle unload
- Switching.
hearthwork start --model Xwhile the host runs switches without stopping the host. New requests wait in the queue, running ones finish (up to 2 minutes), the prompt cache is saved, llama-server restarts with the new model (auto context), and the queue resumes. It refuses while requests are running unless you add--force, which cancels them after 10 seconds (their clients get a clear error). Only one switch runs at a time.hearthwork statusshowsswitching to X (draining N)andloading X. - Switching waits for open agent sessions. An agent session registers with the host the moment it starts (before its first request, so a just-started
hearthwork taskorhearthwork claudecounts). While any session is open,hearthwork start --model X(and a budget/profile change that restarts the model) refuses and lists them:claude session since 14:32:10 (pid 1234). Wait, or use--forceto drain, cancel the running requests and close those registrations;hearthwork statuslists the open sessions. Only local clients register: an agent using a model shared by another computer is gated on that computer. - Idle unload (off by default).
hearthwork idle 30unloads the model after 30 minutes without requests, to free VRAM and RAM. The host keeps running and the next request loads the model again; clients just wait (status saysloading).hearthwork idle offturns it off. The model is never unloaded while a request is running or waiting.
Recovery
The host watches llama-server. If it crashes or runs out of memory, the host restarts it, at most 3 times per 15 minutes (after 2, 10 and 30 seconds). A server that is only busy or slow to answer /health is never restarted.
- A request refused before the model accepted it is retried once after the restart. A stream that breaks midway ends with the API's error event (Anthropic
event: error, OpenAI error chunk); a second generation is never spliced on, and agent tasks are never rerun. - After three restarts the state is
failed: <reason>: requests get a clear 503 naming the reason and pointing tohearthwork logs --server.hearthwork startclears it. hearthwork status(andstatus --json) shows the last failure, exit code and the last 20 lines of the server log.
Diagnostics
| Command | Use it when |
|---|---|
hearthwork status |
You want the current state: host, model, context, slots, queue, route, profile, budget. |
hearthwork logs [--server] [-f] |
You want the host's log (requests, queue, start/stop, repairs) or llama-server's own output. |
hearthwork doctor |
An agent misbehaves and you want to know which layer is at fault. |
hearthwork diagnose |
Sessions were slow or failed and you want the measured reason. |
hearthwork doctor [--agent NAME | --all] [--quick] [--json] [--keep] prints the environment (Hearthwork and llama.cpp versions, model, quantization, architecture, trained and running context, chat template fingerprint), then runs these stages and gives one verdict per agent:
- Server: the model server answers and serves a model (on a remote host, also that the device is still trusted).
- Protocol, once per API the agents use, through the same relay: plain reply, streaming, a tool call, a tool result round trip, the next turn with tool history, and a late system message.
- Agent: installed, its configuration builds, and a headless reply in a disposable folder with its own temporary config (yours is never touched).
- Coding task (skipped by
--quick): the agent createscalc.pywithadd(a, b); Hearthwork imports it and checks the result itself.
Verdicts: works, configuration/connection problem at <stage>, protocol problem at <stage> (<API>), or protocol OK, but the model failed the coding task (model capability). Failed stages come with numbered suggestions. Aider never calls tools, so the tool stages do not count for it. The exit code is 0 when everything passes. Each run is saved as JSON (no credentials) in doctor/ in the data folder.
hearthwork diagnose reads the numbers the host records for every generation request, passively (streams are never buffered or delayed): client, API, outcome, queue wait, time to first byte, duration, prompt/cached/generated tokens, speeds, and the request's size against the context. They go to logs/requests.jsonl (rotated at about 5 MB). No prompt or response text is recorded, and nothing leaves your computer.
hearthwork diagnose                      # everything recorded
hearthwork diagnose --since 30m --client opencode
hearthwork diagnose --last 50 --json
hearthwork diagnose --export report.json # numbers only: no prompts, code, credentials, paths or device names
The report separates Observed findings (backed by the numbers, e.g. time spent waiting in the queue because several clients shared the slots) from Possible causes (explanations the numbers are consistent with, labelled as such), each with a suggestion. What the backend does not report is shown as "unavailable"; model load time, memory use and time in agent tools are not measured.
Opt-in raw capture for debugging: set HEARTHWORK_CAPTURE=1 before starting the host to also write full request and response bodies (your code and conversations) to logs/capture.jsonl. It is a local file, never exported, and off by default; delete it when done.
Where your data lives
Settings, llama.cpp, caches and results are stored per user, outside the install:
| OS | Folder |
|---|---|
| Windows | %LOCALAPPDATA%\hearthwork |
| macOS | ~/Library/Application Support/hearthwork |
| Linux | $XDG_DATA_HOME/hearthwork (default ~/.local/share/hearthwork) |
Set HEARTHWORK_HOME to use another folder. Inside it:
| Path | Contents |
|---|---|
config.json |
Your settings (including the server section and budget). |
bin/ |
llama.cpp builds. |
cache/slots/ |
Saved prompt caches. |
bench/ |
Benchmark results (results.jsonl) and each run's folder (runs/). |
doctor/ |
Doctor reports (JSON). |
profiles/ |
Setup profiles. |
logs/ |
requests.jsonl (numbers only) and the host log. |
templates/ |
Chat-template overrides. |
server.json, server.log |
The running model server, and its log. |
Benchmark
hearthwork bench (or the menu) drives the running model through a coding agent (--agent, Claude Code by default) in a fresh folder, with 8 prompts in one conversation. It grades each step by checking the files and running the code, not by trusting the agent's reply.
| # | Task | Graded by |
|---|---|---|
| 1 | chat | a reply came back |
| 2 | list files | both files named |
| 3 | read a file | the secret phrase is in the reply |
| 4 | write + run fizzbuzz.py |
running it gives the exact FizzBuzz output |
| 5 | add is_prime + run |
function and docstring exist, FizzBuzz still right, the primes below 30 are printed |
| 6 | fix 3 planted bugs | buggy.py prints 20.0, [9, 5], 0 |
| 7 | write unit tests | test_buggy.py passes (half points if it copies the functions instead of importing buggy.py) |
| 8 | summary | names all 3 files |
- Results are per machine. Speed and score depend on your hardware, model, quantization and context, so compare setups on your own computer. Results are added to
bench/results.jsonl, and the scoreboard (bench --show) ranks every model and agent you have tried, by score and then time. - Each run's folder stays in
bench/runs/<date-time>/<agent>/so you can inspect what the agent wrote. - Isolated history. Each run gives Codex and Claude Code an empty config folder (
CODEX_HOME,CLAUDE_CONFIG_DIR), so benchmark sessions never fill your real~/.codexor~/.claude; the run refuses to start if that folder would be your real one. No login is needed. - Release check:
hearthwork bench --allruns every installed agent one after another (never in parallel) and prints and saves a summary table (summary.mdin the run's folder;bench --showprints the latest). A warmup (~30K-token prompts through the Anthropic and OpenAI endpoints) runs first and is not timed;--warmupdoes the same before a single-agent run. If the agent itself fails (crash, does not start, reaches another provider) the run is repeated once in a fresh folder; a failed attempt has anerrorand no score. A wrong answer is a score, not a failure, and is not retried.
Roadmap
- Desktop app
- Mobile app
- MLX for Apple Silicon
- Documentation website
Publishing (maintainers)
Releases go to PyPI from GitHub Actions via Trusted Publishing (.github/workflows/publish.yml).
One-time setup:
- On PyPI: project
hearthwork> Settings > Publishing > add a GitHub trusted publisher: ownerBillyMRX1, repohearthwork, workflowpublish.yml, environmentpypi. - On GitHub: Settings > Environments > New environment
pypi, with Required reviewers set to the maintainer.
Each release:
- Bump
__version__insrc/hearthwork/__init__.py, commit, and push a tag matching it, e.g.git tag v0.9.1 && git push origin v0.9.1. The workflow fails if the tag and version differ. - Approve the
pypideployment on the workflow run in GitHub Actions.
Manual publishing with uv publish still works.
License
1 maintainer

Metadata
1 maintainer
Release files for hearthwork 0.10.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| hearthwork-0.10.0.tar.gz | 269.8 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hearthwork-0.10.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 467.3 kB
Release files / hearthwork-0.10.0.tar.gz
| Download URL | hearthwork-0.10.0.tar.gz |
|---|---|
| Size | 269.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
de6e94606f404c8f898ae9717dfd3b3eeba6bdd981ffe8fe2e3c0c115cb38ab8
|
|
BLAKE2b-256 checksum How to use checksums |
abb7f25db9cd1ead06884bf71b6a60a3699f9113619e00ef8e646d66d08dab37
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / hearthwork-0.10.0-py3-none-any.whl
| Download URL | hearthwork-0.10.0-py3-none-any.whl |
|---|---|
| Size | 197.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fafccbcb5cc5541feaac66c8a993a795e2ed0993700b4d86aea4a089fd57b16a
|
|
BLAKE2b-256 checksum How to use checksums |
46acd6bb6e1cfd1a61f9cc42deec84c723f454ded37eb891e180df0c1fb3f43b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for hearthwork 0.10.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for hearthwork-0.10.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














