
inferlint
inferlint measures what your inference server actually did—and flags what it didn't tell you.
Measure achieved concurrency, preemptions, KV-cache behavior, GPU state, timing quality, and other signals that can silently invalidate inference results.
Serving benchmarks fail quietly. vLLM preempts requests and logs nothing. A config boots cleanly and dies on its first request. The KV pool you measured yesterday is not the one you got today. A cleanup script stops the API server and leaves the engine holding the GPU. None of these raise an error, and all of them change the numbers.
You run inferlint around a benchmark test. It reads the server's start-up log and
counters, measures what happened, and flags each of these problems when it occurs. It
does not start the server or send the load, so it works with the tools you already use.
One run, measured
vLLM 0.28 on an RTX 4090, a 27B hybrid attention/Mamba model with 4-bit weights and CUDA graphs on. 32 concurrent requests, 1,000 output tokens each:
$ inferlint preemption before.json after.json
[ T1] FAIL  22 preemptions during the run
$ grep -ci preempt boot.log
0
$ inferlint series run.series.jsonl --snapshot after.json --requested 32
[T14] PASS  gauge denominator is 42 = num_gpu_blocks (43) - 1 null block
[ T9] WARN  ceiling moved between 7 and 10 as requests grew (one request held 9.5% to 14.3% of the cache); concurrency was not a constant of this run
[ T8] FAIL  requested 32 concurrent, server never ran more than 10
- The client held 32 requests in flight. The server never ran more than 10 at once.
- A fresh request held 4 KV blocks, so 10 fit. As outputs crossed the 784-token block boundary, running requests held up to 6 blocks each on average, and the number that fit fell as low as 7. Each fall evicted running requests, 22 times in all, and the server log says nothing about it.
- The server exports 43 KV blocks, but the usage gauge counts in 42nds. One block is reserved and never holds a request.
Then the API server was killed with SIGKILL, as a crash or the OOM killer would:
$ pkill -9 -f "vllm[ ]serve"; sleep 20
$ ps -eo pid,ppid,rss,args | grep -E "[V]LLM::|[v]llm serve"
   1030     423 2733144 VLLM::EngineCore
$ inferlint gpu-inspect          # the GPU's model and memory lines are left out here
[ T2] FAIL  card not clear; refusing to boot. ... 21768 MiB used, 1 server processes alive
$ inferlint teardown
target  pid=1030     VLLM::EngineCore
(pkill -f 'vllm serve' would miss 1 and wrongly hit 0)
[ T2] PASS  2 consecutive clear readings
The engine outlived its parent and kept 21.3 GiB of the card. The usual cleanup pattern
cannot see it, and the next boot would have loaded a second copy into what was left.
The raw files from this run are in
tests/fixtures/vllm-0.28/live/,
and tests/test_live.py pins every number above.
What it checks
| id | trap | command |
|---|---|---|
| T1 | preemption is silent: a counter moves, no log line is written | inferlint preemption BEFORE AFTER |
| T2 | pkill -f "vllm serve" misses the renamed VLLM::EngineCore |
inferlint teardown, inferlint gpu-inspect |
| T3 | pkill -f in a shell one-liner kills the shell |
inferlint teardown |
| T4 | the KV pool is drawn per boot, in discrete levels | inferlint check-log BOOT... |
| T5 | hybrid models force a large attention block (the allocation unit) | inferlint check-log |
| T6 | the requested attention backend is not applied to the speculative drafter | inferlint check-log |
| T7 | a config boots, then dies on its first request | inferlint probe URL |
| T8 | requested concurrency is not achieved concurrency | inferlint series --requested N |
| T9 | the concurrency ceiling is floor(1 / share), and it falls as requests grow |
inferlint series |
| T10 | integer-second timers are worth several percent | inferlint rate BEFORE AFTER |
| T11 | KV memory differs between boots of one config | inferlint check-log BOOT... |
| T12 | boot failures recorded without a reason | inferlint check-log |
| T13 | a killed campaign's waiter adopts the next server | docs/orchestration.md |
| T14 | the KV usage gauge's denominator is num_gpu_blocks - 1 |
inferlint series --snapshot |
Each is described in docs/tripwires.md with its symptom, why it changes results, and a command that reproduces it from files in this repository.
Install
pipx install inferlint
inferlint --help
pipx gives inferlint an environment of its own and puts the
command on your PATH, so it works in any terminal and from any folder, with nothing to
activate. uv tool install inferlint does the same. To use it as a library, install it
into your project's environment with pip install inferlint (see
Use it from Python).
Python 3.10+, no dependencies. teardown, and the free-GPU check in gpu-inspect, find
the server's processes through /proc, so they need Linux (or WSL), where vLLM runs.
Everything else runs anywhere.
Use
A test with inferlint takes as long as your benchmark. It checks one test at a time; it is not a monitor for a server that runs for days (Prometheus and Grafana do that job).
Use two terminals on the GPU machine, in the same folder: A runs the server, B runs everything else.
# 1. Before the server starts (B)
inferlint gpu-inspect                  # which GPU, its memory; fails if an old server still holds it

# 2. Start the server (A): your usual command, saving its start-up output
vllm serve MODEL 2>&1 | tee boot.log   # wait for "Application startup complete"

#    then check it (B)
inferlint check-log boot.log           # block size, attention backend, start-up failures
inferlint probe http://127.0.0.1:8000  # sends 9 small requests: does it answer?

# 3. The test (B)
inferlint snapshot http://127.0.0.1:8000 -o before.json
inferlint watch http://127.0.0.1:8000 -o run.series.jsonl --interval 0.25 &
vllm bench serve --model MODEL --max-concurrency 32 ...   # your benchmark sends the load
inferlint snapshot http://127.0.0.1:8000 -o after.json
kill %1                                # stops the recording

# 4. The verdict: one HTML page (any time later, on any computer)
inferlint report -o run.html --requested 32 --boot-log boot.log \
    --before before.json --after after.json --series run.series.jsonl

# 5. Stop the server (B)
inferlint teardown                     # stops every vLLM process, waits until the GPU is free
- Your benchmark sends the requests and reports speed and latency. inferlint reads the server's side and says which of those numbers hold.
--requestedis the concurrency your benchmark asked for (--max-concurrencyinvllm bench serve). Requests, tokens and preemptions come from the server's counters.- Each command does one job and exits, except
watch. They only read, exceptprobe(9 small requests) andteardown, which stops the server: don't run it against a server that is serving users. - The same verdicts in the terminal:
inferlint preemption before.json after.json(T1),inferlint rate before.json after.json(T10),inferlint series run.series.jsonl --snapshot after.json --requested 32(T8, T9, T14). - T4 and T11 compare start-ups: keep the log of each start with the same settings and
pass them all (
--boot-log boot1.log --boot-log boot2.log). - In scripts,
inferlint gpu-inspect || exit 1andinferlint probe http://127.0.0.1:8000 || exit 1stop a run before it produces bad numbers. docs/orchestration.md covers scripts that run many tests.
Exit status is 0 when every check passes (warnings allowed), 1 when one fails, and 2
when one cannot decide because a series or a log line was missing. A missing series
is never read as zero. --json gives machine-readable results; --strict fails on
warnings.
The report
inferlint report turns a run's files into one HTML page. It opens with a plain-English
account of what happened (how long the test ran, requests finished and failed, tokens
generated, time spent queued, which tripwires were checked and which need other
files), then the verdicts, charts of what the server did over time, the boot facts, and
a guide to every tripwire. Two collapsible glossaries explain the terms (token, KV
pool, block, preemption) and what Pass, Warning, Fail and Can't tell mean: a Fail is a
finding about the measurement, not a crash, except for T7 and T12.
The page fetches nothing, so it opens offline and can be attached to a ticket as it is. It has a light/dark switch, every chart has a data table, and hovering (or the arrow keys) reads values at any moment.
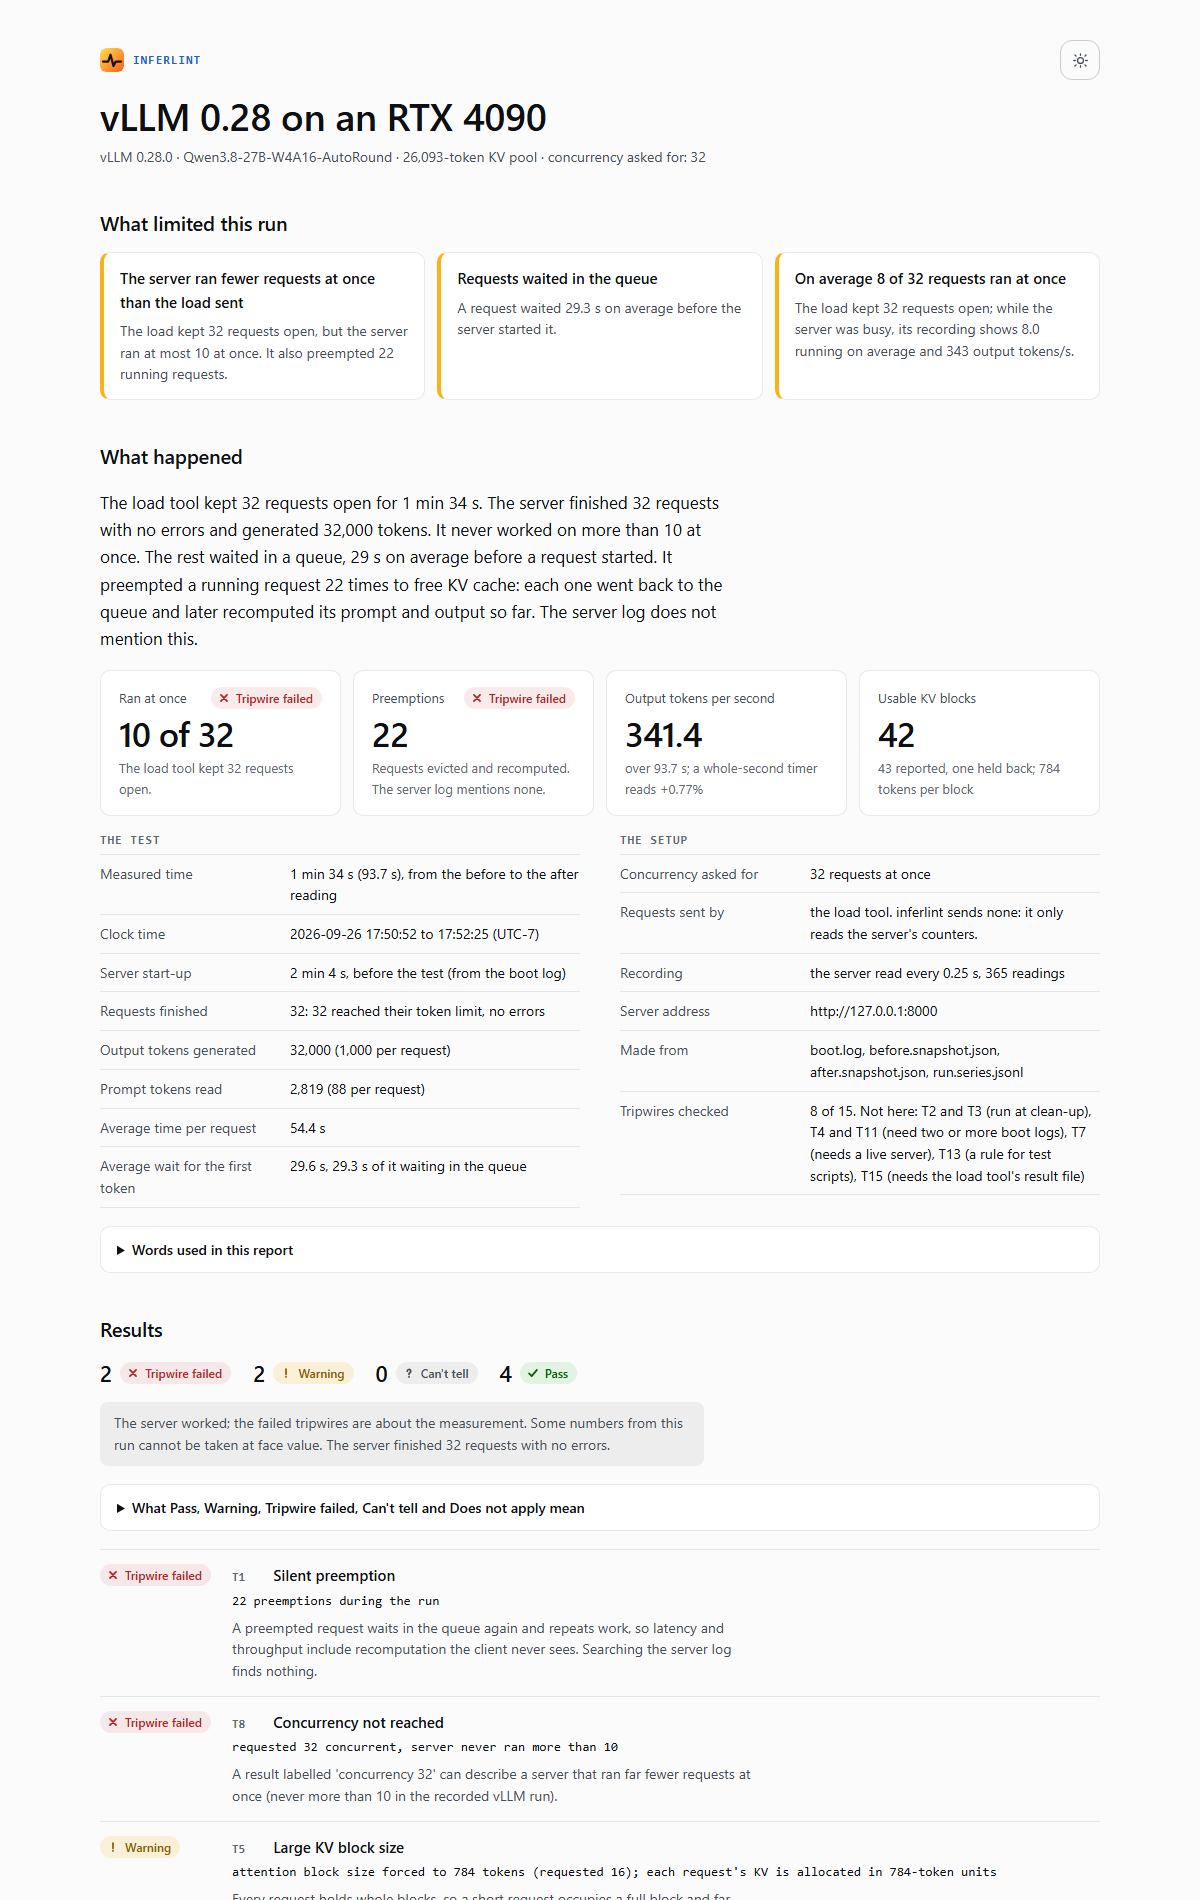
See a full example.
docs/example-report.html
is the complete report for the run above: the charts, the findings and both glossaries.
GitHub shows HTML files as source code, so open the file, choose Download raw file,
and open it in any browser. It works offline.
Try it without a GPU. The example is built from the recorded run in this repository. Download the repository for its files, and make the report yourself:
git clone https://github.com/radianvector/inferlint
cd inferlint
inferlint report -o example-report.html --title "vLLM 0.28 on an RTX 4090" --requested 32 \
    --boot-log tests/fixtures/vllm-0.28/live/boot.log \
    --before tests/fixtures/vllm-0.28/live/before.snapshot.json \
    --after tests/fixtures/vllm-0.28/live/after.snapshot.json \
    --series tests/fixtures/vllm-0.28/live/run.series.jsonl
inferlint explain T9 prints the same plain-English explanation in the terminal.
Use it from Python
Install it into your project's environment with pip install inferlint. Every check
returns a CheckResult with a status (pass, warn, fail or unknown), a message, and
the evidence behind it.
import subprocess

from inferlint import bootlog, checks, telemetry

url = "http://127.0.0.1:8000"
before = telemetry.scrape(url)
subprocess.run(["vllm", "bench", "serve", "--model", "MODEL"], check=True)  # your benchmark
after = telemetry.scrape(url)

result = checks.check_no_preemption(before, after)
print(result.status.value, result.message)  # fail 22 preemptions during the run
result.raise_for_status()  # raises TripwireFailed on a Fail or a Can't tell

facts = bootlog.parse_file("boot.log")
print(facts.attention_block_size, facts.kv_pool_tokens)  # 784 26093
record = {"boot": facts.result_block()}  # pool, block size, backend: keep with your results
raise_for_status() lets warnings through; raise_for_status(allow_warn=False) stops on
them too.
| module | what it gives you |
|---|---|
bootlog |
the facts in a start-up log (parse_file) |
telemetry |
the server's counters (scrape, load) |
series |
recordings made during a run (watch, read) |
checks |
the checks, each returning a CheckResult |
probe |
the first-request check (T7) |
gpu |
which GPU, its family and memory (read_gpus) |
teardown |
stopping the server and waiting for a free GPU (Linux) |
report |
the HTML report (build, render) |
How it is tested
- Real evidence. Fixtures are vLLM 0.28 boot logs and
/metricsoutput from an RTX 4090, with paths removed. Each check is tested against the case it exists for. - Every check is watched failing.
tests/test_mutations.pychanges one number or line in real evidence and requires the verdict to flip. - Instruments against ground truth. The probe runs against a mock server with known
failure modes. Block-count inference (T14) is checked against the count the server
exports. The teardown's process matching runs on a synthetic
/procthat includes the shell one-liner and a bystander. GPU facts are parsed from realnvidia-smioutput. - Unknown formats are reported, not defaulted. When a known log line changes format
in a new vLLM release,
boot-factslists it as unparsed instead of returning a value.
Develop
To change the code, work from a clone in a virtual environment of its own, with the package installed in editable mode (edits take effect without reinstalling) and the test tools added:
git clone https://github.com/radianvector/inferlint
cd inferlint
python -m venv .venv
source .venv/bin/activate          # Windows PowerShell: .venv\Scripts\Activate.ps1
pip install -e ".[dev]"
pytest -q                          # no GPU needed
ruff check src tests && ruff format --check src tests && pyright
The last two lines are what CI runs on Python 3.10, 3.11 and 3.12.
Status
Alpha. Every tripwire is tested against recorded vLLM 0.28 evidence. T1, T2, T5, T8, T9,
T10 and T14 have also been re-measured by this code on a live vLLM 0.28 server. Next: one
command that runs the whole sequence above, re-verification on the current vLLM release,
and support for the llama.cpp /metrics subset.
About
inferlint is made by RadianVector. RadianVector develops
tools and research for evaluating and improving AI systems.
License
Copyright 2026 RadianVector.
This project, including the recorded evidence in tests/fixtures/, is licensed under the
Apache License, Version 2.0. See LICENSE
for details.
1 maintainer

Metadata
1 maintainer
Release files for inferlint 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| inferlint-0.1.1.tar.gz | 542.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| inferlint-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 612.4 kB
Release files / inferlint-0.1.1.tar.gz
| Download URL | inferlint-0.1.1.tar.gz |
|---|---|
| Size | 542.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
19f2f084301c5ad97739b03be93d5d5a51805b0e1e3c7ac0fca07acf03997503
|
|
BLAKE2b-256 checksum How to use checksums |
76180f467b56c61faac46163ca4c4113823ec2db73ef2af581eb99e457769fc5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.6
|
Release files / inferlint-0.1.1-py3-none-any.whl
| Download URL | inferlint-0.1.1-py3-none-any.whl |
|---|---|
| Size | 70.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fdb1d5dac2bd04eb1940256fde930a56aa4c276b15dafe15f12e46a7a8abdcc0
|
|
BLAKE2b-256 checksum How to use checksums |
5d50b2136a30c0f634aaea4f191db3261a5ed3bfb9c9229ff7953efa74e9a0f9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.6
|














