
Jupyter Storage Explorer
Explore your data lake without leaving Jupyter: built for data professionals

StorageExplorer is a file explorer for cloud storage and data lakes, right inside your Jupyter notebook, in the
spirit of Azure Storage Explorer.
Browse Amazon S3, Azure Data Lake / Blob Storage, Google Cloud Storage, local disks and more; preview Parquet files, Delta Lake tables, CSV, Excel, JSON and other formats; page through, sort and filter tables; get ready-to-run code that loads the data into your notebook; and upload, download, move and edit files without leaving JupyterLab. See Using the explorer for all you can do with it.
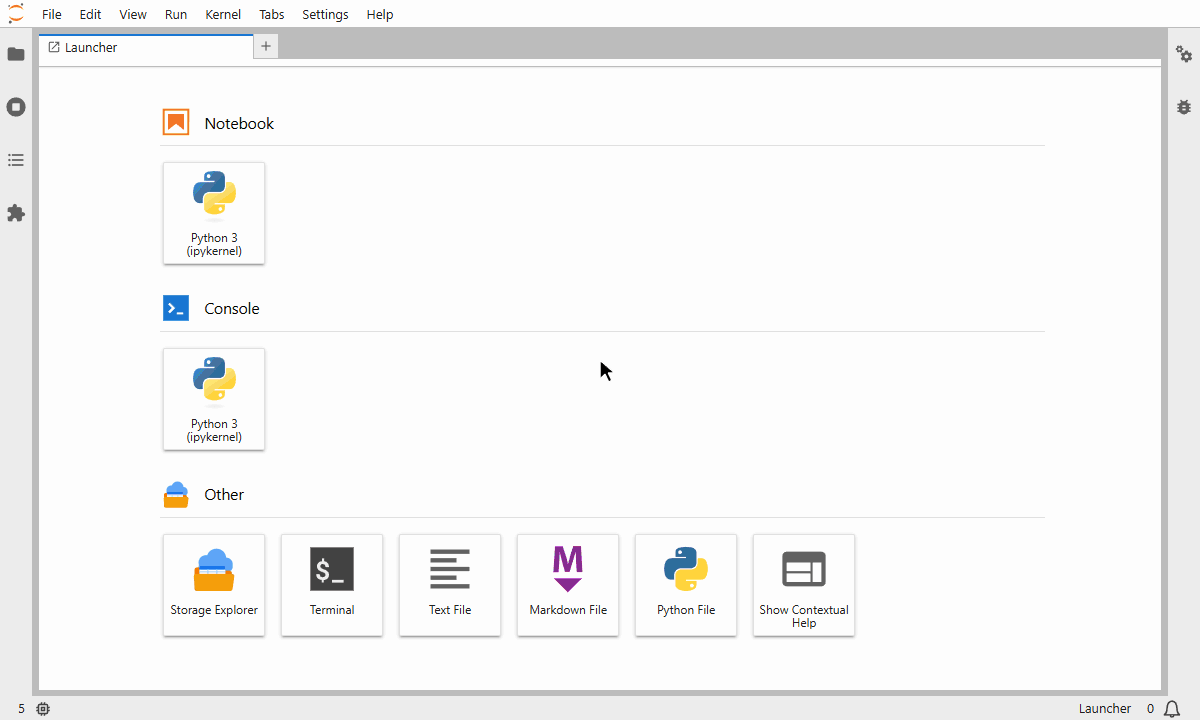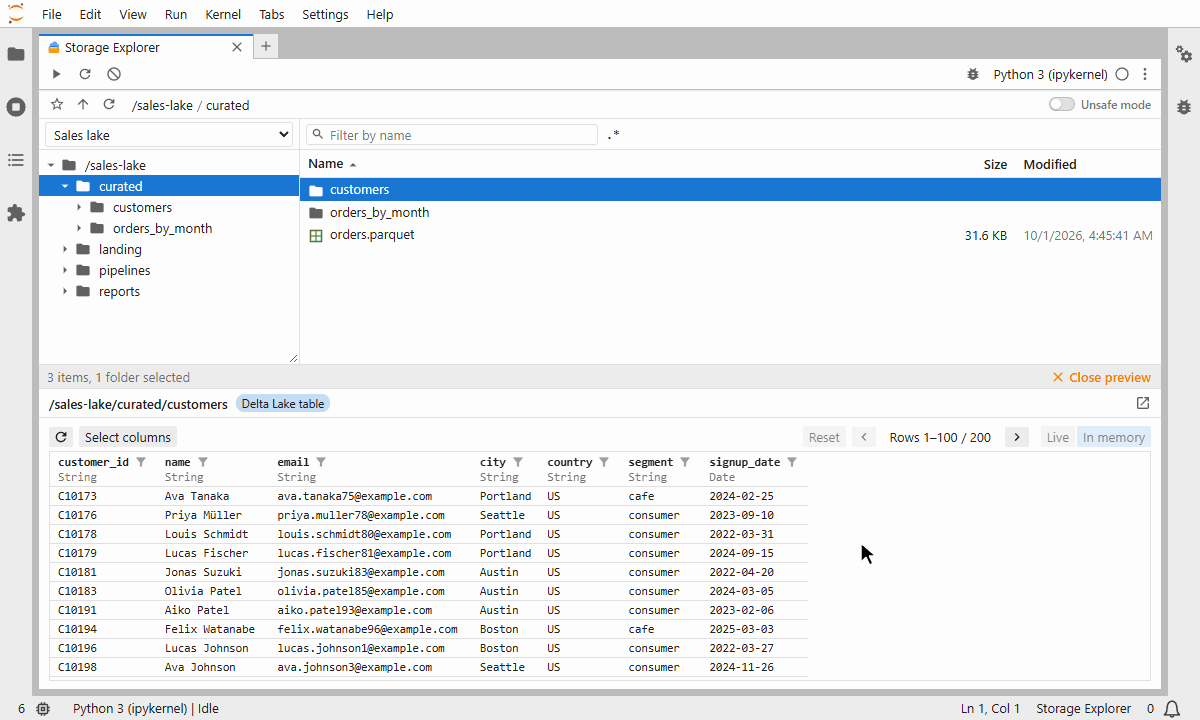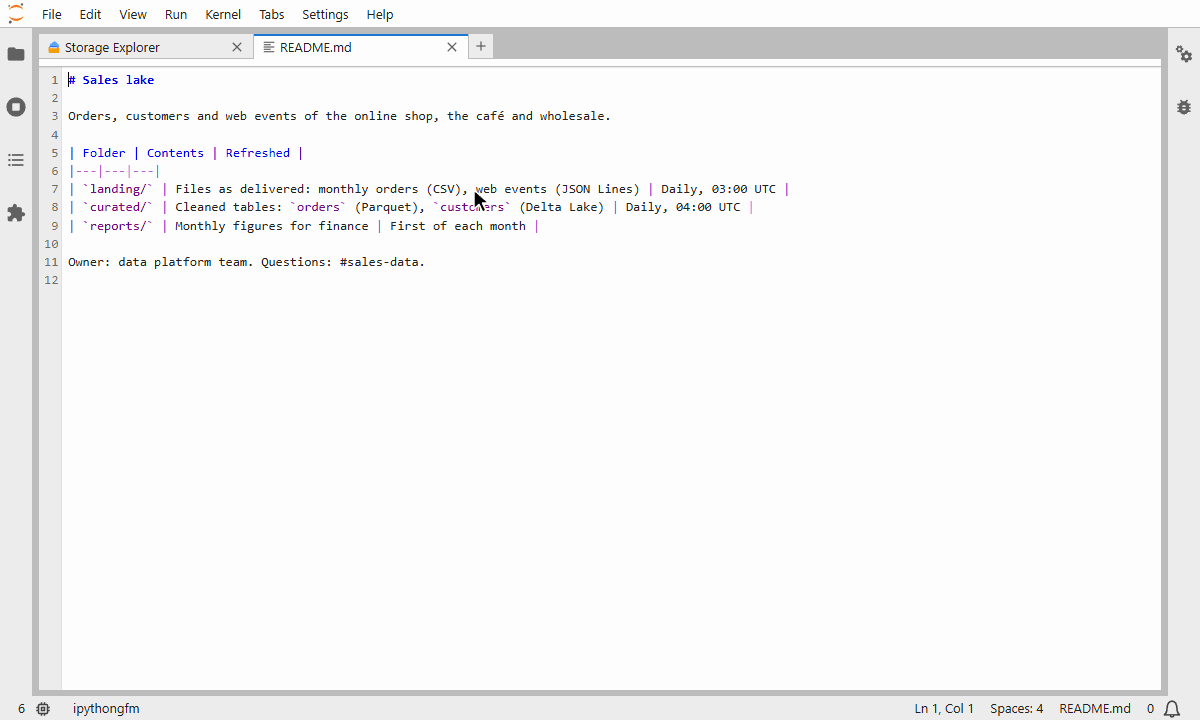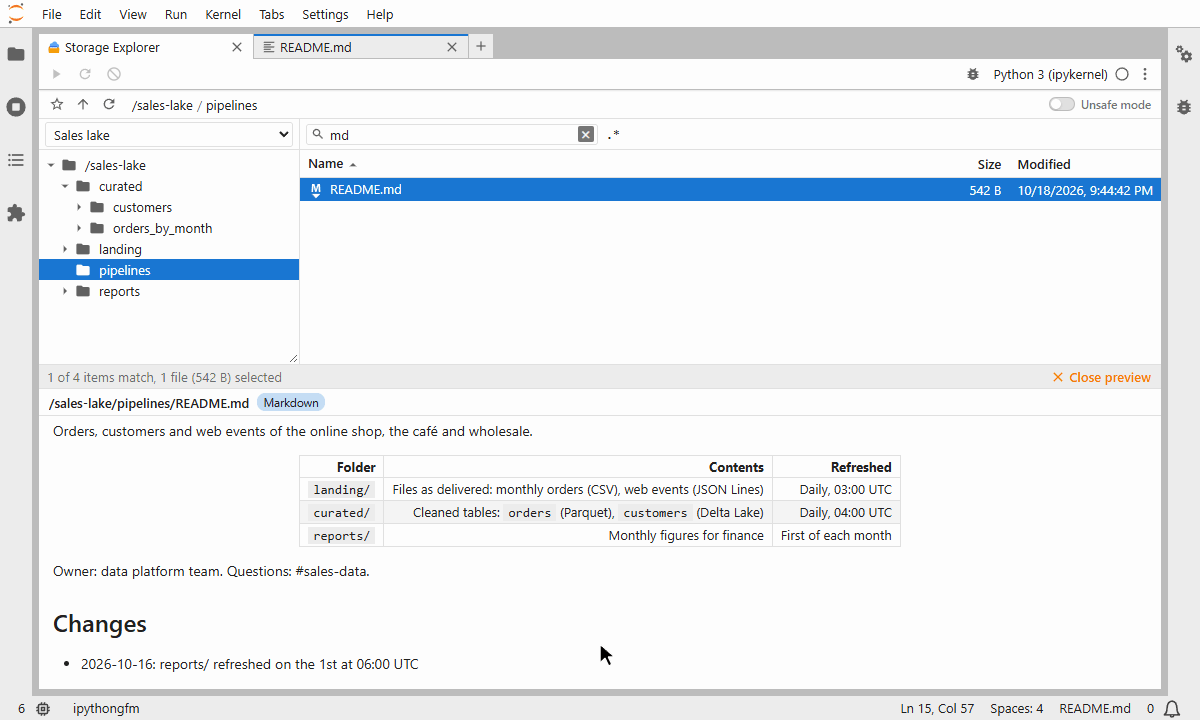
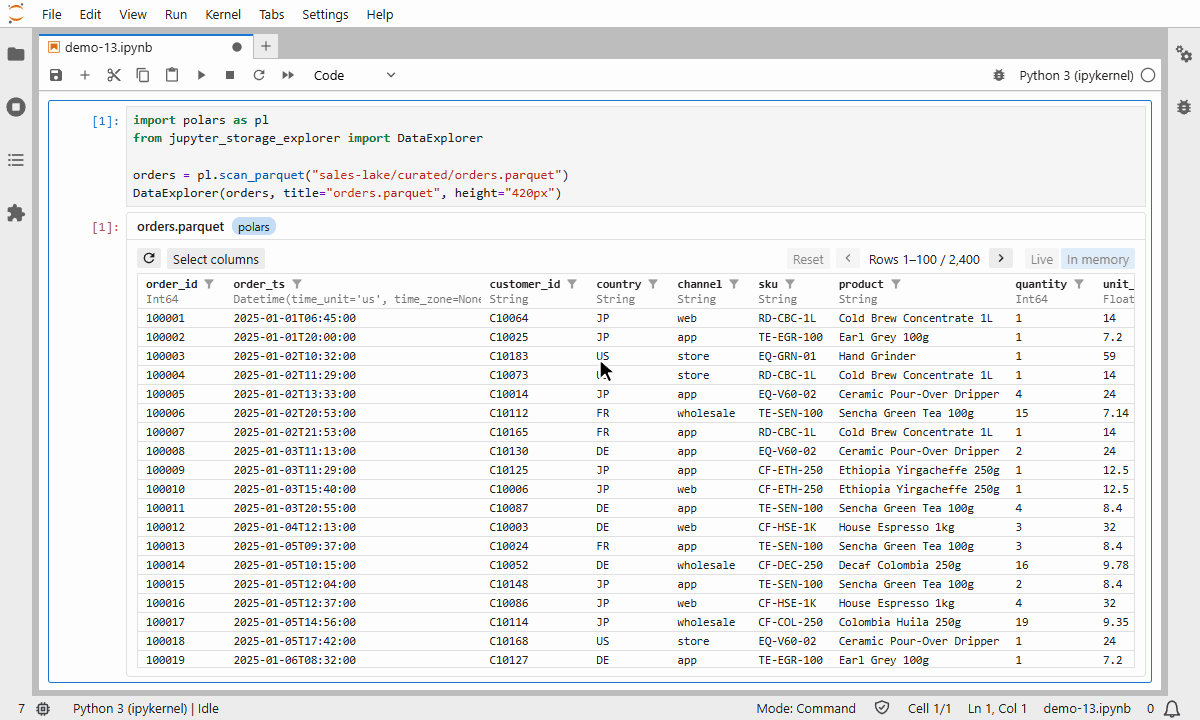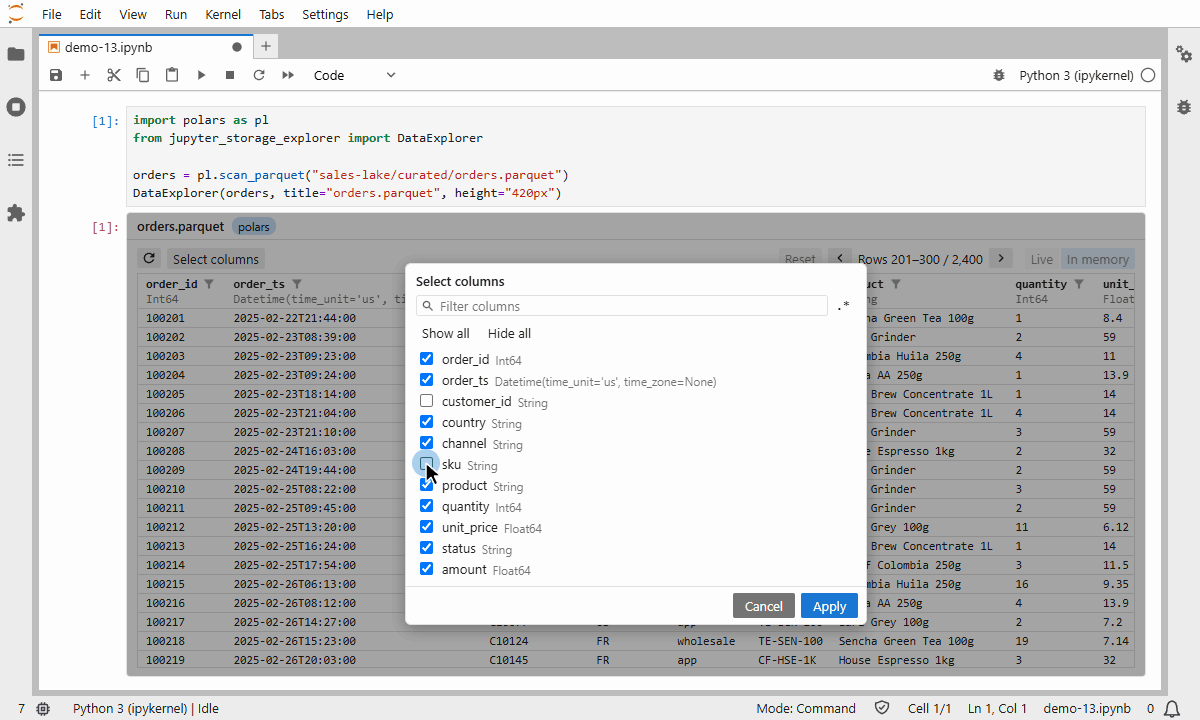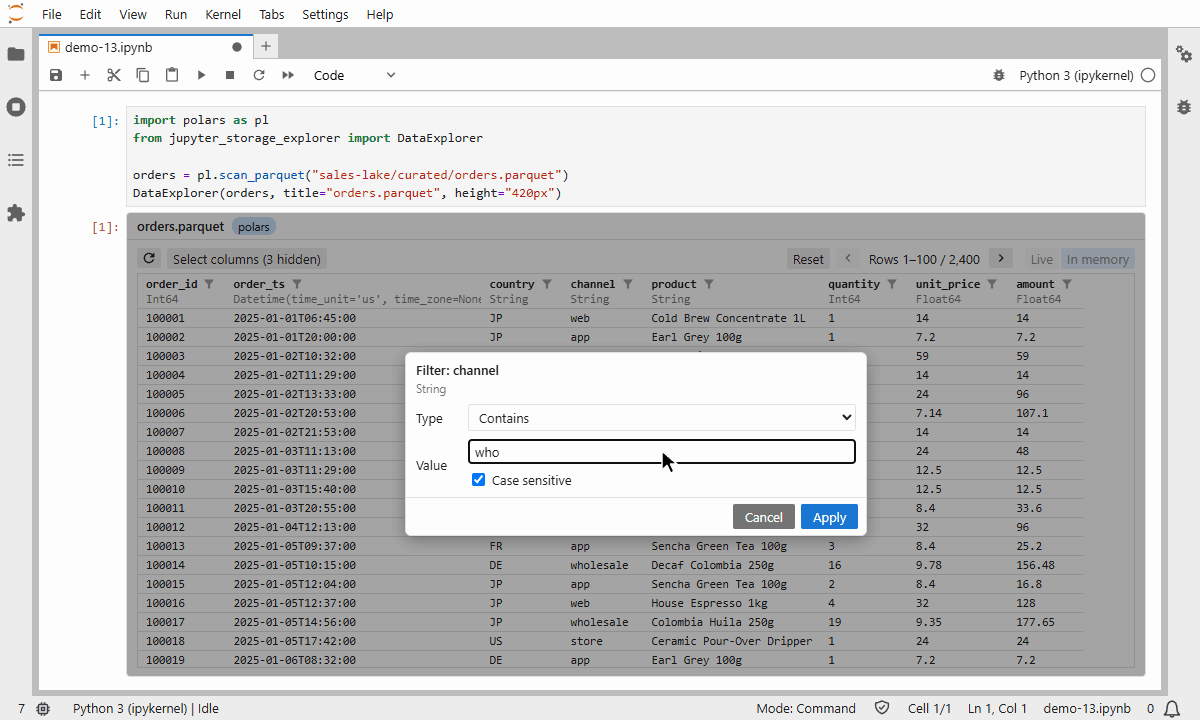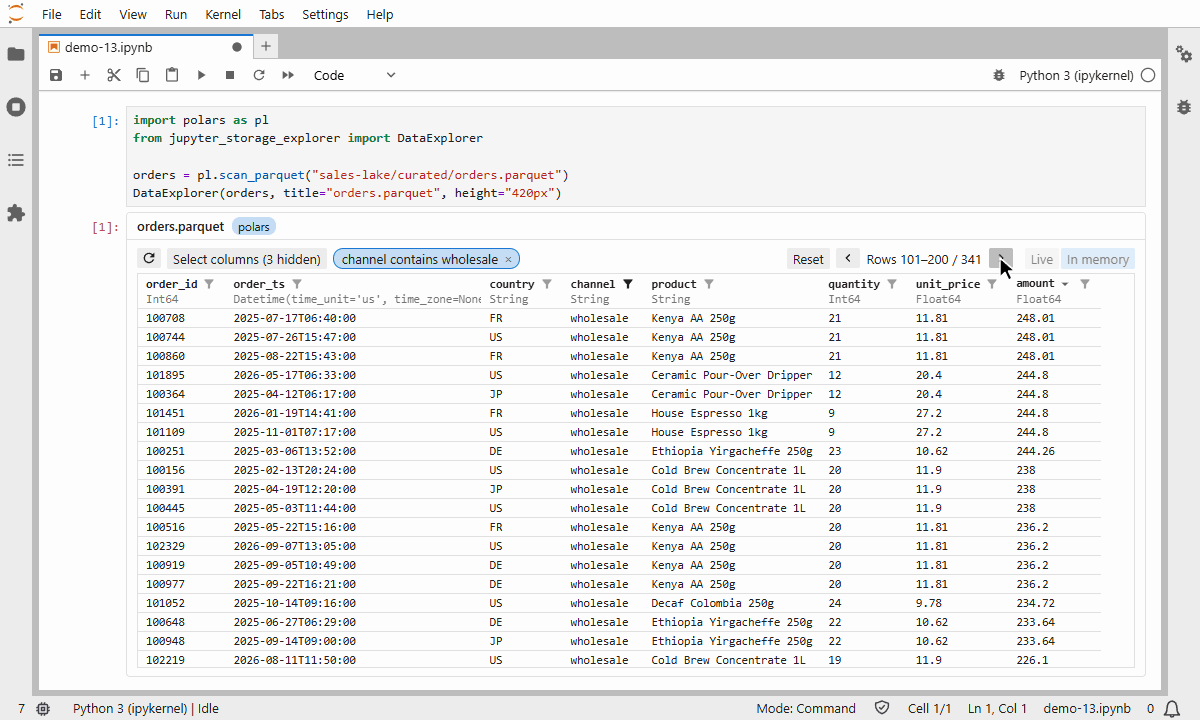
This package also provides the DataExplorer widget, which lets you browse tabular data in your notebook: any
dataframe of pandas, polars, Spark, DuckDB and more. Page through, sort and filter it in the widget, then get the
result back in code.
See Using the data browser
for all you can do with it.
Highlights
StorageExplorer: any fsspec storage, several in one explorer; copy and paste between storages and notebooks.DataExplorer: page, sort and filter any dataframe; get the result back in code.- Previews of Delta Lake, Parquet, CSV, JSON, Excel, text and images, with code to load them.
- Your engine: query data with Polars, pandas or PySpark (also Databricks Connect), chosen from the status bar.
- Plugins for engines and storages: install one, and every explorer uses it; they never change the data libraries of a shared environment.
- Background file operations with progress and Cancel; folder operations only in Unsafe mode.
- Work in JupyterLab: open storage files in JupyterLab's own editors and viewers, and save them back; view tables and files in tabs of their own.
- Bookmarks, remembered queries, transfer rules, a JupyterLab launcher item and a side panel.
Quick start
Try it without installing anything: open the demo on Binder, a made-up data lake in a notebook and in the launcher's tab (it may take a minute to start).
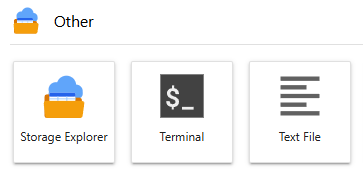
From the JupyterLab launcher
jupyter-storage-explorer-launcher
adds Storage Explorer to JupyterLab's launcher, opening the explorer in its own tab, and to the left side bar:
pip install "jupyter-storage-explorer-launcher[polars]"
From Python code
pip install "jupyter-storage-explorer[polars]"
[polars] adds the Polars plugin with Polars itself; other engines and storages are extras too, e.g.
[polars-support] for the plugin alone, using the libraries you have (recommended in carefully set up kernels). See
Installation
for all of them and the storage packages.
from jupyter_storage_explorer import StorageExplorer

StorageExplorer("s3://my-bucket/data")
Options after the address go to the storage package, e.g. profile="analytics". Double-click a file to preview it;
right-click for everything else.
Browse a dataframe and get the rows you filtered back:
import polars as pl
from jupyter_storage_explorer import DataExplorer

explorer = DataExplorer(pl.scan_parquet("s3://my-bucket/lake/sales/*.parquet"))
explorer
explorer.result().collect() # after filtering and sorting in the widget
The notebooks folder has a demo of each widget on sample data.
Documentation
- StorageExplorer: storages, using the explorer, transfer policy, formats, working with it from Python and options.
- DataExplorer: the data
browser,
result(),on_change(),QuerySettingsand options. - The launcher: configuring
its tab with
launcher.pyfiles. - Development: building, releasing, and custom icons.
- Developing plugins: formats, engines, file operations and storages of your own, packaged as plugins.
Requirements
- Python 3.11 or later
- JupyterLab 4.0 or later (other Jupyter frontends show the widgets, without drag and drop from JupyterLab's file browser)
- For querying data: an engine plugin, e.g.
jupyter-storage-explorer[polars](Polars, tested with 2.0)
Why Storage Explorer?
Storage Explorer aims to be a data-aware file explorer for large data lakes, made for the daily work of data scientists and engineers. Rather than adding data lake access to JupyterLab's file browser, a narrow sidebar, it is a widget in JupyterLab's main area, in a notebook or a tab of its own, with room for what working with data needs (the launcher also has a narrow side panel, for picking files beside your notebooks):
- Built for large folders: data lakes often hold thousands of items in one folder (partitions, part files, daily drops). The list is paged, sorted and filtered as you type, regular expressions included; folders of tens of thousands of items are listed by the kernel, a page at a time. Moving, copying, deleting and uploading run in the background, with their progress and Cancel, so the explorer stays usable while thousands of files move.
- Preview as you browse: tree, list and preview side by side. Click through files and see each one at once, without opening and closing tabs.
- Tables, not just files: Delta Lake tables and partitioned Parquet datasets are recognised as tables, not folders. Open them in the data browser to choose among hundreds of columns and filter and sort the data where it lives, with the engine you choose (Polars, pandas, or one of your own).
- From browsing to code: copy ready-to-run code to load a file or table with polars, pandas, PySpark and more, or
the URLs of the files you selected, ready for any library. In Python,
folder_locationandselected_locationsgive the folder shown and the files selected, with their URLs. - Part of your notebook: explorers are widgets, placed in your notebook next to your analysis. Your code can
follow what you browse (
on_change(),on_query_change()): a chart of the file you click, redrawn as you filter it in the data browser (query_result()).DataExplorerbrings the same data browser to any dataframe, and gives the rows you filtered back to your code (result()). See Working with the explorer from Python. - At home in JupyterLab: drag files from JupyterLab's file browser into an explorer to upload them to a storage, or onto the file browser to download them to the server. Split the main area to put explorers side by side, in notebooks or tabs of their own, and drag files from one storage to another, e.g. from S3 to Azure. Files open in JupyterLab's own editors, and tables in a tab of their own.
- Safe by default: in a data lake, a folder is often a whole table. Folders can't be moved, copied, renamed or deleted by a stray drag: that takes Unsafe mode, which turns itself off after one operation. Teams can also restrict where files may go with a transfer policy.
- Runs in your kernel: with your credentials and your libraries, and no server setup.
It complements JupyterLab's file browser rather than replacing it.
1 maintainer

Metadata
1 maintainer
Release files for jupyter-storage-explorer 0.16.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| jupyter_storage_explorer-0.16.0.tar.gz | 2.1 MB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| jupyter_storage_explorer-0.16.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.4 MB
Release files / jupyter_storage_explorer-0.16.0.tar.gz
| Download URL | jupyter_storage_explorer-0.16.0.tar.gz |
|---|---|
| Size | 2.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
67042104019466376dfbe84b48aa14ae2dfa49201a5f7b4dfbc4489af98ea849
|
|
BLAKE2b-256 checksum How to use checksums |
4a0332b20fc4929db6bc119851e99fbdc7ed4da1b2bae8540bda0f3e4d8f44fd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 21, 2026.
Transparency logRelease files / jupyter_storage_explorer-0.16.0-py3-none-any.whl
| Download URL | jupyter_storage_explorer-0.16.0-py3-none-any.whl |
|---|---|
| Size | 289.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c7af978cbdf14a8f6a099738bcd465beac29826f72a52cdf4f846313f02294da
|
|
BLAKE2b-256 checksum How to use checksums |
af79f8a921768c6e45895666865c96517d3a1564ead0258bc5a7bf7ac6be7208
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 21, 2026.
Transparency logSecurity for jupyter-storage-explorer 0.16.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for jupyter_storage_explorer-0.16.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 21, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














