
ko-hand-ocr
Reads one line of handwritten Korean + English. A 36M model trained from scratch on synthetic data — no handwriting dataset, no inherited terms.


한국어 · English
photo -> line cutting -> ko-hand-ocr -> "부서 : 포테토뭉부서"
At a glance
| What it reads | One line of handwritten Korean + English, from a photo |
| Model | ViT-Small encoder (ImageNet, Apache-2.0) + 6-layer TrOCR decoder trained from scratch |
| Vocabulary | 229 jamo tokens — not 11,172 syllables, so unseen characters are still writable |
| Parameters | 36M — one sixth of ko-trocr (213.7M) |
| Weights | 138 MB single · 414 MB three-way ensemble (downloaded separately) |
| Package | 83 KB — the code only |
| Speed | 0.20 s per line · 1.35 s for a whole photo — CPU only, no GPU |
| Memory | 905 MB single · 1.18 GB ensemble |
| Accuracy | 94.6% mean on six handwriting fonts never seen in training (95.3% ensemble) · worst font 88.5% (90.3% ensemble) |
| Training data | Synthetic — drawn on the fly from OFL fonts. Nothing is stored on disk |
| License | Apache-2.0, weights included — no dataset terms inherited |
| Python | 3.10+ · PyTorch 2.5+ |
What it does — and does not
Does
- Reads a whole photo: finds the lines, cuts them, reads each one (
read_photo) - Reads pre-cut line images, batched (
read) - Constrained decoding — restrict the output to a candidate list, and report whether the free and constrained readings agree (
both) - Ensemble reading — run several checkpoints and take the answer they agree on
- Runs fully offline on CPU. Nothing is sent anywhere
Does not
- Split a table cell into label and value —
read_photoonly cuts down to lines - Handle vertical writing or merged cells
- Stay silent on an empty cell — a cell that is pure scribble still produces something
Why it exists
In practice the only publicly available Korean handwriting OCR model is
ddobokki/ko-trocr, and its training data comes from AI Hub, which places conditions
on purpose of use and on redistribution. That blocks it from being embedded in an
in-house tool or shipped as a public package. So the same capability was rebuilt
from scratch — with a provenance chain that can be audited part by part.

Install
pip install ko-hand-ocr
Weights ship separately — they are too large for the repository, so they are attached to Releases.
Weights are versioned separately from the package. The current weights are on the v0.3.0 release; a package bump does not mean the weights changed. The 4-layer weights from v0.2.0 are still there — they are faster (0.16 s per line).
| Download | Size | What it is |
|---|---|---|
ko-hand-ocr-v62.zip |
128MB | A single checkpoint. Enough for most uses. 0.20 s/line |
ko-hand-ocr-ensemble.zip |
383MB | Three checkpoints. Raises the floor, 8x slower |
curl -LO https://github.com/jysvai/ko-hand-ocr/releases/download/v0.3.0/ko-hand-ocr-v62.zip
Pass the unzipped folder straight to Reader(). It must contain config.json,
vocab.json and model.safetensors.
Quick start
from kohandocr.reader import Reader

reader = Reader("ko-hand-ocr-v62", device="cpu")   # the unzipped folder

# A whole photo. Line cutting is included.
reader.read_photo(open("scan.jpg", "rb").read())
# -> ['보안점검표', '부서 : 포테토뭉부서', '이름 : 감자밭']

# If the lines are already cut, hand the images in directly. Batch them for speed.
reader.read([cell_a, cell_b, cell_c])

# Given a candidate list, the output can be constrained to it.
reader.both([cell_b], options=["포테토뭉부서", "감자밭", "김클로드"])
# -> [{'text': '부서 : 포테토뭄부서', 'constrained': '포테토뭉부서', 'agrees': True}]
Do not trust the constrained result on its own. Because it is constrained, the
model must return something from the list. If the true answer is not in the list you
get a confident wrong answer and nothing looks off. When agrees is false, hand it
to a human.
Reading with several checkpoints
Different checkpoints fail on different cells. Train a little longer on the same data and some cells survive while others die — which tells you those cells were being read by a thin margin. So keep several checkpoints and take the answer they agree on.
unzipped/
  config.json  vocab.json  model.safetensors
  also/
    v20b/  config.json  vocab.json  model.safetensors
    v19/   ...
If also/ is present, Reader uses it automatically. The call site does not change.
Combining by confidence was measured and it did not work — the model is sometimes more confident about a wrong answer. So selection is by how much the outputs agree, not by confidence.
How it is built
  64 x 640 line image
          |
   ViT-Small encoder          facebook/deit-small-patch16-224 (ImageNet-1k, Apache-2.0)
   patch 16                   pretrained weights, continued at a lower learning rate
          |
   TrOCR decoder              6 layers, 6 heads — trained from scratch
          |
   229 jamo tokens            ㄱ ㅏ ㅁ ... assembled into 감
          |
      "부서 : 감자밭"
Two decisions carry most of the result.
Jamo, not syllables. Memorising all 11,172 Hangul syllables needs a large output layer and still fails on anything rare. 229 jamo compose into any syllable, so a character the model never saw in training is still writable — which matters for names.
The encoder is not frozen, but it is not shaken either. It already learned to see on ImageNet, so it continues at a lower learning rate while the blank decoder learns fast. Training both at the same rate destroys what the encoder knew.
Accuracy
Measured two ways. Both matter. All figures below come from
python tools/verify.py (400 lines per font, 11 photos).
| unseen fonts (mean) | worst font | 11 handwriting photos | worst photo | |
|---|---|---|---|---|
| single (v62) | 94.6% | 88.5% | 95.4% | 90.3% |
| three | 95.3% | 90.3% | 95.8% | 90.3% |
Similarity is measured per jamo; on the photo side each photo gets one vote.
Do not take the photo number at face value. It is measured on 11 photos (35 cells) taken by the author, so it swings ±5%p. The figure closer to what you would see on someone else's handwriting is the unseen-fonts column — tested only on six font families never used in training, where the swing is half as wide (±2-3%p).
What several checkpoints buy is the floor, not the mean. The mean moves a little (95.3 vs 94.6), but the worst font goes from 88.5% to 90.3%, and a photo one checkpoint dropped to 93.3% (hand-08) comes back at 100%. Where one checkpoint reads a cell by a hair, another carries it.
Not every page improves, though. A page one checkpoint read at 100% can come down to 96.7% (hand-05) — when two checkpoints agree on the wrong answer, the one that was right is outvoted. And it is eight times slower. Use three checkpoints where a single page reaching a human is costly, one where you need to sweep a lot of pages.
Per font (400 lines each)
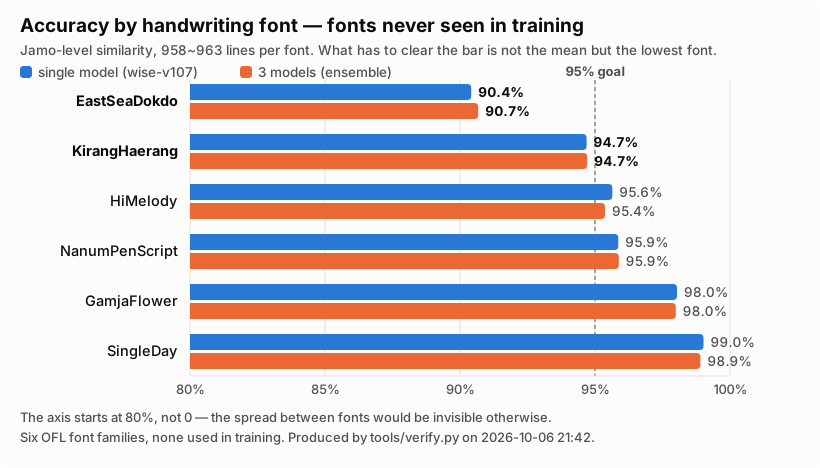
Look only at the average and the font that collapses is hidden. The real spread is 10%p.
| Font | single (v62) | three |
|---|---|---|
| EastSeaDokdo (동해독도) | 88.5% | 90.3% |
| KirangHaerang (기랑해랑) | 93.3% | 93.8% |
| HiMelody (하이멜로디) | 94.6% | 95.6% |
| NanumPenScript (나눔펜스크립트) | 95.2% | 95.5% |
| GamjaFlower (감자꽃) | 97.8% | 97.8% |
| SingleDay (싱글데이) | 98.6% | 99.1% |
What has to clear the bar is not the mean but the lowest font. Once all six passed 90% (2026-09-18) the goal was raised to 95%. Four are over it now; EastSeaDokdo and KirangHaerang are not. Both are hands where strokes merge and get dropped.
All six are fonts never used in training, and all are SIL Open Font License.
python tools/holdout.py <checkpoint-dir> --per-font --sample sample.png
What the test sheet actually looks like
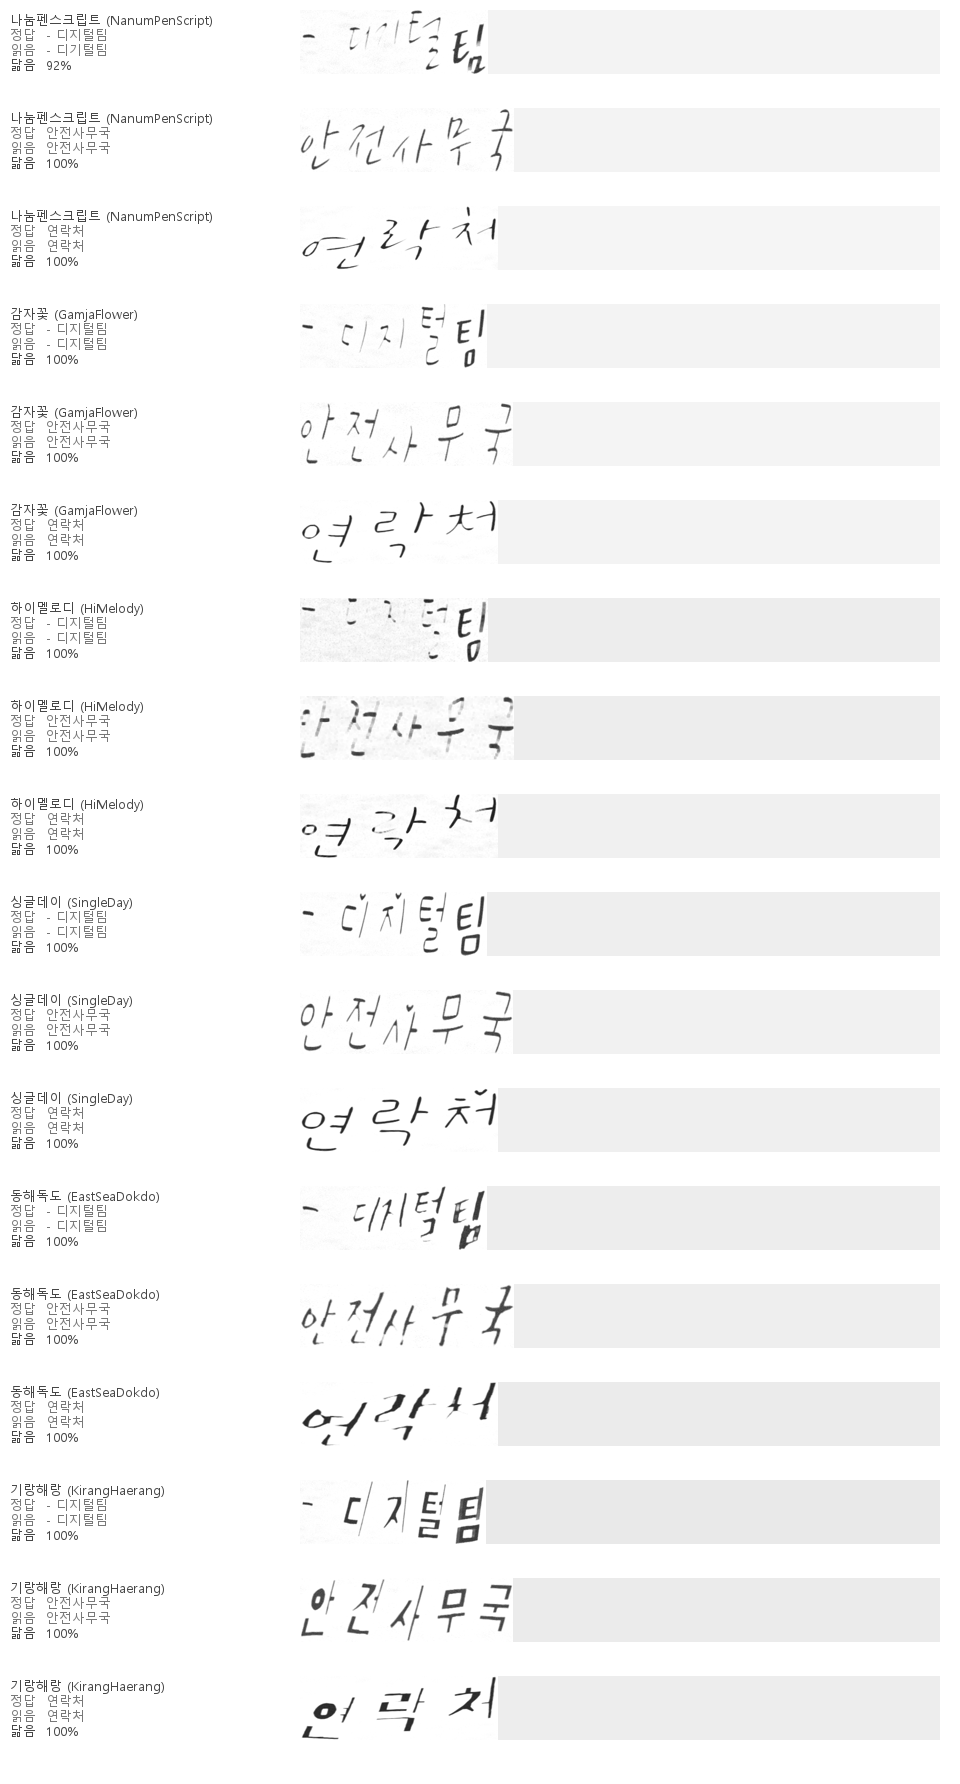
Three lines per font, with the ground truth, what the model read, and the similarity. The pale band on the right is the leftover space from fitting into a 64x640 frame — this is exactly what the model sees.
Every one of the six gets these short form lines right. When the same picture was
produced on 2026-09-02, EastSeaDokdo missed 안전사무국; it does not any more. Where
the fonts pull apart is not lines like these but long sentences and lines no language
knowledge helps with — a third of the sheet is meaningless syllables strung together
(put there on purpose, to train reading from strokes alone), and there a single wrong
jamo has nothing to fall back on.
By shape, SingleDay has well-separated characters and intact strokes, close to print, while EastSeaDokdo and KirangHaerang smear and drop them. That is the difference the table above measures.
This is an image, not a font file. Drawing glyphs with a font is what the OFL
permits; what is not redistributed is the .ttf files themselves
(PROVENANCE.md).
Speed and footprint (measured)
No GPU needed. Emitting jamo one at a time is the bottleneck, so more cores do not help much — and by the same token it does not get slower on a weak machine.
CPU only, median over 11 photos (35 cells). Time is split into cutting and reading — shrinking the model does not shrink cutting, and when a photo holds only three or four lines, cutting is more than half the cost.
| cut | read | one photo (3.2 lines) | per line | 30-line page | |
|---|---|---|---|---|---|
| single, beam 5 | 0.72s | 0.63s | 1.35s | 0.20s | 6.7s |
| single, greedy | 0.73s | 0.34s | 1.07s | 0.11s | 3.9s |
| three, beam 5 | 0.74s | 5.31s | 6.04s | 1.67s | 50.8s |
Memory is about 905MB for one checkpoint, about 1.18GB for three.
The right-hand column is not the photo figure multiplied out. Our test photos hold
three or four lines each, while the "page" other people quote is a thirty-line
document. Quoting our seconds-per-page as if it were theirs flatters us by roughly ten
times. So the batch size is raised step by step to measure how far seconds-per-line
falls, and that value is what gets converted (python tools/bench.py --throughput).
Produced with python tools/bench.py --all --device cpu. That harness walks exactly the
path the application walks — a speed measured along a different path is not the speed
the user gets.
Where it runs
Built and tested on Windows. Training and inference were both run on Windows 11 with Python 3.13/3.14.
| Windows | Where it was built. Training and inference both verified |
| macOS | Untested. Inference is pure PyTorch + PIL so it should run, but it has not been confirmed |
| Linux | Not tried yet |
tools/train.ps1 is PowerShell, so it is Windows-only. Elsewhere, call
python -m kohandocr.train directly — all that script does is wait for the previous
run to release the GPU, launch it, and watch the first few steps.
Training
No data is baked ahead of time. A corpus line is generated, drawn with a handwriting font, and fed in on the spot. Nothing is left on disk, and a change to the distribution takes effect from the next step.
python tools/fetch_fonts.py                       # fetch OFL handwriting fonts
python -m kohandocr.train --out runs/v1 --layers 6 \
       --steps 20000 --batch 40 --workers 5 --letters 128
Fonts are looked up in this order. No path is hard-coded.
- whatever
--fontswas given - the
KOHAND_FONTSenvironment variable ~/.cache/ko-hand-ocr/fonts
Without --layers you get a 4-layer decoder. What ships is 6 layers — at 4 layers,
thirteen rounds of changing the recipe left the font mean stuck between 92.8 and
93.4%, and 6 layers was the first to clear that band. The extra depth costs little on
CPU: 0.16 s per line becomes 0.20 s. The encoder and the input size were left alone.
fetch_fonts.py fetches 482 handwriting fonts. Only 452 of them are trained on;
six are the test above and twenty-four are held back for "does it read widely". A font
with the same design as a test font would quietly inflate the score, so they are
compared as images, not by name, and anything scoring 0.7 or above is set aside.
The fonts are not in this repository and are not redistributed. The 109 Nanum handwriting fonts come from clova.ai/handwriting. Details in PROVENANCE.md.
How closely the synthetic images match real handwriting is checked against the measured
distributions recorded in kohandocr/measured.json — nine of them (ink coverage,
density, aspect ratio, margins and so on).
python tools/match.py # target vs current synthesis, side by side
Running longer does not make it better. After changing the synthesis distribution, run short, keep intermediate checkpoints, and pick between them (measured: 15,000 steps was the peak and 30,000 steps was worse).
python tools/pick.py runs/v1-15000 runs/v1-30000 # score the kept checkpoints and pick
How this was built
The engineering behind this model is written up as a 12-page document — why it exists, the four decisions that shaped it, how the training data was produced at zero labelling cost, how the evaluation was designed, and what is still missing.
Engineering write-up — PDF, 12 pages · 한국어판
It includes the parts that are usually left out: the measurement that was wrong, the approach that was tried and failed, and the numbers that have not been measured yet.
License
Apache-2.0, weights included. The licenses of the fonts used in training do not attach to the weights — the weights are not a derivative of the glyph artwork, they are values learned from images. The reasoning is recorded part by part in PROVENANCE.md.
1 maintainer

Metadata
1 maintainer
Release files for ko-hand-ocr 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ko_hand_ocr-0.3.0.tar.gz | 100.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ko_hand_ocr-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 191.8 kB
Release files / ko_hand_ocr-0.3.0.tar.gz
| Download URL | ko_hand_ocr-0.3.0.tar.gz |
|---|---|
| Size | 100.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1b8358eb3b0ad2029328a81d39cebbdab424ff0e95a183fd21001271153eb9fa
|
|
BLAKE2b-256 checksum How to use checksums |
7e38f1307dca54d7eb4d7fc58fe328949d2d50532cf71016ef7d61fb5018073e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.7
|
Release files / ko_hand_ocr-0.3.0-py3-none-any.whl
| Download URL | ko_hand_ocr-0.3.0-py3-none-any.whl |
|---|---|
| Size | 91.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
431be2883fcf3f36b5509a8239b20ed0b44bc2e18e029d9a0ef76fc2602f91cf
|
|
BLAKE2b-256 checksum How to use checksums |
58947532215ed8c6d2a2432bc67e49d0297af92a663578dcc97f3b10f2402203
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.7
|














