
LLM Preflight
Last reviewed: 2026-10-17 · As of: v2.22.0


No preflight, no merge. A record that your LLM contract passed on this route, recently, in CI. The merge gate rejects stale or borrowed passes.
It doesn't certify production behaviour. It proves the check was done.
Try it in 60 seconds
Find out, with no configuration and no request, which model IDs in a repository the provider has retired or scheduled for retirement:
python3 -m pip install llm-preflight
llm-preflight --audit-source .
The first line is the decision with its counts, the second the exit code;
add --ci to fail a pipeline on it. Findings follow, grouped by model ID:
retired first, each with its date, the provider-stated replacement and a
ready --dry-run command. In a Git checkout only tracked and unignored files
are read. --all lists every model and location; see
model retirements.
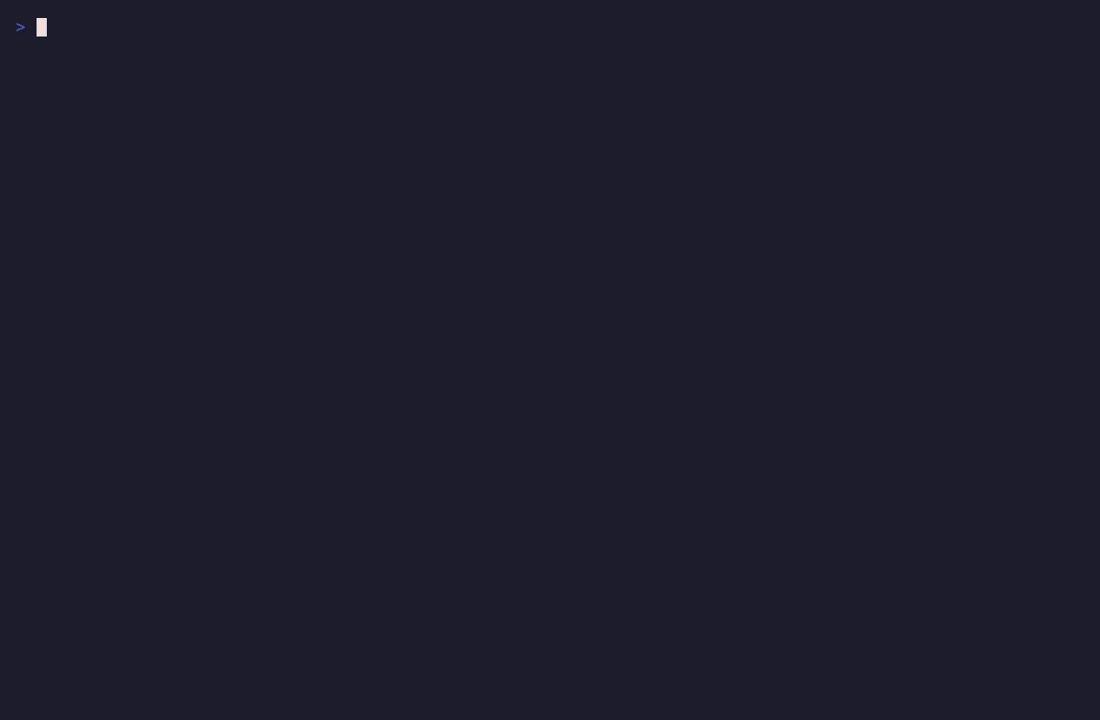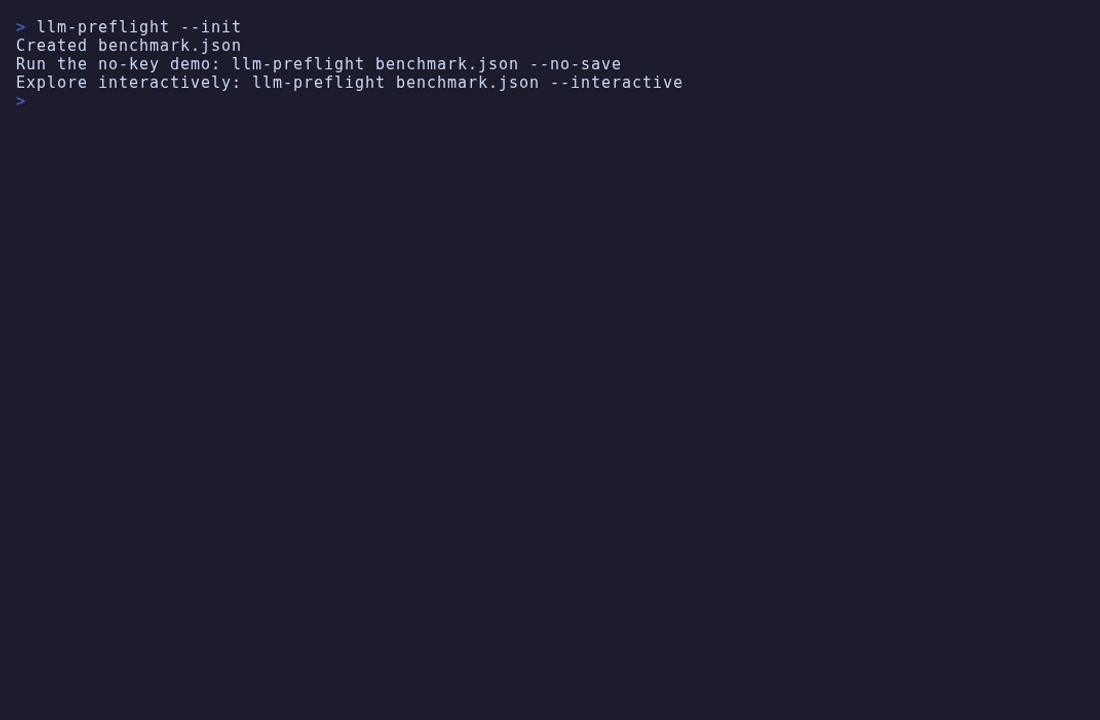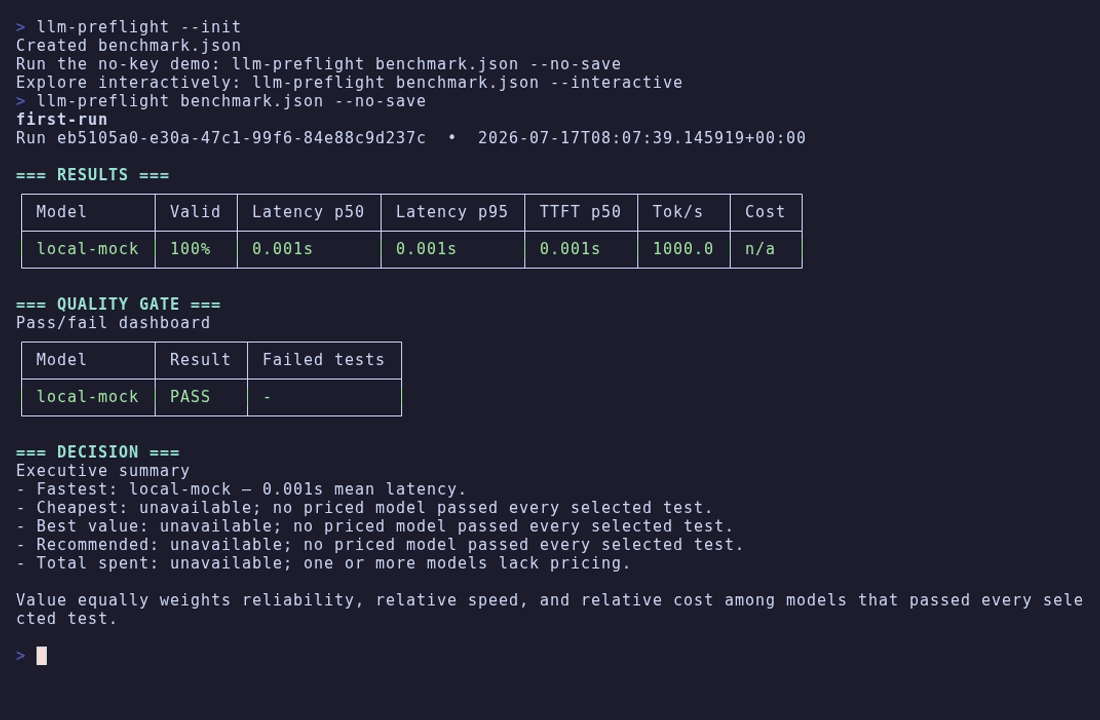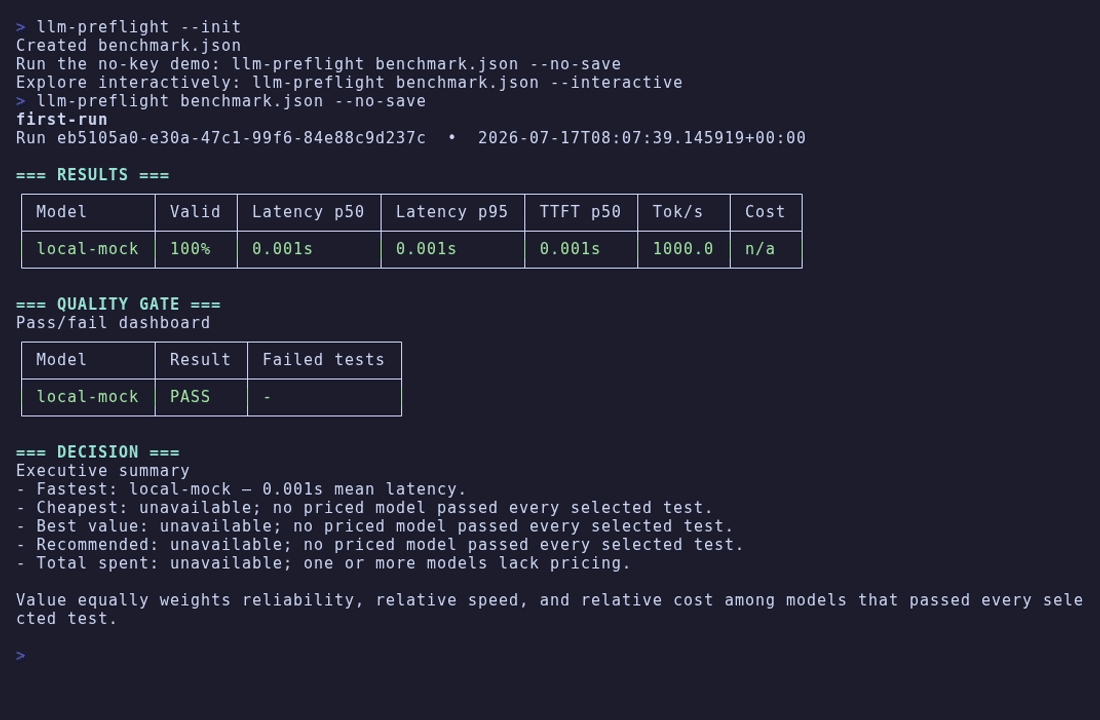
Then create and run a deterministic local benchmark—no API key or network request:
llm-preflight init
llm-preflight benchmark.json --no-save
From a source checkout:
python3 -m llm_preflight init
python3 -m llm_preflight benchmark.json --no-save
init never overwrites an existing config. It creates a mock benchmark so
you can see the report and exit behavior before making a paid request.
Its result is intentionally inconclusive (exit code 3): a local mock
validates configuration and output handling, but cannot approve a live model.
See a contract change fail
These saved results are synthetic fixtures. Render the same report you can attach to a pull request, without contacting a provider. From a checkout of this repository, run:
python3 -m llm_preflight report examples/reports/schema-baseline.json --format markdown
python3 -m llm_preflight report examples/reports/schema-break.json --format markdown
The first result passes. The second catches a response that no longer meets the declared output contract:
Decision: pass (benchmark_passed)
Contract validity: 100%

Decision: fail (contract_failure)
Contract validity: 67%
Contract-only failures: 1
The report gallery adds a cheaper candidate that fails the contract and a compatible baseline comparison with latency and cost regressions. Every number is labeled synthetic; none is a live model claim.
Purpose
Mission: help engineers catch LLM integration regressions before shipping a change.
Vision: every LLM-related pull request carries reproducible evidence of compatibility, latency, and cost.
Positioning: LLM Preflight is a local CLI and CI tool that checks an application's LLM contract and reports compatibility, latency, and estimated cost before a change ships.
It is built for small engineering teams maintaining AI features. Coding agents can run the same checks, while engineers own the decision. Read the north star and the AI implementation testing guide for the intended workflow and boundaries.
Choose your path
- Set up a real project. Adapt a representative contract, reuse an existing env file, and add a no-spend CI check with the project integration guide.
- Validate a change. Compare an approved model, prompt, schema, or provider route with a candidate using the model-change guide.
- Review a new model. Discover metadata, deliberately probe a route, then prepare a bounded candidate smoke with the model-catalogue guide.
- Inspect a measured example. See the dated support-routing model comparison to understand what a narrow contract run can and cannot establish.
- Automate an established contract. Add the no-spend GitHub Marketplace Action or use CI and JSON output.
- Gate merges on a fresh check. Record each approved run in CI and block stale or borrowed passes with proof of preflight.
- Configure a coding agent. Start the local MCP server from a trusted
repository with
llm-preflight-mcp --workspace "$PWD", then use the MCP server guide for your client configuration.
Safety boundary
flowchart LR
    A[Integration change] --> B[No-spend validation\ndoctor, pricing, dry run]
    B --> C{Human reviews\nevidence and cost bound}
    C -->|Explicit approval| D[Bounded paid smoke]
    C -->|No approval or missing evidence| E[Resolve evidence or stop]
    D --> F[Local evidence for\nproduction approval]
LLM Preflight is local evidence, not production approval. It is not a hosted evaluation platform, tracing system, RAG framework, or public leaderboard. Its results apply to your account, network, prompts, and validation rules.
CLI, CI, and MCP
Works as a CLI, GitHub Action, and local MCP server. Every path starts with no-spend validation and planning; a live provider run remains an explicit, bounded human-approved step. See the GitHub Action guide or the MCP server guide.
Native routes and release-reviewed official pricing snapshots are listed in current snapshots. That list is direct-provider price coverage, not a ranking or every discoverable ID.
Release notes for every version are in the changelog.
Common jobs
-
Switch a model or provider. Run the bounded migration check, then add the contract test your feature needs.
-
Check a prompt, schema, parser, or tool change. Define an explicit output contract before the smoke, then run
llm-preflight benchmark.json --contract-checkto prove local accepted/rejected fixtures and lint declared tool schemas. -
Plan an agent-made change. Run
llm-preflight benchmark.json --change-planbefore the ordinary no-spend checks. It identifies static model and contract signals in local Git changes, but never authorizes a paid run. -
Review a newly discovered model. Refresh metadata, then prepare—not run— a bounded candidate plan:
llm-preflight catalog refresh benchmarks/watch.json
llm-preflight catalog prepare benchmarks/watch.json \
  --against benchmarks/approved.json --output benchmarks/candidates.json
llm-preflight benchmarks/candidates.json --migration-check --dry-run
Only explicitly approved, fully evidenced models proceed to paid work; see the model catalogue guide.
-
Investigate a provider or price change. Run
--doctor,--pricing-check, and a dry-run; report a suspected regression through the redacted issue forms. -
Automate a known contract. Use the no-spend GitHub Action or the CI guide with a saved baseline and
--ci.
It measures deterministic test validity, end-to-end latency (p50/p95), time to first token, throughput when the stream is incremental and usage is available, token totals, and estimated cost. Result files retain request metadata and per-request observations for reproducibility.
"Deterministic" describes the validator, not the model: every response is checked against explicit structural rules — a regular expression, a JSON shape, an exact routing label — so the same response always produces the same verdict. The tool does not score semantic quality; that is your task-specific evaluation, and it stays out of scope on purpose.
What live evidence looks like
A completed preflight retains per-request observations and a machine-readable
decision: contract validity, latency (including TTFT where observable), token
usage, estimated cost, pricing evidence, and blocking warnings. The terminal
summary is a convenience; automation should consume the saved JSON decision.
Render saved schema-version-1 JSON as a self-contained offline HTML report with
llm-preflight report results/run.json --output report.html. The renderer
omits prompts, responses, local paths, and identifying run metadata; the
Marketplace Action adds a compact report to the GitHub Actions job summary.
That evidence applies to your account, network, prompts, and validator at one time—not a universal model ranking. For a complete interactive example, see interactive runs.
Tested models
| Model | Checks passed | Mean latency | Est. cost / 16 | Last tested | Connection |
|---|---|---|---|---|---|
| GPT-6 Astra | 16/16 | 2.184s | $0.024610 | 2026-09-28 | OpenAI |
| GPT-6.1 Sol | 16/16 | 1.674s | $0.005112 | 2026-10-14 | OpenAI |
| GPT-6 Luna | 16/16 | 2.150s | $0.000353 | 2026-10-14 | OpenAI |
| Claude Opus 5.5 | 16/16 | 1.985s | $0.013220 | 2026-10-14 | Anthropic |
| Claude Sonnet 5.5 | 16/16 | 1.095s | $0.005740 | 2026-10-14 | Anthropic |
| Claude Haiku 5.5 | 16/16 | 0.934s | $0.000479 | 2026-10-14 | Anthropic |
| Gemini 4 Argon | 16/16 | 2.376s | $0.005546 | 2026-10-14 | Gemini |
| Gemini 3.8 Flash | 16/16 | 2.255s | $0.005666 | 2026-10-14 | Gemini |
| Gemini 3.1 Flash-Lite | 16/16 | 0.977s | $0.000588 | 2026-09-28 | Gemini |
| GLM 5.3 | 11/16 | 1.221s | — | 2026-10-14 | OpenRouter / Relace |
| GLM 5.3 Flash | 16/16 | 1.535s | $0.000178 | 2026-10-14 | OpenRouter / Relace |
| DeepSeek V4.1 Flash | 16/16 | 2.342s | $0.000745 | 2026-10-14 | OpenRouter / Relace |
| Qwen 3.8 Max 0902 | Request rejected | — | — | 2026-10-14 | OpenRouter / Alibaba US |
| Qwen 3.8 Flash | 5/16 | 1.077s | — | 2026-10-14 | OpenRouter / Alibaba US |
First live run
Python 3.10+ is required. The installed CLI and MCP server have no third-party runtime dependencies. Create a bounded provider starter from any directory:
llm-preflight init live.json --template provider \
  --provider openai --model gpt-6.1-sol --api-key-env OPENAI_API_KEY
Set OPENAI_API_KEY in your shell or in .env.production beside live.json.
The starter expects exactly ok. Add the following top-level field to
live.json, keeping its existing fields, to check that validator locally:
{
  "validation_fixtures": [
    {"name": "accepted-label", "response": "ok", "expect": "pass"},
    {"name": "rejected-label", "response": "not ok", "expect": "fail"}
  ]
}
# Review the prompt, validator, model, request limit and estimated-cost cap.
llm-preflight live.json --contract-check
llm-preflight live.json --doctor
llm-preflight live.json --pricing-check
llm-preflight live.json --dry-run

# Paid request: run only after explicitly approving the displayed plan.
llm-preflight live.json
The starter uses one short exact-output check, a three-request limit and a $0.05 estimated-cost cap. Adapt it to a representative application contract before using its result to review a model. The checks above make no generation requests; the final command does.
The CLI reads .env.production beside the config without overriding shell
variables. Select an existing file with --env-file PATH, or use
--no-env-file. Results are saved as JSON and Markdown under results/
unless you use --no-save. See project integration
for an application example and a no-spend CI gate.
Change a model safely
This is the core workflow. Put your approved model and candidate model in one config, review the combined request and cost limits, then preview the small response-and-contract preflight:
llm-preflight benchmark.json --migration-check --dry-run
llm-preflight benchmark.json --migration-check
It sends three short representative cases to each selected model, once each. It answers: did the API work, did each response meet the basic contract, and how quickly did the provider start and finish responding? It is a cheap compatibility check, not a statistical performance conclusion.
When that passes, run the task-specific checks that match your application—for
example exact-routing-check or structured-output-check—before approving a
switch.
Use custom contract tests to express the outputs your
own feature must preserve.
Using a coding agent
Give an agent the same evidence you would use yourself: a reviewed config, an
explicit output contract, and a dry run before paid work. The agent-smoke
alias selects five profiles; --smoke makes six requests per model:
# No generation request: inspect credentials, model selection, and paid-work plan.
llm-preflight benchmark.json --doctor --json
llm-preflight benchmark.json --tests agent-smoke --smoke --dry-run --json

# Paid run, only after reviewing the plan.
llm-preflight benchmark.json --tests agent-smoke --smoke --json --no-save
An agent should not infer model IDs, weaken a validator to turn a failure into a pass, or approve a model without an explicit instruction. The compact LLM and coding-agent guide covers commands, result JSON, exit codes, and automation guardrails. The AI implementation testing guide shows how to make this validation an agent's default testing step.
MCP for coding agents
Use the local stdio MCP server when an agent needs the preflight evidence without shell parsing or arbitrary command execution:
{
  "mcpServers": {
    "llm-preflight": {
      "command": "llm-preflight-mcp",
      "args": ["--workspace", "/absolute/path/to/repository"]
    }
  }
}
It exposes only seven tools: audit a repository's literal model IDs without a config, validate a config, prepare a dry-run plan, run an explicitly confirmed preflight, compare saved baselines, and verify or gate proof-of-preflight records. All but the live run never contact providers or load credentials, and a gate pass is never approval. A live run still needs an explicit paid-run confirmation. See the MCP server guide for tool semantics, workspace boundaries, and the safe agent workflow.
Useful commands once you know your path
# Inspect configuration, credentials, and model selection without generation.
# --doctor provides pricing advisory; use --pricing-check as the fail-closed coverage gate.
llm-preflight benchmark.json --doctor
llm-preflight benchmark.json --pricing-check
llm-preflight benchmark.json --dry-run

# Run a reduced live benchmark.
llm-preflight benchmark.json --smoke

# Run a single ad hoc prompt.
llm-preflight --quick "Return only valid JSON with a status field." \
  --models openai:gpt-6-luna
The guided interactive preflight lets you select models and workload, review the shared plan and local fixtures, then preview, export, edit, or explicitly confirm execution. Try the offline example from a source checkout:
llm-preflight examples/interactive-contract.json --interactive --dry-run --no-env-file
See interactive runs for the prompts, exports and scripted equivalents.
For advanced discovery, interactive runs, CI, baselines, replay, and stop modes, see workflows. For models, environment files, custom prompts, and provider-specific options, see configuration.
What makes a comparison useful
- Keep prompts, system instructions, temperature, and output limits fixed.
- Validate outputs: a fast malformed response is a failed result.
- Run from the same host; network distance and provider load affect latency.
- Treat single-user latency and load testing as separate experiments.
- Prefer dated model IDs over moving aliases.
The CLI distinguishes API FAIL (transport, credentials, provider, or request
failure) from API OK / TEST FAIL (a response that fails your validator).
Recommendations only consider models that pass every selected test.
How it compares
Several good tools live near this space. Use them when their job is your job:
- promptfoo, deepeval — full evaluation suites: scored quality metrics, red-teaming, large ongoing test matrices in CI. Use them to grade prompt and model quality over time.
- Braintrust, LangSmith — hosted platforms: tracing, dashboards, team collaboration, production observability.
llm(Simon Willison) — a general multi-provider CLI for running prompts, not a comparison harness.
LLM Preflight does one narrower job: the local go/no-go check in the moment before an LLM integration change. Your prompt, candidate models, structural validation, latency, and cost — one command, one report, no hosted service, no telemetry, and no vendor between you and the verdict.
Documentation
Start at the documentation homepage, then choose the path that matches your work:
- Start safely: safe demo and model change.
- Validate a change: output contracts, model catalogue, and pricing and safety.
- Automate: CI and JSON output, coding agents, and MCP.
- Look up details: CLI reference, configuration, result JSON, and troubleshooting.
- Understand the product: north star, product decisions, and AI implementation testing.
- Contributing — development setup and the TDD workflow.
- Security — reporting vulnerabilities.
Contributing and license
Contributions are welcome; see CONTRIBUTING.md. Released under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for llm-preflight 2.22.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| llm_preflight-2.22.1.tar.gz | 988.4 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| llm_preflight-2.22.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.2 MB
Release files / llm_preflight-2.22.1.tar.gz
| Download URL | llm_preflight-2.22.1.tar.gz |
|---|---|
| Size | 988.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
881d49147233f460cfa74ff6f40f0758c3ad0baedd7cffc0e5a2c0139663e98f
|
|
BLAKE2b-256 checksum How to use checksums |
373a3b12289ddf08d0ac2793d495c0689a9c3af65ba9b8842406a5596af70b51
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / llm_preflight-2.22.1-py3-none-any.whl
| Download URL | llm_preflight-2.22.1-py3-none-any.whl |
|---|---|
| Size | 167.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0f2347e7c11c37f4e0b9f02c4b061464c0f862a8feb3741cfa5b50dfc1719518
|
|
BLAKE2b-256 checksum How to use checksums |
29fd03b30b29792df3c051752a0488bc633bd9ec0cbdfe8c6a8c59da21a17585
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for llm-preflight 2.22.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for llm_preflight-2.22.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














