
Open Data Stack


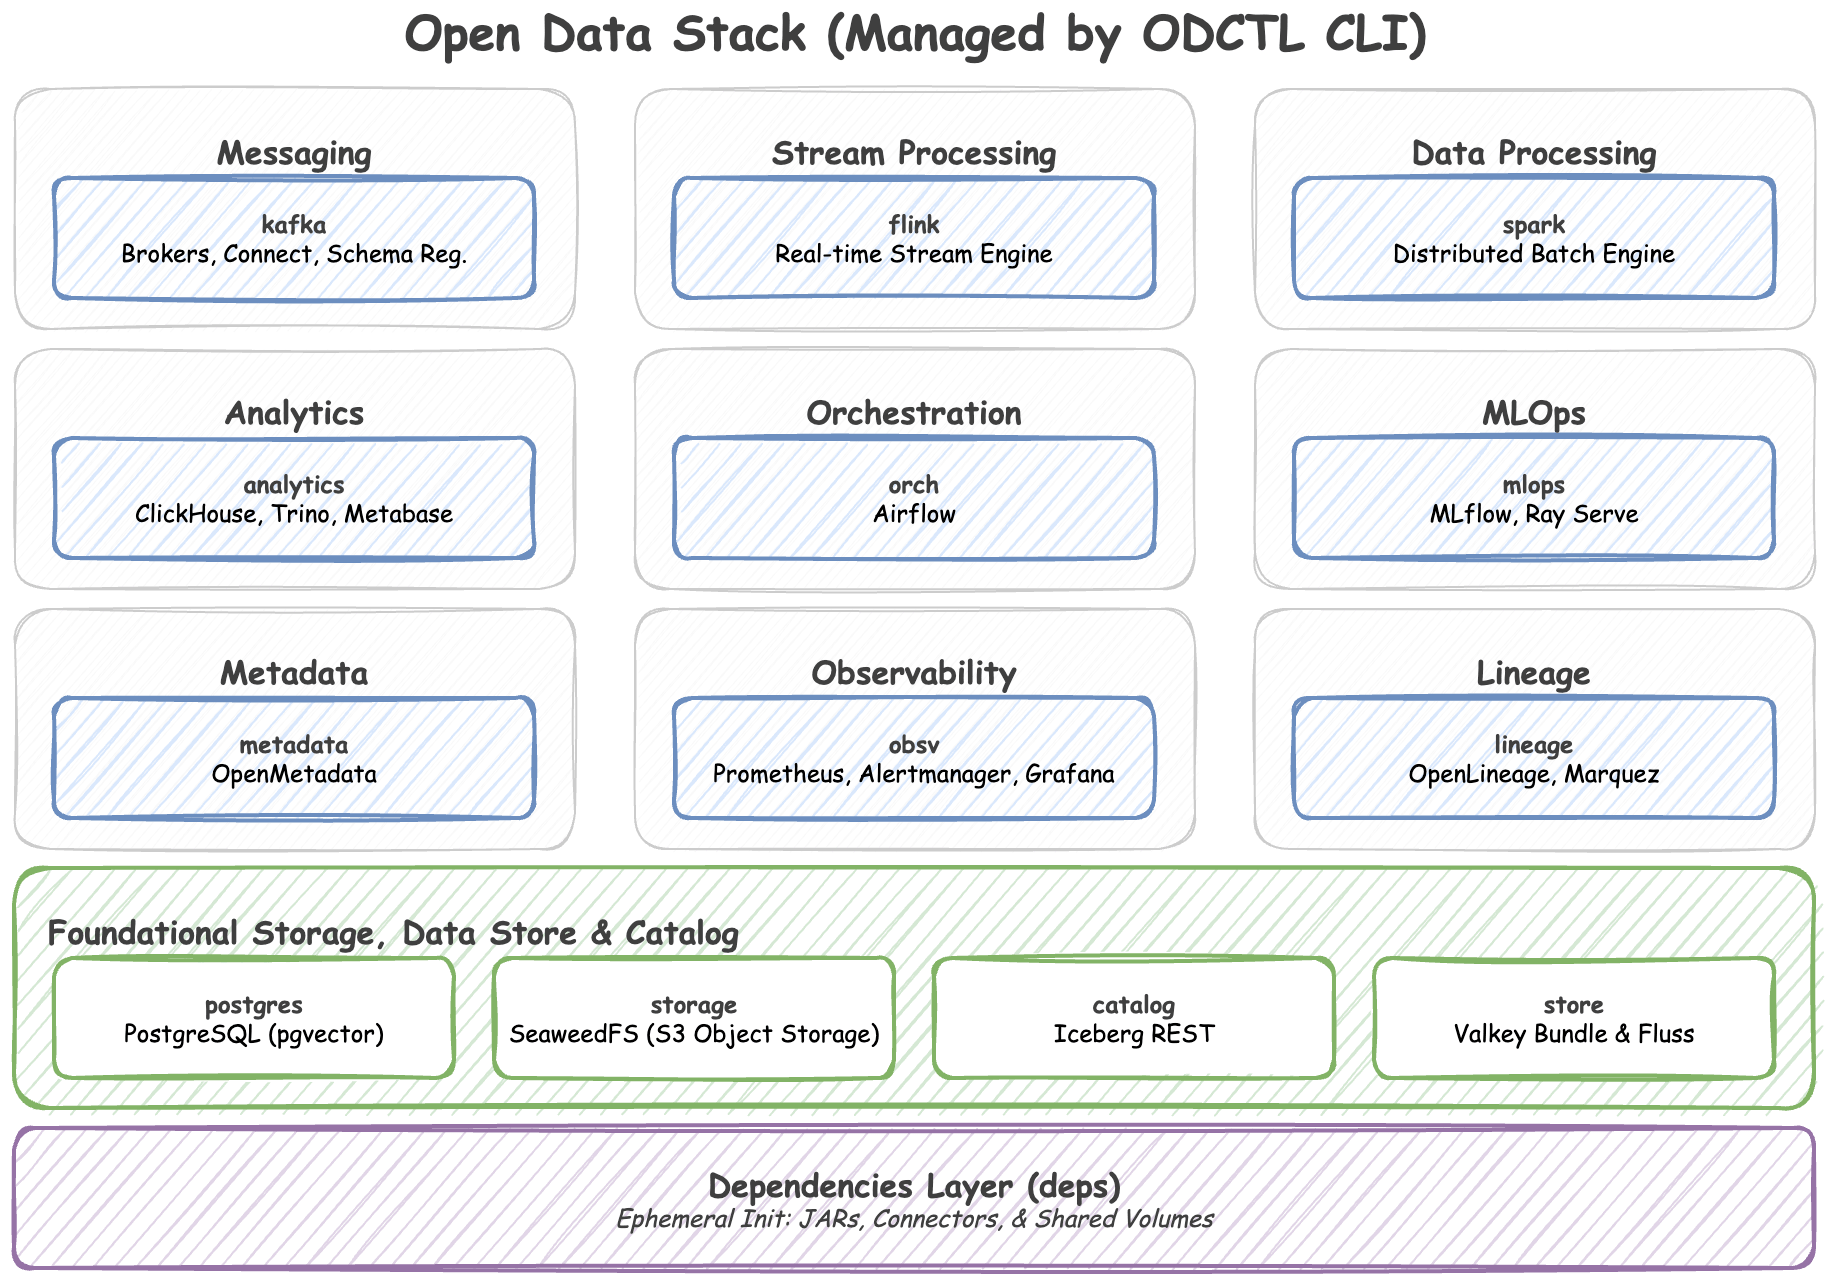
A curated collection of open-source technologies and an accompanying CLI (odctl) for experimenting with modern data architecture and MLOps locally.
Provisioning a local data environment with distributed systems can be highly complex. The Open Data Stack streamlines this process by resolving dependency conflicts, network routing configurations, and integration challenges across tools like Kafka, Spark, Flink, Iceberg, and Airflow. It provides a cohesive, Docker-based blueprint that operates seamlessly out of the box.
Bundled Technologies
The stack is organized into distinct profiles that can be launched independently or together:
- Messaging: Real-time event streaming, schema validation, and robust data ingestion.
- Stack: Kafka (KRaft), Schema Registry (Karapace), Kafka Connect, Kafka UI (kafbat)
- Connect plugins: Apache Iceberg sink (built from the Iceberg release the stack uses), Debezium PostgreSQL source, ClickHouse sink, Aiven JDBC and S3 sink, Redis, and the MSK data generator
- Stream Processing: Stateful stream processing and continuous real-time data transformations.
- Stack: Apache Flink
- Data Processing: Distributed batch processing and large-scale ETL pipelines.
- Stack: Apache Spark
- Analytics: Real-time OLAP querying, federated SQL execution, and interactive BI dashboards.
- Stack: ClickHouse, Trino, Metabase
- Orchestration: Workflow scheduling, DAG execution, and complex pipeline automation, in one container that reads DAGs from object storage. Durable workflows written in code, such as one that waits days for a person to approve an agent's action, in a second container.
- Stack: Apache Airflow (standalone, with the MLflow and Feast clients and the XGBoost, LightGBM and PyTorch runtimes), Temporal (development server with the Web UI and a SQLite database)
- MLOps: Machine learning experiment tracking, model registry, HTTP model serving, a feature store, and monitoring of data drift and model quality over time.
- Stack: MLflow, Feast, Evidently
- Metadata: Centralized data catalog, data discovery, and enterprise governance.
- Stack: OpenMetadata
- Observability: Metrics, traces and logs over OpenTelemetry in one container, with a Grafana dashboard for each service in an
odctlfolder.- Stack: grafana/otel-lgtm (OpenTelemetry Collector, Prometheus, Tempo, Loki, Grafana)
- Lineage: Data provenance, pipeline dependency tracking, and troubleshooting.
- Stack: OpenLineage, Marquez
- Foundational Storage, Data Store, & Catalog: Persistent state, S3-compatible object storage, unified table metadata, vector, keyword and geospatial search, caching, and unified stream storage.
- Stack: PostgreSQL 18, SeaweedFS (S3), Iceberg REST Catalog, Valkey Bundle, Apache Fluss
- PostgreSQL extensions: pgvector (vector search), pg_textsearch (BM25 keyword search, for hybrid search with pgvector) and PostGIS (geospatial queries), created in the
vectordatabase
Images
Most services run their projects' official images, pinned to exact versions. odctl builds five images of its own and publishes them to ghcr.io/jaehyeon-kim/odctl/, tagged with the CLI version, so odctl 0.10.0 runs images tagged 0.10.0:
deps: fills a shared volume with connectors, jars and the Prometheus JMX agent, including the Iceberg REST catalog and the Kafka Connect Iceberg sink, both built from the Iceberg release the stack uses.postgres: PostgreSQL 18 from the official image, with pgvector, pg_textsearch and PostGIS.airflow: Airflow with the MLflow and Feast clients and the model runtimes.mlflow: the MLflow server and model server with the model runtimes.spark: Spark with the Python clients jobs use (ClickHouse, PostgreSQL, Valkey, MLflow and boto3). Its Iceberg and OpenLineage jars come from thedepsvolume.
Prerequisites & Installation
Requirements
- Docker: Docker Engine or Docker Desktop must be running. We highly recommend allocating at least 8GB to 16GB of RAM to Docker, as data processing engines are resource-heavy.
- Python: Version 3.10 or higher.
Installation
Since odctl is a CLI tool, it is highly recommended to install it in an isolated environment using uv tool or pipx.
Using uv (Recommended):
uv tool install odctl
Using pipx:
pipx install odctl
Using pip:
pip install odctl
Quick Start
Get your local cluster up and running in three simple steps.
1. Initialize your workspace
This command copies the default Docker Compose files and configurations into a hidden .odctl folder in your current directory.
odctl init
2. Explore available profiles See a full list of technologies you can launch.
odctl list
3. Launch the streaming and batch processing engines Bring up a robust data engineering environment.
odctl up kafka-lite flink-lite spark-lite
Note: You do not need to memorize dependencies. The CLI will automatically detect that these profiles require foundational infrastructure and will launch PostgreSQL, SeaweedFS (S3), and the Iceberg REST Catalog for you before starting the target compute engines.
CLI Command Reference
The odctl CLI orchestrates the Open Data Stack and is logically grouped by functionality. You can append --help to any command for deeper parameter details.
Global Options
--verbose: Enable debug-level logging across all commands.-w, --workspace PATH: Path to the ODCTL workspace directory (default:./.odctl).
Inspection & Info
odctl list: List all available profiles and their capabilities.odctl explain <profile>: Explain the details, services, images, and dependencies of a profile.odctl ps: List Docker containers managed by the Open Data Stack.odctl info: View package and system-wide Docker daemon health status.
Host addresses in odctl explain use 127.0.0.1. With IPv6 enabled in Docker, localhost can reach a service's IPv6 address, and services that listen on IPv4 only reset the connection. localhost works when Docker's IPv6 is off.
Workspace
odctl init: Initialize a local.odctlworkspace for custom configurations.
Cluster Lifecycle
odctl pull: Pre-fetch Docker images without starting the containers.odctl up: Launch Open Data profiles (automatically resolves upstream dependencies).odctl down: Stop and remove profile containers and networks.
Management
odctl logs: Fetch the logs of containers managed by specific profiles.odctl restart: Restart one or more specific profiles, keeping their containers.odctl recreate: Replace one or more profiles' containers, which is what applies an edited compose file. Add--pullto refresh the images too.
restart and recreate differ in one way that matters: a restart bounces the process inside the existing container, so a new memory limit, port, image tag or environment variable never reaches it, while a recreate replaces the container from its current definition. Recreating therefore discards whatever that container held. Both act only on the profiles you name, unlike up, which stops the ones you leave out.
Examples
# View all profiles and exposed ports
$ odctl list -d

# See exactly what the kafka profile provisions
$ odctl explain kafka-lite

# Launch specific profiles
$ odctl up flink-lite kafka-lite spark-lite

# Complete teardown and wipe all data
$ odctl down --all --volumes
Workspace Customization (.odctl)
The Open Data Stack is designed to be fully hackable. When you run odctl init, a local ./.odctl/ workspace is generated in your current working directory.
This folder contains all the underlying configurations that power the stack:
compose-*.yml: The actual Docker Compose definitions. You can edit these to change exposed ports, adjust memory limits, or inject new environment variables.registry.yml: The internal dependency graph..env: The environment variables used across the stack (e.g., default credentials or timezones).grafana/dashboards/: The Grafana dashboard for each service. Edit a file and restart thetelemetryprofile to load it; changes made in the Grafana UI are not kept.trino/rules.json: Trino's file-based access control. The shipped policy is deliberately generic: it grants every identity full table privileges and deniesanalystschema ownership, and it names no catalog, schema or table, because those belong to your project rather than to this tool. Add your own table rules here for row filtering and column masking, and restart Trino afterwards, since the file is read at startup.
The CLI will always prioritize the files in your local ./.odctl/ directory. If you make a mistake, you can always revert to the pristine default state by running odctl init --force.
Related reading
Blog posts that use this CLI:
- Productionizing an Online Product Recommender using Event Driven Architecture: splits a contextual bandit recommender into a serving layer and a training layer on Kafka, Flink and Valkey.
- Introducing odctl: One CLI for a Local Open Data Stack: why the tool exists and how one command launches the stack.
- Building an Agentic Analytics System over an Iceberg Lakehouse: runs Trino, Iceberg and object storage from this CLI under a semantic layer an agent queries.
Local Development & Contributing
If you want to contribute to the CLI itself, we welcome pull requests!
- Clone the repository.
- Install uv for dependency management.
- Sync the dependencies and install the project in development mode:
uv sync - Install the pre-commit hooks to ensure formatting checks pass:
uvx pre-commit install
- Run the test suite:
uv run pytest tests/
License
This project is licensed under the Apache License 2.0. See the LICENSE file for details.
1 maintainer

Metadata
1 maintainer
Release files for odctl 0.10.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| odctl-0.10.0.tar.gz | 467.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| odctl-0.10.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 639.9 kB
Release files / odctl-0.10.0.tar.gz
| Download URL | odctl-0.10.0.tar.gz |
|---|---|
| Size | 467.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
06196b02806693caec70da3f40df774840964b21b7bc51664ebc3cc1fc8476dc
|
|
BLAKE2b-256 checksum How to use checksums |
6d85658da2ceb9d890e7459c0937a26e43995e747cce5cdecbfa04f2d2a2adc6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logRelease files / odctl-0.10.0-py3-none-any.whl
| Download URL | odctl-0.10.0-py3-none-any.whl |
|---|---|
| Size | 172.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
60cabbce0f67fb16d604d83e4b4b193865bf0d672aa540481b8f93511d679d5f
|
|
BLAKE2b-256 checksum How to use checksums |
ed1090fcde002e833b735f40ce1d9e5934957999c2f978e75a9d2e3e1c9229d7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency log













