
PhaseSweep
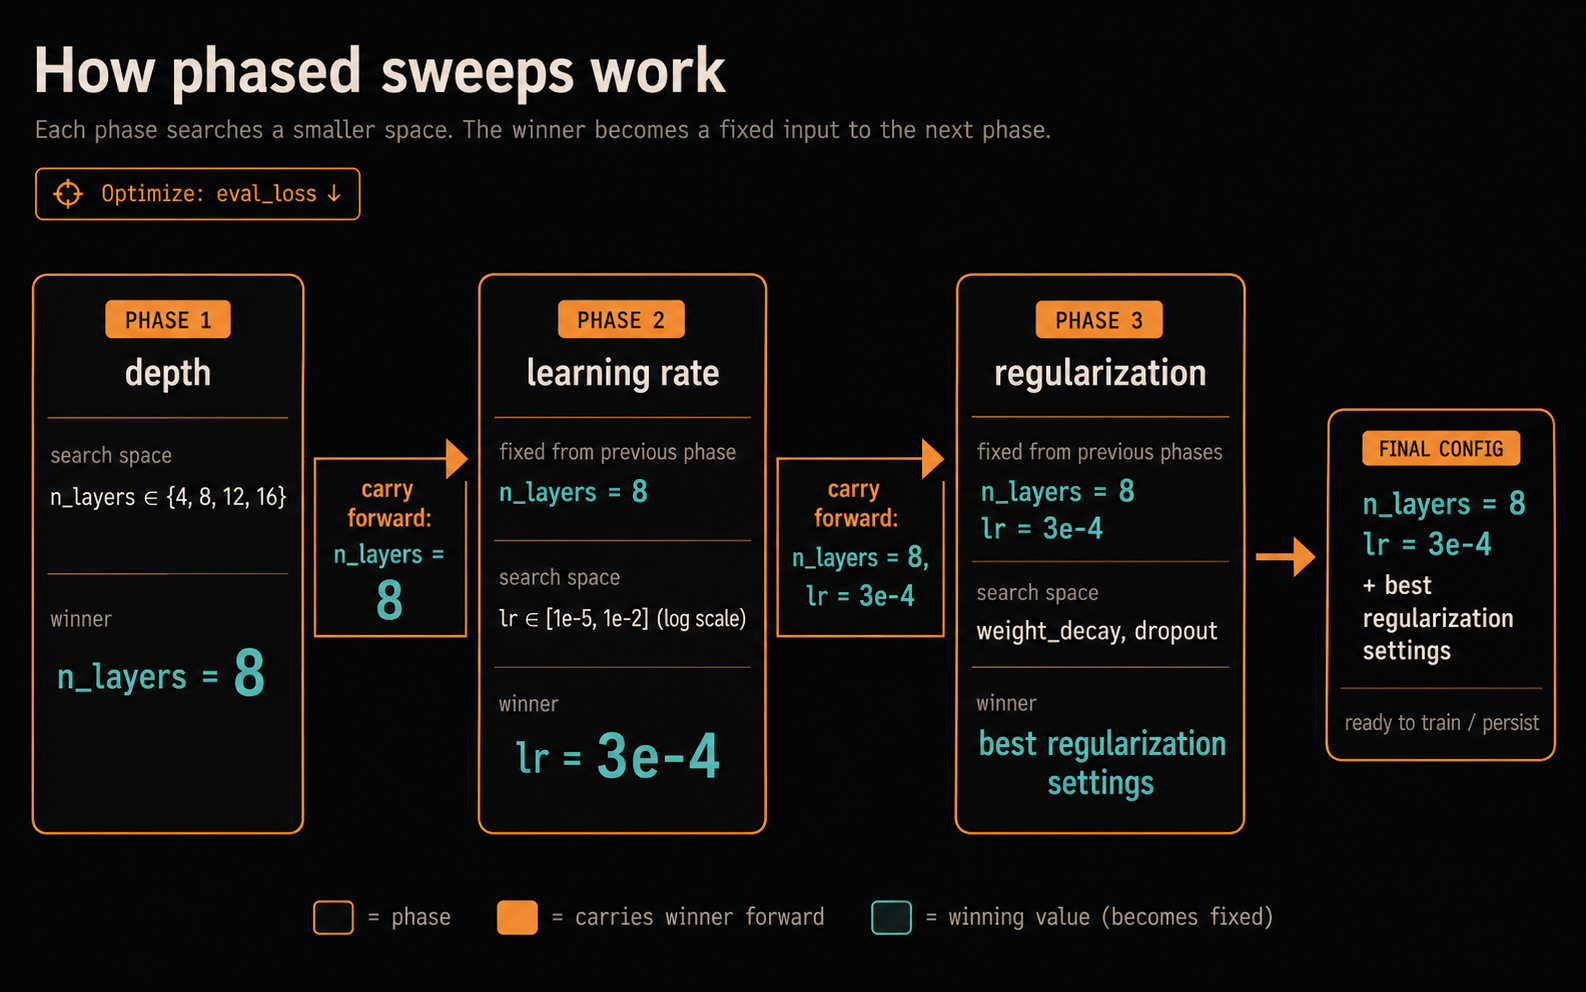
PhaseSweep runs phase-chained hyperparameter sweeps from one ordinary YAML file. That file contains your trainer configuration, the metric, and the search plan. PhaseSweep materializes the configured trainer input for every trial, decides what to try next, persists each phase winner, and carries selected values forward as fixed inputs to later phases.
This is useful when a full joint sweep is too expensive or hard to interpret. For example, choose architecture depth, then tune learning rate, then regularization. The configuration guide explains the inheritance model and its tradeoffs.
How it works
The starter.yaml that phasesweep init writes searches depth before learning rate (abridged; the full file also sets storage, the working directory, and the metric extractor):
experiment: phasesweep_starter

# The trainer receives one complete generated YAML per trial.
trial_command: "python -m phasesweep.examples.fake_train --config {config_path}"

trainer_config:
  model:
    n_layers: 8
    dropout: 0.1
  optimizer:
    lr: 0.0003
    weight_decay: 0.05

metric:
  name: eval_loss
  goal: minimize

phases:
  - name: depth
    n_trials: 2
    sampler: { type: grid }
    search_space:
      model.n_layers: { type: categorical, choices: [6, 8] }

  - name: learning_rate
    inherits: [depth] # the winning model.n_layers is fixed here
    n_trials: 2
    sampler: { type: grid }
    search_space:
      optimizer.lr: { type: categorical, choices: [0.0001, 0.0003] }
The packaged fake trainer reports through the optional report_objective(...) helper, which the json_envelope extractor reads. Your own trainer can report through that helper, W&B, MLflow, ordinary JSON, or logs.
Install and try it
Requirements: Python 3.11+ and a Linux host for real runs. GPUs are optional.
pip install phasesweep
phasesweep --version

mkdir phasesweep-demo && cd phasesweep-demo
phasesweep init                     # writes the starter template, starter.yaml
phasesweep validate starter.yaml    # checks it without launching anything
phasesweep run starter.yaml         # four tiny trials, a few seconds
phasesweep init never overwrites an existing file. phasesweep init --list names the other templates, which cover a trainer that takes --key=value flags, one phase per architecture, a chained search and a noisy objective; --template NAME writes one, and -o PATH names the file or a directory that receives NAME.yaml. Every template runs as written on the packaged toy trainer, so replace its trainer command, keys and extractor with your own.
The run log, runs/phasesweep_starter/run.log beside the config, shows the phase chaining directly and gains one TRIAL line per trial that ends; tail -f follows it while a sweep runs (abridged):
[depth/trial_0] python -m phasesweep.examples.fake_train --config .../trainer_config.yaml
phase=depth TRIAL trial=0 state=COMPLETE outcome=success value=0.3 duration=0.8s (1/2 finished)
[depth/trial_1] python -m phasesweep.examples.fake_train --config .../trainer_config.yaml
phase=depth TRIAL trial=1 state=COMPLETE outcome=success value=0.5 duration=0.7s (2/2 finished)
phase=depth WINNER trial=0 metric=0.3 params={'model.n_layers': 8}
[learning_rate/trial_0] python -m phasesweep.examples.fake_train --config .../trainer_config.yaml
phase=learning_rate TRIAL trial=0 state=COMPLETE outcome=success value=0.3 duration=0.8s (1/2 finished)
[learning_rate/trial_1] python -m phasesweep.examples.fake_train --config .../trainer_config.yaml
phase=learning_rate TRIAL trial=1 state=COMPLETE outcome=success value=0.413822 duration=0.8s (2/2 finished)
phase=learning_rate WINNER trial=0 metric=0.3 params={'optimizer.lr': 0.0003}
The depth winner's model.n_layers: 8 is injected into every learning_rate trial's complete YAML. Winners persist in the working directory, so you can inspect them any time (abridged):
phasesweep show-winners starter.yaml
phase: learning_rate
metric:
  eval_loss: 0.3
  goal: minimize
trial_number: 0
params:
  optimizer.lr: 0.0003
effective_overrides:
  model.n_layers: 8
  optimizer.lr: 0.0003
# ... completion state, fingerprints, objective provenance, and confound
# verdicts on the ranked population follow
Every trial of the same run, with its state, value, sampled params, and a * on each published winner, is one read-only command away:
phasesweep status starter.yaml --trials
experiment phasesweep_starter: winner (*) marks published generation be4f520d0ec04175ac623ac6184d342e; it does not follow a later run until that run publishes

=== depth === (2 trials)
trial  state     value  params            duration_s  winner
    0  COMPLETE    0.3  model.n_layers=8         0.6  *
    1  COMPLETE    0.5  model.n_layers=6         0.5

=== learning_rate === (2 trials)
trial  state        value  params               duration_s  winner
    0  COMPLETE       0.3  optimizer.lr=0.0003         0.6  *
    1  COMPLETE  0.413822  optimizer.lr=0.0001         0.6
A run stopped by Ctrl-C or a kill resumes when you run the same config again: finished phases replay their winners, and a phase cut short reruns the trials the stop interrupted, with their parameters, before it draws anything new. An interrupted trial never counts toward n_trials, so under grid or seeded random the resumed phase evaluates what an uninterrupted run would at any n_jobs, and under seeded tpe or cmaes it does at n_jobs: 1 given the same trial values (interrupted trials rerun, why TPE and CMA-ES need n_jobs: 1).
Use your own trainer
Start from the template closest to your trainer, then choose the input interface it already accepts. phasesweep explain KEY prints the reference for one key, and a configuration error from validate or run ends with see: phasesweep explain KEY lines naming the keys involved.
| Input | Command placeholder |
|---|---|
Complete base-plus-overrides YAML (yaml_file, default) |
--config {config_path} |
Command-line flags (argparse) |
{overrides} produces --key=value for every trainer_config leaf and override |
Native Hydra overrides (hydra) |
{overrides} produces key=value for every trainer_config leaf and override |
Nested JSON, base plus overrides (json_file) |
--overrides {overrides_path} |
argparse renders a boolean as --key=true or --key=false, which a plain store_true flag rejects; validate and --dry-run warn when a configured value would render that way. Write such a flag in trial_command instead, or have the trainer accept a value.
The trainer runs in execution.cwd, or in the directory you started PhaseSweep from when that is unset, with a minimal environment: PATH, HOME, TMPDIR and a few more, not the shell's PYTHONPATH, conda settings, caches or credentials. Name what it needs under env or execution.inherit_env; validate and --dry-run print the environment: and trainer cwd: lines, and a relative path in the config resolves against the config file's directory. The trainer contract has the details.
For ordinary JSON output, pass an output path under {trial_dir} to your trainer and select it with extractor: {type: json, path: result.json, key: eval.loss}. For W&B, use extractor: {type: wandb, entity: YOUR_ENTITY, project: YOUR_PROJECT, metric_key: eval/loss}, have the trainer honor the supplied W&B identity, and install the extra:
pip install "phasesweep[wandb]"
For native MLflow metrics, install phasesweep[mlflow], configure an existing experiment in the mlflow block, and use extractor: {type: mlflow, metric_key: eval/loss, select: last}. See the MLflow guide for both run ownership modes, a complete CPU example, Databricks setup, and retrying result uploads.
Report through phasesweep.report_objective(...) and the json_envelope extractor when the checkpoint behind a value matters, as with Transformers' load_best_model_at_end; the same call can write report-only values with extra=. A top-level observe: list records such values per trial without ranking on them, for example a held-out test score, and metric.min / metric.max keep a collapsed run from winning. When the metric moves with the seed, spend trials on more distinct values and read the trend across neighbors; repeats ranks by a mean over seeds when you compare a few discrete finalists. Noisy objectives and small budgets covers these together, and objective evidence defines the extractors, bounds and observe.
Connect an agent
The optional MCP server connects an AI agent to experiments you have approved without exposing config or storage paths, trainer commands, environment values, or raw logs. Sampled winner values follow the catalog's visible_params policy. Follow the MCP setup to install the extra, review the catalog authority boundary, configure a client-owned connection, and verify the result; phasesweep mcp call runs one tool from a shell without a client.
Reference
- Configuration guide: Experiment YAML, search spaces, inheritance, noisy objectives and small budgets, repeats, gates, and objective extractors.
- Configuration reference: per-key types, defaults, valid values, interactions, and lifecycle warnings. Too long to read whole;
phasesweep explainlists the top-level keys andphasesweep explain 'phases[].sampler'prints one key and everything below it. - Minimal starting configuration: one local toy-trainer attempt; validate or run it from the checkout root.
- Runtime behavior: filesystem layout, locks, GPU leases, process supervision, fingerprints, and resume.
- MCP setup: installed-package agent onboarding and client-owned setup.
- MCP operator reference: catalog fields, tools, authorization, run state, and recovery.
- Toy experiment and MCP catalog: a checkout-local CLI example backed by the packaged fake trainer, plus an MCP catalog whose detached-run state and experiment outputs use absolute scratch paths under
/tmp. - Tiny Decoder Enwik8 example: real-trainer integration.
- Durability invariants: the ordering rules the ledger, publication, and recovery paths must hold, and the test that owns each one.
- Development: source checkout, contributor setup, and quality gates.

License
MIT. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for phasesweep 0.3.8
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| phasesweep-0.3.8.tar.gz | 2.6 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| phasesweep-0.3.8-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 3.2 MB
Release files / phasesweep-0.3.8.tar.gz
| Download URL | phasesweep-0.3.8.tar.gz |
|---|---|
| Size | 2.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b131db751a49ee44026966bb27ff61aabcd0fde3cfcefd2d84a93fde3b5df354
|
|
BLAKE2b-256 checksum How to use checksums |
214f4e3a638920a64ae610e8ba1b53e7a80a2f690829547bbcf0c3f89cbaa6f3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency logRelease files / phasesweep-0.3.8-py3-none-any.whl
| Download URL | phasesweep-0.3.8-py3-none-any.whl |
|---|---|
| Size | 590.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2228d3f9b409a0fed0c2c55cde58ab3c94e7da230085714a86ed468eb670f13e
|
|
BLAKE2b-256 checksum How to use checksums |
af440ed90edc9e96db434816064af5defd2a00af99942e5df9dff647fb7c2fbb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency log













