
ppgrid - Pull-Push Scattered-Data Interpolation


Fast, continent-scale raster interpolation for scattered point data. Turns tens of millions of geolocated points into a pair of GeoTIFFs in minutes on a single machine. No GPU needed.
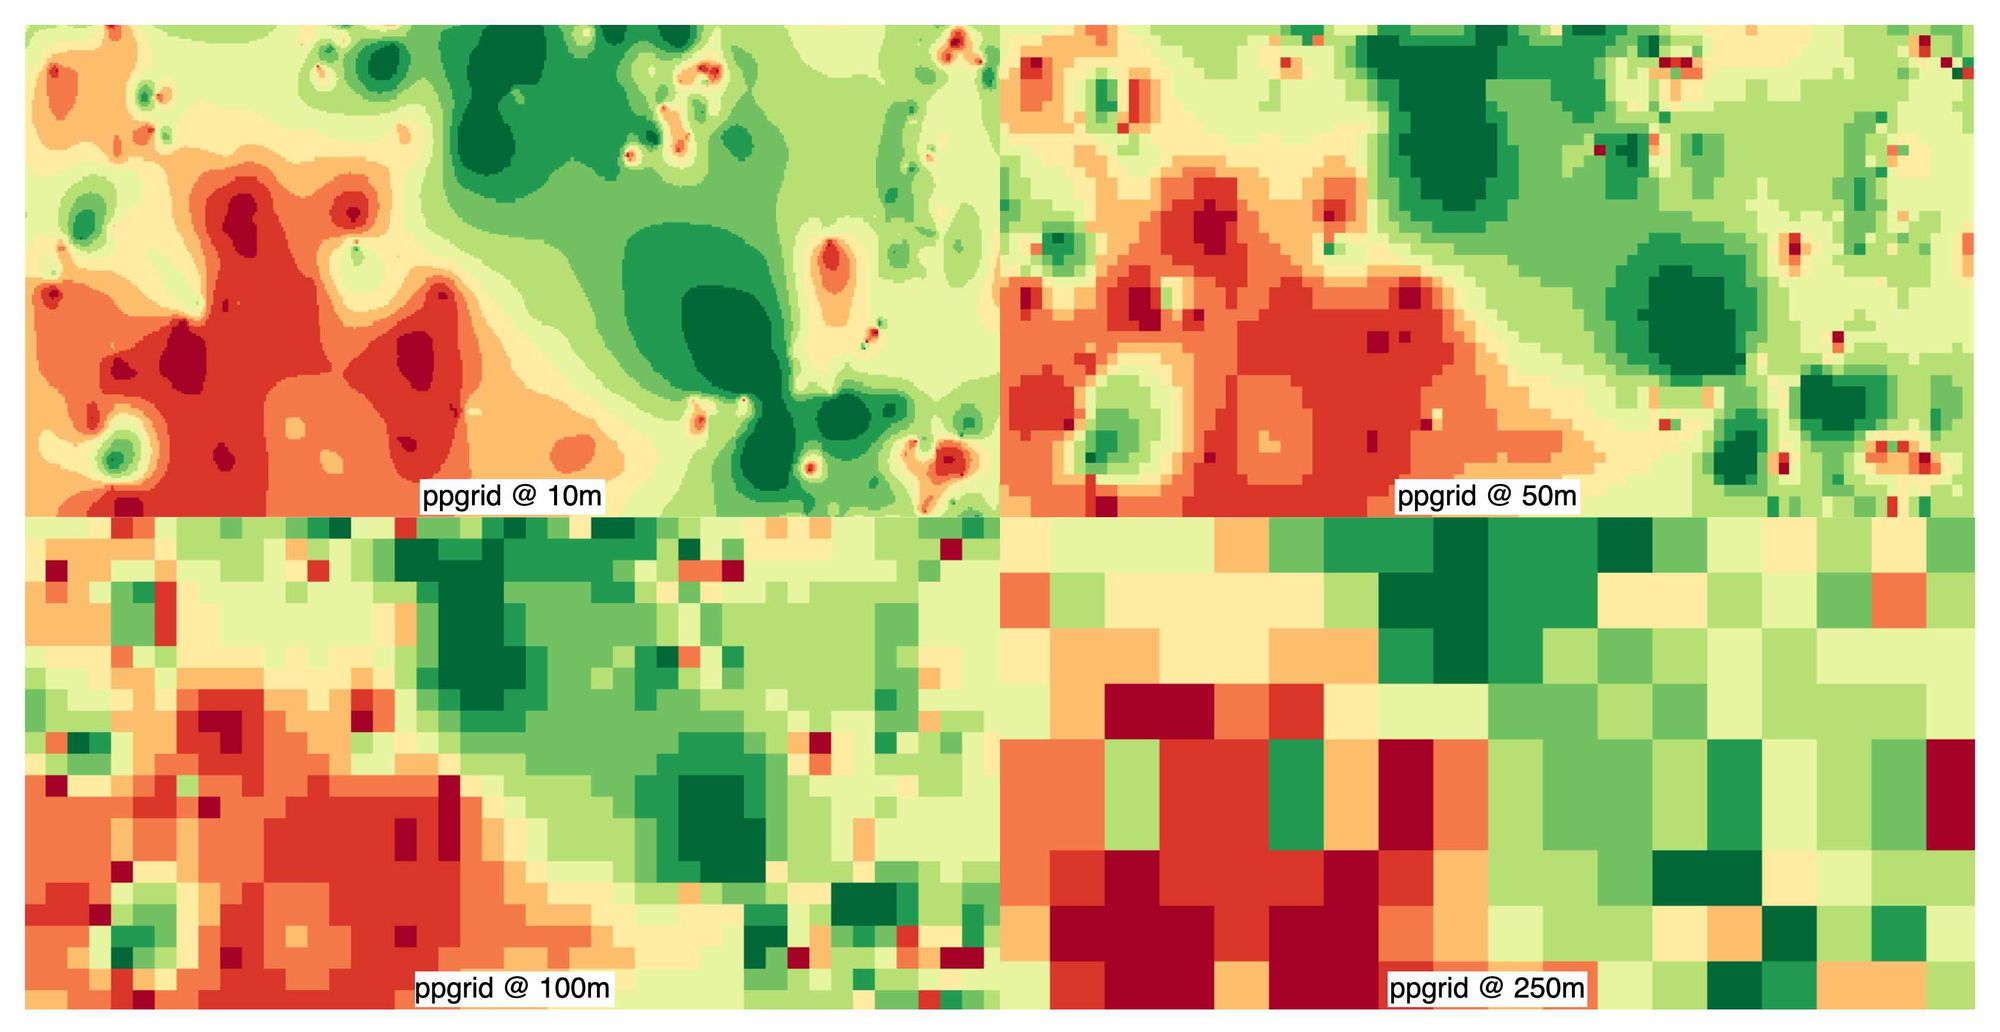
A single 100K-point dataset rendered at four resolutions. The adaptive mipmap pyramid fills sparse regions from coarser layers, so you get a continuous surface instead of patchy gaps.
What it does
You have N points with (longitude, latitude, value). You want a raster where every cell within a specified distance of real data carries an interpolated value, and everything else is nodata.
Standard IDW in QGIS or ArcGIS is O(N*M) (hours to days at 16M points, depending on the IDW implementation and machine). This tool uses pull-push mipmap interpolation to reduce cost to O(M), independent of N.
Known limitations
Two behaviours are by design, not bugs. Each carries a one-line workaround.
- IDW approximation, not a spatially exact interpolator. Pull-push
evaluates the IDW kernel fast (
O(M), independent of point count) and trades a small amount of accuracy for that speed: output is for visualisation, not downstream calculation. Workaround: when values feed further computation, run a spatially exact IDW (e.g.gdal_grid) on the same points and keep ppgrid for the map. --ram-gb/--max-ramcap the shared-field budget, not process RSS. Write and descent buffers sit outside the budget, so a budgeted run can peak well above the cap (measured: 39.4 GB RSS under a 20 GB cap). Only the per-box path is genuinely low-RAM (measured 8.5 GB peak). Workaround: check the planned path with--planfirst; a small enough cap lands the run on the per-box path, and--turbo-strictfails fast (exit 3) when the budget is infeasible instead of OOMing mid-run.
How it works
Pull-Push (mipmap) Interpolation
Based on Gortler et al. 1996 (Lumigraph) and Kraus 2009.
Once points are snapped to a grid, IDW is exactly a normalised convolution:
z = (S ⊛ K) / (C ⊛ K) K(r) = r^-p
Pull-push evaluates this across a mipmap pyramid so cost is O(M), independent of N.
Steps:
- Points are binned into
S(sum of transformed values) andC(count) grids - A mipmap pyramid is built by repeated 2x2 block sums
- The coarsest level seeds the interpolation
- Descending the pyramid, each level blends local estimate vs upsampled parent
- Local confidence is
min(C/saturation, 1). Dense cells trust themselves, sparse cells inherit - A summed-area table (
box_count) provides an exact radius fill cap
Output bands:
- Value: int16, 0-100 percentile,
percentile = DN/scale - Support km: int16,
support_km = 2^(DN/8), effective spatial scale of estimate
Working CRS: EPSG:6933 (Wagner VII) by default. Global equal-area, metres are true. Configurable via --work-crs.
Output CRS: EPSG:3857 (Web Mercator) by default. Configurable via --out-crs.
Calibration (optional)
Before interpolation, the tool can:
- Choose a transform. Tests identity/log10/sqrt/percentile and picks the one with highest intraclass correlation across coarse scales
- Derive a fill cap. Spatially blocked cross-validation to find the honest distance beyond which interpolation has no skill
- Save calibration.json. Contains the percentile-to-value lookup table for decoding the output raster back to real units
Install
Requires Python 3.11-3.14 (older interpreters fail the pip resolver with a bare error; see Support below).
pip install ppgrid
For Parquet support:
pip install ppgrid[parquet]
Or from source:
git clone https://github.com/marzukia/ppgrid.git
cd ppgrid
uv sync
Support
Python 3.11-3.14. All four interpreters are tested in CI on every PR; outside that range no fixes are targeted.
Operating systems:
- Linux — supported, CI-covered (ubuntu-latest: full test matrix + anchor gate).
- macOS — supported, CI-covered (macos-latest: full test matrix including
--turbo+ anchor gate, arm64). - Windows — unsupported. Not in the CI matrix; no fixes targeted at it.
The full scope — what "CI-covered" means, per-OS notes, the Windows re-enable plan — and the feedback path (issues, discussions, email) live in SUPPORT.md.
Quick Start
ppgrid data.csv --value-col price --res 500 --cap-km 10 --skip-calibration
This reads data.csv, interpolates the price column at 500m resolution with a 10km fill cap, and writes value.tif + support_km.tif to out/.
Usage
# Quick run (skip calibration)
ppgrid data.csv --value-col premium --res 500 --cap-km 64 --skip-calibration

# Full run with calibration (saves calibration.json)
ppgrid data.csv --value-col premium --res 100 --cap-km auto

# Custom projection and params
ppgrid data.csv --value-col premium --res 100 --cap-km 25 --transform log10 --workers 8

# Reuse existing calibration
ppgrid data.csv --value-col premium --calibration calibration.json

# Round output percentiles to a step (e.g. 5 -> 90/95/100) for clean vectorisation
ppgrid data.csv --value-col premium --res 100 --cap-km 25 --percentile-step 5

# Write a commented config template (safe defaults; edit values to override)
ppgrid init

# Print help with examples (also: --help)
ppgrid help
CLI Options
The table mirrors the run CLI; ppgrid --help (and ppgrid help) is the
source of truth — update this table when the parser changes.
| Flag | Default | Description |
|---|---|---|
input |
— | CSV or Parquet input path (bare ppgrid exits 2 with a hint; ppgrid help prints usage) |
-o, --out |
out/ |
Output directory |
--value-col |
value |
Value column name |
--lng-col |
longitude |
Longitude column name |
--lat-col |
latitude |
Latitude column name |
--res |
500.0 |
Cell size in metres |
--cap-km |
auto |
Fill cap km, or 'auto' (blocked-CV derived) |
--transform |
auto |
auto, identity, log10, sqrt, percentile |
--saturation |
1.0 |
Counts for a cell to fully self-trust |
--block |
2048 |
Block size in cells |
--workers |
4 |
Number of parallel workers (positive integer, or auto = os.cpu_count()) |
--max-band-parallel |
--workers |
Cap parallel row-band workers for the low-RAM shared descent |
--scale |
100.0 |
DN = percentile * scale |
--percentile-step |
(none) | Round output percentiles to the nearest step (e.g. 5 -> 90/95/100) |
--compress |
ZSTD |
GeoTIFF tile compression (NONE, ZSTD, LZW, DEFLATE, PACKBITS, LERC, LZMA; unknown values exit 2) |
--calibration |
(none) | Path to existing calibration.json |
--calib-max-points |
2000000 |
Max points to use for calibration |
--src-crs |
4326 |
Input CRS (bare int or EPSG:<code> string) |
--work-crs |
6933 |
Working CRS for interpolation (equal-area; bare int or EPSG:<code>) |
--out-crs |
3857 |
Output CRS for final GeoTIFF (bare int or EPSG:<code>) |
--skip-calibration |
False | Skip calibration, use defaults |
--seed |
0 |
RNG seed for the calibration subsampling + blocked-CV bootstrap (same seed + same input → reproducible outputs) |
--turbo |
(none) | Turbo mode: multithreaded pipeline sized to a RAM cap. Optional preset `16 |
--max-ram |
(none) | Explicit RAM cap in GB (overrides the --turbo preset). Implies --turbo |
--ram-gb |
(none) | Alias of --max-ram |
--turbo-strict |
False | Shared path infeasible under the budget: error + exit 3 instead of [warn] + per-box fallback (exit 0) |
--plan |
False | Resolve the full run plan (grid, levels, transform, turbo decision, budget), print it, exit 0 — creates no files or directories |
--check |
False | After writing, reopen the outputs and verify them against the run plan (files, band readability, shape, transform, CRS, nodata tag, tiles, out-of-coverage corners); on mismatch log the exact field, keep the outputs, and exit 1 |
--force |
False | Overwrite existing outputs in the out dir (default: exit 2 when value.tif / support_km.tif / calibration.json / run_summary.json are present) |
--json |
False | Write a machine-readable run summary to <out>/run_summary.json (phase timings, volumetrics, grid metadata, calibration, resolved CLI params, seed, git commit; stdout stays clean) |
--verbose |
False | Debug logging: per-phase wall times + volumetric detail (shorthand for --log-level debug) |
--log-level |
info |
Progress log level on stderr: error, warning, info, debug (env LOGGING; verbose = debug) |
--log-file |
(none) | Also write the run log to this file: created fresh each run, level info, same format as stderr (no color); stderr output is unchanged |
--max-band-parallel |
(none) | Cap parallel row-band workers for the low-RAM shared descent (default: --workers) |
-q, --quiet |
False | Suppress stderr below WARNING (beats --verbose / LOGGING; an explicit --log-level wins) |
--color |
(none) = auto | Color output: auto (TTY, no NO_COLOR/TERM=dumb), always, never (live progress also needs a TTY stderr and no --quiet) |
--config |
(none) = discover | Pipeline options file, TOML. Discover ./ppgrid.toml, then ~/.config/ppgrid/ppgrid.toml; ppgrid init writes a commented template; precedence: CLI flag > config > built-in default |
Config file (ppgrid.toml)
Pipeline options can live in a TOML file instead of the command line. Precedence: CLI flag > config > built-in default — a config value only fills an option you did not pass on the command line.
Discovery order:
--config PATH(explicit; a missing file is a usage error, exit 2)./ppgrid.toml(current directory)~/.config/ppgrid/ppgrid.toml(user default)
No file present is a silent no-op. ppgrid init [DIR] writes a fully
commented template covering every pipeline option, each set to its built-in
default — the file as written changes nothing about a run. It refuses to
clobber an existing file without --force. Dispatch is on the literal first
token: a data file named init in the current directory becomes the
subcommand — run it as ppgrid ./init (any path form works).
Unknown keys (including TOML table headers) warn and are ignored; a value
the flag's own checker rejects (wrong type, out of range, unknown preset)
is a usage error, exit 2. --ram-gb is CLI-only (the config key is
max-ram); --plan and the logging/presentation flags are not config-able.
# ppgrid.toml — example overrides
res = 10000
transform = "log10"
workers = 8
Run fingerprint (ppgrid_run.json)
Every successful run writes <out>/ppgrid_run.json: the effective
parameters (after the flag > config > default merge), the config file used
(or null), the input file name, tool versions (ppgrid, python, numpy,
rasterio, gdal, pyproj), an ISO-8601 UTC timestamp, and a fingerprint —
the sha256 of the canonical (sorted-keys) parameter JSON. The timestamp is
never part of the fingerprint, so two runs with identical effective
parameters share one fingerprint; change any parameter and it changes.
The sidecar is metadata only: it does not block re-runs (the overwrite
guard watches the rasters and run_summary.json).
Subcommands
Subcommands share the CLI. All but init are read-only — they write no
output files (doctor's oracle probe uses one throwaway tile under the temp
dir; init writes the ppgrid.toml template) — and completions runs
without loading the native stack (as cheap as --help). Dispatch is on the
literal first token: a data file named compare, completions, doctor,
init, list-crs, or probe in the current directory becomes the
subcommand — run it as ppgrid ./compare (any path form works). Run
ppgrid <subcommand> --help for detail.
| Command | Exit codes | Description |
|---|---|---|
compare OUT1 OUT2 |
0 identical / 1 different / 2 usage |
Compare two ppgrid outputs — two output dirs (value + support bands) or two GeoTIFFs. Reports per-band shape, transform, CRS, exact-match count, max absolute DN difference, and a mismatch bbox. --max-diff N tolerates max absolute DN differences up to N (exit 0 within it). The report goes to stdout; usage errors (missing path, mixed dir/file, negative --max-diff) go to stderr with exit 2 |
completions bash|zsh |
0 ok / 2 usage |
Print shell completions generated from the live parser (flags, positionals, subcommands, sorted and deterministic). Install: eval "$(ppgrid completions bash)" (bash) or source the zsh script from a $(...) capture. No dependencies |
doctor |
0 all pass / 1 failing checks named |
Stack health: python/ppgrid/numpy/rasterio/GDAL/pyproj versions, the zstd turbo oracle status (which turbo write path this stack takes), the C interp kernel, RAM (physical + cgroup ceiling), temp dir. A warn — e.g. the zstd oracle mismatch or the np.interp fallback — is a byte-identical path and does not fail |
init [DIR] |
0 written / 1 IO / 2 existing file without --force |
Write a fully commented ppgrid.toml template covering every pipeline option, each set to its built-in default (the file as written changes nothing about a run). Stdlib-only (no native stack, like --help); creates DIR with parents. Refuses to clobber an existing file without --force |
list-crs |
0 ok / 1 error |
CRS codes: the curated ppgrid set by default (4326/3577/6933/3857 + UTM examples), the full pyproj/EPSG database with --all |
probe INPUT |
0 clean / 1 problem(s) found / 2 unknown --work-crs code |
Input diagnostic: format (incl. compressed-CSV magic), columns, streamed row count, numeric --value-col candidates, a CRS guess, then the SAME projection validation a real run does (non-finite / out-of-domain / non-finite-projection drops, kept-point domain) for --work-crs (e.g. ppgrid probe data/in.csv --work-crs 6933 --value-col price) |
Exit codes
0— success (alsoppgrid help,--plan, and the subcommands' clean runs)1— pipeline / I/O error (bad output path, missing input file, disk full)2— validation error (bad flag value, missing input column, out dir not empty without--force)3—--turbo-strict: shared path infeasible under the RAM budget
Environment variables
PPGRID_FORCE_MEMMAP=1— force the tmpfs memmap shared-grid regime even on small grids (normally auto-selected past 1e8 cells). A development/testing switch: it changes the memory regime only — the output is bit-identical to the in-RAM pass.
Turbo mode
--turbo enables the multithreaded pipeline. The RAM cap C (a preset, --max-ram, or bare --turbo auto-detect) drives a planning budget Bt = 0.85 * C - 4 GB and a regime, printed by a pre-check after gridding. None of the turbo settings change the output bytes.
Units and presets. GB values are decimal (1e9 bytes). Presets 16|32|64|128 are common box sizes; use --max-ram GB for any value. A preset at or above the process-visible RAM (min(physical, cgroup)) clamps to visible - 8 GB, and the clamp prints its cause, e.g. preset 128 GB >= detected 96.0 GB; using 88.0 GB (96.0 - 8.0 GB headroom).
- A — full in-RAM shared fields. Fastest; needs the most RAM.
- B — input in RAM, output bands file-backed with a limited number of descent bands in flight.
- C — shared all-memmap banded descent: input and output bands file-backed (reclaimable memmap), with an 8 GB page-cache floor in its peak accounting.
- per_box — per-box warp/write fallback, taken when regime C has fewer than 2 in-flight units. This is the only genuine low-RAM mode.
When the shared path is infeasible under the budget, the run prints [warn] and continues on the per-box path (exit 0, correct output). --turbo-strict makes the infeasibility an error (exit 3).
--ram-gb caps the shared-field budget, not process RSS. Write/descent buffers sit outside the Bt sizing, so a regime C run under --ram-gb 20 can peak well above 20 GB RSS (measured: 39.4 GB). Only the per-box path is genuinely low-RAM (measured: 8.5 GB peak).
Byte identity. Turbo output is sha256-identical to the serial path. The optional parallel per-tile ZSTD write is gated by a compression oracle: where the oracle mismatches (e.g. the reference GDAL 3.12.4 / libtiff 6.2 stack), the run uses the stock-codec parallel writer instead, which is byte-exact; the serial per-band write is the last resort only, reached if that writer's layout guards fail.
Decoding the output
The value band stores percentiles, not raw values. To convert back to real units, use the calibration.json saved in the output folder:
import json, numpy as np, rasterio

with open("calibration.json") as f:
    quantiles = np.array(json.load(f)["percentile_quantiles"])

with rasterio.open("value.tif") as r:
    # The value band carries its own scale tag (DN * scale = percentile), so a
    # non-default --scale (e.g. 10) decodes correctly. rasterio reports (1.0,)
    # when the tag is absent, so a legacy untagged raster decodes 100x high and
    # np.interp clips it; re-run the pipeline for tagged output.
    scale = r.scales[0] if r.scales else 0.01
    percentiles = np.array(r.read(1), copy=True) * scale

real_values = np.interp(percentiles, np.linspace(0, 100, len(quantiles)), quantiles)
Benchmarks
Head-to-head on a 100K-point synthetic dataset (M4 MacBook Pro, 24GB) against the traditional GDAL path:
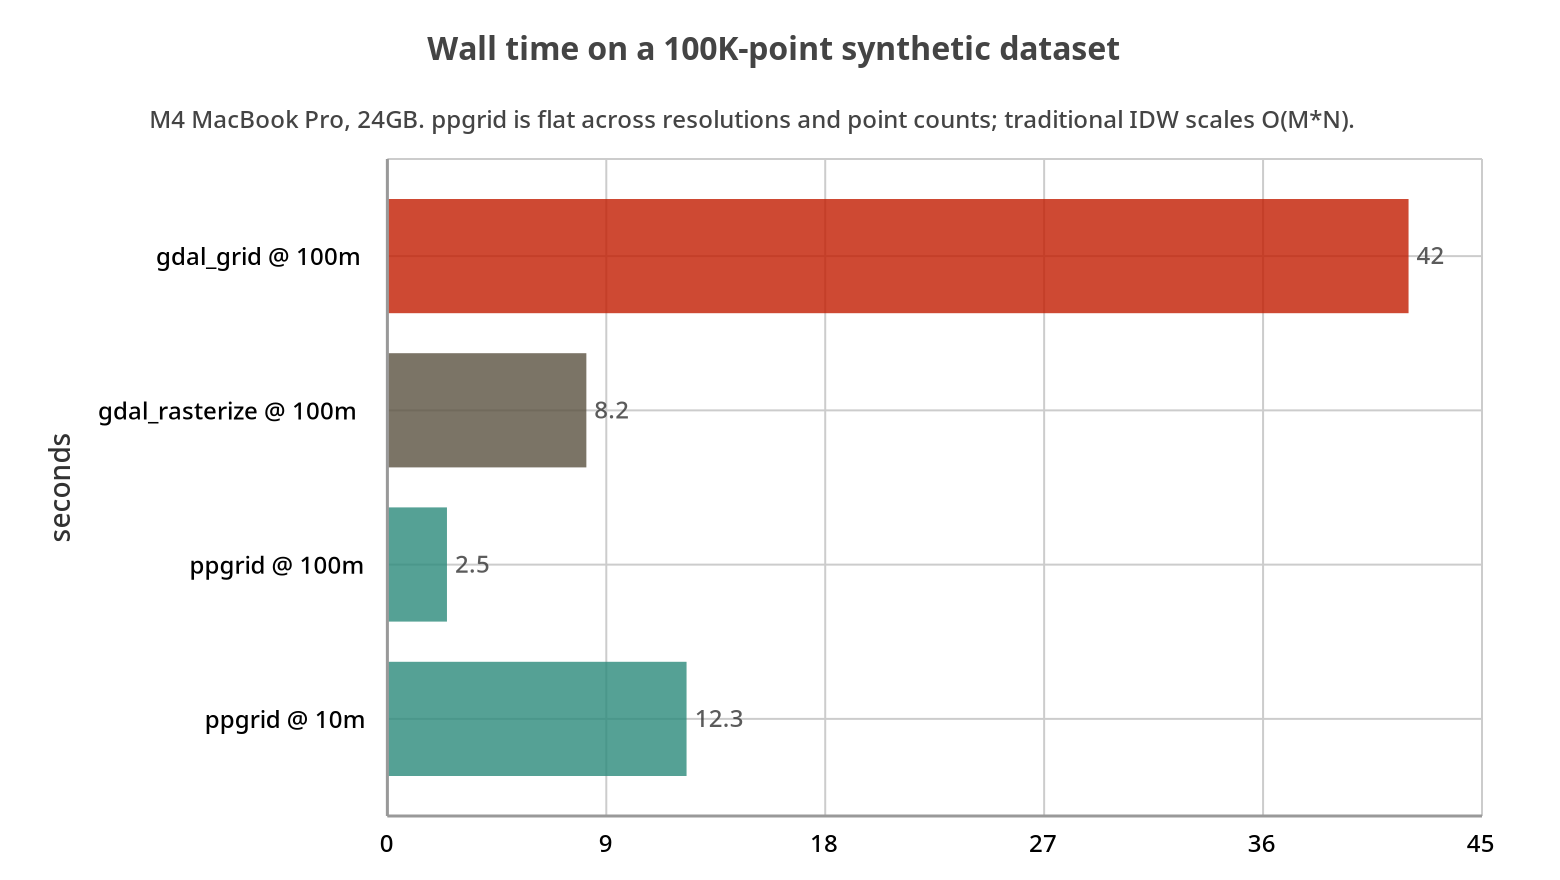
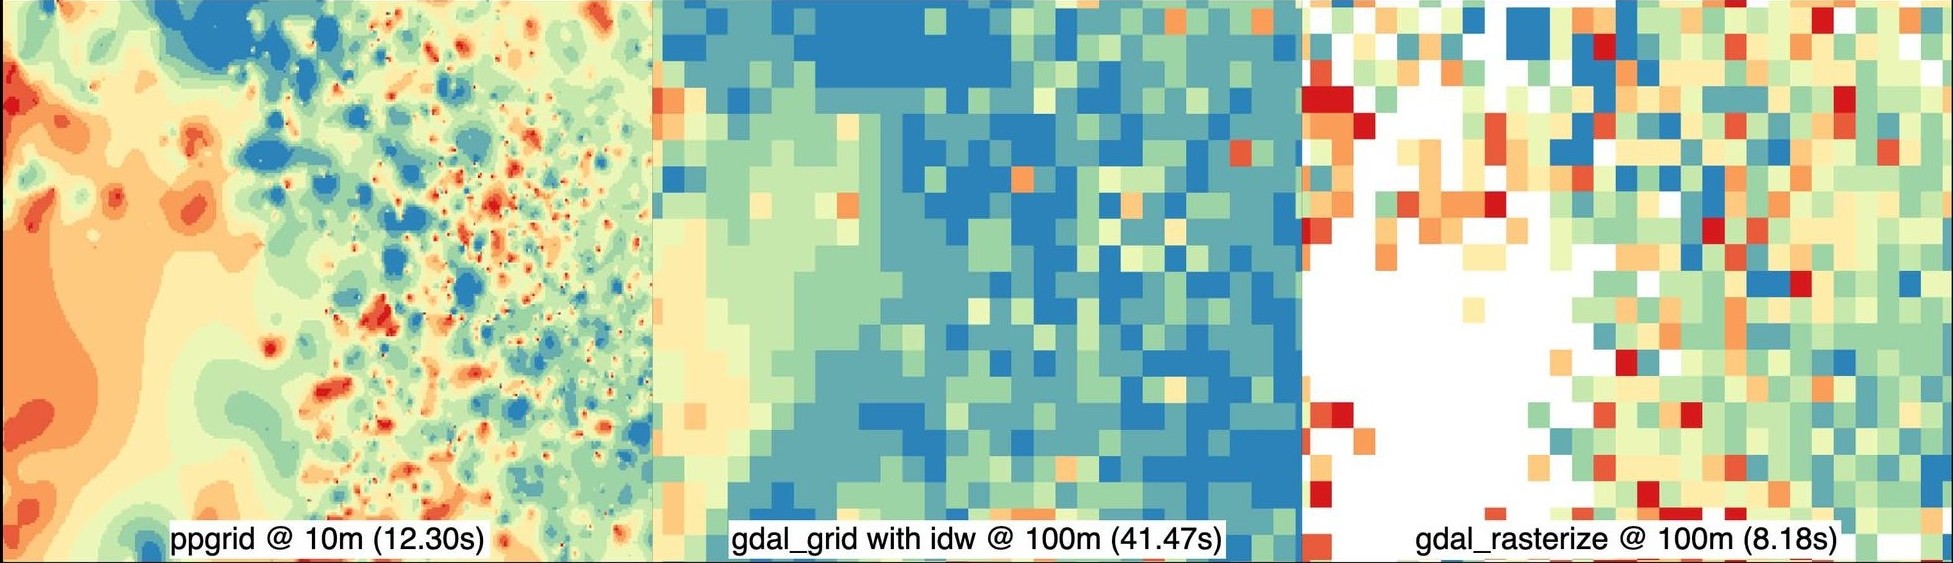
ppgrid at 100m is ~17x faster than gdal_grid and ~3x faster than gdal_rasterize at the same resolution, and it can run 10x finer (10m) in under 13 seconds.
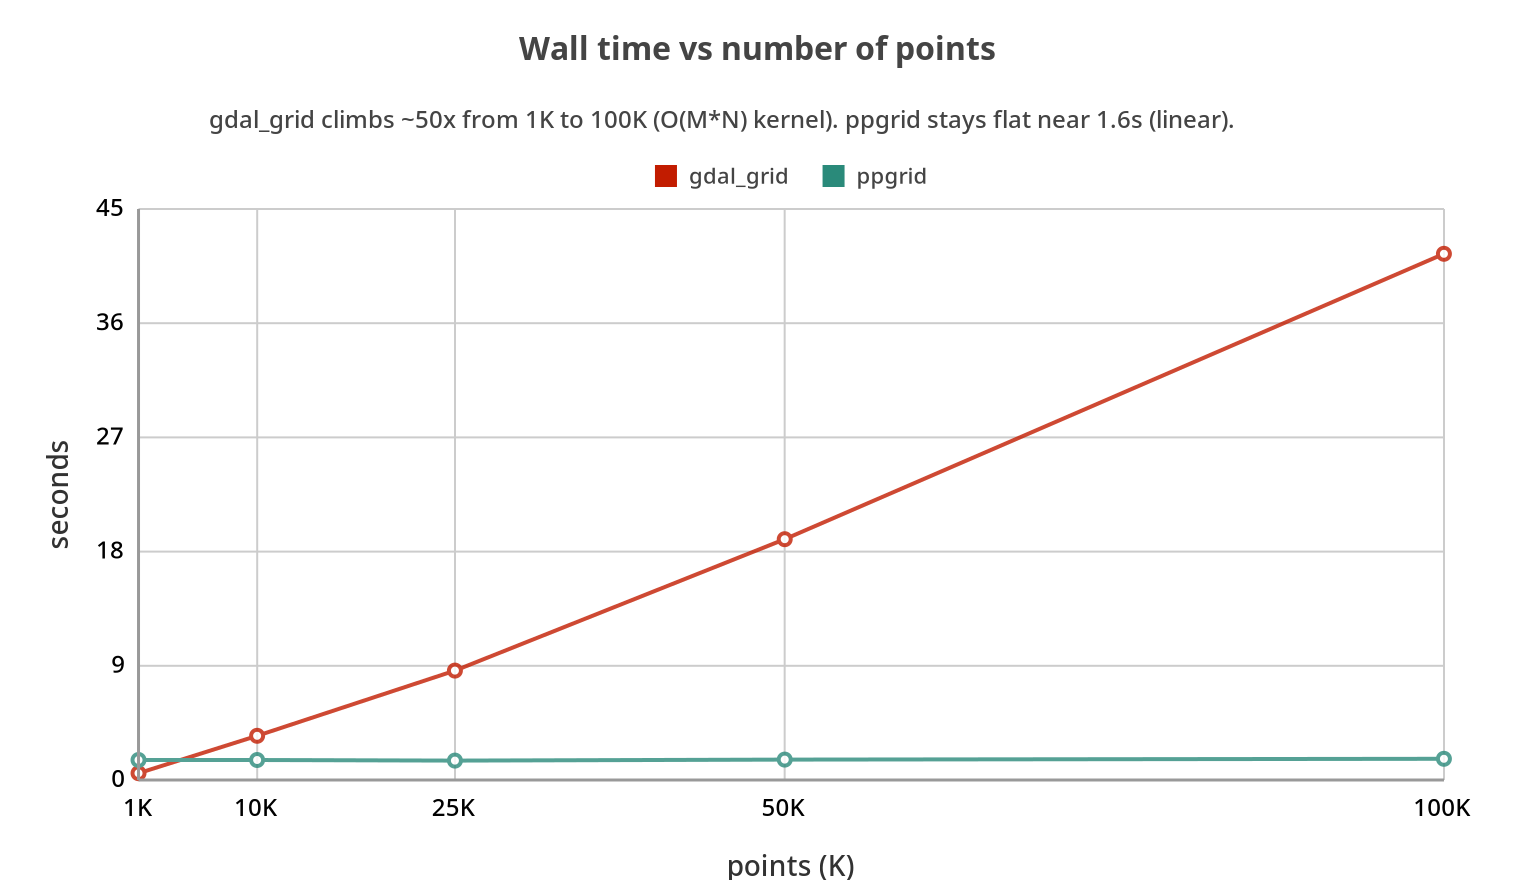
The reason is the scaling behaviour. As the point count grows, gdal_grid climbs ~50x from 1K to 100K points (the O(M*N) kernel), while ppgrid stays flat near 1.6s because each point is binned once and the rest is linear over raster cells:
Resolution sweep
Melbourne Housing dataset (13,580 points) at various resolutions on the same machine:
| Resolution | Wall Time | File Size |
|---|---|---|
| 10m | 26.6s | 27.3 MB |
| 25m | 4.0s | 6.8 MB |
| 50m | 1.3s | 2.3 MB |
| 100m | 0.8s | 749 KB |
| 250m | 0.6s | 159 KB |
| 500m | 0.6s | 49 KB |
Turbo benchmarks (full AU)
Full-Australia grid, 16M points, --res 100 --cap-km 25 --skip-calibration, on marzuki-hydrogen (Threadripper 24C/48T, 125 GB, CPU-only). All outputs sha256-identical across the pre- and post-turbo-code runs.
| Mode | Wall | Peak RSS |
|---|---|---|
Pre-PR turbo code, regime A (--turbo 64, same code) |
30:45 (quiet) to 50:46 (loaded) | 41.7 GB |
Regime A (--turbo 64) |
2:33 | 43 GB |
| per-box (24 GB cgroup slice) | 3:20 | 8.5 GB |
Regime C (--ram-gb 20) |
6:25 pre-PR, 3:08 post | 39.4 GB |
The pre-PR regime-A wall varies 30:45-50:46 with machine load (two measured runs of the same code on the same box), so the speedup range is ~12-20x rather than a single ratio. Note the --ram-gb 20 row: the cap bounds the shared-field budget, not RSS — see the caveat above; per-box is the only genuinely low-RAM mode.
Example Outputs
ppgrid against gdal_grid + IDW and gdal_rasterize on the same data. Left is ppgrid, middle is gdal_grid with IDW, right is gdal_rasterize:
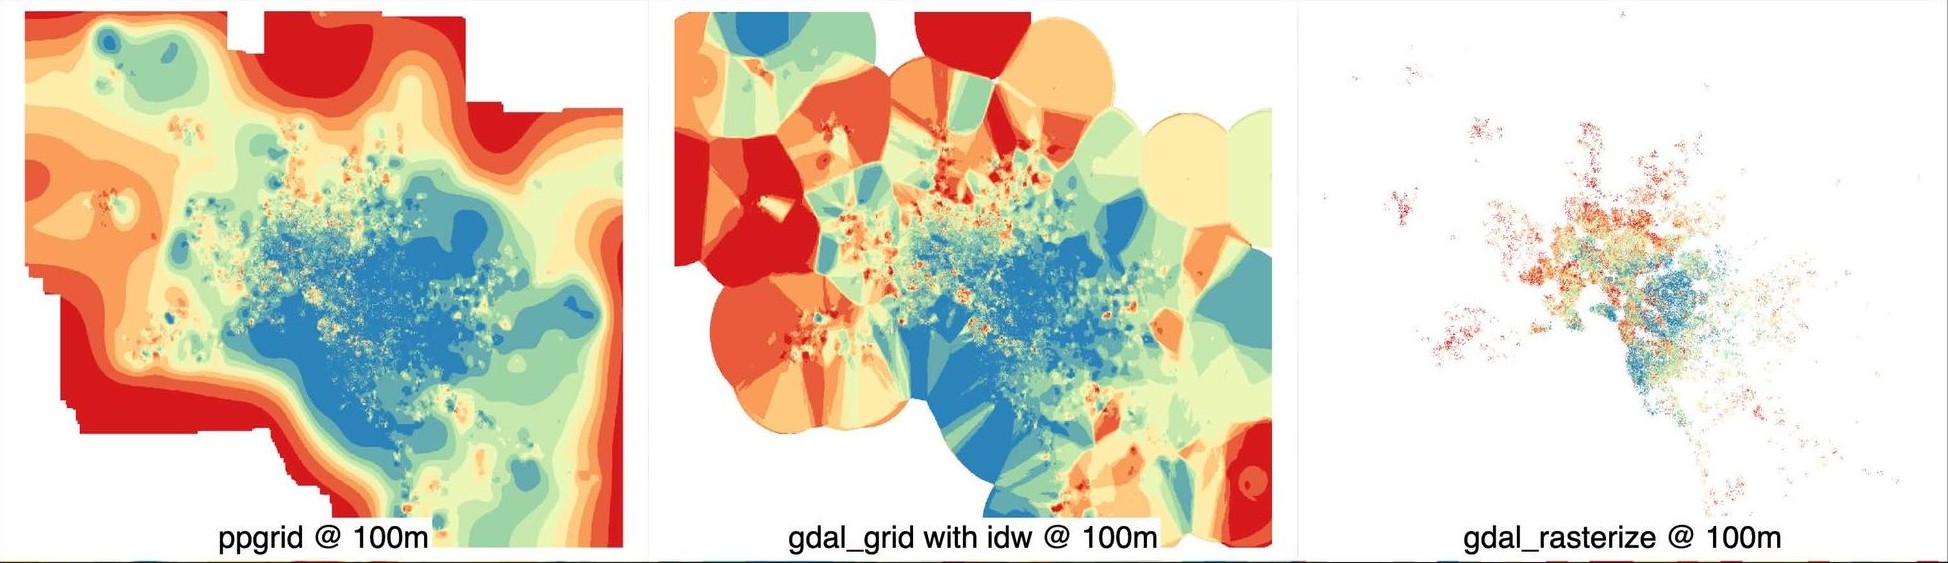
Zoomed in. ppgrid stays continuous where the grid-based methods produce Voronoi-style polygons and patchy gaps:
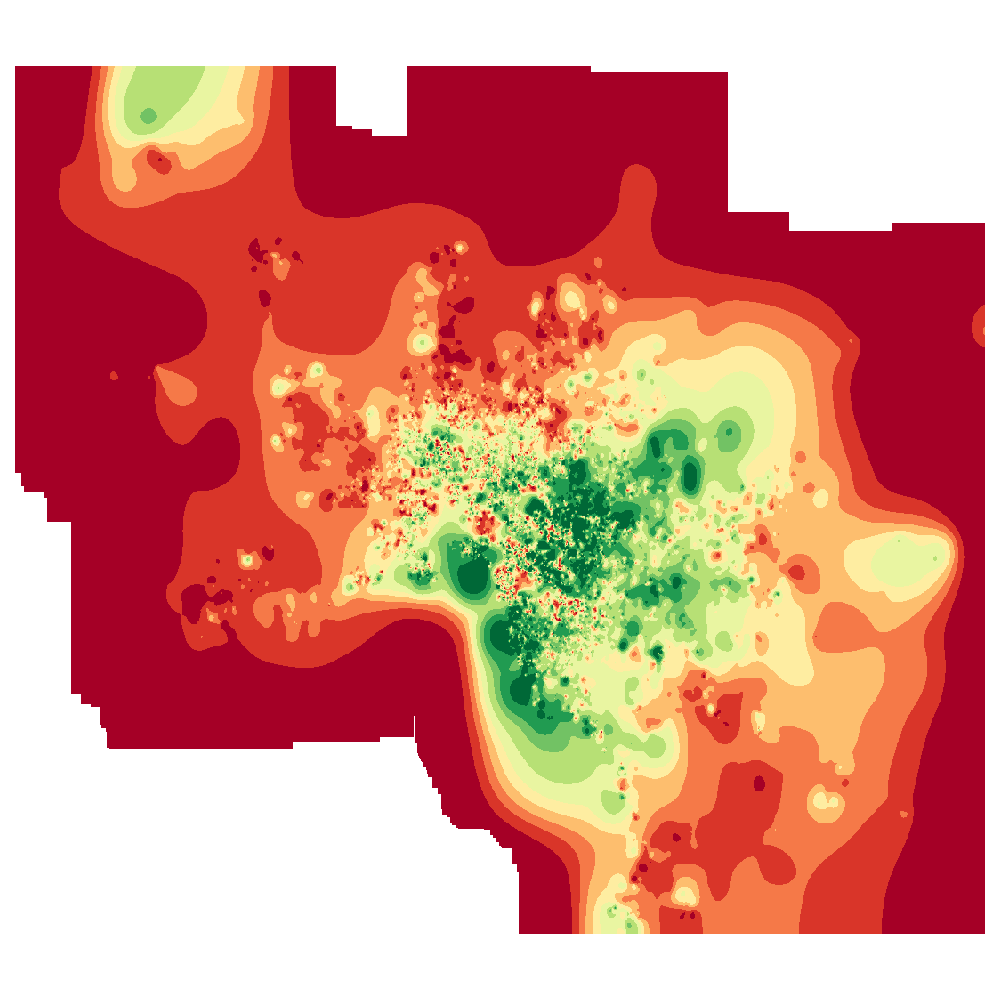
Melbourne Housing interpolated at 10m, full extent:
Data
data/melb_houses.csv: 13,580 Melbourne property sales with latitude, longitude, and price. Sourced from the Melbourne Housing Snapshot (CC BY-NC-SA 4.0).
data/all_equakes.csv: 44,376 earthquake events from Jan-Aug 2026, mag >= 1.5.
Data Lineage
| Step | Description |
|---|---|
| Source | USGS Earthquake Hazards Program |
| API | FDSN Event Web Service |
| Download | Batched CSV requests by month, minmagnitude=1.5, starttime=2026-01-01, endtime=2026-08-08 |
| Processing | Concatenated monthly CSVs (deduplicated header) into single file |
| License | Public Domain (USGS federal data) |
Columns Used
latitude/longitude: spatial coordinates (WGS 84)mag: earthquake magnitude (continuous, for interpolation)depth: focal depth in km (optional value layer)time: event timestamp (ISO 8601)
1 maintainer

Metadata
1 maintainer
Release files for ppgrid 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ppgrid-0.5.0.tar.gz | 581.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ppgrid-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 770.3 kB
Release files / ppgrid-0.5.0.tar.gz
| Download URL | ppgrid-0.5.0.tar.gz |
|---|---|
| Size | 581.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8abe20fb3953d4c6832d408a47f6f954cd7788ea38d5c0eaa63c519b44cf9cf7
|
|
BLAKE2b-256 checksum How to use checksums |
cef60080195feed66e55facd8de5ae291a1091ff06178f1ac2ee58c5e792d11e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.1 {"installer":{"name":"uv","version":"0.13.1","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / ppgrid-0.5.0-py3-none-any.whl
| Download URL | ppgrid-0.5.0-py3-none-any.whl |
|---|---|
| Size | 189.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
de9aec7440928235d7b9bef9724b12c5da823d1e0863e89092cca90d434e394c
|
|
BLAKE2b-256 checksum How to use checksums |
372a4b1fed422e0978b7d4697b2bfab1d9dc2828ae4f24c848e633982a206f36
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.1 {"installer":{"name":"uv","version":"0.13.1","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|














