
predict-rlm
Many LLM workflows are too complex for one prompt and too adaptive for a fixed chain.
predict-rlm gives models a runtime for those workflows: inspect files, keep state, branch, call focused sub-models, use tools, manage large context through code, and return typed output.
You define the inputs, outputs, tools, and operating procedure. The model writes and executes Python in a sandboxed REPL, adapting as it discovers evidence.
Use it when you know the outcome you want, but not the exact path.
Based on the Recursive Language Models
paper by Alex L. Zhang,
Tim Kraska, and
Omar Khattab from MIT CSAIL.


crafted with ♥ in MTL · NYC · FLP
by Trampoline AI
When to use it
predict-rlm is a good fit when the model needs to explore, reason, and adapt before it can produce the final output:
- codebase analysis and investigations
- document review, redaction, extraction, and comparison
- log analysis and incident-style evidence gathering
- spreadsheet and financial-model workflows
- audits, compliance review, and messy data transformation
- multi-file synthesis with typed outputs and readable traces
It is probably not the right tool for simple chat completions, one-shot classification, deterministic ETL, or tiny prompts where a direct LLM call is already enough.
Installation
uv add predict-rlm
Optional extras are available for adjacent tooling:
# GEPA optimization support
uv add "predict-rlm[gepa]"

# Codex-backed DSPy LM and the `codex-lm` CLI
uv add "predict-rlm[codex-lm]"

# Docker Sandboxes backend support
uv add "predict-rlm[sbx]"
With the Codex LM extra installed, import CodexLM or use the script. The
vendored backend supports the GPT-5.6 family: gpt-5.6-sol, gpt-5.6-terra,
and gpt-5.6-luna.
from dspy_codex_lm import CodexLM
codex-lm auth list
codex-lm usage
Why RLMs?

- Avoid context rot — The outer LM works through files, variables, and tool calls instead of trying to keep every detail in one prompt. Large inputs stay as file paths and metadata until the runtime needs to inspect them.
- Adaptive execution inside a defined procedure — A signature gives the workflow a contract, while the REPL lets the model branch, retry, verify, and accumulate state across iterations.
- Focused sub-model calls —
predict()lets the runtime spin up typed DSPy signatures for narrow perception and extraction tasks, including multimodal calls withdspy.Image. - Readable trajectories — Every run records generated code, output, tool
calls,
predict()subcalls, timings, token usage, errors, and finalSUBMITpayloads, so you can inspect what happened instead of guessing. - Optimization-ready traces — The same traces that help humans debug a run can feed tools like GEPA to improve RLM strategies from scored examples.
Features

- Multimodal — process images and rendered document pages through sub-LM calls using native provider multimodal APIs.
- Async tool calling — native RLM async support in the WASM sandbox, enabling concurrent sub-LM invocations and tool calls.
- Skills & tools — bundle domain instructions, PyPI packages, sandbox modules, and host-side tools for reusable task capabilities.
- Simple file I/O — pass local files and mutable workspaces as typed inputs,
and return generated artifacts through
Fileoutputs. - Structured sub-LM calls — native Pydantic and DSPy signature support for type-safe sub-LM invocations with structured outputs.
Demos
| Description | Input / Output | Preview |
|---|---|---|
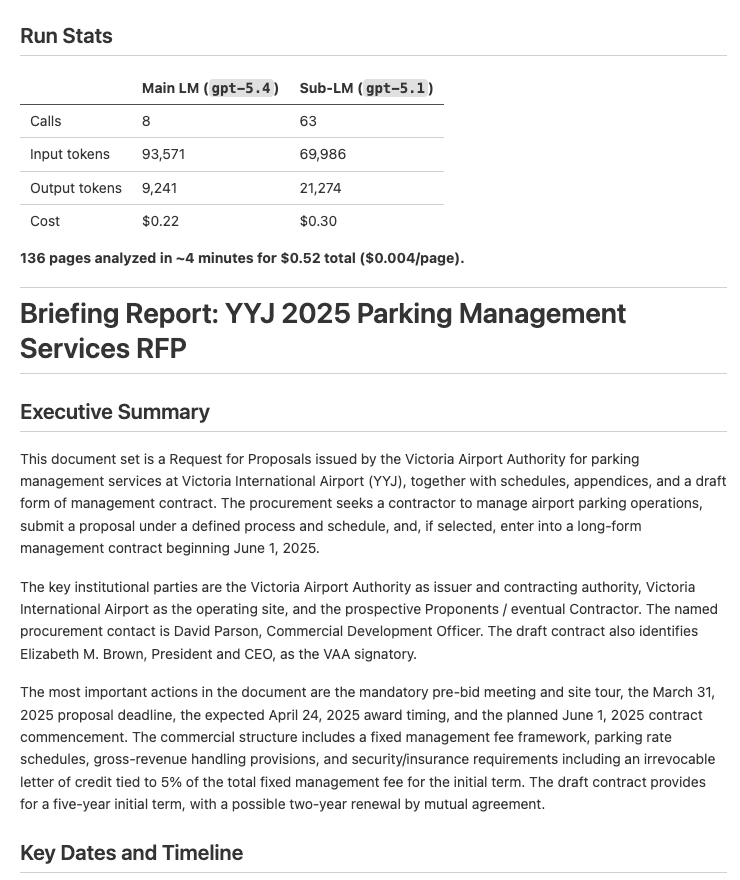
| Document Analysis — Analyze documents and extract key dates, entities, and financial information into a structured report | Input: PDFs Output: Structured briefing report (example output) |
 |
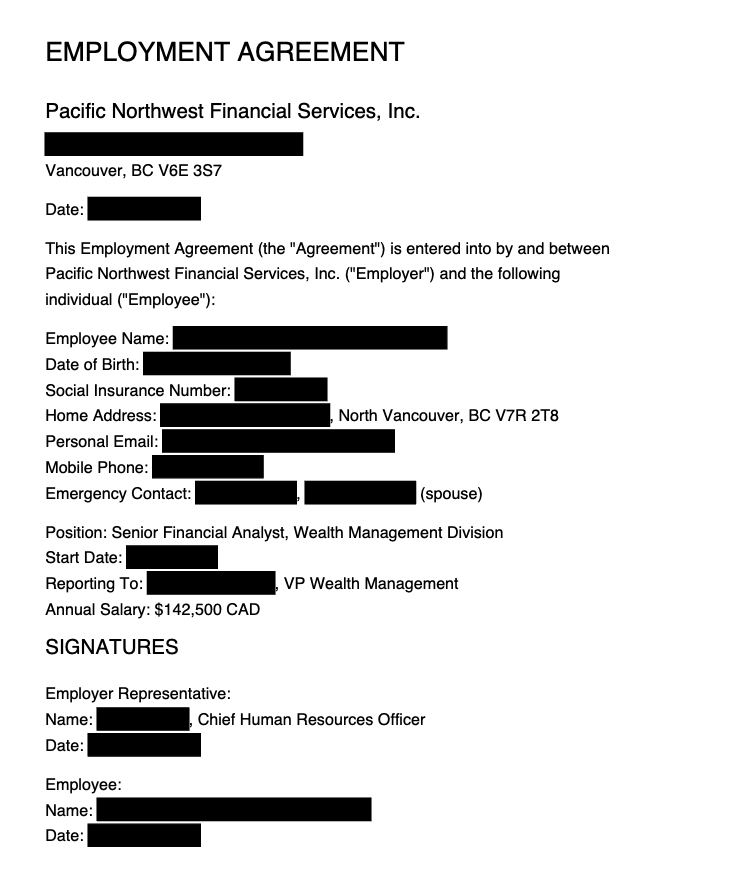
| Document Redaction — Redact PII from PDFs based on a policy, then verify the redactions visually | Input: PDFs Output: Redacted PDFs (example output) |
 |
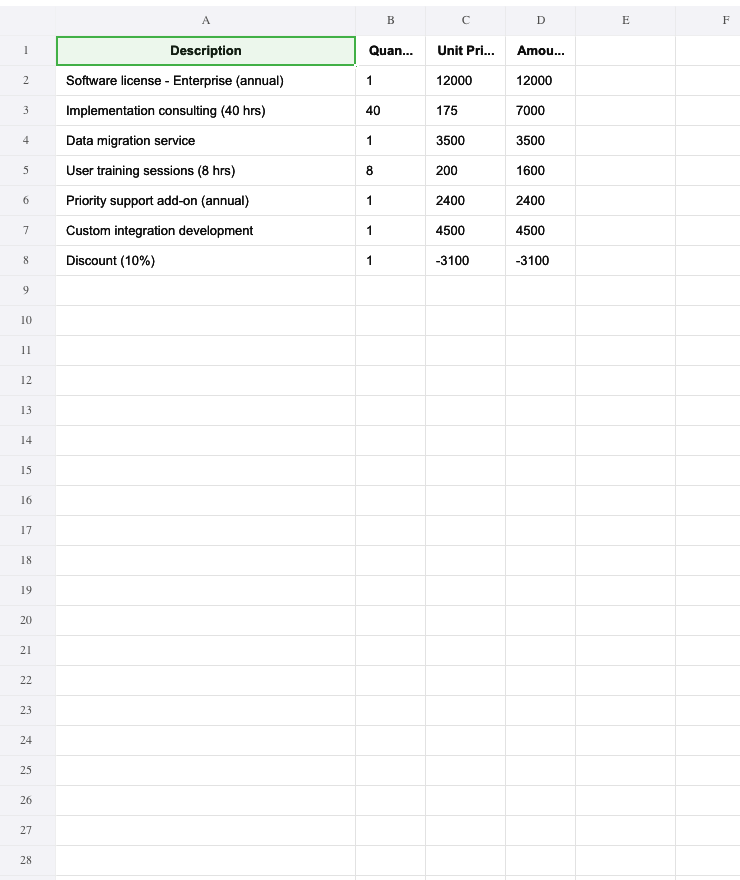
| Invoice Processing — Extract vendor info, line items, and totals from PDF invoices into a consolidated Excel spreadsheet | Input: PDF invoices Output: Excel spreadsheet (example output) |
 |
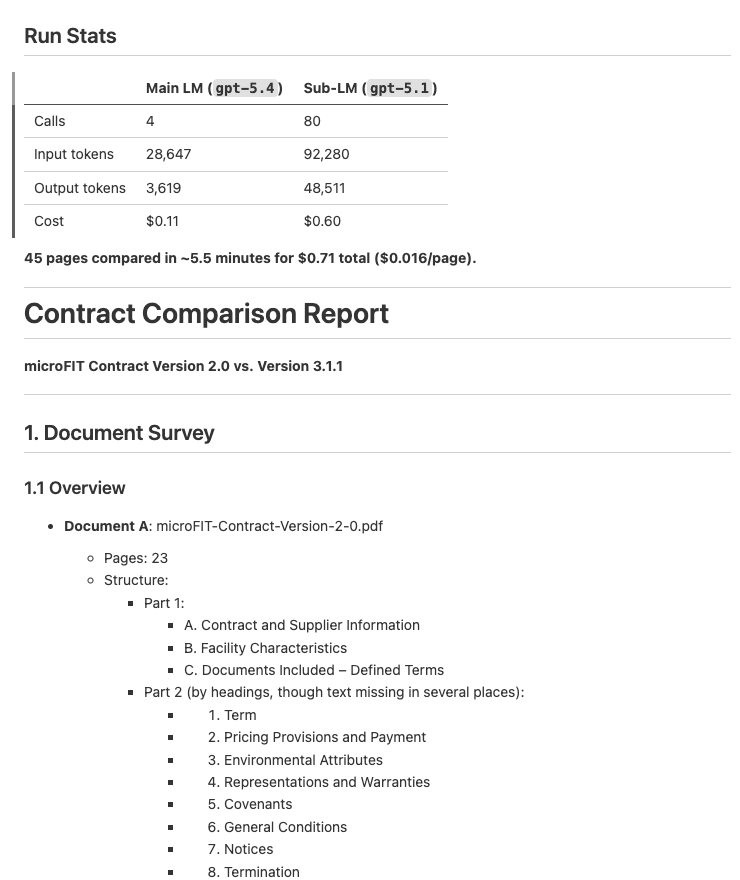
| Contract Comparison — Compare two contract versions and produce a structured diff report with per-section analysis | Input: 2 PDF contracts Output: Structured diff report (example output) |
 |
Quick start
With your coding agent
Install the predict-rlm skill in Claude Code, Codex, Cursor, or any compatible coding agent:
npx skills add Trampoline-AI/predict-rlm
Then ask your agent to build an RLM:
❯ /rlm build an RLM that extracts line items from PDF invoices into a spreadsheet
For train/validation optimization of an existing RLM, use the separate
/rlm-gepa skill.
Quick Example
import dspy
from predict_rlm import CtxStr, File, PredictRLM

class AnalyzeImages(dspy.Signature):
    """Analyze images and answer the query. Load each image as a base64 data
    URI and use predict() with dspy.Image to extract visual information."""
    images: list[File] = dspy.InputField()
    query: CtxStr = dspy.InputField()
    answer: str = dspy.OutputField()

rlm = PredictRLM(
    AnalyzeImages,
    lm="openai/gpt-5.4",
    sub_lm="openai/gpt-5.1",
)

result = rlm(
    images=[File(path="page.png")],
    query="Extract all visible text, then count each letter A-Z (case-insensitive).",
)

print(result.answer)
Use CtxStr for criteria, rubrics, and requests the outer RLM should read before
writing code. Callers still pass a normal string; the value is available both in
the prompt and as a Python variable in the REPL. See Custom path
inputs when adding file-, workspace-, or glob-like
signature inputs.
Observability
Every PredictRLM call returns a structured prediction.trace with iterations,
code, output, tool calls, predict() subcalls, timings, token usage, and errors.
Human-readable colored trace blocks are printed to stderr by default; pass
verbose=False for quiet execution. Use debug=True for timestamped RLM and
sandbox lifecycle diagnostics; error-like debug records are colored red.
Optional: Docker Sandboxes backend
JSPI/Deno/Pyodide remains the default sandbox. After installing
predict-rlm[sbx], use Docker Sandboxes (sbx) when you want an explicit
opt-in Linux Python runner:
brew install docker/tap/sbx
sbx login
from predict_rlm import PredictRLM, SbxConfig, SbxPool

rlm = PredictRLM(
    "question -> answer",
    sandbox_backend="sbx",
    sbx_config=SbxConfig(name="my-predict-rlm-sbx"),
)
By default, SbxConfig passes the explicit non-Docker shell template
docker.io/docker/sandbox-templates:shell to sbx create. Pass a custom
template="..." to override it, or template=None to omit --template and use
Docker's CLI default behavior.
For throughput-sensitive evals or optimization loops, create a pool of prewarmed runners and pass it explicitly:
with SbxPool(size=4, config=SbxConfig()) as pool:
    rlm = PredictRLM(
        "question -> answer",
        sandbox_backend="sbx",
        sbx_pool=pool,
    )
The backend mounts only a per-run staging directory under .predict_rlm_sbx/ by
default, preserving model-facing paths such as /sandbox/input/... and
/sandbox/output/... without exposing the rest of the repo workspace. Use
SbxConfig(extra_workspaces=[...]) only when the sandbox needs explicit
additional host mounts. Real sbx integration tests are skipped by default; run
them with PREDICT_RLM_RUN_SBX_TESTS=1 uv run pytest -m sbx after the CLI is
installed and logged in.
The native execution stack uses a persistent supervisor plus a persistent Python kernel so successful iterations preserve full REPL state. Per-iteration timeouts are recoverable when the backend can interrupt execution cleanly; native hard-kill fallback restores only a pre-timeout pickleable snapshot and tells the RLM which globals / imports were lost.
See predict-rlm Architecture for the component model, timeout behavior, and shared backend contracts.
Using the spreadsheet skill
The optimized spreadsheet skill is built in. Import it and pass it through
skills=[spreadsheet] so the RLM gets the spreadsheet-specific instructions,
openpyxl, pandas, formulas, and the formula_eval verification module
inside its sandbox.
import dspy

from predict_rlm import CtxStr, File, PredictRLM
from predict_rlm.skills import spreadsheet


class UpdateWorkbook(dspy.Signature):
    """Update the workbook following the request.

    Use openpyxl for workbook edits, Excel formulas for derived values, and
    verify formulas before returning the final .xlsx file.
    """

    workbook: File = dspy.InputField(desc="Input .xlsx workbook")
    request: CtxStr = dspy.InputField(desc="Requested spreadsheet changes")
    updated_workbook: File = dspy.OutputField(desc="Updated .xlsx workbook")


rlm = PredictRLM(
    UpdateWorkbook,
    lm="openai/gpt-5.4",
    sub_lm="openai/gpt-5.1",
    skills=[spreadsheet],
)

result = rlm(
    workbook=File(path="model.xlsx"),
    request="Add a Summary sheet with revenue by quarter and formulas for totals.",
)

print(result.updated_workbook.path)
For workflows that combine source documents and spreadsheets, compose skills:
from predict_rlm.skills import pdf, spreadsheet

rlm = PredictRLM(ProcessInvoices, skills=[pdf, spreadsheet])
Lifecycle callbacks
Hook into the RLM iteration loop to broadcast progress to a UI, write
structured logs, or feed an observability pipeline. PredictRLM extends
DSPy's existing callback contract (dspy.utils.callback.BaseCallback)
with two RLM-specific handlers:
| Handler | Fires | Receives |
|---|---|---|
on_rlm_iteration_start |
Before the action LM is called for iteration N | call_id, instance, iteration, max_iterations |
on_rlm_iteration_end |
After iteration N finishes (code executed, IterationStep built — or an error was raised) |
call_id, instance, iteration, step: IterationStep | None, is_final: bool, exception: Exception | None |
call_id matches the parent module's on_module_start/end ID, so events
correlate cleanly with DSPy's own callback events when you invoke the RLM
through DSPy's public module call path (rlm(...) or await rlm.acall(...)).
Existing BaseCallback subclasses keep working unchanged — handlers we
call are opt-in via getattr.
Async-aware. If you use await rlm.acall(...) your handlers may be
coroutines and they will be awaited. Sync rlm(...) calls sync handlers;
if it encounters an async handler the coroutine is closed and a warning
is logged.
Failure-isolated. Handler exceptions are logged and swallowed — a broken callback can never break the run.
Broadcasting a "loading" status to a websocket
import json
from dspy.utils.callback import BaseCallback
from predict_rlm import IterationStep, PredictRLM

class ProgressBroadcaster(BaseCallback):
    def __init__(self, websocket):
        self.ws = websocket

    async def on_rlm_iteration_start(self, *, iteration, max_iterations, **_):
        await self.ws.send_json({
            "type": "iteration_start",
            "iteration": iteration,
            "max_iterations": max_iterations,
        })

    async def on_rlm_iteration_end(
        self, *, iteration, step: IterationStep | None, is_final, exception, **_
    ):
        await self.ws.send_json({
            "type": "iteration_end",
            "iteration": iteration,
            "is_final": is_final,
            "step": step.model_dump(mode="json") if step else None,
            "error": str(exception) if exception else None,
        })

rlm = PredictRLM("query -> answer")
rlm.callbacks = [ProgressBroadcaster(ws)]
result = await rlm.acall(query="...")
Register globally instead with dspy.configure(callbacks=[...]) and the
same handlers fire for every PredictRLM instance.
Tests
The default package regression suite is tests/; example-local suites are
separate. Tests protect observable behavior, not exports, defaults, prompt wording,
docstrings, source text, or mocked argument forwarding.
tests/runtime_contracts/: shared execution, state, submission, files, tools, and recovery contracts across Direct, JSPI, and SBX. Backend-specific gaps are explicit inbackends.py; native Direct callbacks are serial, and deferred submission is a Direct-only interpreter API.- RLM, adapter, file, and workspace tests: generated-code execution, typed predictions, input/output handling, cancellation ownership, and data-loss boundaries.
- Trace and telemetry tests: evidence projection, accounting, redaction, and failure classification.
- GEPA tests: candidate acceptance, merge guardrails, evaluation artifacts, resume, and spend.
tests/codex_lm/: auth, transport completion/recovery, caching, and usage.
make test-unit              # all extras; no Deno or external SBX execution
make test-integration-jspi  # real Deno/Pyodide contracts; no LM credentials
make test-core             # no extras; includes local CPython processes
make test-sbx              # local WebSocket supervisor and pool contracts
make test-gepa
make test-codex-lm
Real SBX tests require the CLI, login, and make test-integration-sbx.
Bootstrap image tests additionally require Docker and
PREDICT_RLM_RUN_BOOTSTRAP_DOCKER_TESTS=1. Timing-sensitive local tests run
locally but are excluded from CI. Add a case only for a distinct failure or
invariant; extend the shared contract instead of copying it into backend suites.
Next steps
- Custom path inputs — add file-, workspace-, or glob-like signature inputs
- Custom adapters and the runtime kernel — implement an advanced typed lifecycle or execution capability
- Runtime observability — connect monitoring, logging, GEPA evidence, or another event consumer
- Architecture — understand and review runtime components, process boundaries, state ownership, and recovery
- How it works — understand the sandbox, REPL loop, signatures, and file I/O
- API reference — constructor params for
PredictRLM,File,CtxStr, andSkill - Skills — define, compose, and mount custom skills
- RLM-GEPA — optimize RLM skills from traces and
configure
AgentSpec - Examples — end-to-end demos with setup instructions
Release files for predict-rlm 0.8.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| predict_rlm-0.8.1.tar.gz | 301.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| predict_rlm-0.8.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 637.1 kB
Release files / predict_rlm-0.8.1.tar.gz
| Download URL | predict_rlm-0.8.1.tar.gz |
|---|---|
| Size | 301.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
28c084344008b0330b1840e59d388f3e8050b540bfa515474ed754f621dc57c5
|
|
BLAKE2b-256 checksum How to use checksums |
19276ebc36075cd914a362f36d619af9f7edd1ad4b17fb6b2134053e4c68fb94
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / predict_rlm-0.8.1-py3-none-any.whl
| Download URL | predict_rlm-0.8.1-py3-none-any.whl |
|---|---|
| Size | 335.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cda8e62631485df3411eebbbea26316f854eba3b3f098fdd4eb44f4df5b28e68
|
|
BLAKE2b-256 checksum How to use checksums |
c3928c05d064a9cacae19ef9517b3da2ba603b781ef540aebc230300a99559fe
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













