


KD discovers the governing partial differential equation from a field
sampled on a spatiotemporal grid. The same Model.fit also takes a plain
feature table and returns a scalar expression y = f(X).
Five in-house algorithms (SGA, DLGA, DISCOVER, EqGPT, LLM4ED) and two external
baselines (PySR, PySINDy) run behind one kd.Model API, with a common dataset
interface, visualization and HTML reports.
Install
In an activated Python 3.11+ environment, install with uv:
uv pip install sail-kd --torch-backend=auto
The option selects the PyTorch build for your hardware: a CUDA build the
installed driver supports, or the CPU build. See
Installation
for environment setup, pip installation, CPU/CUDA builds and optional components.
For a source checkout, clone this repository's trunk branch and run uv sync.
Quick start
Discover Burgers' equation from the bundled 256 × 201 field:
import kd

dataset = kd.load_burgers()
model = kd.Model(algorithm="sga", generations=5, seed=0)
model.fit(dataset)

print(model.result_.equation)  # u_t = -u*u_x + 0.1002*u_xx
The five-generation search recovers
$$u_t = -u,u_x + 0.1002,u_{xx}$$
against the benchmark equation $u_t = -u,u_x + 0.1,u_{xx}$.
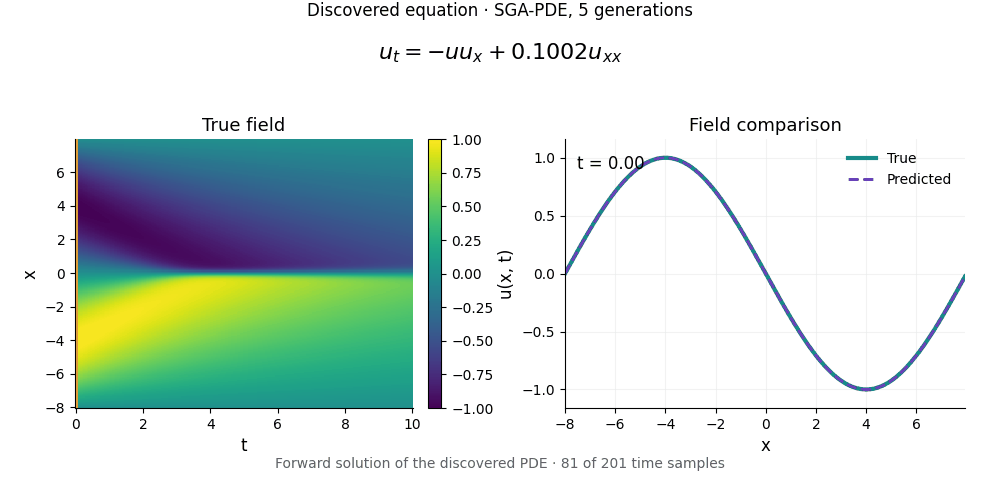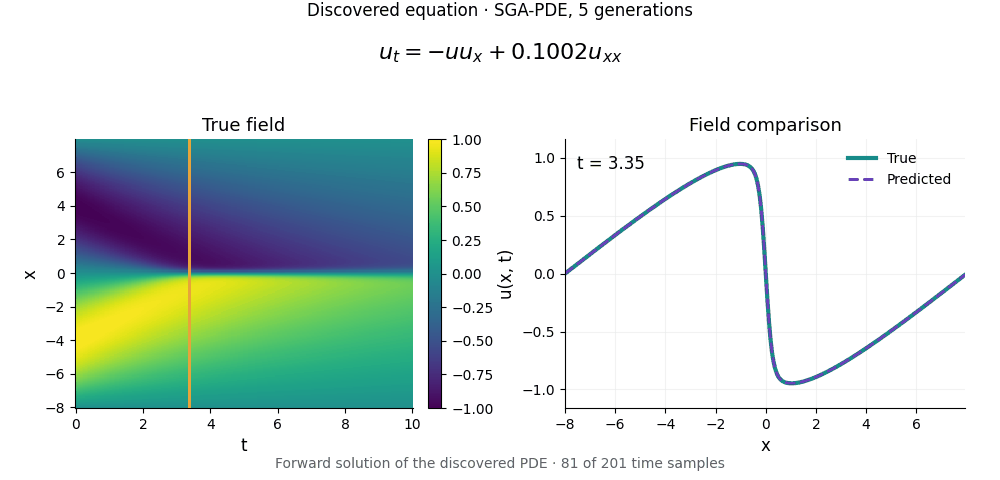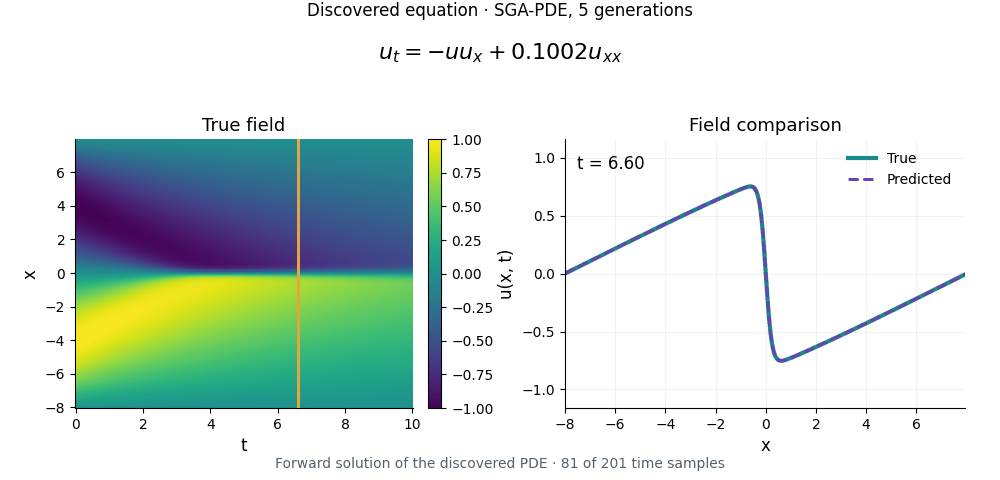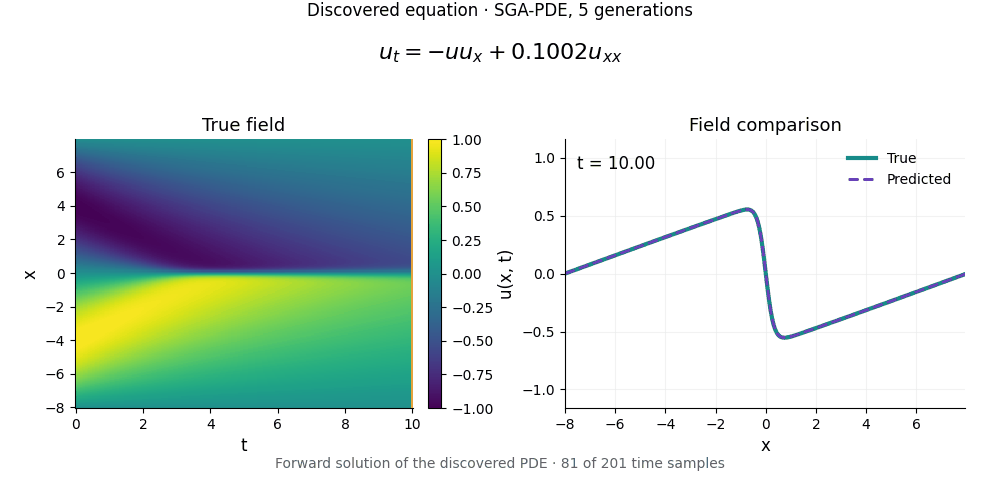
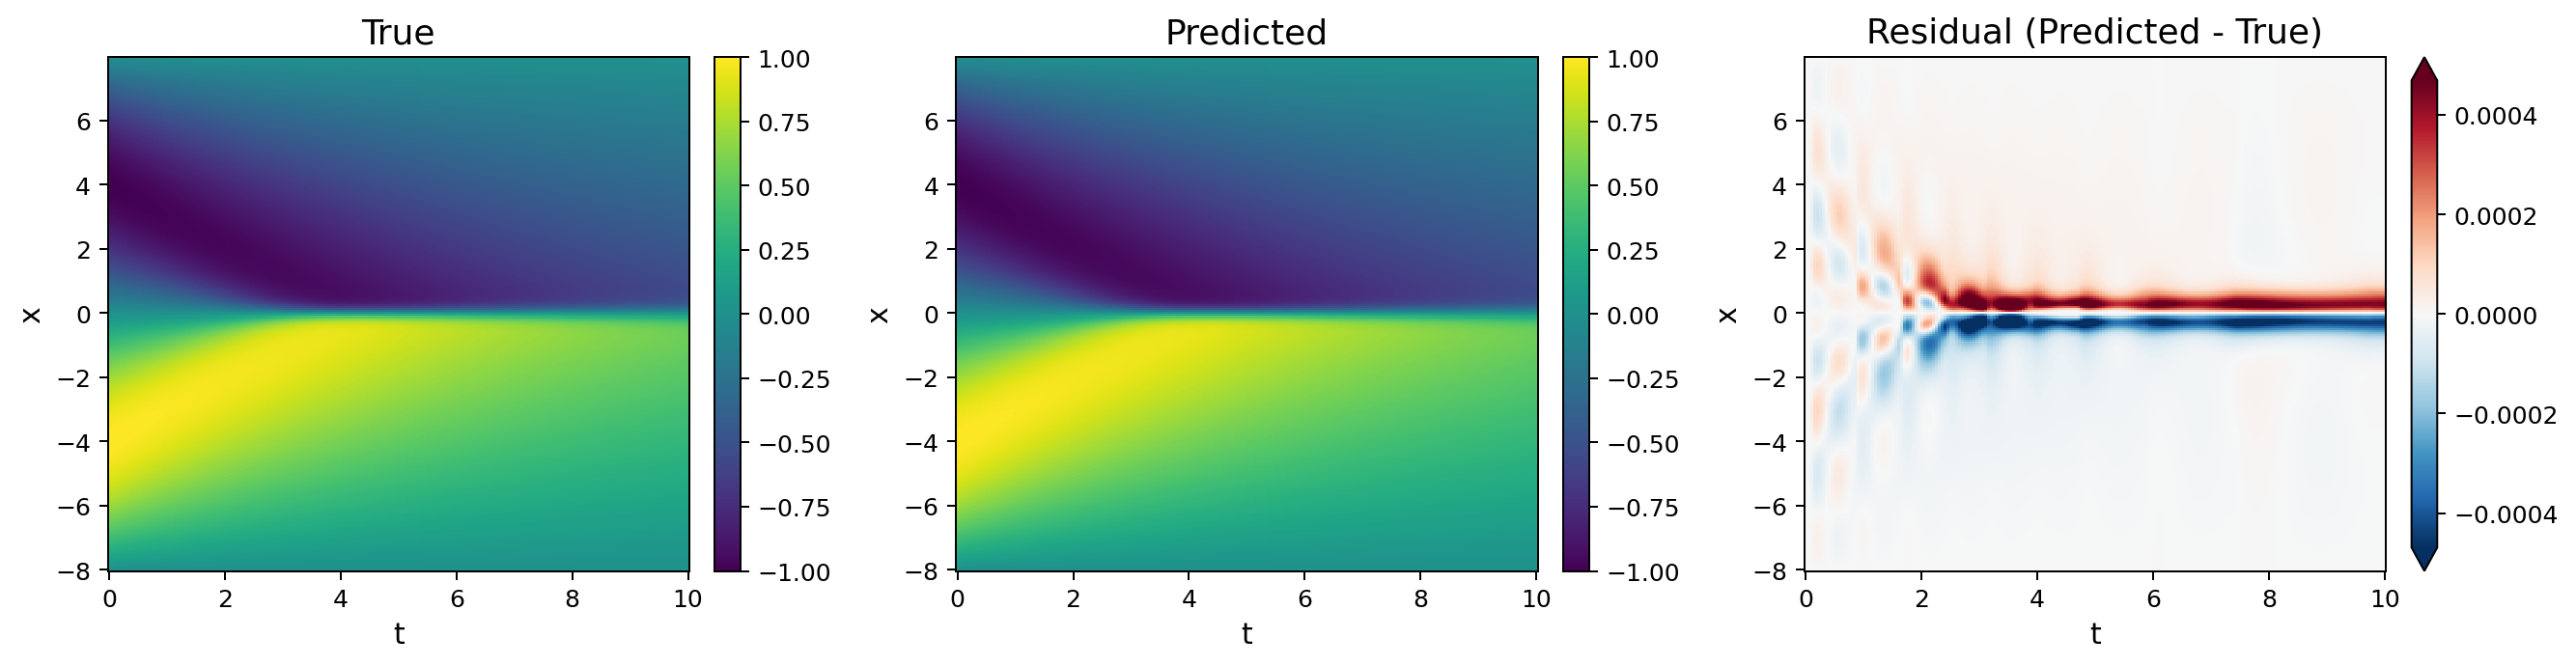
The animation follows the field through time. The marker on the left selects the profile shown on the right, where the observations are compared with the forward solution of the discovered PDE. The solution uses this fit's coefficients, starts from the dataset's initial condition and uses its periodic spatial boundary. The full field comparison includes the residual.
First fit
explains the result and its diagnostics. model.report("out/burgers") writes an
HTML report with convergence, residuals, field comparisons and search diagnostics.
Your own data enters through kd.load, which takes a catalog id or a file path.
Inspect a file's arrays first, then name its coordinates and fields:
kd.inspect_file("run.mat")
dataset = kd.load("run.mat", coords={"x": "x", "t": "t"},
                  fields={"u": "usol"}, lhs="u_t")
Use your own data
also covers registered layouts such as PDEBench HDF5, sample selection and
PDEDataset.from_arrays for arrays already in memory.
Algorithms
The five in-house algorithms are refactored re-implementations of methods
developed in the Scientific Artificial Intelligence Lab. Swap the algorithm=
string to switch; all seven share one dataset interface and one result object.
Each linked page covers the method, its parameters and setup.
| Algorithm | algorithm= |
Origin | Approach |
|---|---|---|---|
| SGA-PDE | "sga" |
Chen et al. 2022 | Genetic algorithm over symbolic expression trees |
| DLGA-PDE | "dlga" |
Xu et al. 2020 | Neural-network surrogate + genetic algorithm |
| DISCOVER | "discover" |
Du et al. 2024 | LSTM controller + policy gradient |
| EqGPT | "eqgpt" |
Xu et al. 2025 | Pretrained GPT proposes candidate PDEs, followed by reward-guided fine-tuning |
| LLM4ED | "llm4ed" |
Du et al. 2024 | An LLM proposes candidate equations as text, scored by a sparse-regression reward |
| PySR | "pysr" |
External, Cranmer 2023 | Genetic programming over expression trees |
| PySINDy | "pysindy" |
External, de Silva et al. 2020 | Native STLSQ sparse regression over a KD term library |
SGA-PDE, DISCOVER, LLM4ED, PySR and PySINDy also accept feature tables. Every algorithm
accepts a sketch for a PDE on gridded data,
apart from the two modes named under "Discovery with a sketch"; a sketch
specifies known terms and constrains the unknown remainder. Algorithm settings
can be passed as Model keywords;
the API reference
documents their types, defaults and programmatic configuration schemas.
Tabular data
Model.fit also accepts a TabularDataset: a plain feature table, searched for
y = f(X) with no fields, no derivatives and no term library to supply. The
example below uses the bundled TLC-CC measurements, 74 chromatography conditions.
The search takes about 17 minutes with OMP_NUM_THREADS=1 and about 30 minutes
with PyTorch's default thread count on a 24-core CPU. At seed 0 its front contains
the published form r/(a*R_F + b), with a and b close to the published 0.147 and
0.0114.
import kd

dataset = kd.load_tlc_cc(target="start")  # X = (R_F, r), y = V_S
model = kd.Model("discover", generations=200, seed=0,
                 batch_size=1000, reward_alpha=0.005, max_length=15).fit(dataset)

for entry in model.result_.pareto_front():
    print(entry.complexity, entry.loss, entry.scale, entry.expression)
The Pareto front records accuracy and expression size. Each entry holds the raw
candidate in entry.expression and its fitted outer coefficient in entry.scale;
both are needed to read the fitted expression. SGA-PDE, DISCOVER, LLM4ED, PySR
and PySINDy run in tabular mode. Column chromatography
compares the DISCOVER and PySR fronts and their recovered coefficients with the
published formula.
ODE trajectories
Time series of an ODE system load with kd.load(..., kind="trajectory"). The
file below is a long table with one row per sample: a trajectory id column
(run), a time column (time) and one column per state. Trajectories may
differ in length and time grid.
import kd

trajectories = kd.load(
    "trajectories.csv",
    kind="trajectory",
    coords={"t": "time"},
    fields={"x": "position", "v": "velocity"},
    trajectory_id="run",
)
table = kd.trajectories_to_tabular(trajectories, "x", trim=2)
model = kd.Model("sga", generations=100, seed=0).fit(table)
kd.trajectories_to_tabular differentiates each trajectory in time and returns
a feature table with every state as an input and the derivative of one state,
here dx_dt, as the target; trim=2 drops two samples at each end of every
trajectory. The fit gives the law of that one state. Integrating the system
forward needs one law per state, so the projection and the fit are repeated for
v.
Examples and datasets
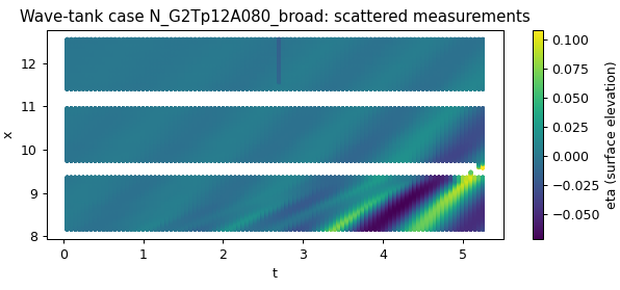 Breaking waves Reproduce the published EqGPT equation on 12 wave-tank experiments. |
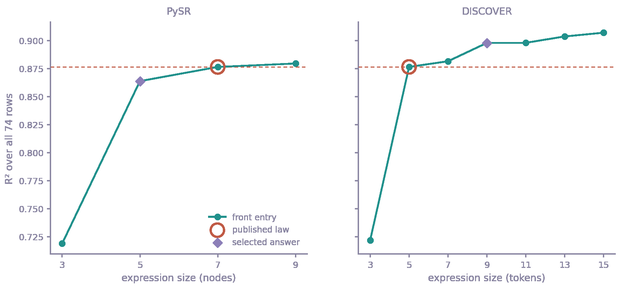 Column chromatography Compare DISCOVER and PySR on 74 measured conditions and locate the published formula on each Pareto front. |
For a longer PDE search, the KdV walkthrough follows 200 generations of SGA-PDE and explains the discovered terms and report.
The simulated datasets come from this lab's PDE-discovery papers, including SGA-PDE, EqGPT and LLM4ED. The catalog runs from Burgers and KdV to 2D Burgers, Klein-Gordon and the Fisher family. KD also bundles two experimental datasets: wave-tank surface elevations and chromatography retention volumes, used with the permission of the authors. The dataset catalog provides equations, grids, measurement protocols, sources and licenses; the dataset API also covers synthetic generators and downloads.
All tutorials and runnable scripts cover every algorithm, including tabular regression and algorithm comparison.
Discovery with a sketch
When part of the law is already known, fit(dataset, sketch=...) states that
part and searches the remainder. A pinned term is subtracted from the regression
target before the search and restored with its coefficient in the solution.
An anchored term fixes the structure while leaving its coefficient free.
A hole declares how many terms may fill it and what forms they may take,
including derivative order, operators, fields and axes.
With the quick start's dataset and model, this sketch pins the advection
term with its coefficient and leaves one hole for a single term of derivative
order at most 2:
sketch = kd.Sketch(pinned={"u*u_x": -1.0},
                   holes=[kd.Hole(max_terms=1, max_deriv_order=2)])
model.fit(dataset, sketch=sketch)
model.result_.equation contains the pinned term, and
model.result_.sketch_outcome reports the clause-by-clause verdict and, when
the law satisfies every clause and fits the data, the certified solution.
Every algorithm accepts a sketch when it searches a PDE on gridded data, except
DISCOVER's PINN mode and EqGPT's multi-case wave mode; kd.instrument_schemas()
declares the support of each mode clause by clause. The
Burgers sketch example pins the advection term,
searches for the missing diffusion term and explains how the result is checked
against the sketch and the data.
Further use
| Capability | Guide or example |
|---|---|
Experimental controller: configure a language-model endpoint, search a dataset and receive a Markdown report with kd-agent |
Controller guide |
| Figures and HTML reports: inspect convergence, residuals, field comparisons and algorithm-specific diagnostics | Visualization |
| Checkpoint and resume: save search state and continue from a recorded checkpoint | Resume guide |
| Batch experiments: run an algorithm × dataset plan with recorded environments and consensus reports | Batch guide |
| Term evaluation: fit candidate terms or validate them with per-term rejection reports | Term API |
| Dataset preview: inspect axes, spacing, field statistics and the left-hand side before searching | Data requirements |
Citation and acknowledgements
For research using KD, cite the original works for the methods and datasets you use. The five lab algorithms are refactored re-implementations of these methods; their algorithm pages provide the papers and references:
- SGA-PDE: Chen et al., Phys. Rev. Research 4, 023174 (2022); original code.
- DLGA-PDE: Xu et al. (2020); paper and references.
- DISCOVER: Du et al. (2024); original code.
- EqGPT: Xu et al., Nat Commun 16, 10255 (2025); original code.
- LLM4ED: Du et al., Phys. Fluids 36, 097121 (2024); original code.
KD also builds on PySR, PySINDy, SymPy and PyTorch. Dataset attribution and redistribution terms are in NOTICE.
License
Apache-2.0. Copyright 2026 Mao, Hao and the Scientific Artificial Intelligence Lab.
1 maintainer

Metadata
1 maintainer
Release files for sail-kd 0.9.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| sail_kd-0.9.0.tar.gz | 20.5 MB | Without provenance | Details for sail_kd-0.9.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| sail_kd-0.9.0-py3-none-any.whl | Python 3 | none | any | Details for sail_kd-0.9.0-py3-none-any.whl |
Total release size: 41.1 MB
Release files / sail_kd-0.9.0.tar.gz
| Download URL | sail_kd-0.9.0.tar.gz |
|---|---|
| Size | 20.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
728fa30a6f557533a9e4f2f7a4a2411130fd194736878e89bc504d559e174d07
|
|
BLAKE2b-256 checksum How to use checksums |
d0378babd94556337b421611e212df319259974e3f2e07bde906dcdb98e6e7e5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.5 {"installer":{"name":"uv","version":"0.13.5","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / sail_kd-0.9.0-py3-none-any.whl
| Download URL | sail_kd-0.9.0-py3-none-any.whl |
|---|---|
| Size | 20.7 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1451efb9b6b048c5f62ae327fce0196da408c32773d9b66dc939059a8fa64a1f
|
|
BLAKE2b-256 checksum How to use checksums |
cb7e5369149fce8df4989c3e6c256f601c3cab096d98464b96f94877f9a0ad36
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.13.5 {"installer":{"name":"uv","version":"0.13.5","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Security for sail-kd 0.9.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.