
Web scrapers that fail loudly when a site changes,
instead of quietly returning empty values.
No model, no API key, no bill.





Documentation · Getting started · In your agent · Scoreboards · FAQ · Changelog
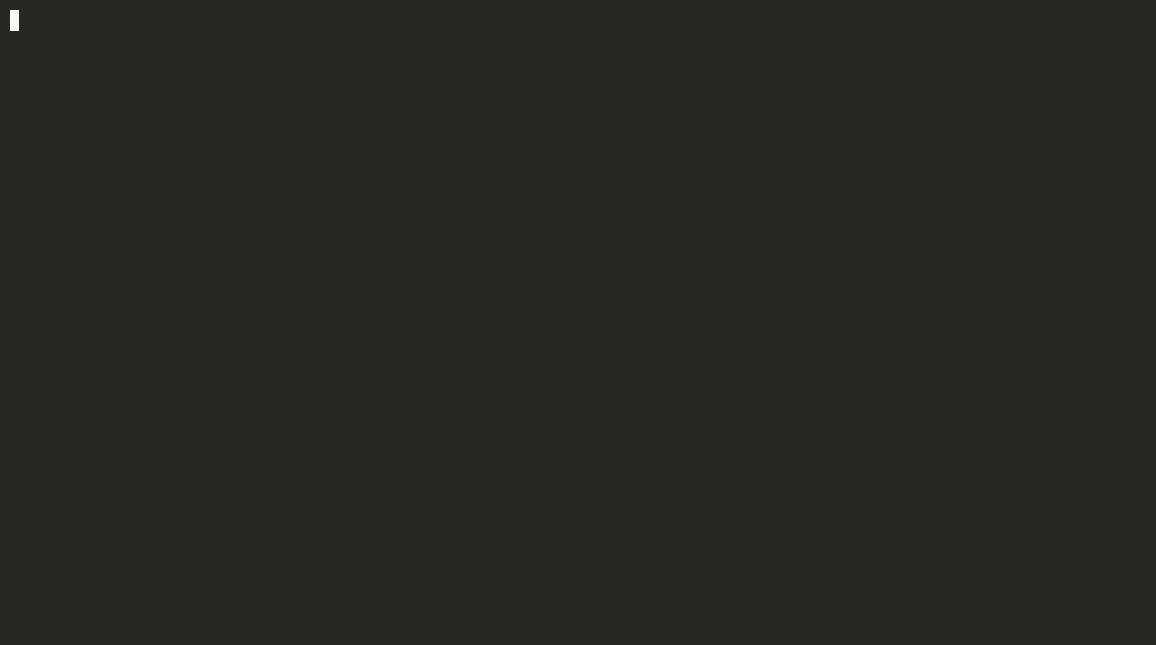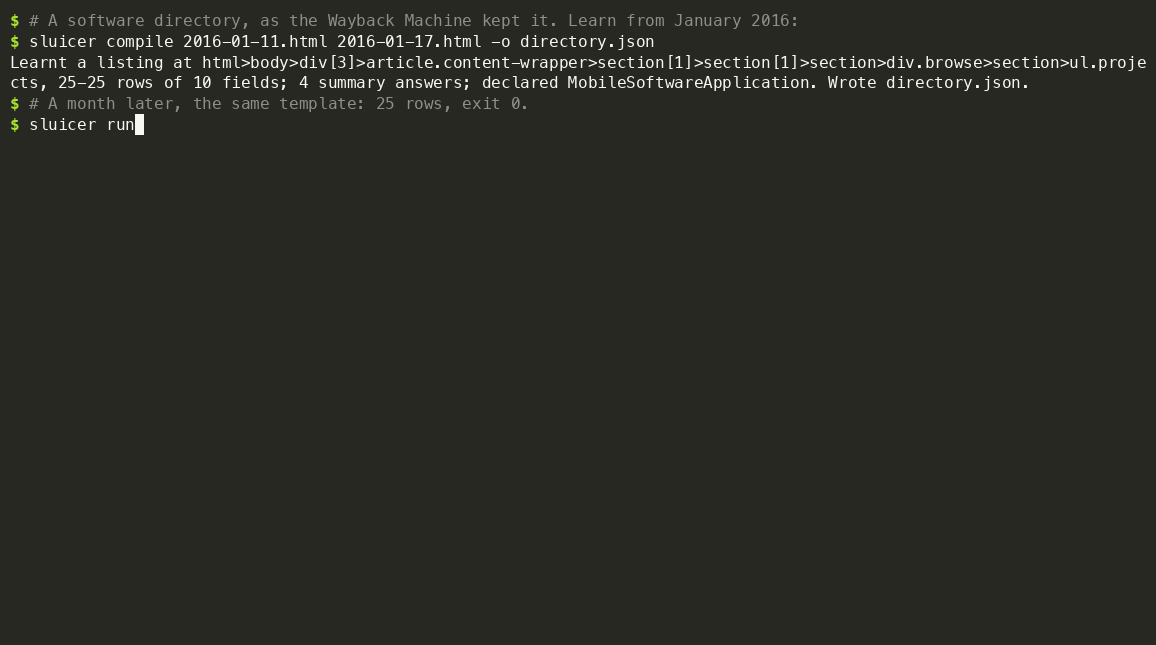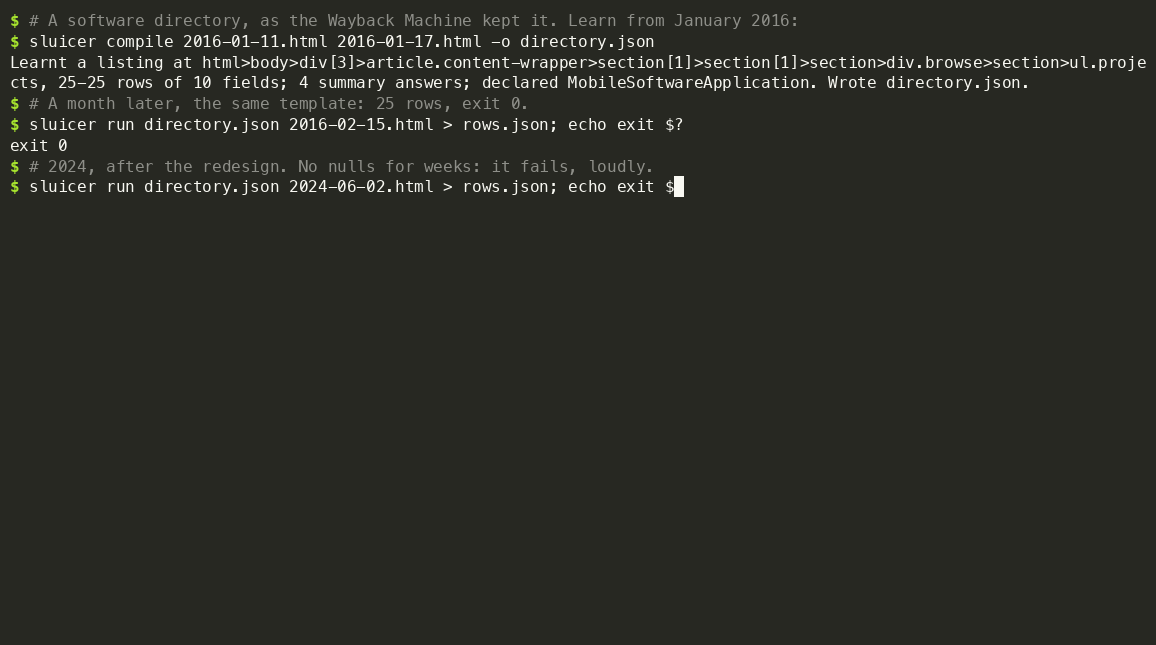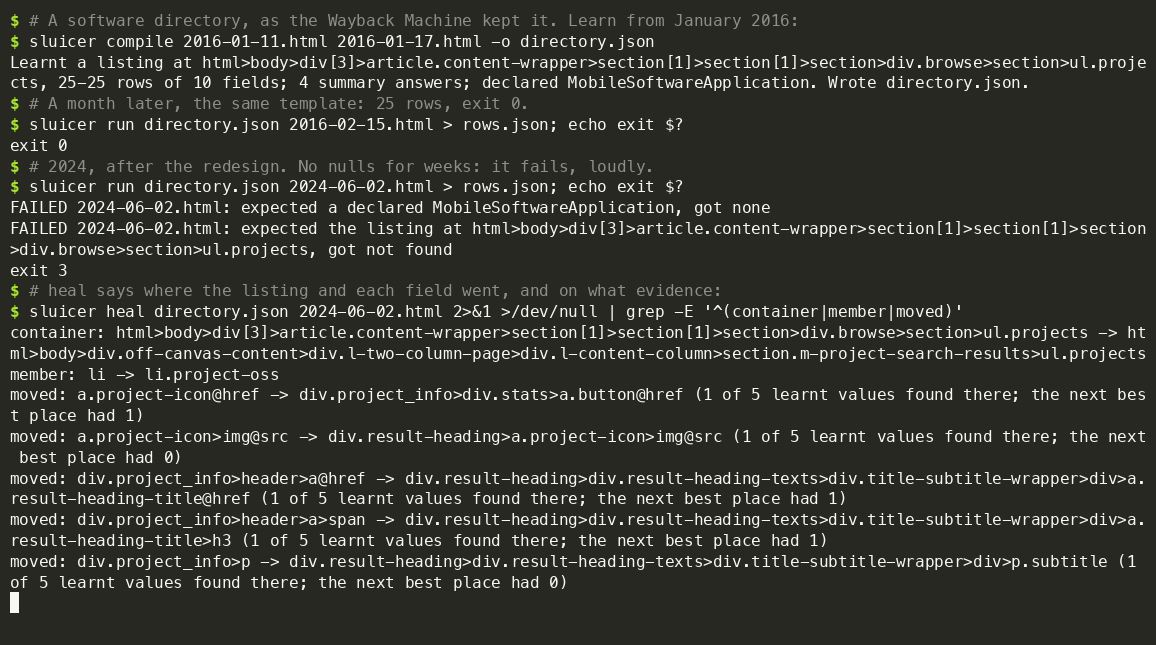
A real site, as the Wayback Machine kept it. The extractor learnt in January
2016 still fits in February. After the 2024 redesign it stops with exit code
3, and heal shows where the listing and most of its fields moved.
Most scrapers break without a sound. The site changes its markup, and the scraper keeps running and returns nulls, or the wrong column, for weeks before anyone notices.
Sluicer works the other way round. Show it a value on a few pages of a site
(a price, a title, a date) and it learns where that value lives. On every
page it reads after that, it checks the page against what it learnt. If the
layout has changed, the run fails with exit code 3 and names the field that
broke, and sluicer heal tells you where each field moved.
It also reads everything a page already declares about itself: JSON-LD, microdata, RDFa, OpenGraph and four more vocabularies, merged into one record per thing, with every value pointing to the exact place on the page it came from. No model reads any page, so the same page always gives the same answer.
Quick start
uv pip install "sluicer[fetch]"

# Learn an extractor from three pages built on one template, given one value from the first.
sluicer compile p1.html p2.html p3.html --want price=41.90 -o shop.json

# Replay it on any page of that template: the values as JSON, or exit 3 if the page changed.
sluicer run shop.json https://shop.example/p/7

# After a redesign: see what moved, and write the healed extractor.
sluicer heal shop.json https://shop.example/p/1 -o shop.json
Exit codes follow grep: 0 found -- a record or a summary answer, a <title>
alone included -- 1 found nothing, 2 could not read the page, and 3 when a page
broke its extractor's checks, a heal lost a field or left a move undecided, or
an audit found a documented rule broken. diff exits 1 when something changed.
The checks are about structure: a run fails when a field is no longer where it was learnt, no longer reads the way it did, or no longer has its shape. A change that keeps all three, such as a different number in the price's place, passes: on SWDE, 17% of the extractors' wrong answers were flagged.
Reading what a page declares needs no example at all. The product page read
here is
examples/brake-pads.html:
>>> import sluicer
>>> page = open("examples/brake-pads.html", "rb").read()
>>> result = sluicer.extract(page, url="https://example.com/p/bp-2210")
>>> price = result.summary["price"]
>>> price.value, price.source, price.key
('41.90', 'jsonld', 'Product.offers.price')
>>> price.where
'/html/head/script[1]#/offers/price'
>>> result.normalised
{'price': '41.90', 'currency': 'EUR', 'gtin': '4006381333931'}
>>> [(answer.value, answer.source) for answer in result.conflicts[0].answers]
[('41.90', 'jsonld'), ('39.90', 'opengraph')]
The page states one price in its JSON-LD and another in its OpenGraph tags;
Sluicer reports the conflict instead of picking one in silence. sluicer inspect page.html shows the same reading laid out for a person.
Install
uv pip install "sluicer[fetch,markdown,mcp]"
pip install works the same way, and uv tool install gives you the command
in an environment of its own. The base install, uv pip install sluicer, reads
HTML you already have, with lxml and click alone.
What each extra adds
| extra | adds |
|---|---|
fetch |
fetching: plain HTTP first, a browser only when the page proves it needs one |
markdown |
a page's main content as Markdown, by trafilatura |
mcp |
the MCP server, with fetch and markdown |
api |
the HTTP API, with mcp |
microformats |
microformats2, which is off by default |
To let Sluicer use a browser, install one once: uvx --from "sluicer[fetch]" scrapling install. Without
it, plain HTTP still works, and a page that needed a browser says so.
What you can give it
| you have | run | and get |
|---|---|---|
| a page, as HTML or a URL | sluicer extract page.html |
every record it declares, a summary that answers 25 questions, its conflicts, each value with where it came from |
| many pages of one template | sluicer compile ... --want price=41.90, then sluicer run |
the fields you gave an example of, from every page, checked |
| a page that declares nothing | sluicer extract page.html --induce |
the rows its markup repeats: a listing's cards, a table's lines |
| a whole site | sluicer map URL, sluicer crawl URL -o site.jsonl |
its addresses from its sitemaps, or every page it links to, read politely |
| a list of URLs, a web archive | sluicer batch urls.txt, sluicer warc crawl.warc.gz |
one JSON line per page |
| a feed | sluicer feed URL |
its items, as one JSON document |
| an article | sluicer markdown URL |
its main text as Markdown |
Every request names Sluicer, and robots.txt and Crawl-delay are obeyed; a
crawl waits when a site asks it to. Only a command that reads single pages or
learns an extractor can be told otherwise, with --stealth or --no-robots;
map, crawl and batch cannot. sluicer --help lists every command, and
the command line reference
explains each one.
In your agent
claude mcp add sluicer -- uvx --with "sluicer[mcp]" sluicer mcp   # Claude Code
codex mcp add sluicer -- uvx --with "sluicer[mcp]" sluicer mcp    # Codex
The MCP server has ten read-only tools, among them extract_declared,
compile_extractor, run_extractor and heal_extractor. Every answer carries
ok, true only when it can be used as it is. The server does not fetch
localhost, private networks or cloud metadata addresses unless it is started
with SLUICER_ALLOW_PRIVATE=1.
In your agent
covers Cursor, VS Code, Gemini CLI, Claude Desktop, Zed, LangChain, the OpenAI
Agents SDK and Pydantic AI. For any other language, sluicer serve offers the
same tools over HTTP (HTTP API).
Measured, losses included
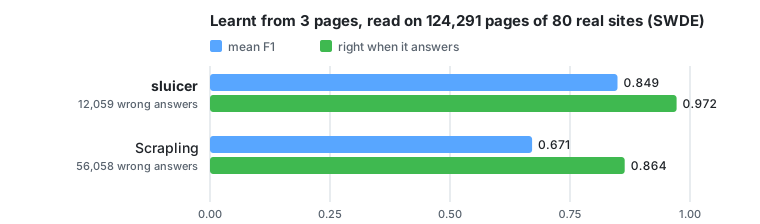
Every number below comes from a public test set, and every scoreboard gives the command that produces it again. Where another tool does better on what a row measures, the row shows it.
| scoreboard | what is measured | Sluicer | beside it |
|---|---|---|---|
| SWDE, 80 sites | extractors learnt from three pages, run on the other 124,051 | F1 0.849, 12,059 wrong answers | Scrapling 0.671, 56,058 wrong |
| Drift, 44 before/after pairs on 25 sites | a change noticed: 21 changed, 23 did not | 0 failed silently, 0 false alarms | -- |
| Products, 140 pages | price, availability (F1) | 0.750, 0.907 | Zyte's paid API 0.918, 0.957 |
| WCXB, 511 pages | title, author, date found; dates invented | 0.727, 0.532, 0.581; 8 invented | trafilatura 0.745, 0.750, 0.838; 216 invented |
| As served, 360 pages | dates found; right when it answers | 0.780; 0.734 | trafilatura 0.855; 0.393 |
| News, 21 languages | title, author, date found | 0.871, 0.829, 0.970 | trafilatura 0.852, 0.879, 0.970 |
| trafilatura's set, 990 pages | title, author, date found | 0.776, 0.468, 0.585 | trafilatura 0.738, 0.669, 0.865 |
Sluicer reads only what a page states in its markup, so on titles, authors and
dates it answers less often than tools that also read the visible text, and it
invents far fewer dates. Its rules were written while reading the pages of these
scoreboards, so the numbers show how it does on pages it was tuned on. The one
held-out test is the half of SWDE's sites whose pages and errors were not read
while making the rules; its numbers were looked at three times, once to decide
whether to keep a rule. There it scores 0.845, including five camera sites that
were read before the split and so are not a clean test.
bench/PREREG.md
records which pages each rule was made on.
When not to use Sluicer
- You need authors or dates that pages do not declare. trafilatura reads
them from the visible text and finds more of them. Sluicer's
--visibleoption guesses them too, but it is new and not yet measured on the scoreboards. - You need an article's full text.
sluicer markdownuses trafilatura for it; if you need trafilatura's options or other output formats, use it directly. - The site blocks bots. Sluicer is not built to get past bot protection:
every request names it, unless a single-page command is given
--stealth.
Why Sluicer compares it with extruct, trafilatura, Scrapling, Crawl4AI and Firecrawl, and says when each is the better choice.
Learn more
- Getting started, a ten-minute tour, and Extractors, how learning, checking and healing work.
- FAQ, Known limits and What is stable before 1.0.
- Moving from extruct:
from sluicer.compat import extructanswers extruct's own calls. - The full documentation is at https://gi0tto.github.io/sluicer/.
Community
Questions, ideas and what you built go to Discussions. A page Sluicer read wrong is an issue: attach the page, so the fix comes with a test. Report a vulnerability privately, as SECURITY.md explains, and see CONTRIBUTING.md to set up a checkout.
Sluicer is built and maintained by one person. If it saves you time or money, sponsoring it pays for keeping the scoreboards measured and the extractors working as the web changes.
Licence
MIT, except two data files under their own licences: schema.org's type names
(CC BY-SA 3.0) and CLDR's month and weekday names (Unicode License v3); the
package's licence expression is MIT AND CC-BY-SA-3.0 AND Unicode-3.0. The base
install needs lxml and click, both BSD-3-Clause. The extras pull a wider
tree that is not all permissive: tld is MPL-1.1, GPL-2.0-only or
LGPL-2.1-or-later, orjson is MPL-2.0 alongside Apache-2.0 or MIT, and
certifi is MPL-2.0. CI lists every licence in that tree and fails on one
nobody has read; NOTICE
says more.
1 maintainer

Release files for sluicer 0.7.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sluicer-0.7.1.tar.gz | 788.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sluicer-0.7.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.2 MB
Release files / sluicer-0.7.1.tar.gz
| Download URL | sluicer-0.7.1.tar.gz |
|---|---|
| Size | 788.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
457e1e170f56fe9c4f9b9faeabde8a2089374cd0566e3c4903d783ca740d7b6b
|
|
BLAKE2b-256 checksum How to use checksums |
1d69fea73dd93bf8ed3ab821dac351656b894b32891d323c3be900b687d6efa1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / sluicer-0.7.1-py3-none-any.whl
| Download URL | sluicer-0.7.1-py3-none-any.whl |
|---|---|
| Size | 368.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9cf01613a26437274968c087e7baf434e6c23fc29733c4ea73b9625f73908dd1
|
|
BLAKE2b-256 checksum How to use checksums |
509a430ebdc4c8d08a06465febb73fa004e8cc30c7ad515dce3c310f530329ca
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













