
Starplast
← Back · Next → · Open slide viewer · PDF · PowerPoint






Starplast is a desktop app for exploring gene evidence in Toxoplasma gondii and Plasmodium falciparum. It brings expression, fitness screens, localization, protein features, interactions, and literature annotations into one place.
Use it to look up a gene, investigate hits from a screen, compare groups of genes, and choose candidates for follow-up experiments. The bundled maps contain 8,140 T. gondii genes and 5,720 P. falciparum genes, viewed separately.
User guide · Python API · Dataset catalogue · Changes
Install
Python 3.10 or newer is required. The desktop app needs a display and OpenGL.
pip install starplast
starplast
From a checkout:
git clone https://github.com/EinarOlafsson/starplast.git
cd starplast
pip install -e .
starplast
The default installation runs analyses on the CPU. For an NVIDIA GPU on Linux x86_64 with a CUDA 12 compatible driver:
pip install "starplast[gpu]"
GPU dependencies are large and optional. starplast-install-gpu can also inspect
your driver and offer an installation command. macOS and Windows use CPU analysis;
the 3D display still uses OpenGL.
The built gene tables and graphs ship with the package. Browsing them works offline. Protein structures are downloaded when requested and cached locally. Rebuilding the bundled data requires the original source datasets.
Explore a screen
- Choose the organism under File → Species.
- Search for a gene ID. For T. gondii, File → Import data adds your screen results.
- Colour and filter the map using the measurements you want to compare.
- Click a gene to read its evidence and inspect each type of relationship separately.
- Select a group with a lasso or brush, then export the gene list for follow-up.
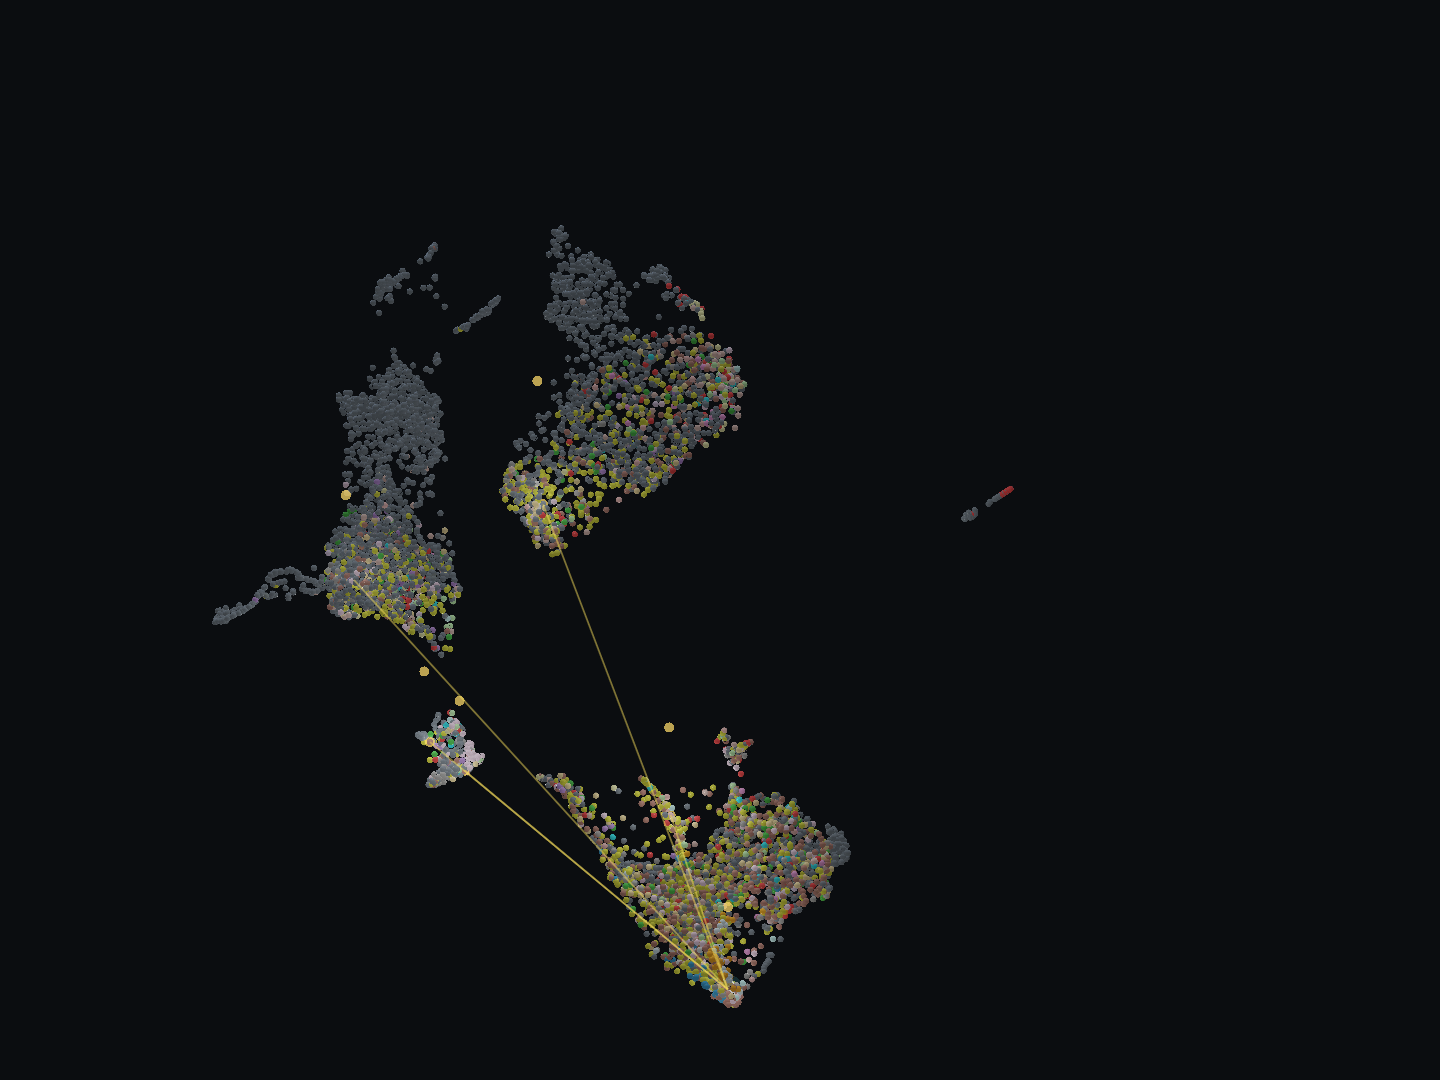
The T. gondii map with CDPK1 (TGME49_301440) selected. The selected gene and
its five neighbours emit light; lines show attention-corrected literature
co-mention links. Colours show compartments. This animation uses the pre-0.43
layout; newly opened maps use the recorded, balanced feature recipe.
View a still image.
Each point is a gene. Its position comes from an embedding of selected features; nearby points have similar inputs, but proximity alone does not demonstrate a shared function or physical interaction. Colours, relationship edges, and the evidence panel provide the context needed to interpret the map. Missing evidence is shown separately from measured values.
The analysis panel lets you change feature sets, build embeddings, cluster genes, and evaluate recovery of labels held out from the input. Search scores help prioritize candidates; they are not experimental validation. See the user guide for controls and analysis settings.
Explore, predict and compare
The Tools menu offers three starting points:
- Explore a gene searches identifiers, symbols and descriptions, then shows the source evidence.
- Predict a trait compares held-out predictions before making calls for unlabelled genes. Related genes stay in the same evaluation group; reports retain missing values, calibration status and exact input settings.
- Compare a screen joins a gene-level CSV/TSV to the existing evidence and keeps unresolved identifiers visible.
The package includes frozen protein sequence representations for 8,064 Toxoplasma proteins and AF3 summary features for 1,210 exactly mapped genes. Sequence features are optional inputs to prediction; local structure files can also be indexed for the structure viewer.
In the 0.43 benchmark, boosted trees with sequence and structure features reached 56.2% localization accuracy across held-out orthogroups. UMAP neighbours performed less well, and several rare classes remained poorly recovered. These are model hypotheses, not experimentally established annotations.
Strategies
The strategies tab, beside Evidence and Analysis, lists 34 named ways of turning the combined data into a claim: hold a category out and search for a map that finds it again; hand over a gene list and hunt for the one cluster that holds it; carry a label along crosslinks or shared folds; predict a screen from other evidence; call a gene only where independent methods agree. Each has a guide, a walkthrough and a self-test that hides known information, asks for it back and compares the answer with the same procedure on shuffled data. On the shipped T. gondii table 28 strategies pass their self-test at their defaults, 5 fail and 1 is inconclusive; beside each, the tab shows the grade its calibration earned.
Measured 2026-09-26 over 5,940 self-tests: every strategy's self-test run over a grid of its settings, several held-out known labels and five seeds. Skill puts every metric on one scale -- 0 is the same procedure on shuffled data, 1 is perfect. Tuned is the best setting chosen on seeds 1-3 and reported on seeds 4-5, so it is not the luckiest of many settings. Intervals are 95%, by bootstrap over held-out targets and runs. Every number, per target and per setting.
T. gondii -- 26 reliable, 7 weak, 1 untestable
| # | Strategy | Metric | Grade | Skill at defaults [95% CI] | Pass | Skill tuned [95% CI] | Pass | Tuned setting | Tests |
|---|---|---|---|---|---|---|---|---|---|
| 01 | Hold out a category and search for a map that finds it | F1 of hidden genes in the cluster chosen for their label on known genes | weak | 0.07 [0.03, 0.11] | 44% | 0.07 [0.03, 0.11] | 40% | min_cluster_size=[10, 25]; n_neighbors=[25, 100]; selection=[eom, leaf] | 150 |
| 02 | Find the map where your gene list is one cluster | F1 of the hidden members against the best cluster's other genes | weak | 0.03 [0.00, 0.04] | 16% | 0.03 [0.00, 0.05] | 10% | min_cluster_size=[20, 50]; n_neighbors=[10, 30] | 100 |
| 03 | Ask which categories the data can rediscover | hidden-gene AUROC of the categories the atlas ranks in its top half | reliable | 0.50 [0.22, 0.67] | 80% | 0.50 [0.22, 0.68] | 80% | k=15 | 75 |
| 04 | Keep only the modules that survive the whole walk | F1 of hidden genes in the module chosen for their label on known genes | weak | 0.07 [0.01, 0.13] | 56% | 0.05 [-0.04, 0.10] | 50% | threshold=0.3 | 75 |
| 05 | Tune a map without labels, then read what it encodes | share of first-half findings that replicate on the second half | reliable | 0.95 [0.88, 1.00] | 100% | 0.96 [0.95, 0.98] | 100% | map_from=chemistry | 70 |
| 06 | Find which kind of evidence carries a label | hidden accuracy of the evidence ranked first (transcription) | reliable | 0.14 [0.06, 0.25] | 64% | 0.16 [0.08, 0.25] | 70% | k=5 | 75 |
| 07 | Call a gene by the genes that behave like it | correct calls per hidden gene | reliable | 0.22 [0.08, 0.36] | 60% | 0.29 [0.16, 0.43] | 80% | k=5; min_share=0.3 | 225 |
| 08 | Call a gene by its neighbours on the map | correct calls per hidden gene | weak | 0.13 [0.01, 0.24] | 60% | 0.11 [-0.04, 0.23] | 60% | k=5; n_neighbors=60 | 225 |
| 09 | Name a cluster by the label it is enriched for | precision of calls on hidden genes | reliable | 0.33 [0.25, 0.42] | 100% | 0.41 [0.30, 0.50] | 100% | min_cluster_size=10; min_lift=3.0; selection=leaf | 300 |
| 10 | Find genes whose label their neighbours contradict | AUROC of surprise for the swapped labels | reliable | 0.64 [0.49, 0.77] | 100% | 0.65 [0.51, 0.78] | 100% | k=15 | 75 |
| 11 | Diffuse a label across one measured network | correct calls per hidden gene | reliable | 0.12 [0.08, 0.17] | 75% | 0.14 [0.10, 0.18] | 88% | layer=coexpression; restart=0.2 | 900 |
| 12 | Let every network vote, weighted by what it has earned | correct calls per hidden gene | weak | 0.30 [-0.04, 0.54] | 80% | 0.26 [-0.18, 0.52] | 90% | k=5 | 75 |
| 13 | Place a protein by the proteins it physically touches | correct calls per hidden gene | reliable | 0.25 [0.08, 0.43] | 60% | 0.26 [0.08, 0.43] | 60% | -- | 25 |
| 14 | Annotate function through shared fold | correct calls per hidden gene | reliable | 0.64 [0.60, 0.66] | 100% | 0.71 [0.71, 0.72] | 100% | level=3 | 15 |
| 15 | Find the communities several networks agree on | F1 of hidden genes in the community chosen for their label on known genes | weak | 0.05 [0.02, 0.08] | 40% | 0.05 [-0.00, 0.09] | 40% | agreement=0.5; resolution=1.0 | 150 |
| 16 | Predict the contacts an interactome missed | AUROC of hidden pairs against degree-matched non-pairs | reliable | 0.61 [0.59, 0.62] | 100% | 0.93 [0.92, 0.93] | 100% | layer=struct | 10 |
| 17 | Read the literature for biology, not fame | share of the top 50 corrected pairs sharing a compartment label | reliable | 0.38 [0.21, 0.55] | 80% | 0.38 [0.21, 0.55] | 80% | top=200 | 75 |
| 18 | List what the data says and the literature has not written | AUROC of hidden pairs against random non-pairs | reliable | 0.11 [0.11, 0.11] | 100% | 0.11 [0.11, 0.11] | 100% | min_layers=1 | 15 |
| 19 | Train a classifier on the known genes and call the rest | correct calls per hidden gene | reliable | 0.32 [0.18, 0.46] | 80% | 0.37 [0.21, 0.50] | 80% | C=10.0 | 100 |
| 20 | Learn what makes your list special, from positives alone | AUROC of hidden members against every other gene | reliable | 0.79 [0.72, 0.85] | 100% | 0.80 [0.74, 0.85] | 100% | bags=5 | 75 |
| 21 | Predict a measurement, and find the genes that defy the prediction | rank correlation of predicted and hidden values | reliable | 0.56 [0.05, 0.91] | 67% | 0.67 [0.15, 0.97] | 100% | model=boosted; own_kind=include | 60 |
| 22 | Fill in what was never measured, and say where that is honest | median per-column rank correlation on hidden entries | reliable | 0.87 [0.86, 0.87] | 100% | 0.90 [0.90, 0.90] | 100% | rank=60 | 15 |
| 23 | Find what matters more in one condition, and why | rank correlation of predicted and hidden values | weak | 0.07 [0.06, 0.09] | 0% | 0.07 [0.05, 0.08] | 0% | model=ridge; own_kind=include | 20 |
| 24 | Describe what your gene list has in common | AUROC of hidden members against every other gene | reliable | 0.61 [0.51, 0.72] | 100% | 0.64 [0.52, 0.75] | 100% | -- | 25 |
| 25 | Grow your gene list along the networks | AUROC of hidden members against every other gene | reliable | 0.59 [0.49, 0.68] | 100% | 0.61 [0.53, 0.67] | 100% | mode=networks + measurements; restart=0.6 | 150 |
| 26 | Find categories that split in two on another measurement | share of findings that replicate | untestable | -- | -- | -- | -- | -- | 15 |
| 27 | Find kinds of gene defined by two labels at once | share of first-half findings that replicate on the second half | reliable | 0.49 [0.38, 0.62] | 100% | 0.53 [0.32, 0.74] | 100% | min_cluster_size=15 | 15 |
| 28 | Find paralogs that changed jobs | AUROC of profile divergence for paralogs with different compartment | reliable | 0.16 [0.06, 0.31] | 60% | 0.16 [0.06, 0.31] | 62% | min_shared=10 | 75 |
| 29 | Carry what one parasite shows to the other | rank correlation of transferred and hidden values | reliable | 0.31 [0.30, 0.33] | 100% | 0.32 [0.29, 0.35] | 100% | -- | 5 |
| 30 | Test inference on the genes orthology cannot reach | correct calls per hidden gene | reliable | 0.26 [0.15, 0.34] | 75% | 0.28 [0.17, 0.36] | 75% | stratum=lineage-specific | 100 |
| 31 | Call a gene only when independent strategies agree | precision of calls on hidden genes | reliable | 0.35 [0.16, 0.48] | 60% | 0.61 [0.33, 0.77] | 80% | min_agree=3 | 75 |
| 32 | Put the understudied genes first | precision of calls on hidden genes | reliable | 0.32 [0.15, 0.46] | 60% | 0.59 [0.32, 0.75] | 80% | min_agree=3 | 75 |
| 33 | Put every layer into one space and read a gene's neighbourhood | AUROC of hidden coexpression edges against degree-matched non-pairs | reliable | 0.59 [0.58, 0.59] | 100% | 0.90 [0.86, 0.94] | 100% | k=5; knn=5; layer=cotranslation | 150 |
| 34 | Train on the networks and rank the edges they are missing | AUROC of hidden coexpression edges against degree-matched non-pairs | reliable | 0.59 [0.58, 0.59] | 100% | 0.88 [0.88, 0.88] | 100% | fraction=0.4; layer=cotranslation; model=logistic | 100 |
P. falciparum -- 20 reliable, 8 weak, 3 works when tuned, 2 untestable, 1 no skill
| # | Strategy | Metric | Grade | Skill at defaults [95% CI] | Pass | Skill tuned [95% CI] | Pass | Tuned setting | Tests |
|---|---|---|---|---|---|---|---|---|---|
| 01 | Hold out a category and search for a map that finds it | F1 of hidden genes in the cluster chosen for their label on known genes | weak | 0.08 [-0.00, 0.22] | 0% | 0.03 [-0.00, 0.07] | 0% | min_cluster_size=[20, 50]; n_neighbors=[10, 30]; selection=[eom, leaf] | 90 |
| 02 | Find the map where your gene list is one cluster | F1 of the hidden members against the best cluster's other genes | reliable | 0.24 [0.06, 0.43] | 87% | 0.26 [0.04, 0.52] | 67% | min_cluster_size=[10, 25]; n_neighbors=[10, 30] | 60 |
| 03 | Ask which categories the data can rediscover | hidden-gene AUROC of the categories the atlas ranks in its top half | reliable | 0.62 [0.49, 0.76] | 100% | 0.62 [0.54, 0.70] | 100% | k=50 | 45 |
| 04 | Keep only the modules that survive the whole walk | F1 of hidden genes in the module chosen for their label on known genes | weak | 0.14 [0.02, 0.32] | 13% | 0.18 [0.02, 0.43] | 17% | threshold=0.5 | 45 |
| 05 | Tune a map without labels, then read what it encodes | share of first-half findings that replicate on the second half | reliable | 0.95 [0.89, 0.99] | 100% | 0.96 [0.95, 0.97] | 100% | map_from=polysomal | 195 |
| 06 | Find which kind of evidence carries a label | hidden accuracy of the evidence ranked first (expr) | works when tuned | 0.11 [0.04, 0.18] | 53% | 0.12 [0.05, 0.19] | 67% | k=5 | 45 |
| 07 | Call a gene by the genes that behave like it | correct calls per hidden gene | weak | -0.02 [-0.52, 0.36] | 40% | 0.24 [0.02, 0.39] | 67% | k=5; min_share=0.0 | 135 |
| 08 | Call a gene by its neighbours on the map | correct calls per hidden gene | weak | -0.13 [-0.78, 0.27] | 53% | 0.19 [0.02, 0.34] | 67% | k=5; n_neighbors=10 | 135 |
| 09 | Name a cluster by the label it is enriched for | precision of calls on hidden genes | reliable | 0.53 [0.28, 0.77] | 100% | 0.62 [0.18, 0.86] | 100% | min_cluster_size=10; min_lift=1.5; selection=leaf | 180 |
| 10 | Find genes whose label their neighbours contradict | AUROC of surprise for the swapped labels | reliable | 0.76 [0.51, 0.99] | 100% | 0.78 [0.52, 0.99] | 100% | k=5 | 45 |
| 11 | Diffuse a label across one measured network | correct calls per hidden gene | reliable | 0.26 [0.16, 0.40] | 90% | 0.30 [0.14, 0.46] | 100% | layer=coexpression; restart=0.2 | 360 |
| 12 | Let every network vote, weighted by what it has earned | correct calls per hidden gene | reliable | 0.49 [0.35, 0.64] | 73% | 0.37 [0.10, 0.64] | 67% | k=15 | 45 |
| 13 | Place a protein by the proteins it physically touches | correct calls per hidden gene | weak | 0.08 [-0.04, 0.24] | 0% | 0.05 [0.02, 0.10] | 0% | -- | 15 |
| 14 | Annotate function through shared fold | correct calls per hidden gene | reliable | 0.59 [0.54, 0.61] | 100% | 0.59 [0.56, 0.61] | 100% | level=2 | 15 |
| 15 | Find the communities several networks agree on | F1 of hidden genes in the community chosen for their label on known genes | weak | 0.01 [-0.04, 0.09] | 33% | 0.04 [-0.01, 0.09] | 33% | agreement=0.3; resolution=2.0 | 90 |
| 16 | Predict the contacts an interactome missed | AUROC of hidden pairs against degree-matched non-pairs | reliable | 0.96 [0.96, 0.96] | 100% | 0.96 [0.96, 0.96] | 100% | layer=struct | 5 |
| 17 | Read the literature for biology, not fame | share of the top 22 corrected pairs sharing a pb_transferred_phenotype label | weak | 0.26 [0.21, 0.30] | 10% | 0.26 [0.20, 0.31] | 0% | top=1000 | 45 |
| 18 | List what the data says and the literature has not written | AUROC of hidden pairs against random non-pairs | reliable | 0.11 [0.11, 0.11] | 100% | 0.11 [0.11, 0.11] | 100% | min_layers=1 | 15 |
| 19 | Train a classifier on the known genes and call the rest | correct calls per hidden gene | reliable | 0.39 [0.34, 0.44] | 100% | 0.40 [0.31, 0.50] | 100% | C=0.01 | 60 |
| 20 | Learn what makes your list special, from positives alone | AUROC of hidden members against every other gene | reliable | 0.89 [0.77, 1.00] | 100% | 0.90 [0.79, 1.00] | 100% | bags=15 | 45 |
| 21 | Predict a measurement, and find the genes that defy the prediction | rank correlation of predicted and hidden values | reliable | 0.52 [0.25, 0.84] | 100% | 0.52 [0.28, 0.84] | 100% | model=boosted; own_kind=include | 60 |
| 22 | Fill in what was never measured, and say where that is honest | median per-column rank correlation on hidden entries | reliable | 0.70 [0.69, 0.71] | 100% | 0.70 [0.70, 0.71] | 100% | rank=20 | 15 |
| 23 | Find what matters more in one condition, and why | rank correlation of predicted and hidden values | reliable | 0.64 [0.64, 0.65] | 100% | 0.65 [0.65, 0.65] | 100% | model=boosted; own_kind=include | 20 |
| 24 | Describe what your gene list has in common | AUROC of hidden members against every other gene | reliable | 0.85 [0.70, 0.95] | 100% | 0.84 [0.71, 0.95] | 100% | -- | 15 |
| 25 | Grow your gene list along the networks | AUROC of hidden members against every other gene | reliable | 0.86 [0.69, 0.99] | 100% | 0.85 [0.67, 0.99] | 100% | mode=networks + measurements; restart=0.6 | 90 |
| 26 | Find categories that split in two on another measurement | share of findings that replicate | untestable | -- | -- | -- | -- | -- | 15 |
| 27 | Find kinds of gene defined by two labels at once | share of findings that replicate | untestable | -- | -- | -- | -- | -- | 15 |
| 28 | Find paralogs that changed jobs | AUROC of profile divergence for paralogs with different pb_transferred_phenotype | no skill | -0.02 [-0.16, 0.12] | 50% | -0.02 [-0.15, 0.11] | 50% | min_shared=10 | 45 |
| 29 | Carry what one parasite shows to the other | rank correlation of transferred and hidden values | reliable | 0.31 [0.30, 0.33] | 100% | 0.32 [0.31, 0.33] | 100% | -- | 5 |
| 30 | Test inference on the genes orthology cannot reach | correct calls per hidden gene | weak | -0.02 [-0.02, -0.02] | 0% | 0.15 [-0.02, 0.37] | 50% | stratum=conserved | 60 |
| 31 | Call a gene only when independent strategies agree | precision of calls on hidden genes | works when tuned | 0.15 [-0.46, 0.52] | 67% | 0.67 [0.51, 0.83] | 50% | min_agree=3 | 45 |
| 32 | Put the understudied genes first | precision of calls on hidden genes | works when tuned | 0.06 [-0.62, 0.46] | 60% | 0.64 [0.48, 0.88] | 50% | min_agree=3 | 45 |
| 33 | Put every layer into one space and read a gene's neighbourhood | AUROC of hidden coexpression edges against degree-matched non-pairs | reliable | 0.39 [0.37, 0.41] | 100% | 0.75 [0.68, 0.82] | 100% | k=5; knn=15; layer=struct | 90 |
| 34 | Train on the networks and rank the edges they are missing | AUROC of hidden coexpression edges against degree-matched non-pairs | reliable | 0.39 [0.37, 0.41] | 100% | 0.73 [0.71, 0.75] | 100% | fraction=0.4; layer=struct; model=logistic | 60 |
All 34 strategies, with their tests and measured verdicts
Guided workflows · Local AF3 structures · Protein sequence features
Working with spaCR
spaCR handles microscopy and image-based screen analysis. Its Starplast launcher installs and opens this app in a separate Python environment. Starplast provides a place to explore the biological evidence around those screen results. Export a gene-level table from spaCR and import it into Starplast; launching the app does not transfer results automatically.
Data and reproducibility
Full table of included data and source links →
The catalogue lists all 130 registered datasets and computed layers, with their measurements, coverage, publication references, and links to source data or inputs. Coverage differs by organism and assay; absence from a literature search does not establish that a gene has never been studied.
python -m starplast.paths       # show data locations and missing cache files
python -m starplast.build_graph # rebuild from available source datasets
| Variable | Purpose |
|---|---|
STARPLAST_CACHE |
Override the directory containing built gene tables and graphs |
STARPLAST_DATA |
Locate raw datasets used for rebuilding |
STARPLAST_STATE |
Override the directory for saved runs, annotations, and downloads |
Methods are described in MATERIALS_AND_METHODS.md. HANDOFF.md contains the development history and earlier design decisions. The repository review describes the current architecture and its limitations.
Development
pip install -e ".[dev,docs]"
QT_QPA_PLATFORM=offscreen pytest tests/test_app_smoke.py tests/test_docstrings.py -q
python scripts/build_docs.py
Open docs/site/index.html for the guide and generated API reference.
Some tests need source datasets, CUDA, or a working OpenGL context; see
development and releases for the release checks.
Develop on nightly and merge checked changes into main. To release, update all
package and runtime versions together with python scripts/release.py bump 0.43.0 and update
the changelog before merging. A version increase on main triggers checks,
builds, PyPI publishing, and a GitHub release. Ordinary merges do not publish.
The initial PyPI account setup is described in the release guide.
The source code is distributed under the MIT license. Source datasets and third-party artwork retain their own licenses and attribution.
1 maintainer

Metadata
1 maintainer
Release files for starplast 0.45.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| starplast-0.45.0.tar.gz | 53.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| starplast-0.45.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 105.5 MB
Release files / starplast-0.45.0.tar.gz
| Download URL | starplast-0.45.0.tar.gz |
|---|---|
| Size | 53.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4bdf826770ae10ab7741cee2722b9c4c768301eec3e06f5ad9513dea43f43f8d
|
|
BLAKE2b-256 checksum How to use checksums |
f76558f855f23f6ff16c19885dc0c4e654b1e7d48da08d5c90a90505d39cff81
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / starplast-0.45.0-py3-none-any.whl
| Download URL | starplast-0.45.0-py3-none-any.whl |
|---|---|
| Size | 52.6 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0fcae87a13a9107567277568687d6419e4263f673634e487c494c429a88feca0
|
|
BLAKE2b-256 checksum How to use checksums |
dbcee086b427ec156cf7024e77368e9f23f55bd3dc4895995cdc6c0d27988558
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













