
High performance client for Baseten.co
This library provides a high-performance Python client for Baseten.co endpoints including embeddings, reranking, and classification. It was built for massive concurrent post requests to any URL, also outside of baseten.co. PerformanceClient releases the GIL while performing requests in the Rust, and supports simultaneous sync and async usage. It was benchmarked with >1200 rps per client in our blog. PerformanceClient is built on top of pyo3, reqwest and tokio and is MIT licensed.
Installation
pip install baseten_performance_client
Usage
import os
import asyncio
from baseten_performance_client import PerformanceClient, OpenAIEmbeddingsResponse, RerankResponse, ClassificationResponse

api_key = os.environ.get("BASETEN_API_KEY")
base_url_embed = "https://model-yqv4yjjq.api.baseten.co/environments/production/sync"
# Also works with OpenAI or Mixedbread.
# base_url_embed = "https://api.openai.com" or "https://api.mixedbread.com"

# Basic client setup
client = PerformanceClient(base_url=base_url_embed, api_key=api_key)

# Advanced setup with HTTP version selection and connection pooling
from baseten_performance_client import HttpClientWrapper
http_wrapper = HttpClientWrapper(http_version=1)  # HTTP/1.1 (default)
advanced_client = PerformanceClient(
    base_url=base_url_embed,
    api_key=api_key,
    http_version=1,  # HTTP/1.1
    client_wrapper=http_wrapper  # Share connection pool
)
Embeddings
Synchronous Embedding
from baseten_performance_client import RequestProcessingPreference

texts = ["Hello world", "Example text", "Another sample"]
preference = RequestProcessingPreference(
    batch_size=16,
    max_concurrent_requests=32,
    timeout_s=360,
    max_chars_per_request=256000,  # Character limit per request
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360  # Total operation timeout
)
response = client.embed(
    input=texts,
    model="my_model",
    preference=preference
)

# Accessing embedding data
print(f"Model used: {response.model}")
print(f"Total tokens used: {response.usage.total_tokens}")
print(f"Total time: {response.total_time:.4f}s")
if response.individual_batch_request_times:
    for i, batch_time in enumerate(response.individual_batch_request_times):
        print(f"  Time for batch {i}: {batch_time:.4f}s")

for i, embedding_data in enumerate(response.data):
    print(f"Embedding for text {i} (original input index {embedding_data.index}):")
    # embedding_data.embedding can be List[float] or str (base64)
    if isinstance(embedding_data.embedding, list):
        print(f"  First 3 dimensions: {embedding_data.embedding[:3]}")
        print(f"  Length: {len(embedding_data.embedding)}")

# Using the numpy() method (requires numpy to be installed)
import numpy as np
numpy_array = response.numpy()
print("\nEmbeddings as NumPy array:")
print(f"  Shape: {numpy_array.shape}")
print(f"  Data type: {numpy_array.dtype}")
if numpy_array.shape[0] > 0:
    print(f"  First 3 dimensions of the first embedding: {numpy_array[0][:3]}")
Note: The embed method is versatile and can be used with any embeddings service, e.g. OpenAI API embeddings, not just for Baseten deployments.
Asynchronous Embedding
async def async_embed():
    from baseten_performance_client import RequestProcessingPreference

    texts = ["Async hello", "Async example"]
    preference = RequestProcessingPreference(
        batch_size=16,
        max_concurrent_requests=32,
        timeout_s=360,
        max_chars_per_request=256000,  # Character limit per request
        hedge_delay=0.5,  # Enable hedging with 0.5s delay
        total_timeout_s=360  # Total operation timeout
    )
    response = await client.async_embed(
        input=texts,
        model="my_model",
        preference=preference
    )
    print("Async embedding response:", response.data)

# To run:
# asyncio.run(async_embed())
Embedding Benchmarks
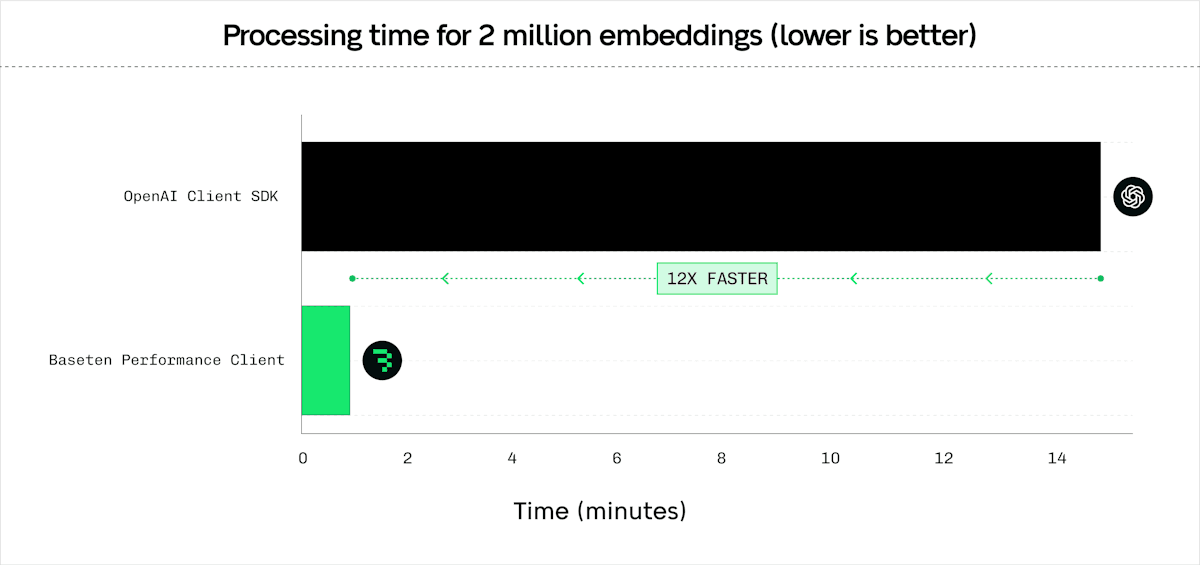
Comparison against pip install openai for /v1/embeddings. Tested with the ./scripts/compare_latency_openai.py with mini_batch_size of 128, and 4 server-side replicas. Results with OpenAI similar, OpenAI allows a max mini_batch_size of 2048.
| Number of inputs / embeddings | Number of Tasks | PerformanceClient (s) | AsyncOpenAI (s) | Speedup |
|---|---|---|---|---|
| 128 | 1 | 0.12 | 0.13 | 1.08× |
| 512 | 4 | 0.14 | 0.21 | 1.50× |
| 8 192 | 64 | 0.83 | 1.95 | 2.35× |
| 131 072 | 1 024 | 4.63 | 39.07 | 8.44× |
| 2 097 152 | 16 384 | 70.92 | 903.68 | 12.74× |
General Batch POST
The batch_post method is generic. It can be used to send POST requests to any URL, not limited to Baseten endpoints. The input and output can be any JSON item.
Synchronous Batch POST
from baseten_performance_client import RequestProcessingPreference

payload1 = {"model": "my_model", "input": ["Batch request sample 1"]}
payload2 = {"model": "my_model", "input": ["Batch request sample 2"]}
preference = RequestProcessingPreference(
    max_concurrent_requests=32,
    timeout_s=360,
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360,  # Total operation timeout
    extra_headers={"x-custom-header": "value"}  # Custom headers
)
response_obj = client.batch_post(
    url_path="/v1/embeddings", # Example path, adjust to your needs
    payloads=[payload1, payload2],
    preference=preference
)
print(f"Total time for batch POST: {response_obj.total_time:.4f}s")
for i, (resp_data, headers, time_taken) in enumerate(zip(response_obj.data, response_obj.response_headers, response_obj.individual_request_times)):
    print(f"Response {i+1}:")
    print(f"  Data: {resp_data}")
    print(f"  Headers: {headers}")
    print(f"  Time taken: {time_taken:.4f}s")
Asynchronous Batch POST
async def async_batch_post_example():
    from baseten_performance_client import RequestProcessingPreference

    payload1 = {"model": "my_model", "input": ["Async batch sample 1"]}
    payload2 = {"model": "my_model", "input": ["Async batch sample 2"]}
preference = RequestProcessingPreference(
    max_concurrent_requests=32,
    timeout_s=360,
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360,  # Total operation timeout
    extra_headers={"x-custom-header": "value"}  # Custom headers
)
    response_obj = await client.async_batch_post(
        url_path="/v1/embeddings",
        payloads=[payload1, payload2],
        preference=preference
    )
    print(f"Async total time for batch POST: {response_obj.total_time:.4f}s")
    for i, (resp_data, headers, time_taken) in enumerate(zip(response_obj.data, response_obj.response_headers, response_obj.individual_request_times)):
        print(f"Async Response {i+1}:")
        print(f"  Data: {resp_data}")
        print(f"  Headers: {headers}")
        print(f"  Time taken: {time_taken:.4f}s")

# To run:
# asyncio.run(async_batch_post_example())
Reranking
Reranking compatible with BEI or text-embeddings-inference.
Synchronous Reranking
from baseten_performance_client import RequestProcessingPreference

query = "What is the best framework?"
documents = ["Doc 1 text", "Doc 2 text", "Doc 3 text"]
preference = RequestProcessingPreference(
    batch_size=16,
    max_concurrent_requests=32,
    timeout_s=360,
    max_chars_per_request=256000,  # Character limit per request
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360  # Total operation timeout
)
rerank_response = client.rerank(
    query=query,
    texts=documents,
    model="rerank-model",  # Optional model specification
    return_text=True,
    preference=preference
)
for res in rerank_response.data:
    print(f"Index: {res.index} Score: {res.score}")
Asynchronous Reranking
async def async_rerank():
    from baseten_performance_client import RequestProcessingPreference

    query = "Async query sample"
    docs = ["Async doc1", "Async doc2"]
    preference = RequestProcessingPreference(
        batch_size=16,
        max_concurrent_requests=32,
        timeout_s=360,
        max_chars_per_request=256000,  # Character limit per request
        hedge_delay=0.5,  # Enable hedging with 0.5s delay
        total_timeout_s=360  # Total operation timeout
    )
    response = await client.async_rerank(
        query=query,
        texts=docs,
        model="rerank-model",  # Optional model specification
        return_text=True,
        preference=preference
    )
    for res in response.data:
        print(f"Async Index: {res.index} Score: {res.score}")

# To run:
# asyncio.run(async_rerank())
Classification
Predict (classification endpoint) compatible with BEI or text-embeddings-inference.
Synchronous Classification
from baseten_performance_client import RequestProcessingPreference

texts_to_classify = [
    "This is great!",
    "I did not like it.",
    "Neutral experience."
]
preference = RequestProcessingPreference(
    batch_size=16,
    max_concurrent_requests=32,
    timeout_s=360,
    max_chars_per_request=256000,  # Character limit per request
    hedge_delay=0.5,  # Enable hedging with 0.5s delay
    total_timeout_s=360  # Total operation timeout
)
classify_response = client.classify(
    inputs=texts_to_classify,
    model="classification-model",  # Optional model specification
    preference=preference
)
for group in classify_response.data:
    for result in group:
        print(f"Label: {result.label}, Score: {result.score}")
Asynchronous Classification
async def async_classify():
    from baseten_performance_client import RequestProcessingPreference

    texts = ["Async positive", "Async negative"]
    preference = RequestProcessingPreference(
        batch_size=16,
        max_concurrent_requests=32,
        timeout_s=360,
        max_chars_per_request=256000,  # Character limit per request
        hedge_delay=0.5,  # Enable hedging with 0.5s delay
        total_timeout_s=360  # Total operation timeout
    )
    response = await client.async_classify(
        inputs=texts,
        model="classification-model",  # Optional model specification
        preference=preference
    )
    for group in response.data:
        for res in group:
            print(f"Async Label: {res.label}, Score: {res.score}")

# To run:
# asyncio.run(async_classify())
Advanced Features
RequestProcessingPreference
The RequestProcessingPreference class provides a unified way to configure all request processing parameters. This is the recommended approach for advanced configuration as it provides better type safety and clearer intent.
The framework defaults are 256 concurrent requests, a batch size of 8, and 8,000 characters per request. max_chars_per_request accepts values from 50 through 1,048,576.
from baseten_performance_client import RequestProcessingPreference

# Create a preference with custom settings
preference = RequestProcessingPreference(
    max_concurrent_requests=64,        # Parallel requests (default: 256)
    batch_size=32,                     # Items per batch (default: 8)
    timeout_s=30.0,                   # Per-request timeout (default: 3600.0)
    hedge_delay=0.5,                  # Hedging delay (default: None)
    hedge_budget_pct=0.15,            # Hedge budget percentage (default: 0.10)
    retry_budget_pct=0.08,            # Retry budget percentage (default: 0.05)
    max_retries=5,                    # Maximum HTTP retries (default: 5)
    initial_backoff_ms=250,           # Initial backoff in milliseconds (default: 125)
    total_timeout_s=300.0              # Total operation timeout (default: None)
)

# Use with any method
response = client.embed(
    input=["text1", "text2"],
    model="my_model",
    preference=preference
)

# Also works with async methods
response = await client.async_embed(
    input=["text1", "text2"],
    model="my_model",
    preference=preference
)
Property-based Configuration: You can also modify preferences after creation using property setters:
# Create preference and modify properties
preference = RequestProcessingPreference()
preference.max_concurrent_requests = 64        # Set parallel requests
preference.batch_size = 32                     # Set batch size
preference.timeout_s = 30.0                    # Set timeout
preference.hedge_delay = 0.5                   # Enable hedging
preference.hedge_budget_pct = 0.15            # Set hedge budget
preference.retry_budget_pct = 0.08            # Set retry budget
preference.max_retries = 3                     # Set max retries
preference.initial_backoff_ms = 250            # Set backoff

# Use with any method
response = client.embed(
    input=["text1", "text2"],
    model="my_model",
    preference=preference
)
Budget Percentages:
hedge_budget_pct: Percentage of total requests allocated for hedging (default: 10%)retry_budget_pct: Percentage of total requests allocated for retries (default: 5%)- Maximum allowed: 300% for both budgets
Retry Configuration:
- HTTP status-code retries are controlled by
max_retries, not byretry_budget_pct. - Retryable status codes by default:
408,409,429, and500through599. - Use
non_retryable_status_codes={529}to opt specific statuses out of the default retry policy. max_retries: Maximum HTTP status-code retries per request (default: 5, max: 6). Set to 0 to disable these retries.retry_budget_pct: Budget for timeout and network-error retry paths (default: 5%, max: 300%).initial_backoff_ms: Initial backoff duration in milliseconds (default: 125, range: 50-45000).- Backoff multiplies by 4 after each retry, caps at 45000ms, and adds 0-99ms jitter. With defaults, the retry sleeps are about 125ms, 500ms, 2000ms, 8000ms, and 32000ms; a sixth retry sleeps about 45000ms.
Request Hedging
The client supports request hedging for improved latency by sending duplicate requests after a specified delay:
# Enable hedging with 0.5 second delay
preference = RequestProcessingPreference(
    hedge_delay=0.5,  # Send hedge request after 0.5s
    max_chars_per_request=256000,
    total_timeout_s=360
)
response = client.embed(
    input=texts,
    model="my_model",
    preference=preference
)
Custom Headers
Use custom headers with batch_post:
preference = RequestProcessingPreference(
    extra_headers={
        "x-custom-header": "value",
        "authorization": "Bearer token"
    }
)
response = client.batch_post(
    url_path="/v1/embeddings",
    payloads=payloads,
    preference=preference
)
HTTP Version Selection
Choose between HTTP/1.1 and HTTP/2:
# HTTP/1.1 (default, better for high concurrency)
client_http1 = PerformanceClient(base_url, api_key, http_version=1)

# HTTP/2 (better for single requests)
client_http2 = PerformanceClient(base_url, api_key, http_version=2)
Connection Pooling
Share connection pools across multiple clients:
from baseten_performance_client import HttpClientWrapper

# Create shared wrapper
wrapper = HttpClientWrapper(http_version=1)

# Reuse across multiple clients
client1 = PerformanceClient(base_url="https://api1.example.com", client_wrapper=wrapper)
client2 = PerformanceClient(base_url="https://api2.example.com", client_wrapper=wrapper)
HTTP Proxy Support
Route all HTTP requests through a proxy (e.g., for connection pooling with Envoy):
from baseten_performance_client import HttpClientWrapper

# Create wrapper with HTTP proxy
wrapper = HttpClientWrapper(
    http_version=1,
    proxy="http://envoy-proxy.local:8080"
)

# Share the wrapper across multiple clients
client1 = PerformanceClient(
    base_url="https://api1.example.com",
    api_key="your_key",
    client_wrapper=wrapper
)
client2 = PerformanceClient(
    base_url="https://api2.example.com",
    api_key="your_key",
    client_wrapper=wrapper
)
# Both clients will use the same connection pool and proxy
You can also specify the proxy directly when creating a client:
client = PerformanceClient(
    base_url="https://api.example.com",
    api_key="your_key",
    proxy="http://envoy-proxy.local:8080"
)
Endpoint Pool and Health Checks
Route traffic across reusable endpoints with deterministic weighted routing. Each Endpoint
owns its own health worker, so the same endpoint object can be shared across many pools
without duplicate probes:
from baseten_performance_client import Endpoint, EndpointPool, HttpClientWrapper, PerformanceClient

health_wrapper = HttpClientWrapper(http_version=1)
endpoint_a = Endpoint(
    base_url="https://model-AAAA.api.baseten.co/environments/production/sync",
    api_key="your_key",
    client_wrapper=health_wrapper,
    deployment_health_path="/health",
    deployment_timeout_is_no_vote=False,
)
endpoint_b = Endpoint(
    base_url="https://model-BBBB.api.baseten.co/environments/production/sync",
    api_key="your_key",
    client_wrapper=health_wrapper,
    deployment_health_path="/health",
    deployment_timeout_is_no_vote=False,
)

endpoint_pool = EndpointPool(
    endpoints=[endpoint_a, endpoint_b],
    endpoint_weights=[0.8, 0.2],  # deterministic weighted routing
)

client = PerformanceClient(
    base_url="https://model-AAAA.api.baseten.co/environments/production/sync",
    api_key="your_key",
    endpoint_pool=endpoint_pool,
)
Health semantics:
- Weights are deterministic weighted routing, not weighted round robin.
- Each configured health check is retried up to
health_check_retries, and one successful retry is enough for that check. - If an endpoint has
deep_health_urlconfigured, both the shallow deployment health path and the deep health URL are evaluated. health_fail_on_first=Trueshort-circuits on the first hard failing check within an endpoint refresh cycle.
Error Handling
The client can raise several types of errors. Here's how to handle common ones:
requests.exceptions.HTTPError: This error is raised for HTTP issues, such as authentication failures (e.g., 401 Unauthorized if the API key is wrong), server errors (e.g., 5xx), or if the endpoint is not found (404). You can inspecte.response.status_codeande.response.text(ore.response.json()if the body is JSON) for more details.ValueError: This error can occur due to invalid input parameters (e.g., an emptyinputlist forembed, invalidbatch_sizeormax_concurrent_requestsvalues). It can also be raised byresponse.numpy()if embeddings are not float vectors or have inconsistent dimensions.
Here's an example demonstrating how to catch these errors for the embed method:
import requests
from baseten_performance_client import RequestProcessingPreference

# client = PerformanceClient(base_url="your_baseten_url", api_key="your_baseten_api_key")

texts_to_embed = ["Hello world", "Another text example"]
try:
    preference = RequestProcessingPreference(
        batch_size=2,
        max_concurrent_requests=4,
        timeout_s=60 # Timeout in seconds
    )
    response = client.embed(
        input=texts_to_embed,
        model="your_embedding_model", # Replace with your actual model name
        preference=preference
    )
    # Process successful response
    print(f"Model used: {response.model}")
    print(f"Total tokens: {response.usage.total_tokens}")
    for item in response.data:
        embedding_preview = item.embedding[:3] if isinstance(item.embedding, list) else "Base64 Data"
        print(f"Index {item.index}, Embedding (first 3 dims or type): {embedding_preview}")

except requests.exceptions.HTTPError as e:
    print(f"An HTTP error occurred: {e}, code {e.args[0]}")
For asynchronous methods (async_embed, async_rerank, async_classify, async_batch_post), the same exceptions will be raised by the await call and can be caught using a try...except block within an async def function.
Development
# Install prerequisites
sudo apt-get install patchelf
# Install cargo if not already installed.

# Set up a Python virtual environment
python -m venv .venv
source .venv/bin/activate

# Install development dependencies
pip install maturin[patchelf] pytest requests numpy

# Build and install the Rust extension in development mode
maturin develop
cargo fmt
# Run tests
pytest tests
Contributions
Feel free to contribute to this repo, tag @michaelfeil for review.
License
MIT License
System One decisions
Send independent requests to /v1/systemone; use a one-element list for one request.
requests = [{
    "state": "My invoice was charged twice.",
    "questions": {"route": {
        "type": "choice",
        "instructions": "Which team should handle this?",
        "criteria": {"billing": None, "support": None},
    }},
}]
response = client.batch_system_one(requests=requests)
print(response.data[0]["answers"]["route"])
# Async: await client.async_batch_system_one(requests=requests)
Add model or backend-specific fields to each request as needed. .data preserves
input order; the response also includes timings and headers. Existing request
preferences apply. Supported question types depend on the backend.
3 maintainers


Metadata
3 maintainers
Release files for baseten-performance-client 0.1.17
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| baseten_performance_client-0.1.17.tar.gz | 124.3 kB | Without provenance | Details for baseten_performance_client-0.1.17.tar.gz |
Built distributions (wheels)
Total release size: 119.6 MB
Release files / baseten_performance_client-0.1.17.tar.gz
| Download URL | baseten_performance_client-0.1.17.tar.gz |
|---|---|
| Size | 124.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5ac306ec20891079f2487b781e94b80288d5373725e7e33c41c58d5de5eaf1d1
|
|
BLAKE2b-256 checksum How to use checksums |
e91e4ac705837aaabd7384f1dc3397bc001f841de3db029b790e52b21c0bcc4f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_x86_64.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_x86_64.whl |
|---|---|
| Size | 6.4 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ x86-64 |
|
SHA-256 checksum How to use checksums |
8be94967098c1ac2dfb6a5095084572619af252b9f79156575cd236b9a9870ea
|
|
BLAKE2b-256 checksum How to use checksums |
c1d76bda46158e84ead2911efe3f9eba45e0ecb27cdf2481767a070e6ddbe7f8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_i686.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_i686.whl |
|---|---|
| Size | 6.2 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ x86-32 |
|
SHA-256 checksum How to use checksums |
5165676617a4303feb0039ef95cd244d522afb84d22df671d927041dee515706
|
|
BLAKE2b-256 checksum How to use checksums |
f9cc06b6ced17affcbd8eeb9dcec4a5267e9a4206a7bed5ac6d6dc67479d0b82
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_armv7l.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_armv7l.whl |
|---|---|
| Size | 5.7 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ ARMv7l |
|
SHA-256 checksum How to use checksums |
0171be575683616e5f5cfdd0aa67766aba75d5681f8af9d31936a55190f0a59a
|
|
BLAKE2b-256 checksum How to use checksums |
c49d6f650ba8b8f4931f279a2827839357bf6347b57bfd4552397acd5b199f93
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_aarch64.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-musllinux_1_2_aarch64.whl |
|---|---|
| Size | 6.7 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux musl 1.2+ ARM64 |
|
SHA-256 checksum How to use checksums |
101d4231ccf7c99f3e7950ece61096d58e7f301dde74d8829f85fa7ce32d1db2
|
|
BLAKE2b-256 checksum How to use checksums |
4370e774f23e8cbfc4df8f02b3733dae360af74bfef08bf94097d04bec18c5b3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 6.0 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
5e040a9c593c771f7e9d59531bd78b05f34929ee6dc7869d3a863c0011d2a0c3
|
|
BLAKE2b-256 checksum How to use checksums |
0f0397bb8a5d88b389990c36214997382ec46e468f4820c09d81791cdc7fde5b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl |
|---|---|
| Size | 6.7 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux glibc 2.17+ PowerPC 64-le |
|
SHA-256 checksum How to use checksums |
b67cff7e82725ddeeb1cc137199f50ac8d532db07d8f072f41195e31cdac0d93
|
|
BLAKE2b-256 checksum How to use checksums |
9c530aeb8bdbea43a8e7781f5582c5f328654c070f5feacb885a762814a53827
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-manylinux_2_17_i686.manylinux2014_i686.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-manylinux_2_17_i686.manylinux2014_i686.whl |
|---|---|
| Size | 6.2 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading Linux glibc 2.17+ x86-32 |
|
SHA-256 checksum How to use checksums |
27af29e53686a25ef984f4ef45220b6846d147bc637b8548bb7e83f8298a0498
|
|
BLAKE2b-256 checksum How to use checksums |
52b9a392f1590cdd5db26e265816a087169ab45c877b077c981b90b413628bdc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-macosx_11_0_arm64.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-macosx_11_0_arm64.whl |
|---|---|
| Size | 3.5 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
8b832ba0b83eb145426c730fc48da3f0fbf5d602b2234330bcf2ab851ac4c43a
|
|
BLAKE2b-256 checksum How to use checksums |
7608a9db40ac024577812c6e67f37fff3c3ca21e4f7a3e5fbfc4b161492f340b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp313-cp313t-macosx_10_12_x86_64.whl
| Download URL | baseten_performance_client-0.1.17-cp313-cp313t-macosx_10_12_x86_64.whl |
|---|---|
| Size | 3.7 MB |
| Tags | CPython 3.13 CPython 3.13 free-threading macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
a5ba34544248f8dc8f1bdd55d572cacc77c74730cbe1b4191c8e55ba9f12dd77
|
|
BLAKE2b-256 checksum How to use checksums |
41950fb7de696c21243d20d9e10e4a1b443eaa92ac6956fbb2f9464490185a2a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-win_amd64.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-win_amd64.whl |
|---|---|
| Size | 3.5 MB |
| Tags | CPython 3.8 Windows x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
3af1b8d5937d7d248732e1ab34c17897f3d383838d3ff81c6c71cda91285e736
|
|
BLAKE2b-256 checksum How to use checksums |
85cdebffa666bdfb7a4e237f9e0b4ba95ad020624615420df1fcd93b7c3a19c1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_x86_64.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_x86_64.whl |
|---|---|
| Size | 6.6 MB |
| Tags | CPython 3.8 Linux musl 1.2+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
8b13e1edce3a4041dc4e03588f8faccdfe6ec88e30e46e47c838d39162146088
|
|
BLAKE2b-256 checksum How to use checksums |
f1d9b1085fbec6f5b3dbdb455e31187a465c91a03c2f2c6929f30e7597b846d4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_i686.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_i686.whl |
|---|---|
| Size | 6.4 MB |
| Tags | CPython 3.8 Linux musl 1.2+ x86-32 abi3 |
|
SHA-256 checksum How to use checksums |
ccf5b4f9c3ebdf402418538724810322b7248f8d3d01067218f99d0218d38113
|
|
BLAKE2b-256 checksum How to use checksums |
1ae2646ba755132f7e7ed53173df63ac226943a0eec041ea3a10047604a77d11
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_armv7l.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_armv7l.whl |
|---|---|
| Size | 5.9 MB |
| Tags | CPython 3.8 Linux musl 1.2+ ARMv7l abi3 |
|
SHA-256 checksum How to use checksums |
7274c2820456c4d4813a18085a3f66d8d1a4c414c6f4bd32a8d4e252b83be5d2
|
|
BLAKE2b-256 checksum How to use checksums |
7bd96d33fe1c0fd8988cd46cdcbda64663c427e08862553e247d1cb107313899
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_aarch64.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-musllinux_1_2_aarch64.whl |
|---|---|
| Size | 6.9 MB |
| Tags | CPython 3.8 Linux musl 1.2+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
ccf61993ab15370e3885931a209d6e4a01c8c31be34e02e6a31756cece735f83
|
|
BLAKE2b-256 checksum How to use checksums |
1ce8e59e2d830e7dff65a42c0420cf7b834c6deebd09ef240078f4a0beb741ec
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-manylinux_2_28_armv7l.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-manylinux_2_28_armv7l.whl |
|---|---|
| Size | 5.6 MB |
| Tags | CPython 3.8 Linux glibc 2.28+ ARMv7l abi3 |
|
SHA-256 checksum How to use checksums |
b3b147e50a8e9161e166efe628ee3d60ec1246b711b33168777d53a16799c426
|
|
BLAKE2b-256 checksum How to use checksums |
8626124c255fd38e9f40c153cd61ac3896664479116f8f06a01b69756ec632bf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-manylinux_2_28_aarch64.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-manylinux_2_28_aarch64.whl |
|---|---|
| Size | 6.5 MB |
| Tags | CPython 3.8 Linux glibc 2.28+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
44e81d01a38b705a8b6d40915aa92577d22a6247e4ccdac8a120c1b6f14757f9
|
|
BLAKE2b-256 checksum How to use checksums |
ab3a65d6a67393dd994cd4efc3ab5deb2636e0e1733dc8c9e878fe24368ee524
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-manylinux2014_x86_64.manylinux_2_17_x86_64.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-manylinux2014_x86_64.manylinux_2_17_x86_64.whl |
|---|---|
| Size | 6.2 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
d2313d9530fd23c5c826ec05a4f6b1ea5b7b87f971ddd9f552e134968ebfce67
|
|
BLAKE2b-256 checksum How to use checksums |
d8b1252b379f0df97433e192fd10e0683995567686d55ac38ae6615346a9351f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl |
|---|---|
| Size | 6.8 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ PowerPC 64-le abi3 |
|
SHA-256 checksum How to use checksums |
bfc6a59eab20e414408645ea18113d2e04c82fcec6918c83ae8f26416390745c
|
|
BLAKE2b-256 checksum How to use checksums |
0522acd158adeb7bab620cb96a1b06962f3d11f0770116175a680d9dc60f7ed3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-manylinux2014_i686.manylinux_2_17_i686.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-manylinux2014_i686.manylinux_2_17_i686.whl |
|---|---|
| Size | 6.4 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ x86-32 abi3 |
|
SHA-256 checksum How to use checksums |
9a3dd6c0438cc9fbe0254129ebbcc051204e6bf02d23d02f688a3ab4c927516a
|
|
BLAKE2b-256 checksum How to use checksums |
7d0cd9cdf0a55b021bd0e9639d7c04bed623b1f8a875db5c57ffe54071688d9b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-macosx_11_0_arm64.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 3.7 MB |
| Tags | CPython 3.8 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
7c6afe56b637ec9fdc87f448378a3a2979059c8aba687274668a5a8f21d3bb4d
|
|
BLAKE2b-256 checksum How to use checksums |
139890101d32e70684743432fe8d6e0a53b01f222fc4fb818f4a60636e4252c9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Release files / baseten_performance_client-0.1.17-cp38-abi3-macosx_10_12_x86_64.whl
| Download URL | baseten_performance_client-0.1.17-cp38-abi3-macosx_10_12_x86_64.whl |
|---|---|
| Size | 3.8 MB |
| Tags | CPython 3.8 abi3 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
dd3798d86ed0bb3a43e1c0cebee22fda38ede6716a6ccf88167e400e87302c07
|
|
BLAKE2b-256 checksum How to use checksums |
0592a608bfd7c717a5085b9f474b4be6916f8dd35ce3e7a75040f0439f64cc94
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
maturin/1.16.0
|
Security for baseten-performance-client 0.1.17
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














