
best-engine-ai-helper
Pick and pull the best local large language model (LLM) or vision-language model (VLM) for the hardware in the current machine.
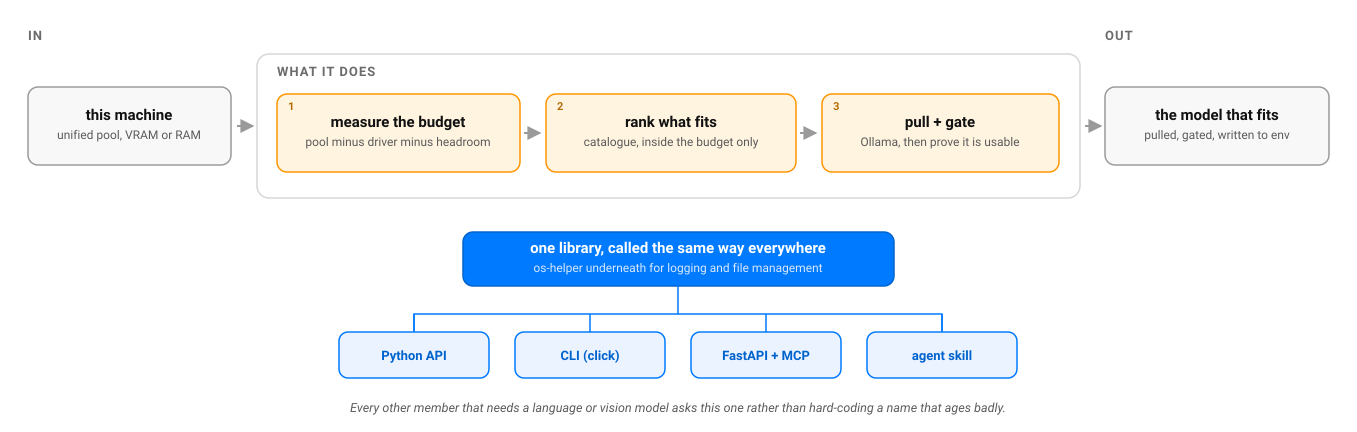
The tool detects available memory (Apple Silicon unified pool, NVIDIA VRAM, or system RAM), consults a bundled model catalog, and selects the highest-scoring model that fits within a configurable safety headroom. After selection, it pulls the model via Ollama and puts it through two quality gates before trusting it: does it catch and fix a known flaw seeded into a short text (the Ralph Loop), and does it spot an obvious visual defect seeded into a small test image (the Ralph Eyeball Loop)? Only a model that passes both gets its environment file written, the file downstream projects read to find the chosen model.
The Promise
best-engine-ai-helper is designed to run entirely offline once the weights
are downloaded. Two honest cases:
- Guaranteed local. Hardware detection, model selection, the quality gates, and writing the environment file all run on your machine. No telemetry, no account, no dependency on a cloud service.
- The only caveat: the initial download. The
pullcommand downloads the model weights via Ollama (a normal download from Ollama's servers). After that, everything runs offline. Refreshing the catalog (catalog update) is also online, but optional: the bundled catalog is enough for everyday use. Layer streaming follows the same rule: one download from the HuggingFace Hub, then the model runs from your own disk — in your own process, with no server at all.
A minimal browser GUI (best-engine-ai-helper gui) covers the read-only half
of this flow (the hardware snapshot and the task-to-engine recommendation)
without touching the terminal. The page is bilingual: French by default,
English via /gui?lang=en, with a header link to switch. See
GUI.md.
In production
This package sits at the base of the AI Helpers suite's model-selection layer, and the suite's rule is that any member needing an LLM or VLM resolves it through this package rather than hardcoding a model name — three published members (md2star, standpoint, vocal-helper) already do, and md2star is the reference implementation to copy. A model name written as a literal in another package is a bug there, not a shortcut: it survives the machine it was chosen on and nothing re-decides when the hardware changes. It ships on PyPI with a green CI gate on every push (ruff, mypy, and a pytest suite held above 90% coverage), and every release is a semantic-version tag on GitHub.
Documentation
Requirements
-
Python 3.10 or later
-
Ollama (needed for
pull,validate,env; not fordetect,recommend, orreport) -
Everything else installs automatically: os-helper (hardware detection), PyYAML, click, requests, langdetect and the FastAPI/MCP surfaces (
fastapi,uvicorn,fastapi-mcp). The CLI, GUI, HTTP API and MCP server are all part of the default install. It is a few megabytes and it installs in seconds. -
Running a model is opt-in; choosing one is not. The deep-learning runtime — torch, transformers, accelerate, safetensors, and diffusers for images — lives behind
[lightweight]and[imagine]. It was core for three days and the measurement is why it is not any more: that stack is 196 MB on a processor-only wheel and gigabytes ofnvidia-*payload when pip takes the CUDA build, which on Linux it does by default. Somebody asking which model fits their laptop should not download a deep-learning stack to be told.Nothing above that line needs it. The catalogues, the scoring, the hardware probe and the footprint and timing arithmetic behind
rank,imagine_rankandimagine_pickare plain Python over a table, and answer on an interpreter that has never heard of torch.detect,recommendandreportare as fast as they ever were, and now the install is too. -
Optional:
[cloud]for cloud-provider mode (retry, caching, pseudonymization, an OS-keychain fallback for API keys) and[filtered]for real NSFW classifiers (a DistilBERT text model; LAION's CLIP-based image detector, viatransformersfor the CLIP encoder and a bundledonnxruntimemodel for the classifier head). See Where the model runs below and EXAMPLES.md's paid-model section for the full story; both degrade gracefully (a keyword heuristic, or an "unavailable" verdict) when absent, never a hard failure.
How it works
Installation
Python 3.10+. This package's own code is pure Python, and so is its default
install: a few megabytes. The layer-streaming runtime brings torch with
it, but it lives behind [lightweight], so that ~2 GB download is paid only
if you ask for it. The other
platform-specific piece is the optional Ollama runtime (needed only for
pull / validate / env, not for detect, recommend, report, the GUI,
or the MCP surface). Pick your OS below.
🍎 macOS
# 1. Python 3.10+ (skip if you already have it: python3 --version)
brew install python

# 2. Install into an isolated virtual environment (recommended)
python3 -m venv .venv
source .venv/bin/activate
pip install --upgrade pip
pip install best-engine-ai-helper

# 3. Optional: Ollama, only if you'll run `pull`
brew install ollama          # then: ollama serve
Hardware detection uses the built-in system_profiler (Apple Silicon unified
memory), so nothing extra is needed.
🐧 Ubuntu / Debian
# 1. Python 3.10+ with venv support
sudo apt update
sudo apt install -y python3 python3-venv python3-pip

# 2. Install into an isolated virtual environment (recommended)
python3 -m venv .venv
source .venv/bin/activate
pip install --upgrade pip
pip install best-engine-ai-helper

# 3. Optional: Ollama, only if you'll run `pull`
curl -fsSL https://ollama.com/install.sh | sh   # then: ollama serve
GPU detection is automatic when the vendor tools are on PATH: nvidia-smi
(ships with the NVIDIA driver) for NVIDIA VRAM, rocm-smi (ROCm stack) for
AMD. With no GPU it falls back to system RAM.
🪟 Windows (PowerShell)
# 1. Python 3.10+ (skip if you already have it: py --version)
winget install Python.Python.3.12

# 2. Install into an isolated virtual environment (recommended)
py -m venv .venv
.\.venv\Scripts\Activate.ps1
python -m pip install --upgrade pip
pip install best-engine-ai-helper

# 3. Optional: Ollama, only if you'll run `pull`
winget install Ollama.Ollama
NVIDIA VRAM is detected via nvidia-smi (installed with the driver).
From source (any OS)
git clone https://github.com/warith-harchaoui/best-engine-ai-helper
cd best-engine-ai-helper
pip install -e .
Verify the install
best-engine-ai-helper --version
best-engine-ai-helper detect     # prints this machine's hardware as JSON
best-engine-ai-helper is the only command line this package ships: one
surface, built with click, which is a core dependency and not an optional
extra. Releases before 1.9.0 also installed a second, suffixed entry point
mirroring it command for command; there is one name now, and it is this one.
Quick start
# See what hardware this machine has
best-engine-ai-helper detect

# See which models would be selected (no download)
best-engine-ai-helper recommend

# Recommend the best engine(s) for a task, as a report (Markdown + JSON)
best-engine-ai-helper report --task "product descriptions and image-quality checks" --out engine

# Browse the full catalog
best-engine-ai-helper catalog show

# Browse the hardware chip table
best-engine-ai-helper hardware show

# Launch the browser GUI
best-engine-ai-helper gui

# Who's calling what, and at what cost (local SQLite ledger)
best-engine-ai-helper activity

# Nothing good fits? See what this machine could run by streaming layers off
# disk, and what the better model would cost you in seconds per token
best-engine-ai-helper lightweight compare --tokens 300

# Which text-to-image model runs here, and how long an image takes
best-engine-ai-helper imagine plan

# Serve all of it as an OpenAI-compatible endpoint: any OpenAI SDK, no code
# changes, and `model="best"` instead of a model name you had to choose
best-engine-ai-helper serve
The same /api/system, /api/recommend, and /api/activity endpoints are
also reachable as MCP tools for any MCP-aware agent host:
best-engine-ai-helper-mcp # -> http://127.0.0.1:8000 (MCP at /mcp)
See EXAMPLES.md for runnable recipes with expected output, and GUI.md for the browser GUI.
GUI
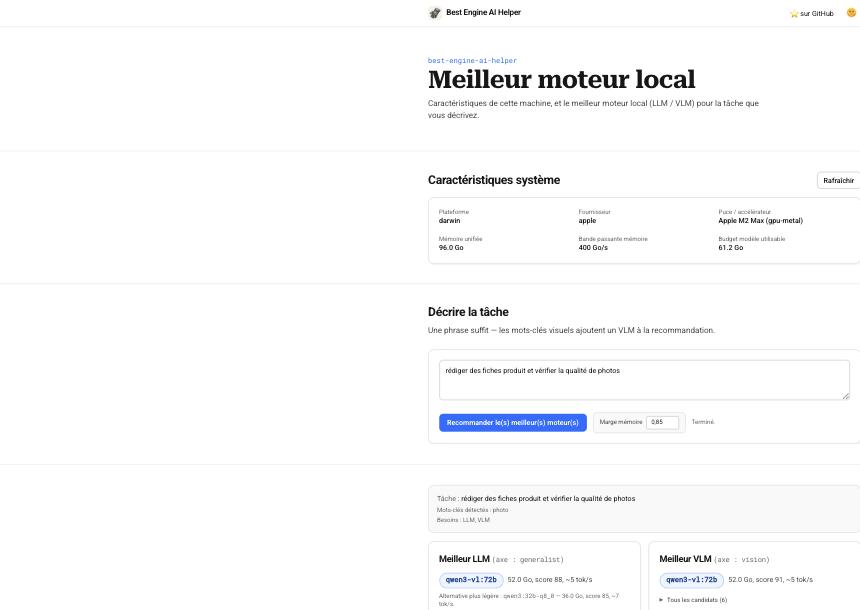
best-engine-ai-helper gui serves a single-page browser GUI (FastAPI +
vanilla JS, no build step) at http://127.0.0.1:8000/gui: the same hardware
snapshot as detect, and a task-description box that returns the same
recommendation as report, with no terminal needed. The page is bilingual
(French by default, English at /gui?lang=en), with a header link to switch.
See GUI.md for the full write-up, the JSON API it's built on, and
how the favicon / touch-icon set is generated from assets/logo.png.
Activity ledger
Every llm.chat() call, whether from this tool's own pull/validate gates
or from any downstream project that imports best_engine_ai_helper.llm, can
be recorded to a local, append-only SQLite ledger
(~/.best-engine-ai-helper/usage.db): who called it (BEST_ENGINE_USER env
var, else the OS login name), which model and backend, latency,
success/failure, and an estimated cost for paid backends (always 0.0 for
local Ollama/vLLM). Built for the "one company, several users on a shared
machine" case: answer "who is calling what, how often, at what cost" without
a separate telemetry stack. Local only, no network call, no third-party
service.
best-engine-ai-helper activity              # table
best-engine-ai-helper activity --format json
The CLI, GUI, and MCP server all enable recording by default; opt out with
BEST_ENGINE_NO_LEDGER=1. The GUI's Activity section and GET /api/activity
read the same ledger. See best_engine_ai_helper.observe for the library API
(enable(), as_user(name), Ledger.summary()).
How selection works
Selection weighs four factors, each made explicit in the report output so the
recommendation is reproducible and can be argued with. (One backend is judged on
different ones, because a different resource binds it: see layer
streaming below.)
The whole of it, before the detail:
flowchart LR
    CAT["the catalogue<br/>every LLM, VLM, embedder"]:::src
    G1{"1 · can a schema<br/>drive it?"}:::gate
    G2{"2 · does it fit<br/>the budget?"}:::gate
    G3["3 · best benchmark on<br/>the task's axis"]:::rank
    G4["4 · tokens/s · and a<br/>lighter near-equal<br/>when there is one"]:::rank
    PICK(["the pick<br/>every number printed"]):::out

    subgraph MACHINE["this machine, measured"]
        direction TB
        HW["unified · VRAM · RAM<br/>bandwidth · chip"]:::hw
        BUD["usable budget"]:::hw
        LIVE["--live: what runs<br/>on it right now"]:::opt
        HW --> BUD
        LIVE -. derates .-> BUD
    end

    ASIDE["ranked lower,<br/>never auto-picked<br/>still findable on request"]:::aside
    BIG["too large"]:::aside
    STREAM["lightweight:<br/>layers streamed off disk<br/>at seconds per token"]:::stream

    CAT --> G1
    G1 -- no --> ASIDE
    G1 -- yes --> G2
    BUD --> G2
    G2 -- no --> BIG
    G2 -- yes --> G3 --> G4 --> PICK
    BIG -. "nothing at all fits" .-> STREAM

    classDef hw fill:#CCE3F0,stroke:#0072B2,color:#000
    classDef opt fill:#DDF0FB,stroke:#56B4E9,color:#000
    classDef src fill:#FCFAD9,stroke:#E69F00,color:#000
    classDef gate fill:#FAECCC,stroke:#E69F00,color:#000
    classDef rank fill:#CCECE3,stroke:#009E73,color:#000
    classDef out fill:#CCECE3,stroke:#009E73,color:#000,stroke-width:3px
    classDef aside fill:#F5E4ED,stroke:#CC79A7,color:#000
    classDef stream fill:#F7DFCC,stroke:#D55E00,color:#000
    style MACHINE fill:#F8F8F8,stroke:#808080,color:#000
Two gates reject, two rankings order, and the only thing the machine
itself contributes is one number: the budget a candidate's ram_gb has to
land under.
1. Structured-output capability (can it be driven by a schema?)
The AI-Helpers suite routes every task through a JSON schema (intent parsing,
edit proposals, visual critique). Some open-weight models cannot honour Ollama's
grammar-constrained structured output and return an empty response under it (the
Qwen3-VL family does this, verified on qwen3-vl:8b). A model marked
structured_output: false in the catalog is never auto-selected, however high
its raw benchmark, and it still appears lower in the ranked list so an explicit
non-schema task can find it. Entries with no such marker are assumed capable.
2. Memory fit (will it run on the accelerator?)
Available memory comes from the highest-priority probe that succeeds: Apple
Silicon unified memory (system_profiler), NVIDIA VRAM (nvidia-smi), AMD VRAM
(rocm-smi), else half of system RAM as a conservative CPU-only estimate.
The usable budget is not the whole pool. On Apple Silicon, Metal caps GPU
allocations at about 66% of unified memory at or below 36 GB and about
75% above it (recommendedMaxWorkingSetSize); past that, work spills to the
CPU and slows sharply. An extra safety headroom (default 0.5, the hard
ceiling: a larger value is clamped down to it) is applied
on top, reserving room for the OS, your own application, and a model's own
working memory: as a conversation or prompt gets longer, a model keeps a
running cache of everything it has already read so it does not recompute it
on every new word (the KV cache), and that cache keeps growing as context
fills. A catalog entry's ram_gb is already a peak-inference estimate
(weights plus a moderate KV cache; roughly weights ÷ 0.7, since weights are only
about 70% of runtime memory and can approach 2× at long context). A model fits
when that ram_gb is at most the budget.
On the machine this was written on, that arithmetic comes out like this:
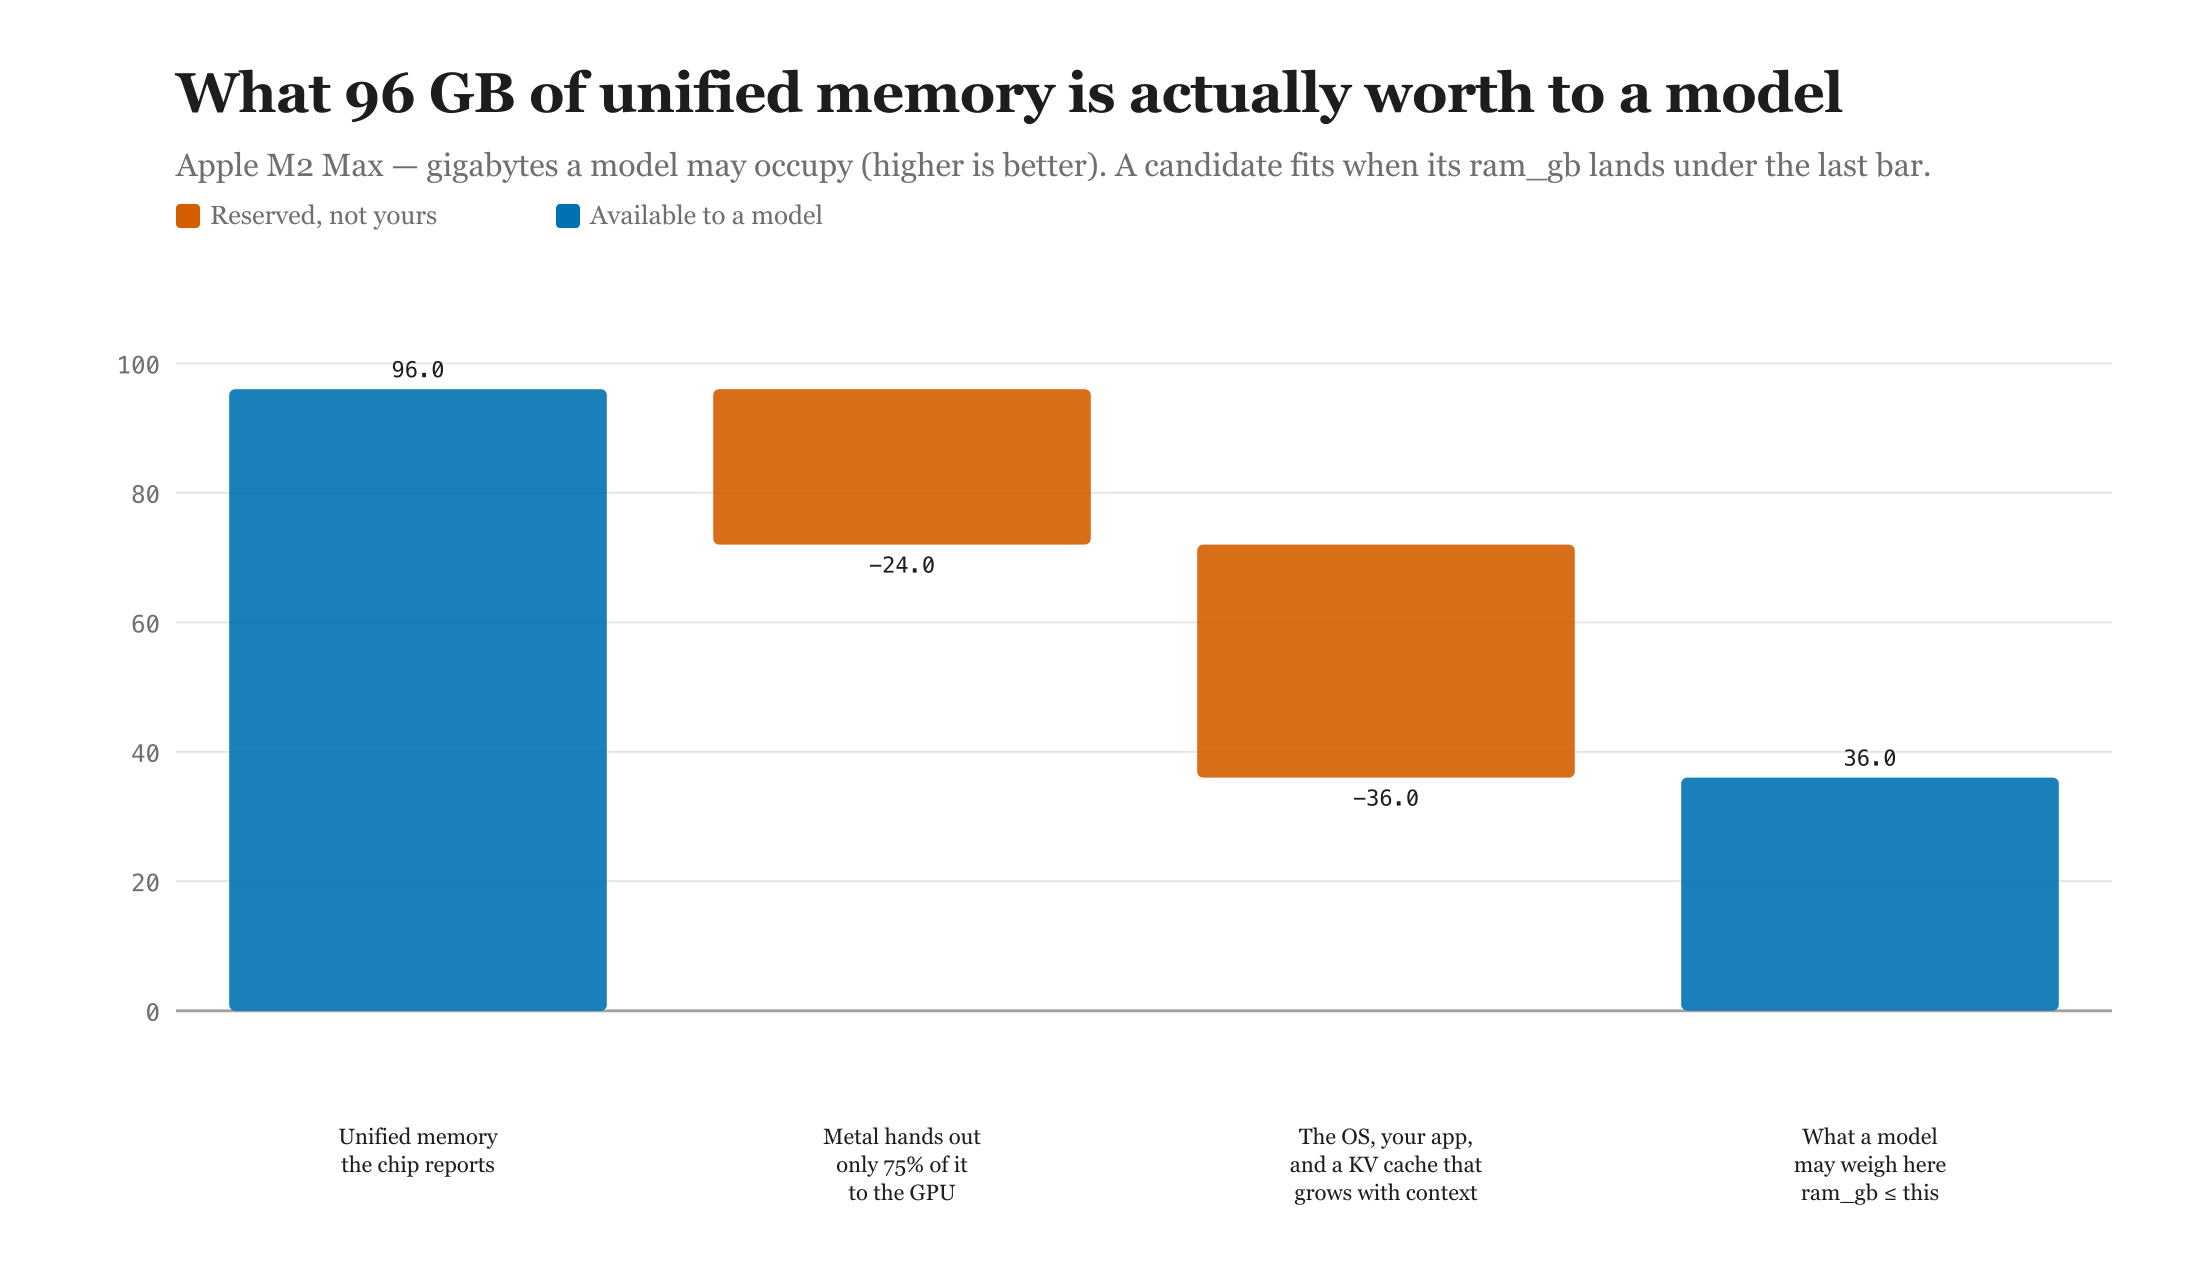
96 GB on the box, 36 GB a model may weigh. The gap is not pessimism: one
half is a driver limit you cannot argue with, the other is a margin you
can (--headroom, up to the 0.5 ceiling it is clamped to).
3. Task fit (is it good at the job?)
A task, even a vague phrase like "retail descriptions and image-quality
checks", maps to a benchmark axis (generalist, code, math, ocr,
vision) and to the model kinds it needs (text implies an LLM, anything visual
implies a VLM).
Among fitting models, the highest benchmark on that axis wins.
4. Throughput (how fast will it generate?)
Token generation is memory-bandwidth bound: each token reads the active
model from memory once, so the ceiling is bandwidth ÷ model-size, derated to
about 65% for KV-cache reads and overhead. report estimates tokens/s per
candidate from the chip's memory bandwidth, and offers a lighter, faster
alternative when one is nearly as strong. Bigger is not automatically better: a
72B model that technically fits may run at a few tokens/s, while an 8-14B model
leaves headroom and runs several times faster.
When nothing fits, the tool falls back to the smallest model and says so — and on a machine with the disk for it, offers to run a good model instead by streaming its layers (see below).
5. Live server load (optional, --live)
The four factors above describe the machine's theoretical capacity. Add
--live (recommend/report; live: true on POST /api/recommend) to also
weigh what else is happening on it right now: current free RAM, CPU/GPU/disk
usage, and how many engines (Ollama models, vLLM servers) are already running.
A busy or already-loaded machine gets a smaller, more realistic budget than an
idle one with identical hardware. Off by default: it adds a short live probe
(~0.1-0.5s: nvidia-smi/ioreg, a local Ollama ping, a psutil sample) and
makes the recommendation depend on this exact moment rather than being a
deterministic function of the hardware alone, which matters for reproducible
reports and CI.
Sources. Apple Metal working-set cap (Apple developer docs / apple-specs);
inference-memory breakdown weights + KV (15-20%) + overhead (5-10%) (local-LLM
sizing guides); bandwidth-bound decode tok/s ≈ bandwidth ÷ active-bytes × 0.5-0.8
(llama.cpp / MLX community benchmarks). The exact ratios live as documented
constants in score.py.
Measured throughput, and why the estimate needed correcting
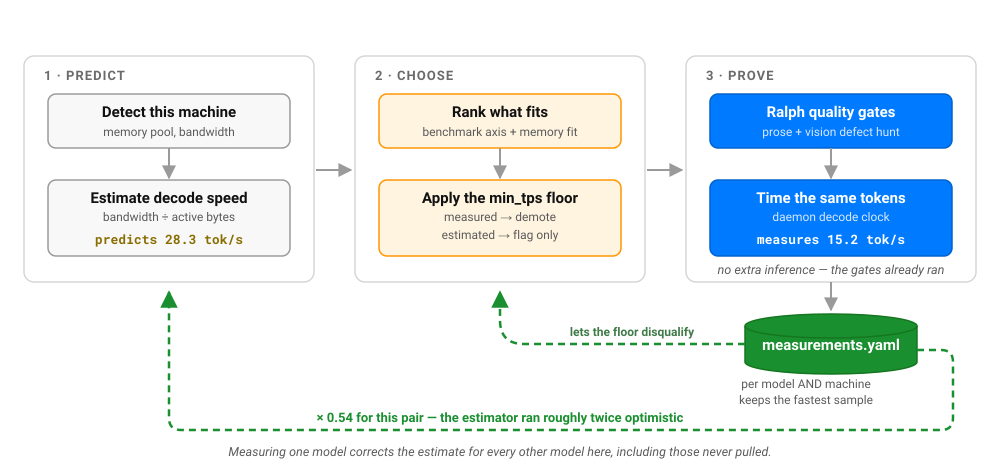
Everything above is an estimate. For a tool whose argument is that you should
measure rather than assume, that was the one place it assumed — so pull and
validate now measure it.
The measurement costs nothing extra. Both commands already pull a candidate and
put it through two Ralph gates, which means the tokens have already been
generated; all that was missing was a stopwatch. The figure lands in
~/.best-engine-ai-helper/measurements.yaml, keyed by model and machine,
since tokens per second is a property of both.
It is timed with Ollama's eval_duration — the decode phase as the daemon
measures it — rather than wall-clock time around the call, which also contains
prompt processing, HTTP, and any queueing. Each measurement records which clock
produced it, and only the daemon's clock is allowed to disqualify a model: wall
time understates decode speed, and understating is what would reject a model
that runs perfectly well.
Re-measuring the same model keeps the fastest sample rather than the latest,
which is a correctness requirement rather than optimism. The quantity being
calibrated is a memory-bandwidth ceiling, and a busy machine can only ever
make an observation look slower than the hardware really is. This was learned
from the behaviour itself: gemma3:12b measured 15.2 tok/s on an idle machine
and 8.7 tok/s with three test suites running — and the contended sample alone
would have yielded a correction of 0.31 against the idle run's 0.54, skewing
every estimate on the machine. samples records how much evidence stands behind
the stored figure.
Three things follow, and the third is the interesting one:
-
A measured figure beats an estimate wherever both exist.
recommendmarks it with*. -
min_tpsbecame a real constraint. Every usage brief already carried a throughput floor and it only ever sorted. A model measured below the floor is now demoted out of auto-selection, exactly as one that does not fit in memory is. A model merely estimated below it is flagged and left alone, so a machine that has never runpullbehaves exactly as it did before. -
Measuring one model improves the estimate for all the others. The ratio of measured to estimated is a property of the machine far more than of the model, so it transfers. On the Apple M2 Max this was developed against,
gemma3:12bdecodes at 15.2 tok/s where the bandwidth model predicted 28.3. That ratio is applied to every subsequent estimate on this machine, including for models that were never pulled.That claim is tested rather than asserted —
scripts/validate_calibration.pycalibrates on one model, predicts another, and reports whether it beat the raw estimate. It did, in every direction tried, cutting the error from 64-118% down to 17-25%. Worth stating both halves: the correction is large and it is not precision. Ratios ranged about 0.46 to 0.61 across models and across repeated runs of the same model, which is why the factor is a median over several measurements rather than one, and why a real measurement still outranks a calibrated estimate wherever one exists. Calibration moves an estimate from wrong by a factor of two to wrong by about a fifth; it does not make it right.
Point 3 is also why the comfort floor mattered more than it looked: COMFORT_TPS
is 15 tok/s, so an uncorrected estimate of 28.3 sails past it while the real
15.2 only just clears it. The correction is the difference between a
recommendation that sounds comfortable and one that is.
Too large to load, still runnable: layer streaming
Everything above answers one question: which model fits? This section is about the question that follows when the honest answer is none of the good ones.
A transformer never needs all of its layers in memory at once. Decoding reads layer 1, then layer 2, then layer 3; only the layer being computed has to be resident. Keep one layer shard in memory, stream the rest off the disk, and the memory a model needs stops scaling with its parameter count and starts scaling with its widest single layer. A 70B model becomes about 4 GB resident instead of 141 GB.
The runtime that does this is this package's own
(best_engine_ai_helper.streaming), and it is one extra away.
pip install 'best-engine-ai-helper[lightweight]'    # the streaming runtime
pip install 'best-engine-ai-helper[generate]'       # streaming + images
Deciding whether a model can be streamed, and how fast, needs none of that:
lightweight plan and lightweight compare answer on a base install, because
the arithmetic is the package's own and the runtime is only wanted once you
actually run something.
It used to be the third-party airllm. That dependency is gone, for reasons
that were measured rather than assumed:
- It did not work on Apple Silicon at all. Its model factory skips
architecture dispatch on macOS and returns a hand-written Llama transformer
in MLX whatever you asked for, so Qwen (attention biases), Llama 3.2 (tied
embeddings, no
lm_headtensor) and older exports (persistedrotary_emb.inv_freq) each failed differently. - It wrote a second copy of the checkpoint to disk as per-layer shards before running, so streaming a 70B needed ~294 GB free rather than ~140. That, not memory, is what used to make most models refuse on a laptop.
This one reads one tensor at a time straight out of the checkpoint's own
safetensors — memory-mapped, with a tensor-level index — so no scratch space
is needed at all, and transformers owns the forward pass, so the
architecture is whatever transformers knows. Apple Silicon is torch on
Metal (MPS), not a second framework.
That is what [lightweight] buys (torch, transformers, accelerate,
safetensors). It is paid once, at install time, and only by callers who asked
for it: the imports are lazy on top of that, so nothing of the stack is loaded
until you actually stream a model, and detect / recommend / report stay
instant either way.
How a streamed forward pass actually runs:
flowchart LR
    subgraph DISK["checkpoint on disk (safetensors, memory-mapped)"]
        L0["layer 0"]:::w
        L1["layer 1"]:::w
        LN["layer N"]:::w
    end
    subgraph MEM["resident memory"]
        R["embeddings + final norm + head<br/>(loaded once)"]:::r
        CUR["exactly ONE decoder layer"]:::cur
    end
    L0 -. "pre-hook reads" .-> CUR
    L1 -. "prefetched while N-1 computes" .-> CUR
    LN -. "…" .-> CUR
    CUR -- "post-hook frees it again" --> FREE(["back to meta"]):::f
    R --> OUT["logits"]:::o
    CUR --> OUT

    classDef w fill:#CCE3F0,stroke:#0072B2,color:#000
    classDef r fill:#CCECE3,stroke:#009E73,color:#000
    classDef cur fill:#FAECCC,stroke:#E69F00,color:#000
    classDef f fill:#F7DFCC,stroke:#D55E00,color:#000
    classDef o fill:#F5E4ED,stroke:#CC79A7,color:#000
What has to be resident is the widest single layer, not the checkpoint. If an interpreter cannot import the stack — a stripped container, a failed wheel build — every surface says so and points at a reinstall, because at that point the install is incomplete rather than un-opted-into.
What it costs: seconds per token, not tokens per second
The trade is real and it is large. Under every other backend, generation is bounded by memory bandwidth. Under streaming it is bounded by the disk, and by a much harder bound: the weights do not stay anywhere, so each token costs a full pass over the checkpoint. On a 4 GB/s NVMe drive a 70B model at bf16 decodes at about 0.024 tok/s — roughly forty seconds a token.
That makes streaming a batch tool: one hard question, an overnight evaluation, a quality reference to judge the small model you run every day. Not a chat window. The package says so in every surface, in seconds per token rather than in tokens per second, because "0.024" reads like a rounding error and "41 s/token" reads like what it is.
The unit is a forward pass, which has three useful consequences
A streamed forward pass walks the layers in order, reads each shard, computes it over every token in the pass, and frees it. So a pass costs what reading the checkpoint once costs — independent of how many tokens rode through it. Three things follow, and the second and third are levers you can pull:
1. One generated token costs one pass. Decoding is autoregressive: token N+1 needs its own walk through every layer. This is where the seconds-per-token figure comes from, and it is why a long answer is expensive.
2. The prompt is nearly free. A 2000-token prompt is processed in the same single pass as a 10-token one. No other backend has that property — under Ollama or vLLM a long prompt is real prefill work. It makes streaming comparatively good at long document in, short verdict out: classification, extraction, judging, a one-line answer over a long context. Past a few thousand tokens the per-layer compute starts to matter and the estimate says so rather than pretending otherwise.
3. A batch of B prompts costs one pass, not B. B independent questions answered together go B times faster per answer. Compression gives about 3×; a batch of 8 gives 8×. For a real batch job the batch is the bigger lever by far, and its only cost is one KV cache per sequence — which the footprint estimate charges you for, so a batch job cannot plan itself into an out-of-memory.
So "how fast is it?" has three answers, and quoting the wrong one is how a batch job gets planned as an interactive one. All three are reported:
| Figure | What it means |
|---|---|
decode_tps |
Steady-state rate, one token per pass. The headline, and the pessimistic reading. |
time_to_first_token_s |
One pass, prompt included — the same as any other token, which is unusual. |
effective_tps |
Tokens delivered per second of wall clock, batch included. The one that decides whether a job finishes overnight. |
What it costs in memory, and where the real constraint is
Resident memory is one shard, plus the one thing streaming does not shrink:
resident ≈ (checkpoint ÷ layers) × 1.25 × shards_resident
           + KV cache for every layer
           + activations and runtime buffers
checkpoint ÷ layersis the average layer. The widest one is the token-embedding matrix rather than a decoder layer — a modern 128k–152k vocabulary makes it so — hence the 1.25.layers_residentis 2 with prefetching on (the next layer is read while the current one computes, which is where its ~10% speed-up comes from) and 1 without. Turning prefetching off is the single knob that gets a 70B model onto a 4 GB card, and this package tries it automatically before rejecting a candidate for memory.- The KV cache is not streamed: autoregressive decoding cannot recompute earlier keys and values, so every layer's slice stays resident for the whole generation. It grows with context and with depth, and on a deep model it is the second-largest term. This is why a context length buys or loses you a model here.
Worked, on a 4 GB/s NVMe drive at a 4k context:
| Model | Checkpoint (= free disk needed) | Layers | Resident (prefetch / serial) | s/token |
|---|---|---|---|---|
| Llama-3.3-70B | 140 GB | 80 | 6.1 GB / 3.9 GB | 41 s |
| Qwen2.5-VL-72B | 146 GB | 80 | 6.3 GB / 4.0 GB | 43 s |
| Mixtral-8x22B (141B, MoE) | 282 GB | 56 | 14.0 GB / 7.7 GB | 83 s |
| Qwen3-235B-A22B (MoE) | 470 GB | 94 | 14.5 GB / 8.2 GB | 138 s |
| DeepSeek-V3 (671B, fp8, MoE) | 671 GB | 61 | 29.0 GB / 15.2 GB | 197 s |
| Llama-3.1-405B | 810 GB | 126 | 18.5 GB / 10.5 GB | 238 s |
Depth is what makes the last row possible: 405B parameters over 126 layers is a
leaner layer than 141B over 56. A mixture-of-experts breaks the usual
relation between size and depth (DeepSeek-V3 is 671B across 61 layers, where
the dense trend would predict twice as many), so a MoE entry that does not
declare its layers is refused rather than guessed at — a guess there is
wrong by a factor of two, in the direction that over-promises.
Read the second column first. Disk space, not memory, is what usually refuses
a model — but only the checkpoint's own size. Layers are read out of the
original safetensors, memory-mapped and tensor-indexed, so nothing is copied and
there is no scratch space to find: a 405B model is an 810 GB download, and then
it is ready. (The previous runtime wrote a second per-layer copy beside the
first, which is why this column used to read 1701 GB and why almost every row of
lightweight plan used to say runs: NO.) Memory is the easy half of
streaming.
These figures were checked against airllm's published numbers, and the check is worth stating precisely because the headline "70B on a 4 GB GPU" is true at a context length nobody mentions: the same model is 3.0 GB serially at a 1k context — the demo — 3.9 GB serially at 4k, and 6.1 GB at 4k with prefetch on. The weights are identical in all three. What moves is the cache that is not streamed.
Native model or streamed model? lightweight compare answers in one screen
This is the decision streaming actually forces, and neither ranking answers it alone. A machine that runs a 14B model comfortably can also stream a 70B one: the two differ by a handful of benchmark points in one direction and three orders of magnitude of latency in the other.
A tokens-per-second column cannot settle it — 26 and 0.024 do not sit on a scale anybody reasons about. Seconds for the same answer do:
best-engine-ai-helper lightweight compare --tokens 300
=== LLM: ollama vs lightweight, for a 300-token answer ===
  budgets: 11.04 GB resident (ollama) · 22.08 GB per layer (lightweight) · disk 4.0 GB/s (declared)
model                       backend  score  resident  tok/s  answer  runs
--------------------------  -------  -----  --------  -----  ------  ----
qwen3:72b-q8_0              ollama   89     78.0      8.4    36 s    NO
qwen3:72b-q4_k_m            ollama   87     48.0      13.7   22 s    NO
qwen3:14b                   ollama   78     10.5      62.4   5 s     yes
gemma3:12b                  ollama   77     9.2       71.2   4 s     yes
Qwen/Qwen3-72B-Instruct     lightweight   89     6.2       0.024  3.5 h   yes
Qwen/Qwen3-VL-72B-Instruct  lightweight   88     6.2       0.024  3.5 h   yes

  Streaming buys 11 benchmark points (89 vs 78) for 2647x the wait: 3.5 h
  instead of 5 s for a 300-token answer.
Read the runs column: the 72B that scores 89 is right there in the Ollama
catalog and does not fit this 24 GB card. Streaming is what puts the same
class of model within reach, at the price in the answer column.
Each side is ranked by its own backend's rules, and the streamed side inverts the usual one. Everywhere else this package picks the leanest model within a few benchmark points of the best, because a gigabyte of residency is paid on every run and competes with your own workload. Streaming breaks that premise: residency is one shard whatever the model's size, so leanness buys nothing and the anti-greed rule lands on an 8B model — the one senseless outcome, since an 8B model runs natively a hundred times faster. The streamed pick is instead the most capable model that runs, by benchmark score, with parameter count deciding only where no benchmark does.
Not simply the biggest, and the difference is not academic: the first rule here was "biggest that runs", and this very table showed what it cost — a 141B mixture-of-experts scoring 84 beat a dense 72B scoring 87 on parameter count while taking twice as long per token. Bigger, slower and weaker is dominated on every axis a caller cares about.
The comparison carries one deliberate bias, stated so you can discount it: the native timing counts decode only and ignores prompt processing, while the streamed timing is complete. That flatters the native side — the right direction for an honest comparison whose conclusion is usually "stay native", and the backend has to be willing to say that about itself.
When it switches on
Never by default. Two triggers, and nothing else:
flowchart TB
    ASK["the brief · --backend ·<br/>BEST_ENGINE_LIGHTWEIGHT"]:::src
    SW{"lightweight"}:::gate
    AUTO{"does a conventional<br/>backend fit this kind?"}:::gate
    USUAL["Ollama or vLLM,<br/>as usual"]:::ok
    STREAM["stream the layers off disk,<br/>priced in seconds per token"]:::stream
    REC(["recorded in the descriptor,<br/>per kind, with its reason —<br/>including when it was no"]):::out
    MIX["so Ollama for the LLM and<br/>streaming for the VLM is<br/>an honest engine file"]:::opt

    ASK --> SW
    SW -- "never · wins over all" --> USUAL
    SW -- "auto · the default" --> AUTO
    SW -- "always · a human asked" --> STREAM
    AUTO -- yes --> USUAL
    AUTO -- no --> STREAM
    USUAL --> REC
    STREAM --> REC
    REC -.- MIX
    classDef src fill:#FCFAD9,stroke:#E69F00,color:#000
    classDef gate fill:#FAECCC,stroke:#E69F00,color:#000
    classDef hw fill:#CCE3F0,stroke:#0072B2,color:#000
    classDef opt fill:#DDF0FB,stroke:#56B4E9,color:#000
    classDef ok fill:#CCECE3,stroke:#009E73,color:#000
    classDef out fill:#CCECE3,stroke:#009E73,color:#000,stroke-width:3px
    classDef aside fill:#F5E4ED,stroke:#CC79A7,color:#000
    classDef stream fill:#F7DFCC,stroke:#D55E00,color:#000
Automatic — the conventional backend resolved nothing that fits this
machine for a kind your brief needs. Streaming is then the difference between a
model and no model, so resolve proposes it with its cost stated. The rescue is
per kind: if your LLM fits and no VLM does, only the VLM falls back, and the
engine file is honestly mixed (Ollama for one kind, lightweight for the other —
model_for() reads the per-kind backend first). The descriptor records the
decision and its reason under lightweight:, including when the answer was no, so
a machine that cannot stream says why instead of staying silent.
Manual — you ask:
best-engine-ai-helper resolve --brief llm.brief.yaml --backend lightweight
or in the committed brief:
kind: llm
task: judge the quality of generated product descriptions
lightweight: always          # auto (default) | always | never
or in the environment, which outranks nothing but defaults:
export BEST_ENGINE_LIGHTWEIGHT=always # or never, to switch the whole path off
never wins over everything, including the automatic trigger. A human who
wants a 235B model on a laptop overnight is making a legitimate choice that no
automatic rule should have to guess, and a human who never wants their disk
thrashed deserves one switch that means it.
The commands
# Can this machine stream, should it, and what is in the way?
best-engine-ai-helper lightweight status
best-engine-ai-helper lightweight status --measure      # measure the disk, don't assume it

# What could it stream, biggest runnable first?
best-engine-ai-helper lightweight plan --kind llm --compression 4bit --batch 8

# Native or streamed, same answer length, both prices
best-engine-ai-helper lightweight compare --tokens 300 --batch 8

# Pay the download now, not inside your first call
best-engine-ai-helper lightweight prepare --model meta-llama/Llama-3.3-70B-Instruct
--measure is worth knowing about. The drive sets the entire speed of this
backend, so assuming its class (Apple internal NVMe, generic NVMe, SATA SSD,
spinning disk) is a weaker input than measuring it. The measurement writes and
reads back ~256 MB with the page cache bypassed (F_NOCACHE on macOS,
O_DIRECT on Linux); without that step the read is served from RAM and reports
the memory bus — which is how this probe first claimed 13 GB/s on a drive whose
own specification tops out near 7. On a platform with no way to bypass the cache
it returns nothing rather than a flattering number, and every surface labels the
figure measured or declared.
Limits, stated plainly
- No structured output. The runtime exposes raw generation, with no equivalent of
Ollama's grammar-constrained
format. Every streamed model is thereforestructured_output: false— a fact about the backend, not about the weights — and the suite's schema-driven tasks stay on an Ollama model.llm.chatraises rather than honouring a schema in name only. - Text only. The adapter returns a bare causal language model, without the image processor a VLM prompt needs. Images raise instead of being silently answered from the text alone.
- No server. The runtime is a library, so a streamed model runs in your own
process; the engine file's
base_urlis empty on purpose, because inventing a localhost port would send a consumer looking for a daemon that will never exist.llm.chatkeeps the loaded model between calls — re-reading a 141 GB checkpoint's index per call would make the transport unusable. - safetensors only. A checkpoint published only as
pytorch_model.binis refused by name. Pickle carries no tensor-level index, so "read one layer" would mean reading the whole file once per layer — which is the one thing this backend exists not to do. - No per-expert MoE streaming. A sparse mixture-of-experts layer is materialised whole, so its resident figure is the full expert set rather than the handful a token actually routes to. The sizing charges for the whole set, which is why a MoE row looks expensive next to a dense model of the same depth.
- No quantisation on the fly. The checkpoint runs at the dtype it ships in.
There is no
--compressionknob, because there is nothing here that could honour one: to stream in fewer bits, point at a repository already published that way, and the catalog'sdtypeprices it. (An earlier version accepted such a flag and quoted a 3× speed-up the runtime never delivered.) - CPU works, slowly.
cuda,mpsandcpuare all real paths — the device is named explicitly rather than guessed. A CPU-only machine is still not offered streaming automatically, because the rate it would get is below the batch floor; it can be asked for. - The context is 4096 tokens unless you ask for more. A tokenizer left at
its own default truncates past it, so the runtime always configures
max_seq_lenexplicitly — set to the same 4k the footprint above is priced at. The two numbers are deliberately the same one: a tool that quotes memory for a 4k context and then quietly runs a 512-token one would be lying in the direction where you lose the end of your prompt. Raise it withmax_seq_len=and the KV term rises exactly as the formula says.
Why this runtime is our own rather than an import
A fair question, and the answer changed. The technique was demonstrated by airllm (Apache-2.0), which this package imported at first. Three measurements moved it in-house:
- It did not work on Apple Silicon at all. airllm's
AutoModeldispatches on architecture everywhere except macOS, where it hard-returns a hand-written Llama transformer in MLX withbias=Falsethroughout. Qwen carries attention biases; Llama 3.2 ties its embeddings, so there is nolm_headtensor; older exports persistrotary_emb.inv_freq. Three different crashes, on the platform this suite is developed on — andgenerate()never got that far anyway, raisingAttributeError: 'AirLLMLlamaMlx' object has no attribute 'device'on the first call on every Mac. - It wrote a second copy of every checkpoint to disk. Per-layer shards,
written before anything ran, so a 70B needed ~294 GB free rather than ~140.
That is what made almost every row of
lightweight planreadruns: NOon a normal laptop: the models fit in memory-per-layer terms and failed on scratch space that no longer has to exist. - It carried MLX, bitsandbytes and a subclass per model family — Llama, Qwen, DeepSeek, Mixtral, ChatGLM, Kimi — each rewritten as the family shipped. All of that left with it.
What replaces it is smaller, not larger: build the model on the meta device,
hang a forward pre-hook on each decoder layer that materialises its weights from
the checkpoint's own memory-mapped safetensors, and a post-hook that frees
exactly those again. transformers owns the forward pass, so the
architecture is whatever transformers knows, and the decoder stack is
discovered — the ModuleList whose length matches the config's layer count —
rather than named in a per-family table somebody has to maintain.
The division of labour inside this package is unchanged: streaming.py owns the
forward pass, and offload.py owns every selection question — the footprint
arithmetic, the disk-bound timing model, the activation policy, the
native-versus-streamed comparison, and the catalog metadata all of it needs
(layers, dtype, moe). None of offload.py imports torch, which is what
makes lightweight status and lightweight compare answer correctly and
instantly even where the runtime itself would not load.
From Python
import best_engine_ai_helper as beah  # lightweight is a dependency, nothing to install

hw, disk = beah.available_memory(), beah.disk_profile()

# Should this machine stream at all?
decision = beah.lightweight_decide(conventional_resolved=False)
print(decision["activate"], decision["reason"], decision["blockers"])

# What would a 70B cost here?
entry = {
    "id": "llama3.3:70b",
    "size_b": 70,
    "layers": 80,
    "hf_id": "meta-llama/Llama-3.3-70B-Instruct",
}
print(beah.lightweight_footprint_gb(entry))  # 6.1 GB resident
print(beah.lightweight_generation_time(entry, disk["read_gbs"], new_tokens=300, batch=8))

# Native or streamed, for a 300-token answer?
report = beah.lightweight_compare(
    beah.load_catalog(),
    hw=hw,
    disk=disk,
    bandwidth_gbs=beah.compute_profile()["bandwidth_gbs"],
    new_tokens=300,
)
print(report["verdict"])

# And actually run it
text = beah.lightweight_generate(
    "Judge this description:…", model="meta-llama/Llama-3.3-70B-Instruct", max_new_tokens=64
)
The HTTP surface answers the same questions in one call —
GET /api/lightweight?answer_tokens=300&batch=8 returns the decision, the storage
profile, the ranked plans and the comparison — and it is reachable as an MCP
tool like every other endpoint.
Available commands
| Command | Description |
|---|---|
detect |
Print the detected hardware as JSON |
recommend |
Rank candidates for this hardware (no download) |
report |
Recommend the best engine(s) for a task (Markdown + JSON) |
resolve |
Turn a committed usage brief into this machine's llm.engine.yaml |
doctor |
Compare what the engine file resolved against what the daemon can serve |
storage |
Plan capacity: what fits on disk, and what fits in memory together |
providers |
Which cloud providers are usable right now, and for the others, the variable to set |
catalog show |
Print the merged model catalog |
catalog update |
Refresh the model cache (--ollama for pullable tags from the official library, --arena to merge LM Arena ratings, --limit N for a partial refresh) |
hardware show |
Print the known hardware chip table |
hardware update |
Record this machine's chip and memory in the hardware cache |
pull |
Download the best model and run the Ralph gates |
validate |
Run the Ralph gates on the currently configured model |
env |
Print the shell export block ready for ~/.zshrc |
gui |
Launch the browser GUI |
activity |
Summarize the local activity/cost ledger (calls, cost, by user/model, errors) |
usages list |
List usage profiles and families (needs only, never a model) |
usages show <profile> |
Show one profile's needs (task, structured output, floors) |
usages resolve <profile> |
Resolve a profile (or --family) to the model best-engine picks here |
lightweight status |
Can this machine stream layers off disk, should it, and what is in the way (--measure to measure the drive) |
lightweight plan |
What a too-large model would cost here, ranked: resident shard, seconds per token, disk to split |
lightweight compare |
Native model vs streamed model, same answer length, both priced in seconds |
lightweight prepare |
Download and split a checkpoint now, instead of inside the first call |
imagine plan |
Which text-to-image model this machine can run, its footprint and its seconds per image |
imagine generate |
Generate one image locally, to a PNG file |
serve |
Serve the OpenAI-compatible API: point any OpenAI SDK at it and ask for best |
Model catalog
The bundled seed catalog (models.yaml) covers the Qwen 3, Qwen 2.5, Qwen 2.5-Coder, and Gemma 3 families (from 3B to 72B parameters, across Q4_K_M and Q8_0), plus a small set of kind: embed text embedders for the retrieval index. The catalog tracks on-disk size, estimated peak RAM, and benchmark scores from the Open LLM Leaderboard v2, the OpenVLM Leaderboard, EvalPlus (code), and MTEB (embedding retrieval). This is the search space best-engine picks from: it is never a per-usage choice.
catalog update refreshes the cache from the ApXML LLM directory (open-weight models with their per-quant VRAM needs, consulted regularly). It fetches the specs, normalizes them to catalog entries, and merges them into ~/.best-engine-ai-helper/catalog_cache.yaml by id (the bundled seed is never modified). Use --limit N for a quick partial refresh. ApXML's static pages carry specs but no numeric leaderboard scores, so refreshed entries keep null benchmarks (and rank low) until a scored source, such as the Open LLM Leaderboard v2 or the OpenVLM Leaderboard, fills them.
--ollama widens the catalog from the official Ollama library instead of ApXML, and it exists because the servable catalog was stuck at twenty models for a reason that was never about scoring. ApXML can add hundreds of entries, but it names them by the paper's slug (qwen36-35b-a3b), which is a HuggingFace repo name that ollama pull cannot resolve — so those entries are vLLM-only. The library instead publishes families, their capabilities, and the sizes each one ships, and a family plus a size is a pull tag: qwen3 plus 8b is qwen3:8b, exactly the spelling the seed already uses. 256 families expand to roughly 420 pull tags, from a single request.
These entries carry no benchmark scores, because the library publishes sizes and descriptions rather than leaderboard results. They therefore rank below every scored model until a scored source fills them in. That is the point rather than a limitation: it widens what the tool can size and pull without changing what it recommends, and an invented score would be worse than an absent one — a null ranks low and is honest, a guess ranks wrongly and looks authoritative.
Sizes are derived from a constant measured against the seed's own fourteen Q4 entries, not guessed: 0.646 GB per billion parameters for text models and 0.714 for vision ones, since an image tower is genuinely heavier per parameter. That lands within about 5% of the seed's known-good figures. A family listing no size at all is skipped rather than recorded as zero, which would have made it appear to fit every machine.
--arena additionally merges conversational ratings from LM Arena mirrors, and two measured facts about that axis are worth knowing before you reach for it.
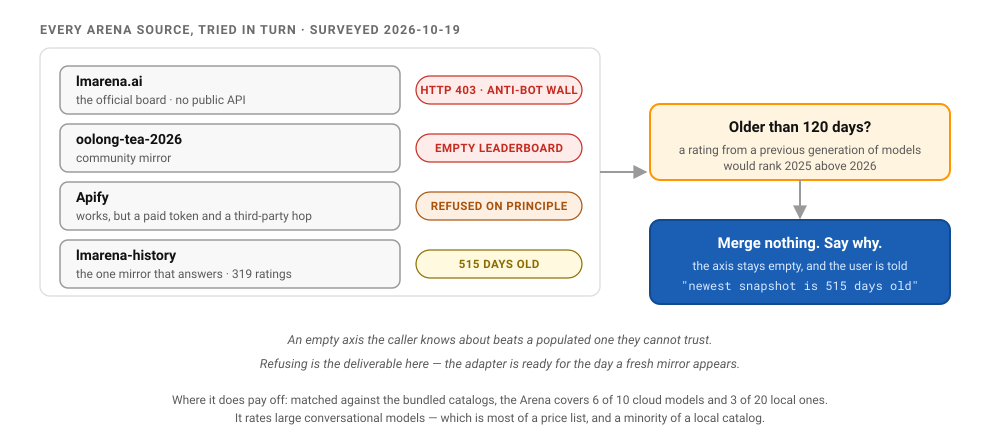
It rates hosted frontier endpoints, and nothing else. Arena rates what its voters can chat with, which today means names like claude-opus-5.5-max, gpt-6-astra-max and gemini-4-argon-high. Re-surveyed 2026-10-28, that is 37 models, and none of them matches either bundled catalog: models.yaml holds open-weight Ollama tags nobody votes on, and pricing.yaml holds 2024 API models Arena stopped ranking generations ago. The families overlap — claude, gemini, gpt — but the versions do not, and matching claude-opus-5.5-max's Elo onto claude-3-5-sonnet would be worse than matching nothing. The matcher refuses, correctly.
Embedding models cannot match by construction either: nobody chats with an embedder, so no leaderboard of chat preferences will ever rate one. The command prints its own matched/total every run, so you never have to take this paragraph's word for it.
It is a third-party scrape, and the mirrors rot in ways that look like outages. Arena publishes no API. One mirror stopped updating 524 days ago. The other runs daily and keeps producing a directory even on days its own scrape returns nothing — so its index names an empty one, and the adapter used to read that, report "no usable data", and stop. It now walks back to the newest snapshot that has data, and reads the board names from the mirror's own index rather than guessing them: two of the four names it used to guess (overall, coding) were never published, so the code axis was silently empty against a mirror that was serving it as code. That is the difference between 0 ratings and 37.
Past MAX_SNAPSHOT_AGE_DAYS the adapter still refuses and names the reason, because an Elo from a previous generation would rank 2025's models above 2026's — strictly worse than no Elo. It never reports a success that enriched nothing.
Hardware table
hardware.yaml lists known GPU and Apple Silicon chip configurations with their usable memory (physical pool minus OS and driver overhead). There is no public specs API spanning every chip, so hardware update records ground truth for the machine it runs on instead: it detects this machine's chip, memory pool, and Ollama-usable share, and upserts that row into ~/.best-engine-ai-helper/hardware_cache.yaml (keyed on chip + memory tier).
Downstream integration
There are two ways to consume the selected model. Use the first when every tool on the machine should share one model. Use the second when a project has its own idea of the job and wants the pick that fits that job, not a generic one.
Pattern A: one shared model for the whole machine
After best-engine-ai-helper pull completes, it writes ~/.best-engine-ai-helper/env.sh. pull picks one model that clears both quality gates and points the text and vision slots at it, so both tags match (the exact tag depends on your hardware):
export BEST_LLM_TEXT=gemma3:12b
export BEST_LLM_VISION=gemma3:12b
export BEST_LLM_BACKEND=ollama
export BEST_LLM_BASE_URL=http://localhost:11434
Projects that consume the selected model source this file or read the companion config.json.
Pattern B: a per-project engine resolved from a tuned brief
A project usually knows its job more precisely than a machine-wide default can, and the quality of the pick depends on how well that job is described: the task text is what maps to a scoring axis and decides whether a VLM is needed (see How selection works). So the project keeps a committed brief describing the job and resolves it, per machine, into a gitignored engine file that names the backend and model to use. No DEFAULT_MODEL constant lives in the project: the model is always read from the resolved engine file.
-
Commit the brief:
llm.brief.yamlin the repo, hardware-independent:kind: both # llm | vlm | both headroom: 0.5 # max fraction of usable accelerator memory (clamped to 0.5) min_tps: 15 # comfort throughput floor (tokens/s) structured_output: true # the job needs schema-constrained output task: >- Name PCA axis poles as schema-constrained JSON, write a short analysis in the table's own language, and sanity-check the rendered chart image.
-
Resolve it, per machine: writes a gitignored
llm.engine.yaml:best-engine-ai-helper resolve --brief llm.brief.yaml --out llm.engine.yaml
The backend is chosen by a three-branch decision tree, matching what each backend actually supports well rather than what it merely runs on:
- macOS -> Ollama. vLLM ships no native macOS runtime.
- CPU-only (Linux or macOS) -> Ollama. vLLM's CPU-only path — notably on Linux — is its own reported weak spot; Ollama's CPU path is the well-trodden one.
- Discrete GPU (NVIDIA/AMD) on Linux — the real production case -> vLLM, chiefly for the request-batching/concurrency handling it offers under real load, which Ollama does not match.
Windows falls back to Ollama too (no native vLLM wheel, WSL-only), so in short: vLLM only on Linux with a discrete GPU; Ollama everywhere else. The pick is deliberately conservative in other ways too: the memory headroom is capped at 0.5, and among models within a few benchmark points of the best it takes the leanest and fastest, not the largest that merely fits. vLLM picks are sized against full FP16 weights (heavier than the Ollama Q4 estimate), so a vLLM pick is realistic on the real GPU. The output is hardware-specific; add it to
.gitignore:backend: ollama base_url: http://localhost:11434 llm: {model: gemma3:12b, ram_gb: 9.2, est_tokens_per_s: 28.3, structured_output: true} vlm: {model: gemma3:12b, ram_gb: 9.2, est_tokens_per_s: 28.3, structured_output: true} serve: [ollama pull gemma3:12b]
-
Consume it, no constant: read the engine at call time and let the transport route to the right backend:
from best_engine_ai_helper import ensure, llm

# loads llm.engine.yaml, or resolves it from llm.brief.yaml on first use
engine = ensure(".")
summary = llm.chat(prompt, engine=engine, kind="llm")
critique = llm.chat(prompt, engine=engine, kind="vlm", images=[png], json_schema=SCHEMA)
chatreads the backend and model from the engine file and dispatches to Ollama (/api/generate) or vLLM (OpenAI-compatible/v1/chat/completions) transparently, with schema-constrained structured output on both.
Missing-file policy. The brief is committed, so its absence is a real bug and ensure raises loudly with the command to run. The engine file is gitignored and machine-specific, so its absence is normal: ensure resolves it from the brief on first use. This keeps the model out of any variable: the resolved engine file is the single source of truth.
The suite's consumers, Standpoint, vocal-helper, and md2star, follow this pattern; each ships an llm.brief.yaml describing its own job (Standpoint's, for instance, names schema-constrained JSON, so the structured-output gate rules out higher-scoring vision models that cannot honour a schema and picks the strongest one that can) and reads the model only from the resolved engine file.
Where the model runs
This is the one package in the AI Helpers suite that can reach a paid third-party cloud service, so it is worth being exact about when it does. There are three places a resolved model can live, and only the third one costs money or leaves your network:
| Where | Brief | Costs | Reaches a third party |
|---|---|---|---|
| This machine | mode: local (the default, or no mode field) |
nothing | no |
| Your own server | mode: local + --endpoint / base_url |
your own hardware | no |
| A paid provider | mode: cloud + an api_key_env whose variable is actually set |
per token | yes |
Every brief picks one of two modes with mode: local (the default) or mode: cloud. Both resolve to the same shape of engine file and the same llm.chat(engine=..., kind=...) call site downstream: only the transport and the cost change.
Which of the three a brief lands on, and what it costs:
flowchart LR
    BRIEF["the brief"]:::src
    MODE{"mode:"}:::gate
    KEY{"is the variable named by<br/>api_key_env actually set?"}:::gate
    HERE["this machine<br/>Ollama · vLLM · lightweight<br/>$0.0 a call"]:::hw
    MINE["your own server<br/>--endpoint / base_url<br/>$0.0 a call"]:::hw
    PAID["a paid provider<br/>OpenAI · Mistral · Anthropic<br/>· Gemini · OpenRouter…<br/>priced per token"]:::stream
    NOPE["not even a candidate<br/>providers says which<br/>are usable, and why"]:::aside
    CALL(["llm.chat(engine=…, kind=…)<br/>the same call site downstream,<br/>whichever one it was"]):::out

    BRIEF --> MODE
    MODE -- "local · the default" --> HERE
    MODE -- "local + an endpoint" --> MINE
    MODE -- cloud --> KEY
    KEY -- no --> NOPE
    KEY -- yes --> PAID
    HERE --> CALL
    MINE --> CALL
    PAID --> CALL
    PAID -. "a failed paid call falls back" .-> HERE
    classDef src fill:#FCFAD9,stroke:#E69F00,color:#000
    classDef gate fill:#FAECCC,stroke:#E69F00,color:#000
    classDef hw fill:#CCE3F0,stroke:#0072B2,color:#000
    classDef opt fill:#DDF0FB,stroke:#56B4E9,color:#000
    classDef ok fill:#CCECE3,stroke:#009E73,color:#000
    classDef out fill:#CCECE3,stroke:#009E73,color:#000,stroke-width:3px
    classDef aside fill:#F5E4ED,stroke:#CC79A7,color:#000
    classDef stream fill:#F7DFCC,stroke:#D55E00,color:#000
On this machine (free, and the default)
mode: local, or no mode field at all, is the promise: hardware detection, model selection, and every quality gate run on this machine against a model already pulled via Ollama or served via vLLM. Every call costs $0.0, always, with no paid API call to price (see Activity ledger).
On your own server (still free of any third-party charge)
Local mode does not mean this box. --endpoint URL (or base_url in the brief) points the same resolved engine at a server you run — typically vLLM on a GPU machine down the hall, with --backend vllm to force it. The selection is still made for the hardware that will serve the model, the ledger still prices every call at $0.0, and nothing leaves infrastructure you control. This is the middle option, and it is the one people forget exists: "not on my laptop" does not have to mean "on someone else's account".
On a paid provider (opt-in, and only once you supply a key)
A paid call never happens by accident. It takes a brief that says mode: cloud, and an api_key_env naming an environment variable that is actually set — api_key_env holds the variable's NAME, never the key itself, and the key is never persisted into the engine file. When the brief pins no provider, the auto-pick only considers providers whose key resolves right now — holding one Mistral key and no Gemini key, you get Mistral, even where Gemini scores higher — and best-engine-ai-helper providers lists exactly which ones are usable and why the others are not. A pinned provider is still honoured without a key, because api_key_env holds a variable name and a descriptor is meant to be written where the secret is absent and executed where it is present; the engine file records api_key_present: true|false so you can tell the two apart. That is also how report prices a paid model it never calls. Nothing in this package escalates from local to paid on its own; the only automatic direction is the safe one, paid → local, when a paid call fails.
mode: cloud routes through a paid provider instead: OpenAI, Mistral, OpenRouter, Together, or Azure OpenAI (all OpenAI-compatible), plus Anthropic and Gemini (their own wire formats), while keeping the exact same llm.chat(engine=..., kind=...) call site downstream. Two ways to pick the model:
- Pin it: name
providerandmodelexplicitly in the brief, exactly as before. - Auto-pick it: omit
model(andprovider, to search every provider) and best-engine picks the best paid model from a small bundled catalog (pricing.yaml, extended with benchmark scores per model), the same way local mode auto-picks frommodels.yaml, except that the resource being budgeted is price, not memory, since every paid model fits on any machine. Aquality_vs_costknob (0..1, default 0.7) tips the pick:1.0picks purely on benchmark score,0.0picks purely on price, and the default leans quality with price as a tiebreaker.
Keeping the paid catalogue honest
pricing.yaml is hand-maintained, and for a long time it had no source to
refresh from — so it aged silently while observe.py priced every paid call
against it and the auto-pick ranked on the same numbers. It now has one:
best-engine-ai-helper catalog update --cloud
This pulls list prices and context lengths from
LiteLLM's public table into
~/.best-engine-ai-helper/pricing_cache.yaml, overlaid on the bundled seed,
which is never modified. The merge is deliberately narrow, and the narrowness
is the point:
- Prices, context lengths and capability flags are refreshed. When this
landed, four of the ten seed entries were wrong —
mistral-large-latestwas priced at four times its real cost, so the ranker avoided the model that was actually cheap, whilemistral-medium-latestunder-billed by nearly four. Both directions matter, becausequality_vs_costranks on exactly these numbers. - Benchmark scores are never touched. A price table has no opinion about quality, so refreshed entries keep the scores already in the seed. This package will not put a number nobody measured into a file that bills people.
- Nothing is added or deleted automatically. Models the source knows and the catalogue does not are printed for you to triage, not merged: a paid model with no benchmark score cannot be ranked. Models the source has never heard of — four of ten, including both Gemini 1.5 entries, retired by Google well before this — are reported and left exactly as they are, because absence from one source is strong evidence rather than proof.
Until you run it, every cloud surface says the table carries no date. That is
accurate: the seed's numbers were written from recollection rather than
verified on a given day, so there is no honest as_of to stamp. A refresh
writes a real fetched_at per entry, and the warning stops.
mode: cloud
kind: both
quality_vs_cost: 0.7           # optional, 0..1; auto-pick only, default 0.7
task: extract structured line items from an invoice PDF's OCR text
Three further keys exist for the pinned case, and the brief is the only place they can be set. vlm_model pins the vision slot separately — with kind: both and only model given, the same model serves both. base_url overrides the provider's endpoint (for a proxy or a regional deployment), and api_key_env overrides the NAME of the environment variable the key is read from, which defaults to the provider's conventional one. Neither ever holds the key itself.
best-engine-ai-helper resolve --brief llm.brief.yaml --out llm.engine.yaml
# Wrote llm.engine.yaml
#   backend: openai  (llm=gpt-4o, vlm=gpt-4o)
Preview the auto-pick for any task before writing a brief, side by side with the local pick, with no API key and no network call:
best-engine-ai-helper report --task "extract line items from an invoice"
# ... local section ...
# ## Best cloud VLM (axis: ocr)
# **→ `gpt-4o`** (openai) — score 69, ~$6.25/1M tokens (blended)
(--no-cloud skips that section; --quality-vs-cost and --cloud-provider tune it.)
Every cloud engine also carries an embedded local fallback, resolved from the SAME brief, so a failed paid call degrades to the always-available local model: paid → local, the one safe direction (a local engine never silently escalates to a paid call). Four more things happen automatically at the llm.chat() call site once engine= is a cloud descriptor:
| Concern | Default | Opt out / configure |
|---|---|---|
| API key | the NAME in api_key_env (never the key value) is looked up in one pass (settings.yaml, then any .env file, then the process environment), then the OS keychain via keyring |
pip install 'best-engine-ai-helper[cloud]' for the keyring fallback |
| Safety scan | every prompt/image scanned outbound, every response scanned inbound, for BOTH local and cloud (a content-policy concern, not a cloud-only risk) | chat(..., safety=False) |
| Pseudonymization | off; when on, scrubs personal data with the LOCAL fallback model before the prompt leaves the machine, restores it in the response | chat(..., pseudonymize=True), needs [cloud] |
| Retry + cache | off; retry replays a transient transport failure before failing over, cache memoizes identical calls so a repeat never pays twice | chat(..., retries=3, cache=True), cache needs [cloud] |
| Cost tracking | every call, local or paid, appended to the local activity ledger, priced from real provider token counts when reported, else a character estimate | best-engine-ai-helper activity, opt out with BEST_ENGINE_NO_LEDGER=1 |
See EXAMPLES.md's paid-model section for the full worked recipe (settings.yaml, keyring, structured output, the failover chain) and GUI.md for the activity dashboard.
Use it as an OpenAI endpoint
Everything above is this package's own idiom: briefs, engine files,
model_for(). This section is the other direction — from the outside, it
behaves like an OpenAI-compatible server.
best-engine-ai-helper serve # http://127.0.0.1:8000/v1
from openai import OpenAI

client = OpenAI(base_url="http://127.0.0.1:8000/v1", api_key="not-needed")

client.chat.completions.create(model="best", messages=[{"role": "user", "content": "…"}])
client.embeddings.create(model="best-embed", input=["…"])
client.images.generate(model="best-image", prompt="a red bicycle")
No code changes in the client, and no model name to know. That second half is
the point: the usual OpenAI-compatible server — vLLM, Ollama's /v1, LM Studio
— asks you which model to load, which leaves the hard part (does it fit, is it
fast enough, is a bigger one worth the wait) to whoever writes the config. Here
the protocol is the familiar one and the choice is the product.
best is a virtual model name
It resolves per request, against this machine, to the highest-ranked model that fits — and a request carrying an image needs a VLM, so the same name resolves differently depending on what is in the request. The grammar is small:
| Model name | Resolves to |
|---|---|
best / auto |
Best text model; best vision model when the request carries images |
best-llm |
Best text model; an image in the request is refused rather than ignored |
best-vlm |
Best vision-language model |
best-embed |
Best embedding model, ranked on retrieval (MTEB) rather than on general knowledge |
best-image |
Best text-to-image model |
best:<task> |
Best model for that task — best:write SQL, best:read screenshots. The task picks the benchmark axis, exactly as report --task does, and gives a better pick than the bare alias |
| anything else | Passed through verbatim, so qwen3:14b still means qwen3:14b |
The response reports the model that actually ran ("model": "qwen3:14b"), which
is what a virtual name buys back: you gave up naming it, so the answer tells you.
The whole grammar, and where each name ends up:
flowchart LR
    REQ["any OpenAI SDK<br/>model: 'best'"]:::src
    NAME{"the name"}:::gate
    MODE["a mode may prefix it:<br/>best-cloud-llm,<br/>best-local-vlm"]:::opt
    IMG{"does the request<br/>carry an image?"}:::gate
    FIT["ranked against this<br/>machine — only what<br/>fits is offered"]:::hw
    LLM["the best LLM"]:::ok
    VLM["the best VLM"]:::ok
    EMB["the best embedder,<br/>ranked on MTEB"]:::ok
    IMA["the best text-to-image<br/>model"]:::ok
    AXIS["the task picks the<br/>benchmark axis"]:::ok
    THRU["passed through verbatim:<br/>qwen3:14b still means<br/>qwen3:14b"]:::aside
    ANS(["'model': 'qwen3:14b'<br/>the answer names what ran"]):::out

    REQ --> NAME
    NAME -.- MODE
    NAME -- "best · auto" --> IMG
    IMG -- yes --> VLM
    IMG -- no --> LLM
    NAME -- "best-llm · image refused" --> LLM
    NAME -- "best-vlm" --> VLM
    NAME -- "best-embed" --> EMB
    NAME -- "best-image" --> IMA
    NAME -- "best:write SQL" --> AXIS
    NAME -- "anything else" --> THRU
    LLM --> FIT
    VLM --> FIT
    EMB --> FIT
    IMA --> FIT
    AXIS --> FIT
    FIT --> ANS
    THRU --> ANS
    classDef src fill:#FCFAD9,stroke:#E69F00,color:#000
    classDef gate fill:#FAECCC,stroke:#E69F00,color:#000
    classDef hw fill:#CCE3F0,stroke:#0072B2,color:#000
    classDef opt fill:#DDF0FB,stroke:#56B4E9,color:#000
    classDef ok fill:#CCECE3,stroke:#009E73,color:#000
    classDef out fill:#CCECE3,stroke:#009E73,color:#000,stroke-width:3px
    classDef aside fill:#F5E4ED,stroke:#CC79A7,color:#000
    classDef stream fill:#F7DFCC,stroke:#D55E00,color:#000
What it serves
| Endpoint | Notes |
|---|---|
GET /v1/models |
The aliases above, plus every catalogue model that fits this machine — so a client's model picker stops offering a 72B to a laptop |
POST /v1/chat/completions |
Text and vision. Streaming (real SSE), response_format as a genuine schema constraint, multi-turn rendered as a labelled transcript rather than truncated to the last message |
POST /v1/completions |
The legacy endpoint, routed through chat — every backend here is instruction-tuned, so there is no separate raw-completion mode to expose |
POST /v1/embeddings |
float or base64 encoding, one vector per input, indices included |
POST /v1/images/generations |
Local diffusion. size: "auto" (the default) uses the model's native resolution; b64_json is the default response format, since a local server has nowhere to host a file |
/v1 sits on the same app as the GUI, the /api/* routes and the MCP
endpoint: one process, one port. The MCP surface deliberately does not
publish the /v1 routes — its description promises that no model call happens
inside its tools, and that stays true.
What is deliberately not faked
A compatibility layer earns trust by refusing rather than pretending:
- Token counts are real where the backend reports them. Ollama returns
prompt_eval_count/eval_countand those are whatusagecarries. Where a backend reports nothing, the counts are a character estimate — andsystem_fingerprintsays so (usage=estimatedversususage=reported) instead of passing one off as the other. - Streaming is real streaming for plain text. For a request that also needs a schema or carries an image it degrades to a single chunk, because the underlying stream carries neither. A word-by-word drip over an already-complete answer would look better and tell you nothing true about progress.
- Unsupported parameters are errors that name themselves.
n > 1,logprobsandtoolsreturn a 400. A parameter silently ignored is worse than one refused: you would believe you got what you asked for. (For tools, ask for a JSON schema instead — every Ollama model enforces one natively.) - Remote image URLs are off by default. A
data:URI always works; anhttp(s)one makes the server fetch an address the caller chose, which is a server-side request forgery primitive, and this server usually runs on a machine with access to a private network. SetBEST_OPENAI_FETCH_IMAGE_URLS=1to allow it. - Errors use OpenAI's envelope, down to FastAPI's own 422s: an SDK unwraps
error.message, and a{"detail": …}body reaches the user as "unknown error". Scoped to/v1—/apicallers keep FastAPI's conventions.
The claim "an OpenAI SDK parses this" is tested with the OpenAI SDK
(tests/test_openai_sdk.py), not with assertions of our own choosing.
Pixels as well as text: local image generation
kind: image is the third kind of model this package chooses, and it is chosen
the same way as the others — a footprint against this machine's real budget, a
time estimate in the unit a human waits in, a catalogue entry rather than a
hardcoded name.
best-engine-ai-helper imagine plan                    # what runs here, and how fast
best-engine-ai-helper imagine generate --prompt "a red bicycle" --out bike.png
=== Image models: 36.0 GB budget, 400.0 GB/s memory bandwidth ===
id             params  size       steps  gb    offload  s/image  runs
-------------  ------  ---------  -----  ----  -------  -------  ----
flux1-schnell  16.9B   1024x1024  4      30.8  yes      16.9     yes
sd35-medium    10.9B   1024x1024  28     28.3  no       24.8     yes
sdxl           3.5B    1024x1024  28     9.8   no       25.8     yes
sdxl-turbo     3.5B    512x512    4      9.0   no       0.9      yes
sd15           1.1B    512x512    28     2.9   no       2.1      yes
A diffusion model is not one stack of layers but three or four networks that take turns — text encoders, a denoiser (UNet or transformer), a VAE — and two consequences of that run through the whole feature:
Memory depends on how they take turns. All resident, the footprint is their
sum. Handed to diffusers' enable_model_cpu_offload(), only the component
computing stays resident and the peak becomes the largest one — the same trade
layer streaming makes for an LLM, at a far smaller penalty, because the
components swap a few times per image rather than once per token. That is the
offload column above, and it is tried automatically before a model is rejected
for memory: on FLUX, where 8.4B of 16.9B is a T5 text encoder used once per
image, it is the difference between running it and not.
Time is steps, not tokens. The sampling loop runs a fixed number of denoising steps, each a full pass through the denoiser, so the honest unit is seconds per image — and the biggest lever is the step count, which is a property of the weights, not a preference. SDXL-Turbo and FLUX.1-schnell are distilled for 1–4 steps where SDXL wants 28; running a distilled checkpoint at 28 is slower and worse. So the step count comes from the catalogue, which is what makes an auto-selected image model usable at all.
Two more things the catalogue carries for the same reason. The native
resolution, because that is the one size a diffusion model is good at: asking
a 512px model for 1024×1024 duplicates subjects rather than adding detail, which
is why size: "auto" resolves to the model's own figure. And the licence
differs per model — SD 1.5 and SDXL are CreativeML OpenRAIL-M, SD 3.5 is the
Stability Community licence, FLUX.1-schnell is Apache-2.0 (its [dev] sibling
is not) — so check the one you pick before shipping its output.
Usages / task profiles
Where a brief is written per repo, the recurring eight workloads are named once in a bundled usage catalog (usages.yaml). Each profile, text2sql, rag-answer, embeddings, text2sql-figures, report-bluf, classification, pii-rgpd, persona, states only its needs: task type (text / code / vision / embeddings), whether it needs structured output, a throughput floor, a memory headroom, an advisory quality bar, and a context-length hint. A profile is, at heart, a named brief, so it is resolved by the same four-criteria picker as any brief.
A profile never names a model. best-engine is the sole decider: it reads the needs, probes the machine, and chooses the concrete local model, writing that choice only into a generated engine file (llm.engine*.yaml) that is gitignored and machine-specific, never a committed literal. That is the whole point of the tool.
Profiles are grouped into families: the usages that can share one model, so a machine need not hold eight:
| Family | What it needs | Profiles |
|---|---|---|
| F1: constrained generation | code + reliable structured output (SQL / JSON), deterministic | text2sql, text2sql-figures, classification, pii-rgpd |
| F2: prose generation | faithful FR/EN prose over long context | rag-answer, report-bluf, persona |
| F3: embeddings | multilingual, multi-granular retrieval vectors (never a chat model) | embeddings |
Resolving a family yields one model for the group; resolving a single profile yields the possibly-specialised model for that job when the hardware allows it. On a roomy machine best-engine may specialise; on a tight one a family collapses onto one model.
Discover and resolve through the existing CLI / library surface:
best-engine-ai-helper usages list                 # every profile + family (needs, no models)
best-engine-ai-helper usages show text2sql        # one profile's needs
best-engine-ai-helper usages resolve text2sql     # -> the model best-engine picks here
best-engine-ai-helper usages resolve --family F1 --out llm.engine.F1.yaml
from best_engine_ai_helper import resolve_usage, resolve_family, list_usages

for u in list_usages():
    print(u["name"], u["family"], u["status"])

engine = resolve_usage("text2sql")  # best-engine chooses the model for THIS machine
family = resolve_family("F1")  # one model for the whole constrained-generation group
best-engine writes the retained models into the gitignored llm.engine*.yaml for this machine (the extension of the env.sh it already emits); the app reads that file and re-resolution re-decides if the hardware changes. Adding a profile is a few lines in usages.yaml; a user overlay at ~/.best-engine-ai-helper/usages_cache.yaml overrides by name.
Use it as an agent skill
skills/best-engine-ai-helper/ packages best-engine-ai-helper as a Claude Skill and an OpenCode
skill, so an agent can reach for it on your behalf. See
skills/README.md to install it (symlink into
~/.claude/skills/ and ~/.opencode/skills/), and
TRIGGERS.md for the exhaustive trigger catalogue —
scripts/check_triggers.py keeps the skill's description in sync with it, and
the test suite fails if a capability stops being named.
Author
Acknowledgements
Special thanks to Victor Favreau for fruitful discussions.
License
BSD-3-Clause. Copyright 2026 Warith Harchaoui.
1 maintainer

Metadata
1 maintainer
Release files for best-engine-ai-helper 1.10.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| best_engine_ai_helper-1.10.0.tar.gz | 1.8 MB | Without provenance | Details for best_engine_ai_helper-1.10.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| best_engine_ai_helper-1.10.0-py3-none-any.whl | Python 3 | none | any | Details for best_engine_ai_helper-1.10.0-py3-none-any.whl |
Total release size: 3.4 MB
Release files / best_engine_ai_helper-1.10.0.tar.gz
| Download URL | best_engine_ai_helper-1.10.0.tar.gz |
|---|---|
| Size | 1.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
44e7809587ff840d16afc716ed16ef187a1d31e715d6084a4652842174b3d443
|
|
BLAKE2b-256 checksum How to use checksums |
882f5bc9b200fb4db48aeffd6d90a77e8a1bc84768b53cc18eac35df2d551314
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|
Release files / best_engine_ai_helper-1.10.0-py3-none-any.whl
| Download URL | best_engine_ai_helper-1.10.0-py3-none-any.whl |
|---|---|
| Size | 1.6 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1d8c7bbb4f2b3b620e63413b019ea0716ebc5fb8a9b6cdfb77abbf470b1d9964
|
|
BLAKE2b-256 checksum How to use checksums |
5b603ba9fd59012f51de475a93247ae4af09bef37a99739616de4ce12e27df81
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|
Security for best-engine-ai-helper 1.10.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














