
docket — local document AI, invoice & receipt OCR parser with LLMs
Turn scanned invoices, receipts, and contracts into structured, validated JSON using local OCR and vision-language models — and export them as EU e-invoices (XRechnung, ZUGFeRD / Factur-X, Peppol UBL, Facturae).
Apache-2.0 licensed: use it in your own products, commercial or not. Embed it as a Python library, run it as an HTTP service, or call the CLI.
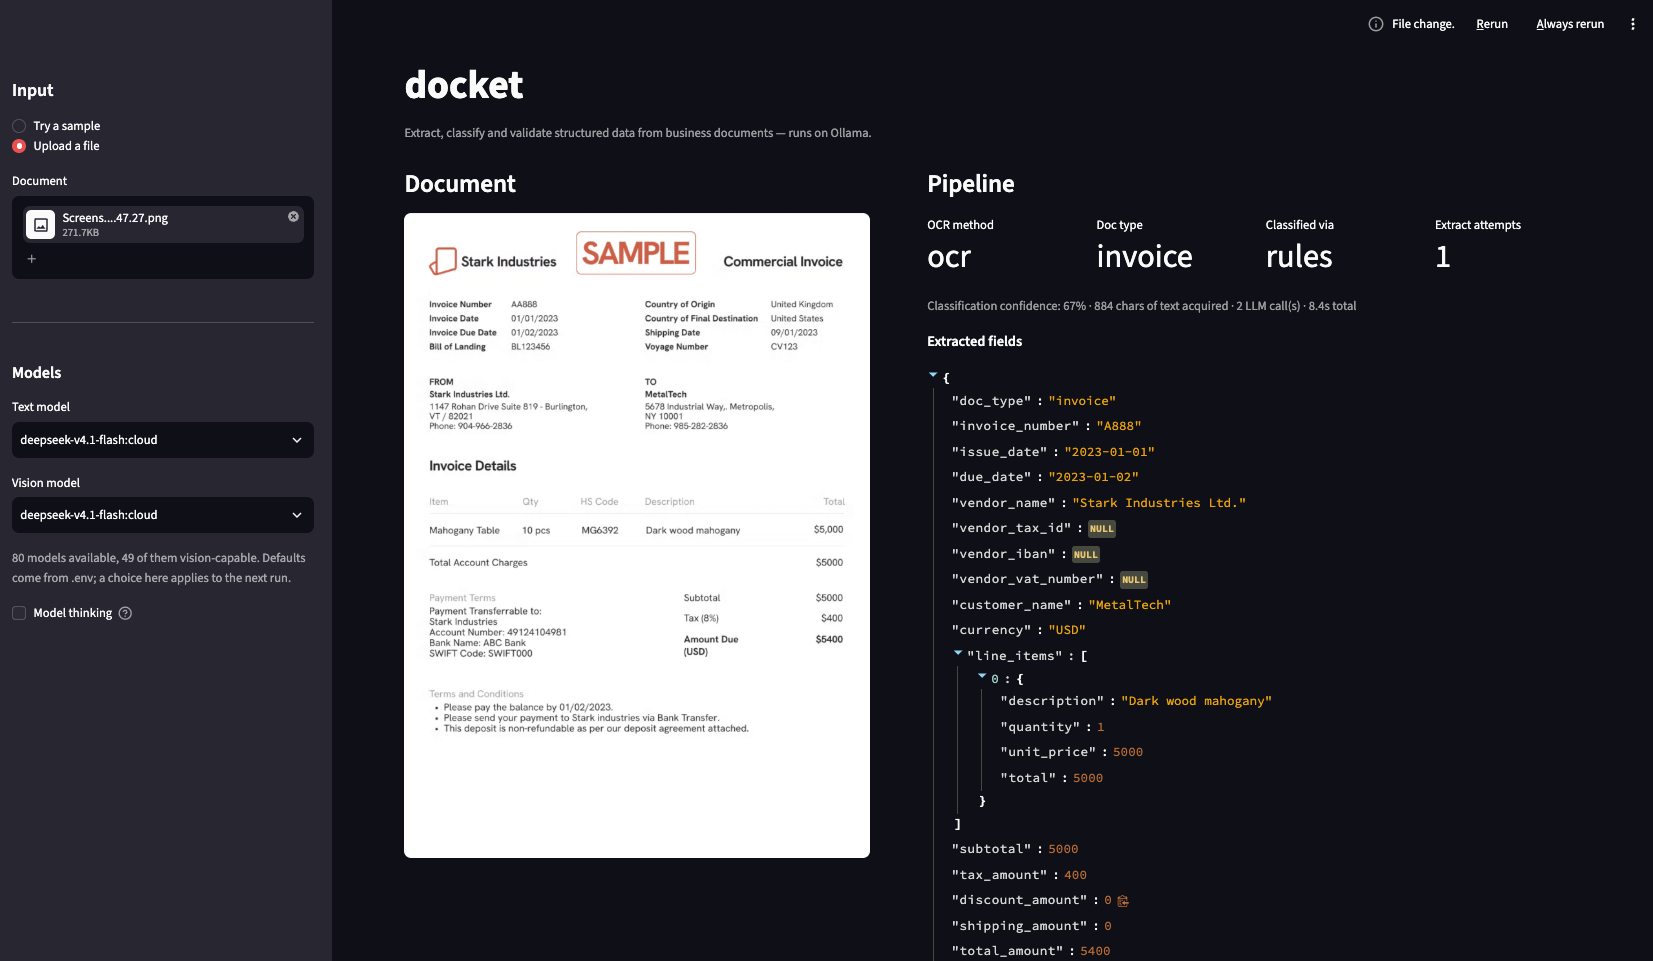
Runs locally with Ollama or on any OpenAI-compatible API (Mistral, OpenAI, Azure, vLLM) · Pydantic schemas · Grounded citations · Zero hallucinations
Quick start: local invoice & receipt parsing
You need Tesseract on PATH (brew install tesseract, apt install tesseract-ocr) and an LLM: either Ollama with a text
and a vision model pulled, or an OpenAI-compatible API key (see
Configuration).
pip install docket-idp
docket invoice.pdf
Classification, OCR extraction, and validation all run against whichever
models your environment or .env names.
{
  "doc_type": "invoice",
  "invoice_number": "FAC-2026-0042",
  "issue_date": "2026-03-15",
  "vendor_name": "Talleres Montjuïc S.A.",
  "subtotal": 1234.56,
  "tax_amount": 259.26,
  "total_amount": 1493.82,
  "currency": "EUR"
}
The process exits non-zero when validation fails, so it drops into a shell pipeline as-is.
Use it in your application
As a Python library
from docket import Invoice, export_document, process

result = process("invoice.pdf", enqueue_review=False)  # your app owns the review flow
if result.is_valid and isinstance(result.document, Invoice):
    print(result.document.vendor_name, result.document.total_amount)
    xml = export_document(result.document, "xrechnung")
else:
    print(result.review_reasons, result.validation_issues)
result.document is the typed schema (Invoice, Receipt, Contract, …);
result.field_sources says where on the page each value was read.
As an HTTP service (any language)
docker run -p 8000:8000 -e DOCKET_API_KEY=secret ghcr.io/kazkozdev/docket
# or: pip install "docket-idp[api]" && docket-api --port 8000
curl -H "Authorization: Bearer secret" -F file=@invoice.pdf localhost:8000/process
The OpenAPI spec is in docs/openapi.json —
generate a typed client for TypeScript, Java, C#, Go, etc. from it.
As a CLI
docket invoice.pdf                       # JSON on stdout, exit code 2 if invalid
docket invoice.pdf --export xrechnung    # e-invoice XML on stdout
docket --list-formats
Runnable versions of all three, a TypeScript client, a Mistral-backed
docker-compose.yml and an exporter plugin are in examples/.
EU e-invoicing and ERP export
| Format | --export / export_document(…) name |
|---|---|
| XRechnung (CII) | xrechnung |
| ZUGFeRD 2.2 / Factur-X, EN 16931 | zugferd |
| UBL 2.1 / Peppol BIS Billing 3.0 | ubl |
| Facturae 3.2.2 (Spain) | facturae |
| SAP IDoc / journal CSV | sap-idoc, sap-csv |
| Xero, QuickBooks | xero-csv, xero-json, quickbooks-iif, quickbooks-json |
Need a format that isn't here? Register one in a few lines
(register_exporter("my-erp", func, accepts=(Invoice,))), or ship it as its own
pip package through the docket.exporters entry point — see
examples/exporter_plugin.
Always validate generated XML against your recipient's official validator
(e.g. KoSIT for XRechnung) before going live.
Structured data extraction with Pydantic schemas
Each document type has a strict Pydantic schema, and the model fills it under a JSON Schema contract rather than being asked nicely for JSON. A result that fails validation is sent back to the model with the error attached.
docket invoice.pdf
python tui.py invoice.pdf        # same pipeline, live per-stage progress
streamlit run app.py             # browser UI with a document preview
European and American number conventions are both parsed, so 1.234,56 and
1,234.56 read as the same amount. Keyword rules cover English and Spanish.
Commercial contracts & CLM analysis
docket eval/golden_dataset/contract_services.txt
{
  "doc_type": "contract",
  "contract_title": "SERVICES AGREEMENT",
  "parties_a": ["Vertex Consulting LLC"],
  "parties_b": ["Meridian Retail Inc."],
  "effective_date": "2026-03-01",
  "expiration_date": "2027-03-01",
  "governing_law": "State of New York",
  "payment_terms": "within 30 days of invoice",
  "auto_renewal": false,
  "key_obligations": [
    "Party A shall deliver monthly infrastructure audits.",
    "Party A shall provide a dedicated support engineer during business hours.",
    "Party B shall pay Party A within 30 days of invoice."
  ]
}
Contracts undergo specialized legal validation: counterparty cross-checking (parties cannot contract with themselves), grounding checks (parties, governing law, payment terms, signatories, and liability caps must appear in the raw document), and automated risk assessment (unlimited liability, auto-renewal traps, notice and cure period bounds).
Human-in-the-loop (HITL) review queue for flagged documents
Low classification confidence, a failed extraction or an error-severity validation issue routes the document to a review queue instead of a database. Each entry gets a stable id, a status, the preserved original, and an audit history of who changed what.
docket eval/golden_dataset/invoice_bad_total.txt
doc_9479a6b321e02ab6de25  pending  invoice
    validation error: total_amount — subtotal + tax + shipping - discount = 270.60,
    total_amount says 500.00
That document prints Amount Due: 500.00 while its own subtotal and tax add up
to 270.60. Nothing silently reconciles it.
Embedding docket in an app with its own review UI? Pass
process(..., enqueue_review=False) (or set DOCKET_REVIEW_QUEUE_ENABLED=false)
and act on result.needs_review / result.review_reasons yourself.
Document AI REST API with FastAPI and async worker
DOCKET_API_KEY=secret docket-api
curl -H "Authorization: Bearer secret" -F file=@invoice.pdf localhost:8000/process
POST /process runs synchronously; POST /jobs queues and returns 202 with a
job id for GET /jobs/{id}. GET /review-queue lists what is waiting for a
person, and /review-queue/{id}/original returns the document that produced it.
Interactive OpenAPI docs at /docs.
Pipeline architecture: hybrid OCR, classification, and validation
Text comes from the cheapest source that works: a PDF text layer if there is one, Tesseract for scans, and a Vision-Language Model (VLM) only when OCR confidence is low or a cheap text model judges the scan unusable. Classification tries keyword rules, then a TF-IDF model, then an LLM — each tier runs only because the last was not confident. Extraction fills a Pydantic schema and cites, for every number, the verbatim line it was read from.
Validation is completely deterministic and never calls a model: it checks arithmetic, date ranges, IBAN mod-97 (ISO 7064 across Europe & Brazil), VAT check digits (all 27 EU member states, UK, Switzerland, Norway), national tax IDs (US EIN, Canadian BN, Brazilian CNPJ/CPF), and asserts that each cited line exists and contains the number claimed. Detailed flow in ARCHITECTURE.md.
document → text layer / OCR / VLM → classify → extract + cite → validate → JSON or review
Configuration
| Option | Default | What it does |
|---|---|---|
DOCKET_LLM_PROVIDER |
ollama |
ollama, or openai for any OpenAI-compatible API |
DOCKET_LLM_BASE_URL |
https://api.openai.com/v1 |
Endpoint when provider is openai (e.g. https://api.mistral.ai/v1) |
DOCKET_LLM_API_KEY |
unset | API key when provider is openai |
DOCKET_TEXT_MODEL |
deepseek-v4.1-flash:cloud |
Model for classification and extraction |
DOCKET_VISION_MODEL |
deepseek-v4.1-flash:cloud |
Model for transcribing scans |
OLLAMA_HOST |
http://localhost:11434 |
Where Ollama is listening |
DOCKET_OCR_LANG |
eng |
Tesseract languages, e.g. eng+deu+fra+spa+ita |
DOCKET_ENABLE_THINKING |
false |
Reasoning tokens; off is markedly faster for this task |
DOCKET_MIN_CONFIDENCE |
0.55 |
Classification confidence below which a document goes to review |
DOCKET_TFIDF_CONFIDENCE_FLOOR |
0.65 |
TF-IDF confidence needed to skip the LLM tier |
DOCKET_OCR_QUALITY_CHECK |
true |
Ask a cheap model whether a scan is usable before extracting |
DOCKET_VISION_TIMEOUT_S |
300 |
Vision call timeout |
DOCKET_MAX_FILE_BYTES |
20971520 |
Upload limit for the API |
DOCKET_MAX_PDF_PAGES |
100 |
Page ceiling per document |
DOCKET_API_KEY |
unset | Bearer token; the API refuses requests without it when set |
DOCKET_REVIEW_QUEUE_ENABLED |
true |
Write flagged documents to the file-based review queue |
DOCKET_REVIEW_QUEUE |
data/review_queue.jsonl |
Review journal path |
Full list in src/docket/config.py; LANGFUSE_PUBLIC_KEY and
LANGFUSE_SECRET_KEY enable optional tracing.
Requirements
- Python 3.10+
- macOS or Linux
- Tesseract OCR on PATH
- An LLM: a running Ollama with one text and one vision model pulled, or an OpenAI-compatible API (Mistral La Plateforme keeps data in the EU)
Limitations
- Four document types: invoice, receipt, contract, boarding pass.
- Keyword rules and the TF-IDF corpus cover English and Spanish only.
- The vision model has been observed altering digits to make a page reconcile — a printed
450.00read three times out of three as480.00. No fix for that is in this repo. - Line items carry no source citations, so the cited-source check does not cover them.
- The review queue is one file: durable on one node, not across hosts.
- Windows is untested; CI runs Linux only. 3.6–9.5 s per document, more when a page needs the vision model.
Manual installation, Docker, development setup
Install options
pip install docket-idp            # library + CLI
pip install "docket-idp[api]"     # + HTTP service (docket-api)
pip install "docket-idp[all]"     # + Streamlit UI, terminal UI, Langfuse tracing
From source
git clone https://github.com/KazKozDev/docket.git
cd docket && python3 -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
cp .env.example .env
On macOS, double-clicking start.command creates the venv, starts Ollama if
needed, frees ports 8000/8501 and opens the UI.
Docker
docker run -p 8000:8000 -v docket-data:/app/data ghcr.io/kazkozdev/docket
# or build it yourself: docker build -t docket .
The image ships Tesseract with the main EU language packs and talks to Ollama
on the host by default; set the DOCKET_LLM_* variables to use a hosted API
instead.
Development
pytest                                # none need a running LLM
python eval/run_eval.py               # accuracy, P/R/F1, latency on the golden set
python eval/benchmark_methods.py      # the rules vs TF-IDF vs LLM comparison




1 maintainer

Release files for docket-idp 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| docket_idp-0.1.0.tar.gz | 134.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| docket_idp-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 233.5 kB
Release files / docket_idp-0.1.0.tar.gz
| Download URL | docket_idp-0.1.0.tar.gz |
|---|---|
| Size | 134.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
126d18e7e83bbbbc8dacd09d4de5687d033aa498070304dfa8cd91dd74b99480
|
|
BLAKE2b-256 checksum How to use checksums |
7ac054b90d5e10fdbacee7436f589e965c54c5092eeb6faca223fff4239e2207
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 21, 2026.
Transparency logRelease files / docket_idp-0.1.0-py3-none-any.whl
| Download URL | docket_idp-0.1.0-py3-none-any.whl |
|---|---|
| Size | 99.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
deb94c23ca304a520471f9300e3deb9665b3f8a0db9405acf1409a9048241c43
|
|
BLAKE2b-256 checksum How to use checksums |
92df943b9de9fce187823e5b490258801ac49c85c621dcd09cd45c7e21ecee3d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 21, 2026.
Transparency log












