
docket — invoice and receipt OCR for Python with LLMs
Extract data from invoices, receipts and contracts with a source line for every field, check it with plain code, and flag what a person must review.
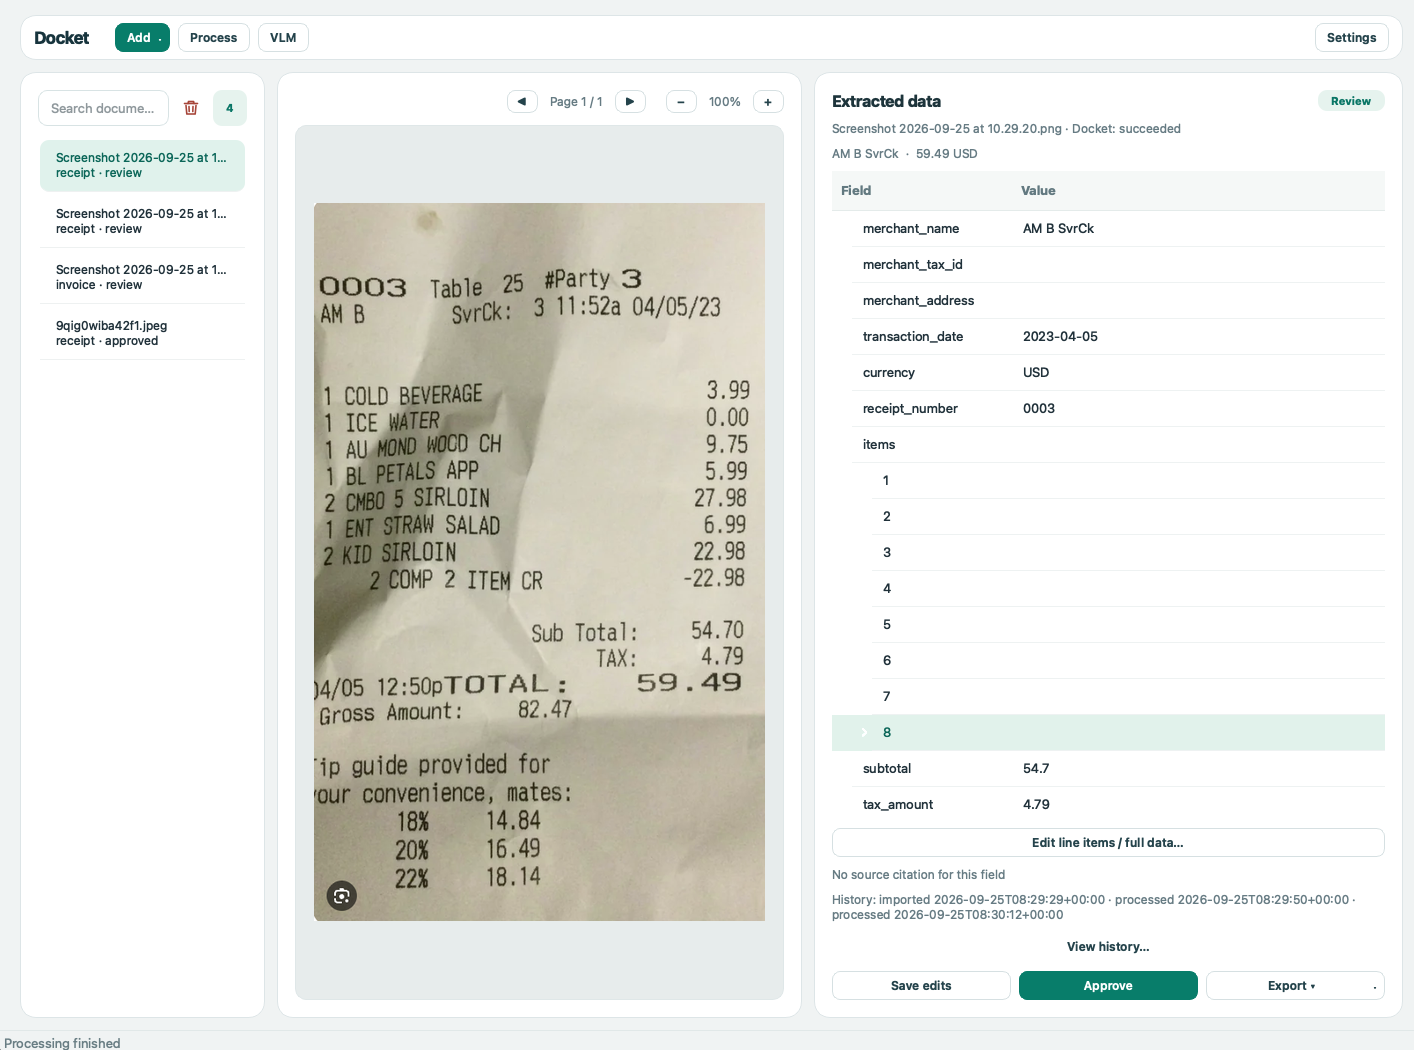
Docket Desktop
Quick start
You need Python 3.10+, Tesseract for scans, and a text model you run or reach: Ollama, or any OpenAI-compatible server (vLLM, llama.cpp, LM Studio, a hosted API). Docket picks no model: set DOCKET_TEXT_MODEL, and DOCKET_VISION_MODEL for the default OCR fallback. Language models has local recipes. Check the active settings with docket config show.
docket process invoice.pdf
The command prints a JSON result with extracted fields, source citations, validation issues and review reasons. Its exit code is 0 for succeeded, 1 for needs_review, 2 for failed, or 3 for a configuration error.
Extract invoice, receipt and contract data in Python
Use the typed result in your own application. Keep results needing review out of automatic downstream updates.
from docket import DocumentStatus, ProcessOptions, process_document

result = process_document("invoice.pdf", ProcessOptions(document_type="invoice"))
if result.status == DocumentStatus.SUCCEEDED:
    print(result.document)
    print(result.field_sources.get("total_amount"))
else:
    print(result.status.value, result.review_reasons)
result.document is a Pydantic schema; each available field source includes its page, quote and location. Seven built-in document types are listed by docket schemas list. You can register another schema or OCR backend; see the examples.
Process invoices and receipts in a folder into CSV
Batch processing writes a summary CSV, a line-item CSV and a checkpoint file. Repeating the command resumes completed documents; one failure does not stop the rest.
docket batch scans/ --recursive --workers 4 --format csv --output results.csv
Use --format jsonl for one complete result per line or --ocr-backend paddle after installing the optional PaddleOCR backend.
Validate and export European e-invoices from PDFs
Install the validator and fetch official rule files that cannot be shipped in the package. Export is refused when the extracted result needs review or the invoice cannot be represented faithfully.
pip install "docket-idp[einvoice]"
docket einvoice fetch
docket process invoice.pdf --document-type invoice --export xrechnung-ubl --validate-export -o invoice.xml
Other built-in formats include UBL, Peppol, XRechnung CII, Factur-X and Facturae (docket formats). Converting a supplier PDF gives you data for your books; it does not issue a legal e-invoice on the supplier's behalf.
How it works
document → read text → classify → extract + cite → check → JSON, or review
- Read the text. A PDF with a usable text layer is read directly, with no OCR and no model. A scan or photo goes through OCR (Tesseract by default, or PaddleOCR or Docling). If OCR confidence is too low, or the text model judges the OCR text to be garbage, the vision model reads the page image instead.
- Classify. Keyword rules decide first, then a TF-IDF model. The text model is asked only when neither is confident.
- Extract. The text model fills the document's schema, such as number, dates, parties, amounts and line items. For every field it cites the line it read the value from. An invoice from a registered vendor template is read by that template, with no model call.
- Check. Plain code, with no model involved, compares each value with the line it cites. It also checks the arithmetic, dates, and IBAN and VAT check digits. If the checks fail, the page is read again by the vision model and the better result is kept. Anything still wrong or uncertain is marked
needs_reviewinstead ofsucceeded. - Output. Every result comes out as JSON (
docket process) or as CSV and JSONL rows (docket batch), with its status and review reasons. An e-invoice export (UBL, Peppol, XRechnung, Factur-X, Facturae) is refused unless the result passed its checks.
The architecture describes the stages and extension points.
Configuration
| Environment variable | Default | Purpose |
|---|---|---|
DOCKET_LLM_PROVIDER |
ollama |
ollama or openai for an OpenAI-compatible endpoint |
DOCKET_TEXT_MODEL / DOCKET_VISION_MODEL |
unset | Extraction model (required) / page-image model |
DOCKET_LLM_STRUCTURED_OUTPUT |
json_schema |
Send the schema to OpenAI-compatible servers for constrained decoding, or json_object |
OLLAMA_HOST |
http://localhost:11434 |
Ollama server URL |
DOCKET_LLM_BASE_URL |
https://api.openai.com/v1 |
OpenAI-compatible API URL |
DOCKET_LLM_API_KEY |
unset | Key for the OpenAI-compatible API |
DOCKET_OCR_BACKEND / DOCKET_OCR_FALLBACKS |
auto / vlm |
Primary OCR / fallback chain |
DOCKET_OCR_LANGUAGES |
en |
Comma-separated language codes, e.g. en,de |
DOCKET_MIN_SOURCE_CONFIDENCE |
0.8 |
Minimum OCR confidence for cited key fields |
DOCKET_CONFIG |
unset | TOML file; environment and explicit options override it; CLI also reads ./docket.toml |
Requirements
- Python 3.10 or newer on macOS or Linux; CI tests Python 3.10–3.12 on Ubuntu.
- Tesseract on
PATHfor scanned pages, or install the optional PaddleOCR or Docling backend. Usable PDF text layers need no OCR engine. - A reachable Ollama server or OpenAI-compatible API, with a text model configured. The
vlmfallback also needs a vision model. - The
[einvoice]extra anddocket einvoice fetchfor official e-invoice validation. - The desktop app is a separate source package in
apps/desktop; its native build targets macOS.
Limitations
- Wrong fields can still pass as
succeeded. Review critical values before use. - The vision model can change digits to reconcile totals.
- Windows is untested. The local macOS app build is unsigned and unnotarized.
- The desktop workflow handles invoices and receipts; contracts and e-invoice tools remain in the library and CLI.
Desktop app, extras, HTTP API and development
Desktop app
From a checkout, install the separate package with python -m pip install -e . -e apps/desktop and run docket-desktop. It imports PDF/images, supports correction and approval, and exports approved data as XLSX, CSV or JSON. See the desktop guide.
Extras
docket-idp[api] adds the HTTP service; [photo] adds photo cropping; [paddle] and [docling] add OCR backends; [review] adds the persistent review queue. See pyproject.toml for the full list.
HTTP API and Docker
docker run -p 8000:8000 -e DOCKET_API_KEY=secret -e DOCKET_TEXT_MODEL=<model> -e DOCKET_OCR_FALLBACKS= ghcr.io/kazkozdev/docket
curl -H "Authorization: Bearer secret" -F file=@invoice.pdf localhost:8000/process
The image looks for Ollama at host.docker.internal:11434; on Linux add --add-host=host.docker.internal:host-gateway. See the OpenAPI specification for endpoints and responses.
Development
git clone https://github.com/KazKozDev/docket.git && cd docket
python3 -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]" && pytest


Issues · Contributing · Security · License · Architecture · Benchmarks · Changelog
1 maintainer

Metadata
1 maintainer
Release files for docket-idp 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| docket_idp-0.5.0.tar.gz | 520.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| docket_idp-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 978.6 kB
Release files / docket_idp-0.5.0.tar.gz
| Download URL | docket_idp-0.5.0.tar.gz |
|---|---|
| Size | 520.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b860b284ccf4d957d6d6f9a836afe044ba0c29b586d906b6220cf97dd135f981
|
|
BLAKE2b-256 checksum How to use checksums |
b2a664fcd32db5bcfdc7f91e9a89bb255023b2874c32e857798262491248f085
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 28, 2026.
Transparency logRelease files / docket_idp-0.5.0-py3-none-any.whl
| Download URL | docket_idp-0.5.0-py3-none-any.whl |
|---|---|
| Size | 458.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c17a1f03c5eee8247437abcf5a003538e279f43970b6b45240b81f7abee61088
|
|
BLAKE2b-256 checksum How to use checksums |
fb1c772a63b3e1cde22615cd2b8c46a42a2ebb33f6672cfd0f64ac8c64f9929f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 28, 2026.
Transparency log













