

Memory SDK — Python client for Kagura Memory Cloud


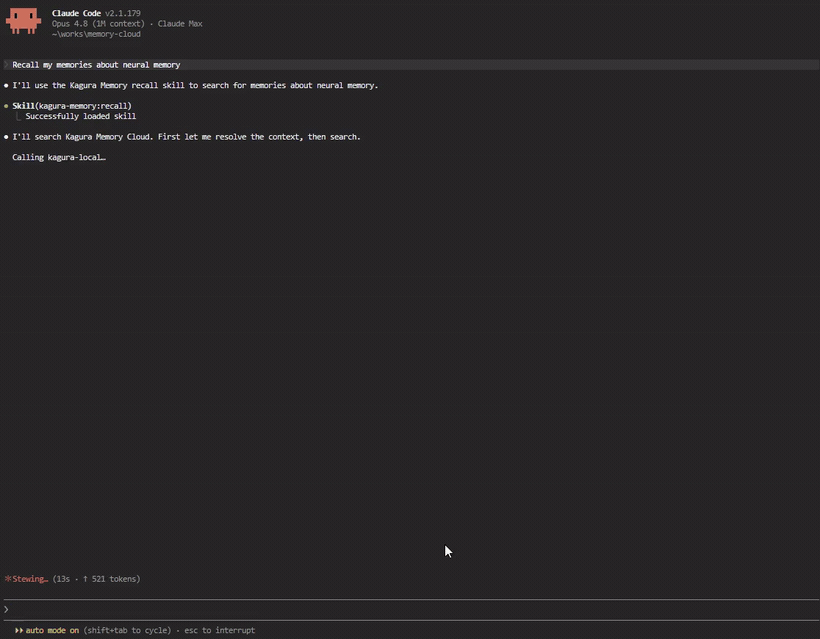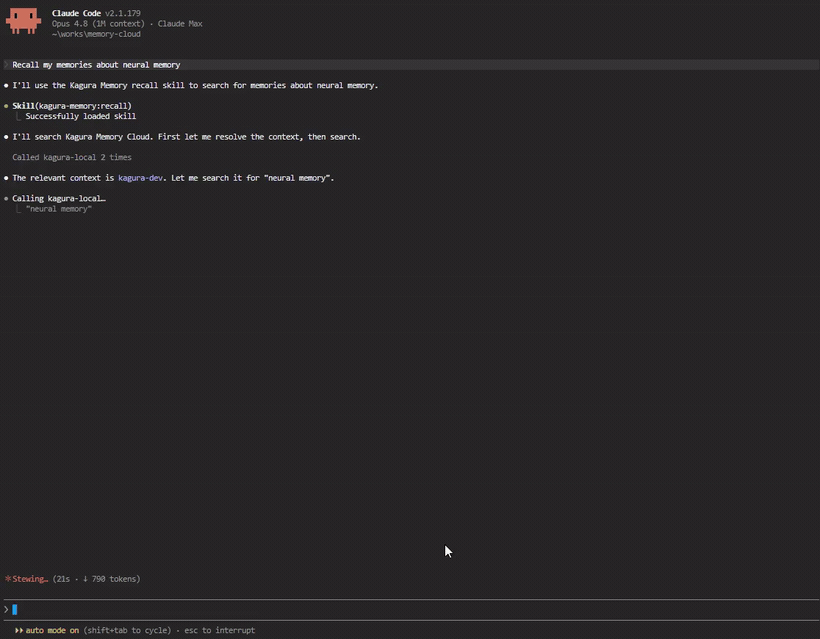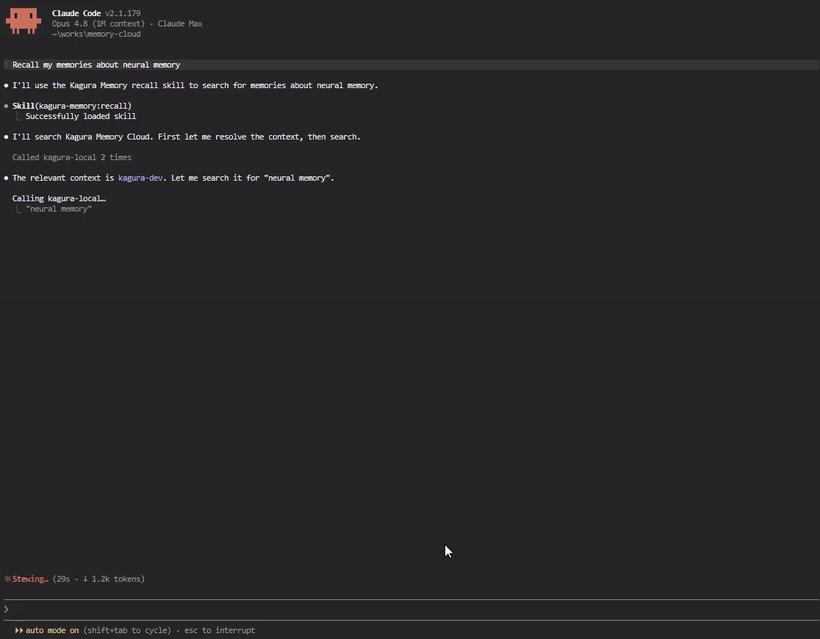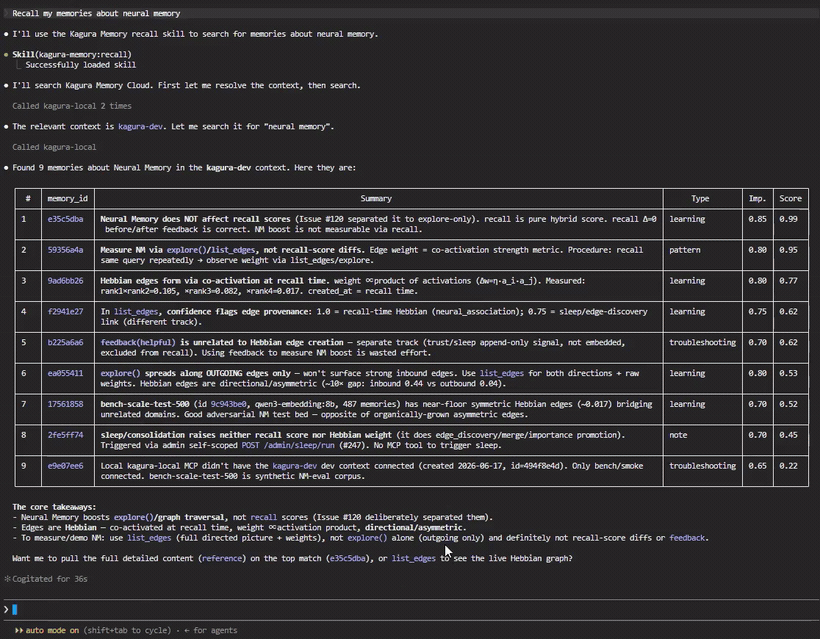
Recall past memories straight from Claude Code — Kagura Memory over MCP.
What is this?
This SDK connects your Python code to Kagura Memory Cloud, giving AI assistants the ability to remember, search, and learn from past interactions — and to ingest documents (PDFs, URLs) directly into a searchable memory graph. It provides seven clients (plus a document ingestor) for different use cases:
| Client | Protocol | Use Case |
|---|---|---|
KaguraClient |
MCP (JSON-RPC) | Direct memory ops — remember, recall, explore, reference, forget |
ResourceClient |
REST API | External data ingestion — push data from Slack, CI/CD, CRM into Kagura |
FilesClient |
REST + presigned PUT | File uploads with sha256 integrity binding (R2); optional per-file context binding for ACL |
SecretClient |
REST + age crypto | Zero-knowledge secrets — age recipient encryption, local decryption (the server only ever stores armored ciphertext) |
WorkspaceClient |
REST API | Workspace member / invitation management + owner-provisioned member keys (owner API key only); context member add and operation history (web session only) |
AgentsClient |
REST API | Agent bootstrap — one-call session-start rehydration for API-key-only callers (server v0.49.0+) |
MemoryClient |
REST API | Tool guardrails for API-key-only hooks and setup scripts — load_guardrails + the AGENTS.md digest (server v0.74.0+) |
FileIngestor |
CLI + SDK | Document ingestion — PDF/Office/HTML/EPUB, audio & YouTube transcripts → memory graph + R2 archive |
60-second demo
Turn a PDF into a structured graph of memories — one overview memory plus per-section summaries, linked via declared_link edges. The original file is archived to your workspace's storage so you can always pull the bytes back.
pip install 'kagura-memory[ingest-pdf]'
kagura auth login
kagura ingest ./report.pdf

kagura recall "report findings" -k 5        # search across sections
kagura files download-url <file_id> -c <context-id>   # short-lived GET on the original
Ingestion extracts text — from PDFs, Office/HTML/EPUB documents, audio/video transcripts, and YouTube captions. Images embedded in a document are detected and counted (IngestResult.skipped_images) but not yet OCR'd: a vision provider (Gemini 2.5 Flash by default) is configured and validated, but the orchestrator does not currently invoke Provider.describe_image() — image-to-text memories are a planned follow-up. Pass --no-vision to skip provider configuration entirely, or --dry-run to see token / cost estimates without calling an LLM.
Sharing OAuth credentials with the TypeScript SDK
Concurrent writers require Python SDK 0.45.0+ and TypeScript SDK 0.16.0+.
Before migrating, stop every old and new CLI, proxy, and SDK process
using the file. Only then manually retire the legacy credentials.json.lock
if present. Do not restart mixed versions against the same credentials file.
Writers now create credentials.json.lock-v1 exclusively. After a crash,
confirm that every participating client has stopped before manually removing
an abandoned marker. Its age alone cannot establish abandonment. Keep the
token-free credentials.json.revocations-v1 alongside the file after logout:
it prevents queued refreshes from restoring a removed profile. Explicit login
can recreate the profile and retains the revocation history.
Installation
pip install kagura-memory                   # core SDK
pip install 'kagura-memory[ingest-pdf]'     # adds PDF ingestion support
pip install 'kagura-memory[ingest-all]'     # all document formats (see below)
# or
uv add kagura-memory
Supported document formats
kagura ingest (and FileIngestor) dispatch to a structural extractor based
on the file's MIME type / extension. Heavy parser dependencies are opt-in
extras — install only what you need, or ingest-all for everything:
| Format | Extensions | Extra | Parser |
|---|---|---|---|
| Plain text / Markdown | .txt, .md |
(none — base [ingest]) |
stdlib |
| HTML | .html, .htm |
[ingest-html] |
beautifulsoup4 |
.pdf |
[ingest-pdf] |
PyMuPDF | |
| Word | .docx |
[ingest-docx] |
python-docx |
| Excel | .xlsx |
[ingest-xlsx] |
openpyxl |
| PowerPoint | .pptx |
[ingest-pptx] |
python-pptx |
| EPUB | .epub |
[ingest-epub] |
PyMuPDF (reused) |
Each extractor is pure-parse — no network, no LLM. It maps the document
into structural sections (Markdown/HTML headings, Word heading styles, one
section per sheet/slide, PDF/EPUB outline) that the chunker and summarizer
then turn into memories. Office and EPUB files are ZIP containers, so each
extractor enforces decompression-bomb caps (max sheets/rows/slides/pages and
total decoded text). A missing extra surfaces as a clear
KaguraIngestError naming the package to install.
Quick Start
Configuration
Copy the example and fill in your credentials:
cp .kagura.json.example .kagura.json
# Edit .kagura.json — set api_key and mcp_url
Used by the CLI (kagura commands) and load_config() in Python code:
{
  "api_key": "kagura_your_api_key",
  "mcp_url": "http://localhost:8080/mcp/w/{workspace_id}",
  "context_id": "auto"
}
Or use environment variables: KAGURA_API_KEY, KAGURA_MCP_URL, KAGURA_CONTEXT_ID
Get your API key from the Kagura Memory Cloud Web UI: Integrations > API Keys
Looking for
KaguraAgent? The LLM-powered session-analysis actor was removed in v0.37.0 — its role moved to dedicated ecosystem packages: kagura-agent (memory-backed autonomous agent) with kagura-brain as its LLM head, while conversation→memory compilation is handled server-side (Memory Analysis) and by the connector workers. This SDK stays a pure substrate client, and base installs no longer pull thelitellmdependency tree (it now ships with the[ingest]extra).
Ollama for ingestion
kagura ingest reads OLLAMA_API_KEY and OLLAMA_API_BASE from the environment (litellm picks them up directly for the ollama_chat/ route), for both local Ollama and Ollama Cloud (ollama signin sets the key automatically):
export OLLAMA_API_KEY="..."          # Ollama Cloud only; local needs no key
export OLLAMA_API_BASE="https://ollama.com"
kagura ingest report.pdf --text-provider ollama
The ingest provider uses litellm's ollama_chat/ route (system messages preserved), so cloud and local share the same code path.
KaguraClient — Direct Memory Operations
For programmatic control without LLM:
from kagura_memory import KaguraClient

async with KaguraClient(api_key="kagura_...", mcp_url="https://...") as client:
    await client.remember(context_id="dev", summary="OAuth2 pattern", content="Use Authlib...")
    results = await client.recall(context_id="dev", query="OAuth2", k=5)
    await client.explore(context_id="dev", memory_id="uuid", depth=3)

    # Filtered recall — ALL listed tags, optional date range
    results = await client.recall(
        context_id="dev", query="budget",
        filters={"tags": ["予算", "2026"], "tags_match": "all",
                 "created_after": "2026-03-01T00:00:00Z"},
    )

    # Cross-context recall — search several contexts at once
    results = await client.recall(query="auth", context_ids=["ctx-1", "ctx-2"], k=10)

    # Result shape. Since memory-cloud v0.108.0 hits are compact by default: a 160-char
    # summary head (summary_cut=True when cut) without tags or context_summary.
    # verbosity="full" adds tags, context_summary, scope, version and the uncut summary.
    # Since v0.114.0 the top `full` hits also carry content (up to 1,500 chars each;
    # the deployment default is 3, full=0 means summaries only), and max_chars
    # (10,000-100,000, default 20,000; v0.82.0+) bounds the whole reply. All three are
    # keyword-only and sent only when set; a server from 0.82.0 that predates one refuses it
    # (KaguraError, invalid_argument) and the library does not retry: `kagura recall` does.
    detailed = await client.recall(context_id="dev", query="OAuth2", verbosity="full", full=0)
    for hit in detailed["results"]:
        print(hit["summary"], hit.get("tags", []))  # empty tags are omitted, not []
    top = await client.recall(context_id="dev", query="deploy runbook", full=1, max_chars=40_000)
    # top["results"][0]["content"]; with content_truncated, reference() has the whole memory

    # explore_hints follow the MCP URL's tool list (v0.135.0+): add ?add_tools=explore
    # or ?profile=full to mcp_url, or the reply carries explore_hints_omitted instead.
    hinted = await client.recall(context_id="dev", query="auth", include_explore_hints=True)
    seeds = hinted.get("explore_hints") or []

    # Optional response keys (degraded, tag_suggestions, ...) are absent when they do not apply — use .get().
    # degraded=True: the semantic half was down, so results are keyword-only (v0.66.0+);
    # an empty result then means "search impaired", not "nothing stored".
    # tags_normalize also matches "Dev_Environment" for "dev-environment" (v0.65.0+).
    results = await client.recall(context_id="dev", query="setup",
                                  filters={"tags": ["dev-environment"], "tags_normalize": True})
    if results.get("degraded"):
        print("keyword-only:", results.get("degraded_reason"))

    # Reranking is tri-state (memory-cloud v0.69.0+). Omit use_rerank to follow the
    # context's search config (update_search_config); True requests it, applied only
    # when the context enables it; False skips it for this call, e.g. to save latency.
    # With context_ids, the first listed context's config decides.
    # Servers before v0.69.0 rerank only on True.
    fast = await client.recall(context_id="dev", query="OAuth2", use_rerank=False)

    # Find a context by name. On memory-cloud v0.73.0+ rows are slim
    # (id/name/is_private/is_locked/last_used_at); summaries are opt-in.
    found = await client.list_contexts(name_contains="auth", include_summary=True, limit=50)
    # From v0.82.0 the directory is paged (100 a page; limit=1-200 picks the size, at
    # most 20 with include_details and no name_contains): pass next_cursor back with
    # the same other arguments, limit included.
    if found.get("has_more"):
        more = await client.list_contexts(name_contains="auth", include_summary=True,
                                          limit=50, cursor=found["next_cursor"])

    # Trust-tier filter (provenance) — exclude untrusted / connector-ingested
    # memories from behaviour-influencing reads (OWASP LLM01/LLM03)
    safe = await client.recall(context_id="dev", query="policy",
                               filters={"trust_tier": "trusted"})
AI agent memory substrate
Primitives for autonomous agents — a deterministic load path, a retrieval-feedback signal, and a TTL-bounded run-state lane kept separate from knowledge:
async with KaguraClient(api_key="kagura_...", mcp_url="https://...") as client:
    # Deterministic delivery — pin on write, load the full pinned set every turn
    # (Goal / critical-policy memories, distinct from probabilistic recall).
    # For a rule tied to a tool call, use a tool guardrail (next section).
    await client.remember(context_id="dev", summary="Goal: ship the v2 importer by June",
                          content="...", delivery_mode="always")
    pinned = await client.load_pinned(context_id="dev")

    # Time Memories — deterministic "what's upcoming" query (no semantic search).
    # Items carry `trigger` on server v0.73.0+; include_details=True returns `details`.
    upcoming = await client.recall_upcoming(context_id="dev", from_="now")

    # WHERE axis — deterministic "what's near here" query, nearest first
    # (SDK v0.38.0, server v0.53.0+). radius_m/k/include_details are keyword-only.
    # lat/lon must be JSON numbers; the server 422s string-typed coordinates.
    saved = await client.remember(context_id="dev", summary="Coffee with Sato", content="...",
                                  details={"location": {"lat": 35.68, "lon": 139.76, "label": "Tokyo HQ"}},
                                  observed_at="2026-11-04")  # when it held (server v0.127.0+)
    nearby = await client.recall_nearby(context_id="dev", lat=35.68, lon=139.76, radius_m=500)
    # Items carry `location` (server v0.82.0+); include_details=True returns `details`.
    # update_memory(details=...) REPLACES details wholesale — no deep-merge. Re-send
    # location, or change only some keys with details_patch (server v0.140.0+; a None
    # value deletes a key), or this drops off the map.
    await client.update_memory(context_id="dev", memory_id=saved["memory_id"],
                               details_patch={"status": "done"}, add_tags=["status:done"],
                               expected_version=saved["version"])  # else KaguraVersionConflictError
    # Map viewport over the REST list (SDK v0.40.0, server v0.54.0+): keyword-only,
    # one-sided bounds OK, any bound keeps only located memories (item.location).
    page = await client.list_memories(context_id="dev", lat_min=35.5, lat_max=35.9,
                                      lon_min=139.5, lon_max=140.0)

    # HOW-MUCH axis — an append-only numeric series (SDK v0.40.0, server v0.54.0+).
    # Separate from memories: never embedded, never returned by recall(), never
    # merged or rewritten by Sleep consolidation. No delete — an operator-set
    # retention window is the only thing that removes rows (docs/compatibility.md, 0.40.0).
    # Raw numbers here; prose ("hit goal weight") via remember().
    await client.record_measurement(context_id="dev", metric="weight_kg", value=71.5,
                                    unit="kg")  # measured_at: ISO str or datetime (naive = UTC)
    weekly = await client.recall_series(context_id="dev", metric="weight_kg",
                                        period="week", agg="avg")  # default: last 30 days
    for b in weekly.series:  # empty buckets omitted; max window 365 days
        print(b.bucket, b.value, b.count)

    # Supersede — store a newer version WITHOUT destroying history (server v0.45.0+).
    # The old memory is shadowed, not deleted: it leaves default recall but stays
    # reachable, and deleting the edge restores it. Prefer this over forget() +
    # remember(), which throws away the history the supersede edge exists to keep.
    await client.remember(context_id="dev", summary="Deploy target: ap-northeast-1",
                          content="...", supersedes="old-memory-uuid")
    # Read the history back. NOTE: a top-level argument, NOT a filters key.
    history = await client.recall(context_id="dev", query="deploy target",
                                  include_superseded=True)  # results carry superseded_by
    # Reject a wrong supersede_candidate suggestion (server v0.65.0+; memory_id only).
    res = await client.update_memory(context_id="dev", memory_id="uuid",
                                     dismiss_supersede_candidate=True)
    # Only res.get("supersede_candidate_dismissed") confirms it: older servers drop the flag.

    # Retrieval feedback — teach the substrate which recall results were useful
    await client.feedback(context_id="dev", memory_id="uuid", helpful=True, query="OAuth2")

    # Agent session-state lane — TTL-bounded, structurally excluded from recall()
    await client.set_state(context_id="dev", key="step", value={"n": 3}, ttl_seconds=3600)
    state = await client.get_state(context_id="dev", key="step")  # omit key → all live entries
    # Values are capped at 16,384 characters of compact JSON (ValueError before any
    # request). From v0.82.0 the list mode is paged (limit 1-200, default 50; max_chars
    # 10,000-100,000): get_state("dev", cursor=page["next_cursor"], limit=100).
    # cursor/limit/max_chars belong to list mode: with key they raise ValueError.
Tool guardrails (v0.39.0, server v0.74.0+)
A memory whose details.tool_trigger names a tool (and optionally a pattern in its
input) is a tool guardrail: a client-side hook injects its summary when a matching
call happens (action="inform"), or denies the call with the summary as the reason
(action="block"). The server validates the patterns on write and never runs them;
matching happens in the hook, which loads the set deterministically with
load_guardrails:
from kagura_memory import KaguraClient, MemoryClient, ToolTrigger

CTX = "ctx-uuid"

async with KaguraClient() as client:
    # Needs context editor+ and a user credential (agent-bound keys can read, not author).
    await client.remember(
        context_id=CTX,
        summary="Never force-push to main; open a PR instead",
        content="...",
        tool_trigger=ToolTrigger(tool="Bash", match=r"git\s+push\s+--force", action="block"),
    )

    # Two independently capped lanes (pinned + tool_triggered), never silently cut.
    rails = await client.load_guardrails(CTX)
    if rails.tool_triggered_truncated:
        rails = await client.load_guardrails(CTX, cap=1000)

    # Hookless clients get the tool-triggered set in the get_context_info() block.
    info = await client.get_context_info(CTX)
    block = info.guardrails  # None when the MCP URL carries ?guardrails=off

async with MemoryClient.from_mcp_url() as memory:  # REST twin for API-key hooks / scripts
    rails = await memory.load_guardrails(CTX)
    digest = await memory.get_guardrail_digest(CTX)  # the AGENTS.md export block
    print(digest.tool_triggered_version)             # changes when the set changes
update_memory(details=...)replacesdetailswholesale: re-sendtool_triggerwith any other details you change, or the memory stops being a guardrail — or change only some keys withdetails_patch(server v0.140.0+;tool_trigger=merges into it). Passing bothtool_trigger=and a"tool_trigger"key raisesValueError.forgetsilently skips a guardrail the caller may not delete (below context editor, or an agent-bound key), sodeleted_countcan be0with no error.- A hook that caches the set treats a
GuardrailSet.formatgreater thanGUARDRAIL_FORMATas absent (fail-open):formatbumps only when a field changes meaning. - With an OAuth profile,
MemoryClient.load_guardrails(aPOST) needsmemory:write; a--read-onlylogin loads the set throughKaguraClient.load_guardrails(MCP) instead. kagura guardrails digest <ctx> --out AGENTS.mdkeeps an always-loaded file in sync (see CLI). The block is workspace memory, not repository content: point--outat an untracked file, or rungit update-index --skip-worktree AGENTS.mdon a tracked one, so the guardrail summaries never land in a commit (or, in a public repository, get published).
Session start, change log and batch writes (server v0.93.0+)
bootstrap opens an interactive session on one context in one deterministic call (no
recall): the context block, its tool guardrails, the pinned memories, the upcoming Time
Memories and what changed since a time, each lane fail-soft (degraded). changes_since
pages the change log on, list_matching (the MCP list tool) returns every memory that
matches exact filters with a total, remember_batch stores up to 50 memories in one call
and forget(memory_ids=[...]) deletes up to 50 with one result row per id:
async with KaguraClient() as client:
    start = await client.bootstrap("ctx-uuid", since="7d", format="index", max_chars=5000)
    changes = start.components.changes                # None when include= leaves it out
    if changes and changes.status == "ok":
        for row in changes.changes:
            print(row.kind, row.memory_id, row.summary)  # summary is None once forgotten
    for notice in start.plan_headroom or []:          # server v0.142.0+: a cap at 80 %+
        print(notice.level, notice.dimension, notice.help)

    page = await client.changes_since("ctx-uuid", "2026-11-01T00:00:00Z", kinds=["created"])
    backlog = await client.list_matching(
        "ctx-uuid", filters={"type": ["tech-debt"], "tags": ["status:open"]}
    )

    saved = await client.remember_batch("ctx-uuid", [
        {"summary": "Decision: ship the session tools", "content": "PR review", "type": "decision"},
        {"summary": "Lesson: page changes by cursor", "content": "#301", "type": "lesson"},
    ], atomic=True)                                   # all or nothing; failed excludes skipped
    ids = [r.memory_id for r in saved.results if r.memory_id]
    gone = await client.forget("ctx-uuid", memory_ids=ids)
    print(gone.succeeded, [r.status for r in gone.results])  # deleted | skipped | error
bootstrap(format=...) and a max_chars below 10,000 need server v0.115.0+, forget(memory_ids=)
v0.117.0+. describe_tools / guide read the tools a URL does not list and the server's tool
manual (v0.93.0+), list_revisions a memory's revision log (v0.113.0+), and rollback_session
plans (dry_run=True, the default, always sent) or undoes one session's writes, or the caller's
own in a window of at most 7 days (v0.113.0+; window v0.114.0+). Each method raises
KaguraResponseError on a reply it cannot read. A batch that wrote nothing raises KaguraError:
code == "batch_failed" (every item or id failed) or "batch_refused" (an atomic
remember_batch with an invalid item) carries the rows in details["results"], while
"timeout" (an atomic batch rolled back at its time limit) carries none, so send fewer items or
drop atomic. An atomic batch over the daily quota raises KaguraQuotaError, a partial
rollback_session KaguraPartialSessionRollbackError. plan_headroom (server v0.142.0+) lists
each plan cap at 80 % or more of its limit on bootstrap and remember_batch (typed as
PlanHeadroomNotice) and on the remember / update_memory dicts; below 80 % it is absent, and
a write shows it at most hourly.
Agent bootstrap — one-call session-start rehydration (v0.37.0, server v0.49.0+)
get_agent_bootstrap composes the primitives above (context guide + pinned +
trusted-only recall + upcoming time memories + agent state) into one envelope, so an
agent starts a session with a single round-trip. Components are fail-soft: a failing
component reports status="error" while the rest still return (top-level degraded
flag). Also available over REST (AgentsClient) for API-key-only callers such as
agent-bound member keys:
from kagura_memory import AgentsClient, KaguraClient

async with KaguraClient() as client:  # MCP surface
    # One-time provisioning (owner/admin): register the agent, bind its context
    agent = await client.register_agent("ci-agent", framework="claude-code")
    await client.bind_agent_context(agent.id, "ctx-uuid", is_default=True)

    bootstrap = await client.get_agent_bootstrap(
        "agent-uuid",                     # context_id omitted → default binding
        session_id="run-42",              # echoed in the correlation block
        query="current task",             # enables the trusted-only recall component
        include=["pinned", "recall", "state"],
        max_chars=40_000,                 # whole-envelope budget (server v0.82.0+; default 20,000)
    )
    # Server v0.82.0+ loads 20 pinned memories by default here (pinned_cap= raises it).
    pinned = bootstrap.components["pinned"]  # {"status": "ok", "memories": [...], ...}

async with AgentsClient.from_mcp_url() as agents:  # REST companion
    bootstrap = await agents.bootstrap("agent-uuid", include=["pinned"])
⚠️ Error handling changed in v0.29.0 (breaking). Every
KaguraClientMCP tool method now raises on a server domain error instead of returning an error dict: a missing context/memory raisesKaguraNotFoundError, any other domain error raisesKaguraError. Replaceresult["status"] == "error"checks withtry/except:from kagura_memory import KaguraNotFoundError, KaguraError try: results = await client.recall(context_id="dev", query="auth") except KaguraNotFoundError: ... # context or memory not found except KaguraError: ... # other server-side error
A success response the SDK cannot parse — usually a server newer than this SDK — raises
KaguraResponseError from every KaguraClient method and the REST clients (a KaguraError
subclass; .operation names the MCP tool or <Client>.<method>, e.g.
KaguraClient.get_server_info, which check_server_version reports too) instead of a raw
pydantic ValidationError or KeyError. The message names the failing fields, not their
values. Upgrading kagura-memory is the likely fix. A network failure, a non-JSON 2xx body and
a non-2xx status other than 401, 429 and a 403 insufficient_scope raise KaguraConnectionError
instead (a 503 its subclass KaguraServiceUnavailableError).
Every error the server reported keeps what it sent: code is its error code (the MCP envelope's
error, e.g. payload_too_large or version_conflict, or the REST error, e.g. FEAT-001) and
details its other fields. Branch on code, never on the message. Since memory-cloud 0.78.0 an
MCP refusal carries help, the next step, and a server failure cause (timeout,
service_unavailable, internal_error), correlation_id, retryable and, for a write,
outcome: "unknown" with the read that shows whether it took effect; KaguraError exposes
these as the help, cause, correlation_id, retryable and outcome properties. A memory
over 1 MB is a plain KaguraError with code == "payload_too_large" and limit / actual in
details (memory-cloud 0.108.0+; REST keeps 429 QUOTA-001).
An OAuth token without the scope a call needs (HTTP 403 insufficient_scope, memory-cloud
0.79.0+) raises KaguraAuthError naming the scope: memory:read for the read-only tools,
recall and get_agent_bootstrap, memory:write for every other tool, so a
kagura auth login --read-only profile gets it on every write. An HTTP 503 raises
KaguraServiceUnavailableError, a KaguraConnectionError with retry_after (from
Retry-After) and reason (REST DB-002's details.reason, the MCP cause, or
temporarily_unavailable when /mcp could not verify the credential).
Plan, quota and capacity refusals raise typed errors, from the KaguraClient MCP tool methods
and the REST clients alike. All four are KaguraError subclasses:
KaguraQuotaError— a quota or cap was reached:rememberpast the daily memory quota, a tool call past the daily MCP call cap,create_contextat the context cap, the resource-token or member-seat cap, or the daily REST quota. The REST clients other thanSecretClientalso raise it for any other 429, such as the per-minute rate limit.quota_type,limit,current,used_todayandresets_atcarry the server's numbers when it sends them.create_contextchecks the cap throughlist_contextsbefore it calls the server, so that refusal hasquota_type,currentandlimitbut norequired_plan.detailsholds every field the server sent, including those without an attribute, such as the embedding-spend cap'scap_usd.retry_afteris the number of seconds until the quota resets, taken fromRetry-Afteror derived fromresets_at. It isNonefor a count cap, because waiting does not free one. OnKaguraClient, an HTTP-level 429 still raisesKaguraRateLimitError. That includes the daily MCP quota when the server's rate-limit middleware refuses the request before the tool runs.KaguraFeatureNotAvailableError— the workspace cannot use the feature.gatesays why:"plan"means an upgrade lifts it (required_plan/required_plan_display), while"allowlist"and"deployment"have no upgrade path. Since memory-cloud 0.100.0 a plan that dropped below what the workspace holds raises it too:feature == "members"on every workspace route for a member without a seat,feature == "contexts"on a content write into a context without a writable slot. Resource ingest raises it when the plan's allowance is 0.KaguraCapacityLockedError— a Free workspace over its capacity is locked (memory-cloud 0.99.0+): search and saving are refused until it is cleaned up or re-subscribed, while listing, deleting, export andget_usagekeep working.cleanup_urlis the page to do it, andover_memories/over_bytes(withmemory_count,memory_limit,used_bytes,storage_limit_bytes) say how far over it is. It is neither a quota nor a plan gate.get_usage().capacity_lockreports the same figures while the lock holds.KaguraPartialRollbackError—rollback_sleep_runreversed only part of the run..summaryis theRollbackSummaryof what was reversed, with the failed steps inerrors. It isNonewhen the server's summary could not be read.
Against memory-cloud 0.75.0+ the SDK types a refusal by its gate descriptor
(#1644). Against older servers it
falls back to the error code and the legacy fields. A quota_exceeded refusal that names no
quota, such as the 1 MB memory-size guard, stays a plain KaguraError, because no plan lifts it
and waiting does not help. kagura commands print the reset time, the required plan, the
cleanup page, the 503 retry window and the server's help and correlation id under the error
message.
from kagura_memory import KaguraFeatureNotAvailableError, KaguraQuotaError
try:
    await client.remember(context_id="dev", summary="...", content="...")
except KaguraQuotaError as e:
    print(e.quota_type, e.resets_at, e.retry_after)
except KaguraFeatureNotAvailableError as e:
    print(e.feature, e.required_plan_display)
More operations — tag-vocabulary discovery (list_tags), merge_contexts, context lifecycle (create_context/update_context/delete_context), workspace get_usage, get_memory_stats, find_duplicates, get_embedding_status — are runnable in examples/client_advanced.py; the API Coverage table lists the full surface.
ResourceClient — External Data Ingestion
Push data from external systems into Kagura so AI can search it:
from kagura_memory import ResourceClient, ResourceEventRequest

async with ResourceClient.from_mcp_url(api_key="kagura_...", mcp_url="http://localhost:8080/mcp/w/...") as client:
    # One-call setup: create public context + set resource_id + create token.
    # The context is named after the resource unless you pass context_name.
    token = await client.setup_resource(resource_id="products")
    print(f"Save this token: {token.token}")  # Shown only once!

    event = ResourceEventRequest(
        op="upsert", doc_id="SKU-001", version=1,
        payload={"name": "Wireless Headphones", "price": 79.99},
    )
    await client.ingest_event("products", token.token, event)

    # Check ingestion stats
    stats = await client.get_resource_impact("products")
    print(f"Memories: {stats.memory_count}, Tokens: {stats.token_count}")
The server requires a context name: setup_resource (and kagura resource setup) uses
resource_id unless you pass context_name (--name). A resource id always matches the
context-name pattern, but it needs a name of its own when it is longer than the 100-character
name limit, or when the workspace already has a context of that name (the server refuses with
validation_error: "Context '' already exists in this workspace.").
summary is deprecated and no longer sent, because the server's setup_resource has none;
set it afterwards with KaguraClient.update_context or
kagura context update <context_id> --summary ... (context owner only).
A resource_id is unique on the server, not just in the workspace: a slug another workspace's
context uses is refused too (resource_id_conflict; memory-cloud 0.129.0 says so in the message,
#2284). Token management is
workspace-scoped from memory-cloud 0.94.0
(#1863): list_tokens lists every token
of the workspace, whoever minted it, update_token / revoke_token reach any of them (also after
the resource's contexts were deleted). From 0.97.0
(#1919) the active-token cap counts the
workspace's tokens, not the caller's, and another workspace's token raises KaguraNotFoundError
(older servers answered some of those 403, raised as KaguraConnectionError).
Creating a resource, a resource token or a public context is plan-gated (plan_required).
Since memory-cloud 0.68.0 (#1551) the
gate is the plan's resources / public_contexts feature (XL only by default); earlier servers
gated it on the plan's shared contexts and token cap. Resources, tokens and public contexts that
already exist keep serving.
See examples/ for complete working examples.
FilesClient — File Uploads with Checksum Binding
Upload files to the workspace's object store via short-lived presigned PUT URLs. The SDK binds the body's sha256 into the PUT signature so the server (memory-cloud v0.15.1+, R2_CHECKSUM_BINDING_ENABLED=true) can reject tampered uploads with 400 BadDigest:
from pathlib import Path
from kagura_memory import FilesClient

async with FilesClient.from_mcp_url(api_key="kagura_...", mcp_url="https://memory.kagura-ai.com/mcp") as client:
    # Upload from a Path (read fully into memory; server caps file size at 100 MiB)
    f = await client.upload(context_id="ctx-uuid", source=Path("./report.pdf"))
    print(f"Uploaded {f.id}, sha256={f.sha256}, size={f.size_bytes}")

    # Upload from bytes — filename is required (server enforces non-empty)
    f2 = await client.upload(context_id="ctx-uuid", source=b"...", filename="payload.bin")

    # Optionally bind a file to an owning context for access control (server
    # v0.41.0+). binding_context_id is the wire `context_id` — distinct from the
    # `context_id` arg, which is the workspace. Omit it for a workspace-scoped
    # (NULL-context) file. FileObject.context_id reflects the binding (or None).
    f3 = await client.upload(
        context_id="ctx-uuid",
        source=Path("./plan.pdf"),
        binding_context_id="owning-ctx-uuid",
    )
    print(f3.context_id)  # -> "owning-ctx-uuid"

    # Short-lived presigned GET URL. download_url / delete require the owning
    # context_id (workspace) — server v0.41.0 scopes file-id lookups to it.
    url = await client.download_url(f.id, context_id="ctx-uuid")

    # List & delete
    page = await client.list(context_id="ctx-uuid", limit=50)
    await client.delete(f.id, context_id="ctx-uuid")
Re-uploading bytes whose sha256 already exists in the workspace returns the existing FileObject (idempotent dedup happy-path) — no exception. memory-cloud 0.80.0+ (#1693) sends that file in its 409 RES-002 only when it is in the same context as the upload (both unbound counts as the same) and its upload has completed; a duplicate bound to another context, or one whose earlier upload never finished, raises the 409 as KaguraConnectionError (.code == "RES-002").
From memory-cloud 0.126.0 a workspace-scoped API key keeps its own workspace on every file route: a context_id naming another workspace answers 403 instead of overriding it. KaguraClient.delete_context soft-deletes the context's files with it, and merge_contexts(delete_source=True) moves them to the target (0.101.0+, #1960). The server's DELETE /api/v1/contexts/{id}/files, which clears a context's files without deleting it, takes a browser session only, so the SDK does not wrap it.
A file bound via binding_context_id routes read/write/list/delete through that context's ACL (server v0.41.0+): you need write (EDITOR+) access to the context, and it must belong to the upload's workspace (else 403 / 422). A denied download surfaces as a 404 (existence-hiding), not a 403. Unbound uploads stay workspace-scoped and fully listable.
Runnable: examples/files_upload.py.
SecretClient — Zero-Knowledge Secrets
Client side of the secret store (memory-cloud v0.39.0+, requires the [secret] extra: pip install 'kagura-memory[secret]'). Secrets are encrypted to recipients' age/X25519 public keys and decrypted locally — memory-cloud only ever stores armored ciphertext, never plaintext. All crypto is delegated to the audited pyrage binding; the age private key is held in your OS keychain (keyring) and never transmitted.
from kagura_memory.secrets.client import SecretClient

async with SecretClient.from_mcp_url(api_key="kagura_...", mcp_url="https://memory.kagura-ai.com/mcp") as client:
    # Register your public key (lands in `pending` until an owner approves it).
    me = await client.register_pubkey("age1...", label="laptop")

    # Encrypt-and-store in one call. recipients_snapshot / grant_pubkey_ids are
    # derived 1:1 from the recipient set, so the server's grant-consistency
    # invariant holds by construction.
    actives = [p for p in await client.list_pubkeys() if p.status == "active"]
    await client.put_secret_for_recipients("db-prod", b"hunter2", actives)

    # Fetch ciphertext (decrypt locally with your own key — not shown here).
    sv = await client.fetch_secret("db-prod")
Most workflows use the CLI instead — see kagura secret below, which handles keychain custody and the get/put/grant/rotate flows with built-in misuse guards.
WorkspaceClient — Workspace Member Management
Owner-key operational tooling for workspace members and invitations (memory-cloud v0.42.0+). Every endpoint requires the workspace owner's static API key when called programmatically — OAuth tokens are rejected by the server with an actionable 403, and the assignable roles are member / admin / viewer (owner changes go through the ownership transfer flow):
from kagura_memory import WorkspaceClient

async with WorkspaceClient.from_mcp_url(api_key="kagura_...") as client:
    members = await client.list_members("workspace-uuid")
    for m in members:
        print(m.user_id, m.role, m.user_email)

    # Invite a new user by email. member/viewer invitations REQUIRE a
    # context grant (allowed_context_ids, min 1); expires_in_days accepts
    # only the server presets 7/30/90/365 (None = never expires).
    inv = await client.create_invitation(
        "workspace-uuid",
        "new@example.com",
        role="member",
        allowed_context_ids=["context-uuid"],
        expires_in_days=30,
    )
    print(inv.invitation_url)  # shown once — a join credential

    # Role changes / removal
    await client.update_member_role("workspace-uuid", "google_123", role="admin")
    await client.remove_member("workspace-uuid", "google_123")
Notes: add_member does not validate the user id server-side (a typo creates a dangling row — prefer create_invitation for onboarding); invitation ids are integers with no status field (derive pending from is_accepted/is_expired); listing invitations programmatically returns token/invitation_url as None (server-side token hygiene).
Context access (memory-cloud 0.126.0+). An owner or admin reaches every shared context of the workspace. A member or viewer reaches exactly the contexts its allowed_context_ids list names. With no list, a viewer reaches every shared context and a member none, writes included. A private context stays its creator's (or a linked account's), whatever the role or the list. A context outside the list answers not-found (REST 404, MCP context_not_found, both KaguraNotFoundError) where some paths answered 403. A workspace viewer is read-only everywhere, including a private context it created. A role change keeps the list, except that a member with no list who becomes a viewer gets an empty one, so update_member_role never widens reach. On memory-cloud 0.144.0+, an owner key can set allowed_context_ids in add_member, inspect the member's assignable contexts with get_member_context_access, and replace the list with set_member_context_access. Pass [] for no contexts or None to restore role defaults.
Use kagura workspace member add USER --role member --context UUID (repeat --context) or --no-contexts. The existing add success line is unchanged. get-context-access USER prints JSON with user_id, role, allowed_context_ids and contexts. set-context-access USER requires a list, --no-contexts or --role-default and prints status, user_id and allowed_context_ids. Both preserve JSON null versus []. OAuth is refused, the deployment switch enable_owner_key_member_management must be enabled, and a key confined to another workspace gets 404.
Adding a member to a shared context requires a signed-in web session. Use WorkspaceClient.from_web_session(base_url=..., session_cookie=...) or kagura context add-member CONTEXT USER --server URL --role editor (hidden cookie prompt or KAGURA_SESSION_COOKIE). On server 0.144.0+, a workspace owner/admin may pass --extend-access-list to extend the list in the same transaction. Otherwise a missing grant returns 409 RES-002, exposed as KaguraContextAccessListError with details["reason"] == "context_not_in_access_list". Success prints the context member as JSON, including access_list_extended.
Operation history (memory-cloud 0.154.0+). list_operation_history reads one page of the workspace's operation history: who changed which memory, context, member, credential, integration or Sleep run, when, through which surface (web, API, MCP, system) and with which credential or client. It takes a signed-in web session only — an API-key or OAuth client raises ValueError before any request — and the caller must be an owner or admin of the workspace, on a Pro or Max plan (or any plan whose features include operation_history; otherwise KaguraFeatureNotAvailableError with feature == "operation_history"). Read the cookie from a variable you provide, and print neither it nor the history:
import os
from datetime import UTC, datetime, timedelta

async with WorkspaceClient.from_web_session(
    base_url="https://memory.kagura-ai.com",
    session_cookie=os.environ["KAGURA_SESSION_COOKIE"],
) as client:
    cursor = None
    while True:
        page = await client.list_operation_history(
            "workspace-uuid",
            target_type="memory",
            outcome="success",
            since=datetime.now(UTC) - timedelta(days=7),  # timezone-aware only
            limit=100,
            cursor=cursor,                                # opaque, sent back as is
        )
        ...                                               # page.items: OperationHistoryItem
        if not page.next_cursor:                          # None (or a drifted "") ends it
            break
        cursor = page.next_cursor
    print(page.total, page.total_capped, page.retention_days)
Filters are keyword-only and combine: query (≤ 120 characters), context_id, actor (≤ 255), agent_id, operation (≤ 40, e.g. memory.updated; the server refuses one outside its set), target_type, outcome, since / until (sent as the same instant in UTC) and limit (1-100, default 30). Only unset (None) filters are left out: a blank query / actor reaches the server as no filter, a blank operation is refused there (422), and a blank cursor is refused locally (ValueError). total stops at 1,000 (total_capped), while paging reaches every match. Recording starts when the server runs the feature or the workspace moves to an entitled plan — no backfill, and Free and Starter record nothing — and events are kept for retention_days (90 days plus the workspace's add-on). Only ids, times, operation names, counts and changed-field names are stored, never contents or values. A private context's events are shown to its creator only, a shared credential's owner is not asserted to be the person who made the call, and the history is not an immutable audit ledger and has no export. See examples/operation_history.py.
On 0.144.0, invitation acceptance rechecks the workspace's team_invitations plan feature. A 403 FEAT-001 leaves the invitation pending. The signed-in user's pending invitation feed matches their email case-insensitively and excludes expired, accepted, and unaddressed link-only invitations. This feed is separate from the owner's workspace invitation list.
The same client also provisions member API keys (memory-cloud #1165): mint_member_key(ws, user_id, name, expires_days) (member/viewer targets only, never yourself — leaked-owner-key self-replication is blocked server-side; plaintext_key is returned exactly once), list_member_keys (metadata only), and revoke_member_key (soft revoke). CLI: kagura auth create-key|list-keys|revoke-key.
SDK ↔ memory-cloud Compatibility
MIN_SERVER_VERSION is 0.17.1 and advisory: the SDK never blocks a call on the server version. SDK 0.46.0 is checked against memory-cloud up to 0.155.0, and a surface newer than the floor carries its own, given in the compatibility page section of the release that added it.
| SDK | memory-cloud checked up to | What changed |
|---|---|---|
| 0.46.0 | 0.155.0 | Session-only workspace operation history reader, order_by="event_start", the plugin server_url keeps context=, RollbackSummary.related_indexes_reverted |
| 0.45.1 | 0.144.0 | Security dependency floors and refreshed lock; Click 8.5 compatibility. |
| 0.45.0 | 0.144.0 | Workspace member context access, signed-in context member add, and OAuth credential locking shared with TypeScript SDK 0.16.0. |
| 0.44.0 | 0.142.0 | Session tools (bootstrap, changes_since, list_matching, remember_batch), new remember / update_memory arguments, list paging, plan_headroom, auth refresh under the lock |
| 0.43.0 | 0.141.0 | Recall shape (verbosity, full, max_chars), MCP URL options, typed server errors, cursors and write caps |
Every release back to 0.13.x, with each surface's floor, how the SDK reads a server version, and the full notes: docs/compatibility.md.
CLI
Authentication (OAuth2 device flow)
Log in once with kagura auth login — the SDK stores credentials at
~/.kagura/credentials.json (mode 0600) and KaguraClient() plus all
kagura CLI commands pick them up automatically:
kagura auth login                                    # default: memory:read + memory:write
kagura auth login --read-only                        # read-only scope
kagura auth login --scope "memory:read profile:read" # custom scope set
kagura auth login --no-browser                       # SSH / headless
kagura auth login --profile work                     # named profile for a second workspace
kagura auth login --invite https://<host>/join/<token> # invite-only sign-up (link or bare token)

kagura auth status                                   # show profile, server, expiry, scope
kagura auth list                                     # list all stored profiles (default marked *)
kagura auth list --json                              # machine-readable profile list
kagura auth refresh                                  # manual token rotation
kagura auth refresh --scope "memory:write"           # incremental consent (re-runs device flow)
kagura auth token                                    # raw access_token to stdout (CI use)
kagura auth logout                                   # revoke + delete profile
kagura auth logout --all --yes                       # remove every profile
Invite-only servers. When a deployment admits new accounts only by
invite link (/join/<token>), pass that link — or its bare token — to
kagura auth login --invite. The token is checked locally against the
server's pattern before any network call, is never sent to the API, and is
never written to credentials.json or included in an error message. The CLI
builds the /join link on the web app's host (taken from the device flow's
verification_uri, not from --server, since the API can live on another
origin) and refuses a full link for a different server. It then reads the
public /api/v1/system/info: when features.beta_invites is not true
(invites turned off, or a server older than v0.70.0) it says invites have no
effect and shows the normal prompt. On memory-cloud v0.76.0 and later it
prints one link, /join/<token>?return_to=…, that signs you up and lands on
the approval page with the code filled in, followed by the plain approval URL
in case you end up on the dashboard. On an older server, or when that probe
fails, it prints two steps in order — open the invite link and sign up, then
open the approval URL. Either way the browser opens only the invite link
(--no-browser just prints).
Sign-in rate limit. memory-cloud v0.76.0 and later limit device sign-in
requests per client address. When the server refuses one with HTTP 429,
kagura auth login says so and how many seconds to wait (from the
Retry-After header, 60 when it is missing).
Token lifecycle on the server. From memory-cloud v0.79.0 a refresh token
yields one token, also under concurrent requests
(#1686). KaguraClient,
the REST clients and kagura-mcp refresh under one cross-process lock on
credentials.json and re-read it first, so they never send the same refresh
token twice. kagura auth refresh and kagura auth token refresh under the
same lock and keep a token another of them rotated meanwhile; up to 0.43.0 they
refreshed outside it, so one of them run while a proxy refreshed the same
profile could fail with "login expired". A password reset revokes every OAuth
token and device code of the account (v0.83.0+,
#1738), and only
kagura auth login recovers. From v0.83.0 the account's verified address is
emailed on every device-flow approval and for every API key minted for it,
including keys an owner mints with kagura auth create-key
(#1752).
kagura auth logout revokes the profile's refresh token, which on memory-cloud
v0.82.0+ also revokes the access token issued with it
(#1741; that release also
needs the client_id it sends), and deletes the profile. A profile without a
refresh token has its access token revoked. SDKs up to 0.42.2 revoked only the
access token, which left the refresh token valid on the server.
Two integration paths:
| You want… | Use |
|---|---|
CLI / KaguraClient (terminal use, scripts) |
kagura auth login — refresh happens automatically |
Claude Code MCP (Claude Code reads .mcp.json) |
kagura setup claude --profile <name> — OAuth via the refresh-aware kagura-mcp proxy (recommended) |
| Codex, Hermes Agent, OpenClaw | kagura setup codex|hermes|openclaw --profile <name> — the same proxy (below) |
| CI / service accounts | kagura setup claude with a long-lived API key from the web UI |
Claude Code's MCP client reads its config once at startup and never
refreshes tokens, so a short-lived OAuth access_token baked into
.mcp.json would 401 silently after it expires. kagura setup claude --profile <name> instead points .mcp.json at the kagura-mcp
stdio proxy, which owns ~/.kagura/credentials.json, forwards every
MCP request to the server, and injects an always-fresh bearer token —
so the same kagura auth login credentials power both the CLI and
Claude Code. If the server rejects an expired MCP session (the MCP
Streamable HTTP 404), the proxy — like a long-lived KaguraClient —
re-runs the initialize handshake and retries the request once, so
Claude Code keeps working without a restart. Use the long-lived API-key
path only for CI / service accounts, where a static token is preferable.
Credential resolution order when KaguraClient() is called with no
arguments: KAGURA_API_KEY env (CI / service accounts always win) →
KAGURA_PROFILE env or explicit profile= arg → default_profile
from ~/.kagura/credentials.json → legacy .kagura.json.
Diagnostics (kagura doctor)
Run kagura doctor when a local setup is not behaving as expected:
kagura doctor                  # human-readable pass/warn/fail report
kagura doctor --profile work   # inspect a named OAuth profile
kagura doctor --json           # machine-readable output for CI/scripts
The report covers effective auth source, OAuth/static API-key health,
the Claude Code kagura-memory MCP entry in effect (from local, project
.mcp.json or user scope, plus any entry it shadows), kagura-mcp PATH wiring, MCP URL HTTPS,
server reachability/version, the tools/list view of the CLI's MCP URL (tool count, and the
profile and add_tools it lists: core (default) without ?profile= on memory-cloud 0.93.0+;
a kagura-mcp entry's own --tool-profile/--add-tools are not applied), optional ingestion extras, LiteLLM supply-chain
status, and local LLM provider key/model diagnostics. Provider diagnostics are
local-only: GEMINI_API_KEY, ANTHROPIC_API_KEY, OPENAI_API_KEY, and
OLLAMA_API_KEY are reported with redacted previews, and model/key mismatches
are warnings only. doctor exits non-zero only on fail checks; warnings do
not fail CI.
Other commands
# Direct memory operations
kagura remember -s "FastAPI DI" --content "Use Depends()..." -c dev
kagura remember -s "Coffee with Sato" --content "..." --location "35.68,139.76,Tokyo HQ"
kagura remember -s "Release 2.0 shipped" --content "..." --observed-at 2026-11-01   # when it held (v0.127.0+)
kagura remember -s "Deploy key rotated" --content "..." --dedupe check --tags-normalize  # v0.93.0+
kagura recall "dependency injection" -k 10
kagura recall "dependency injection" --no-rerank   # skip reranking; no flag follows the context config (v0.69.0+)
kagura recall "project context" --trusted-only     # exclude connector-ingested memories (filters.trust_tier, v0.24.0+)
kagura recall "project context" --verbosity full   # uncut summaries + tags; compact is the server default (v0.108.0+)
kagura recall "deploy runbook" --full 1 --max-chars 40000   # content on the top hit only (v0.114.0+); reply budget (v0.82.0+)
# A server that refuses one of --verbosity/--full/--max-chars (invalid_argument) gets one
# retry without the ones it names (all three sent when it names none), with a note on stderr.
kagura explore -m "memory-uuid" --depth 3
kagura forget -m "memory-uuid"
kagura forget --ids "uuid-1,uuid-2"                  # up to 50, one row per id (server v0.117.0+); not with -k
# When every id fails (batch_failed), each row goes to stderr as "<id> <status> [<error>]": resend the not_attempted ones.
kagura bootstrap --since 7d --format index --max-chars 5000   # session start (v0.93.0+; index v0.115.0+)
kagura changes 2026-11-01T00:00:00Z --kinds created,forgotten  # change log, oldest first (v0.93.0+)
kagura changes 2026-11-04T09:00:00Z --by-me --limit 20   # own writes (v0.114.0+); --session-id ID (v0.113.0+); --cursor pages on
kagura list --filters '{"type": "task", "details.status": "open"}'   # exact filters + total (v0.93.0+)
kagura list --order-by observed_at --direction asc --details   # observed_at order needs v0.127.0+; page with --cursor
kagura list --order-by event_start --direction asc   # event date order (v0.152.0+); no event date sorts last
kagura update-memory -m "memory-uuid" --dismiss-supersede-candidate   # server v0.65.0+
kagura update-memory -m "memory-uuid" --accept-supersede-candidate    # server v0.126.0+
kagura update-memory -m "memory-uuid" --observed-at 2026-11-01        # when it held (server v0.127.0+)
# --details replaces details wholesale; --merge-details sends a details_patch and keeps the other keys
# (server v0.140.0+; older servers get a reference() round-trip instead)
kagura update-memory -m "memory-uuid" --details '{"location": {"lat": 35.68, "lon": 139.76}, "client": "acme"}'
kagura update-memory -m "memory-uuid" --location "35.68,139.76,Tokyo HQ" --merge-details
kagura update-memory -m "memory-uuid" --add-tag status:done --remove-tag status:open \
  --details-patch '{"status": "done", "assignee": null}' --expected-version 3   # v0.140.0+ / v0.113.0+
kagura context search-config <context-id> --content-chunks --no-llm-selector   # owner/admin only (v0.110.0+ / v0.115.0+)
kagura contexts                                     # one page; on v0.82.0+ a stderr line names the next --cursor
kagura context list --name-contains auth --summary   # server v0.73.0+; --details, --stats
kagura context list --limit 50 --cursor 50          # server v0.82.0+; a cut page names next_cursor on stderr

# Resource tokens
kagura resource setup -r products                   # context named after the resource; --name to override
kagura resource tokens create -r products -d "Product sync"
kagura resource ingest -r products -k TOKEN --doc-id SKU-001 -V 1 -p '{"name":"Widget"}'
kagura resource ingest-batch -r products -k TOKEN -f events.json
kagura resource stats -r products
kagura resource schema -r products

# Sleep Maintenance — observability + rollback
kagura sleep history <context-id> --limit 5 --source all  # sleep (default) | analysis | all (server 0.138.0+)
kagura sleep report <context-id> <report-id> [--actions-limit 100] [--actions-cursor C]  # <context-id> is kept for compatibility and ignored:
kagura sleep rollback <context-id> <report-id> -y    # the server finds the run by <report-id> (destructive: prompts unless --yes / -y)

# Tool guardrails (server v0.74.0+); context-id defaults to .kagura.json
kagura guardrails load <context-id> --cap 200         # pinned + tool-triggered lanes as JSON
kagura guardrails digest <context-id>                 # print the AGENTS.md export block
kagura guardrails digest <context-id> --out AGENTS.md # splice it in; unchanged set → no write, empty set → block removed
                                                      # (keep it out of commits: untracked file or --skip-worktree)
kagura guardrails digest <context-id> --target instructions --profile core  # preview the MCP instructions for ?profile=core
kagura guardrails digest <context-id> --target instructions --add-tools explore  # …for ?add_tools=explore (server v0.129.0+)

# Measurement lane — numeric series kept apart from memories (server v0.54.0+)
kagura measure record <context-id> weight_kg 71.5 --unit kg --at 2026-09-01T07:30:00Z   # --at defaults to now
kagura measure series <context-id> weight_kg --period week --agg avg   # default: day/avg over the last 30 days

# File uploads (R2 checksum binding)
kagura files upload ./report.pdf -c <context-id>
kagura files upload ./plan.pdf -c <context-id> --binding-context-id <ctx>   # bind to an owning context for ACL (v0.41.0+)
kagura files list -c <context-id> --limit 50
kagura files download-url <file-id> -c <context-id>   # -c required (server v0.41.0)
kagura files delete <file-id> -c <context-id>         # -c required (server v0.41.0)

# Workspace member management — owner API key ONLY (server v0.42.0+; OAuth tokens are rejected)
kagura workspace member list [--json]
kagura workspace member add <user-id> --role member|admin|viewer   # user must already exist — prefer invite
kagura workspace member set-role <user-id> --role member|admin|viewer
kagura workspace member remove <user-id> --yes
kagura workspace invite create <email> --role member -c <context-id> --expires-days 30
kagura workspace invite list [--include-accepted]
kagura workspace invite revoke <invitation-id>

# Owner-provisioned member API keys — owner API key ONLY (server v0.42.0+)
kagura auth create-key --user <member-id> --name ci-bot --expires-days 90   # key printed ONCE; member/viewer targets only, never yourself
kagura auth list-keys --user <member-id>            # metadata only — plaintext is never re-shown
kagura auth revoke-key <key-id> --user <member-id>  # soft revoke (row kept for audit)

# Config
kagura config show
Zero-knowledge secrets (kagura secret)
Requires the [secret] extra (pip install 'kagura-memory[secret]') and memory-cloud 0.39.0+. Your age private key lives in the OS keychain; memory-cloud only ever stores armored ciphertext.
kagura secret keygen --label laptop          # generate keypair → keychain, register public key (pending)
kagura secret approve <pubkey-id>            # owner: approve a pending key (verify its fingerprint out-of-band)
kagura secret put db-prod < secret.txt       # value from stdin/--from-file — never from argv
kagura secret get db-prod | psql             # refuses to print to a TTY; pipe it, or use -o FILE (0600) / --reveal
kagura secret exec --as DATABASE_URL=db-prod -- ./server   # inject into a child env, no disk/scrollback
kagura secret grant db-prod --to <pubkey-id> # re-encrypt to the expanded recipient set
kagura secret revoke db-prod --to <pubkey-id># revoke a grant (then `rotate` — revoke ≠ invalidation)
kagura secret rotate db-prod                 # encrypt a NEW value to the remaining recipients
kagura secret list                           # secret metadata (never the values)
kagura secret delete db-prod                 # owner-only hard delete (cleanup, not invalidation — rotate first)
kagura secret audit-verify                   # verify the tamper-evident audit chain
deleteis cleanup, not a security control. It removes the stored ciphertext (all versions + grants) but does not un-share a value a recipient already fetched, nor rotate the live upstream credential. To contain a leak, rotate the upstream credential first, then delete. Owner-only; needs memory-cloud 0.41.0+.
Document ingestion (kagura ingest)
See the 60-second demo above for the happy path. The full option surface:
# Local file or URL → one overview + N sections + R2 archive
kagura ingest ./report.pdf
kagura ingest https://example.com/report.pdf --tags "Q1,research"

# Preview cost / sections without calling any LLM
kagura ingest ./report.pdf --dry-run

# Skip vision-provider configuration entirely (images are not OCR'd yet, so
# this just avoids validating a vision provider you don't need)
kagura ingest ./report.pdf --no-vision

# Storage: skip the R2 archive (no file_id stamped on the overview memory)
kagura ingest ./report.pdf --no-archive

# Machine-readable output for scripts
kagura ingest ./report.pdf --json
Exit codes: 0 when the overview memory is created (per-section errors are still 0, they show up in result.errors); 1 when the overview itself fails (corrupted PDF, network error, etc.); 0 for any --dry-run invocation.
For the SDK-level FileIngestor API, see examples/ingest_pdf.py.
Provider configuration (env vars, picked up automatically via litellm):
ANTHROPIC_API_KEY— text summarization (default modelclaude-sonnet-4-6via theclaudepreset)GEMINI_API_KEY— audio/video transcription (default modelgemini/gemini-2.5-flashvia thegeminipreset); also the default vision provider for image OCR, which is configured but not yet invoked (see above)- Override per invocation:
--text-provider {claude|gemini|ollama},--vision-provider {claude|gemini|ollama}
Claude Code Integration
Wire Kagura Memory into Claude Code as an MCP server. Recommended: OAuth via
the refresh-aware kagura-mcp proxy — log in once, then setup claude writes
the stdio .mcp.json form and tokens refresh automatically:
kagura auth login --profile default        # one-time OAuth device flow
kagura setup claude --profile default      # writes .mcp.json → kagura-mcp stdio proxy
This writes a .mcp.json that launches kagura-mcp as the MCP server (no secret
in the file), plus .claude/ hooks and /kagura-recall · /kagura-remember
skills. Check the active mode any time with kagura auth status (it reports
refresh-aware vs legacy static API-key token for the entry Claude Code uses
in the current directory, and which scope it comes from).
CI / service accounts — use a long-lived API key instead (static token, no refresh needed):
kagura setup claude --api-key kagura_xxx --mcp-url https://memory.kagura-ai.com/mcp
One entry for every project — the stdio entry holds nothing project-specific (a local command and a profile name), so when one profile serves all your projects, put it at Claude Code's user scope:
kagura setup claude --profile default --scope user # via `claude mcp add-json --scope user`
With an API key instead of --profile, the user-scope entry does not hold the
key: it sends Authorization: Bearer ${KAGURA_MCP_API_KEY}, which Claude Code
fills in from its own environment when it connects. The key is never on the
claude mcp add-json command line, where any local user could read it in the
process list, and never in ~/.claude.json. Set the variable in the environment
that starts Claude Code, e.g. export KAGURA_MCP_API_KEY=kagura_xxx in your shell
profile. Setup says whether the current shell has it, and kagura doctor warns
when it is unset. It is a separate variable from KAGURA_API_KEY, which the SDK
ranks above .kagura.json and OAuth profiles for every kagura command. (The
--profile entry needs no key at all. --scope project still writes the key into
.mcp.json, so keep that file out of version control.)
--scope project (the default) writes <project>/.mcp.json: that is the scope
Claude Code shares through version control, and it asks you to approve a new
project server before first use. --scope user writes through the claude
CLI, since Claude Code owns ~/.claude.json; without claude on PATH, setup
prints the command and stops. A different user-scope kagura-memory entry is
replaced: an interactive run asks first, -y replaces it (and says so). Each run
still writes the project's .kagura.json and hooks. Claude Code uses the
kagura-memory entry from the strongest scope — local > project > user — and
ignores the rest (local scope belongs to the git repository root, whichever
subdirectory you start in; project scope is the closest .mcp.json defining it,
in that directory or any parent), so setup checks every scope first: it warns (and
with -y exits 1 without writing) when a stronger entry would hide the new one,
and notes any weaker entry the new one hides. kagura doctor reports the same.
Upstream URL query — --guardrails off|<context-uuid> (server v0.74.0+),
--tool-profile <name> (server v0.73.0+), --add-tools <name>[,<name>…] (server
v0.129.0+) and --context <context-uuid> (server v0.114.0+) put memory-cloud's
?guardrails= / ?profile= / ?add_tools= / ?context= on the upstream MCP URL:
as kagura-mcp --guardrails … --tool-profile … --add-tools … --context … arguments
for --profile (the proxy adds them to the profile's URL at run time, replacing
any earlier value), or in the url's query for an API key. Nothing is copied into
--server or ~/.kagura/credentials.json, and changing them never forces a
re-login. The entry is rebuilt from the flags on every run, so pass them again
when you re-run setup (it notes any it dropped). --guardrails off also removes
the guardrails block from get_context_info: use it only when hooks deliver
guardrails (see below).
What tools/list shows: since memory-cloud 0.93.0 a bare /mcp URL lists the
core profile, the memory loop (21 tools on 0.141.0), and --tool-profile full
lists every tool (72). The server knows only full and core (case-sensitive) and
fails tools/list for any other name, which leaves Claude Code with no Kagura
tools. Setup leaves that list to the server and refuses only a blank name or one
starting with - (exit 2), which the stored kagura-mcp arguments would read as a
flag. --add-tools lists more tools on top of the profile, e.g. --add-tools explore: recall's explore_hints need explore listed (memory-cloud 0.135.0
moved it out of core), so add it or use full. Unknown names are ignored, and a
?tools= allowlist already on the URL wins over both flags (setup warns). A profile
is a view, not an authorization boundary: tools/call reaches an unlisted tool too,
and describe_tools names what the view leaves out. --context makes that context
the default for tools called without context_id, so a session can skip
list_contexts; an explicit context_id wins, and the default is checked like one.
It is a UUID, unlike --context-id, which picks the project's hooks and commands.
Older servers ignore the parameters they do not know.
kagura-mcp --session-id NAME (or KAGURA_MCP_SESSION_ID; server v0.114.0+) sends
Kagura-Session-Id: NAME on every upstream request, so the server records the
writes under that session (changes_since(session_id=…)). An invalid flag value
stops the proxy; an invalid variable is ignored with a warning. Claude Code speaks stdio
to the proxy, so there is no request header to pass on; a tool call's
params._meta["ai.kagura/sessionId"] still passes through and wins for that call.
kagura doctor reports how many tools tools/list returns on the CLI's MCP URL
and which profile it lists (its tools section).
Hooks and commands — the SessionStart hook recalls project context with
kagura recall "project context and recent decisions" -c <context> -k 5 --trusted-only --verbosity full --full 0 2>/dev/null | head -c 5000 || true (--trusted-only needs
server v0.24.0+), so connector-ingested memories never reach the session unreviewed,
and on memory-cloud 0.114.0+ the five hits arrive as uncut summaries with their tags
and without content: since 0.108.0 recall is compact unless asked, and since 0.114.0
it puts content on the top hits. From 0.82.0 a server refuses an argument it does
not declare and names it, and kagura recall retries once without the ones named,
so the same hook gets uncut summaries with tags on every server: 0.108.0–0.113.x
keep --verbosity full and drop --full, 0.82.0–0.107.x drop both (the full shape
is their only one), older servers ignore both, and no server before 0.114.0 sends
content. Re-running setup replaces an earlier SDK-written hook in
place. --no-session-hook, --no-sync-hook (the
.claude/memory sync) and --no-commands (/kagura-recall · /kagura-remember)
skip them; re-running with one removes only what setup itself wrote. When the
memory-cloud kagura-memory plugin is installed (claude plugin list), an
interactive run offers to skip /kagura-recall and /kagura-remember, which
duplicate its /kagura-memory:recall and :remember (default: skip), and asks
separately about the SessionStart hook (default: keep — the plugin recalls
nothing automatically: its SessionStart hook only announces active guardrails, and
/kagura-memory:session-start is a command you run). -y keeps both and names
--no-commands. Setup never sets --guardrails off for you: once the plugin's
guardrail hooks are configured (/kagura-memory:setup), re-run with
--guardrails off. Setup prints the plugin's server_url and context_id
values (never an API key); the plugin's context_id is one guardrail context for
every project, and its hooks need a user API key even when setup uses --profile.
server_url is the MCP URL as the plugin's own setup derives it: the query is
dropped except guardrails=off and a context= (from --context or the
--mcp-url query) naming the
context being configured, which the plugin's SessionStart hook announces as the
default context (the plugin shipped with memory-cloud 0.149.0).
Or use the CLI directly:
kagura remember -s "FastAPIのDIパターン" --content "DIはDepends()を使う" -c dev
Also running the memory-cloud kagura-memory Claude Code plugin (its guardrail hooks and
/kagura-memory:setup)? Both expect the MCP entry named kagura-memory, and the plugin's
hooks need their own API key — see the coexistence note in
skills/setup/SKILL.md.
Claude Code plugin (CLI-as-skills)
This repo also ships a thin Claude Code plugin under
.claude-plugin/ + skills/ that wraps
the high-value CLI commands as skills (doctor, auth, setup, memory, ingest,
resource, files, secret) — each shells out to the installed kagura CLI and returns
clear guidance when it is not installed/authenticated. The plugin is named
kagura-cli (distinct from the kagura-memory SDK package and the existing
kagura-memory MCP plugin). Registration in the kagura-plugins marketplace (so
it installs via /plugin install kagura-cli@kagura-plugins) is tracked as a
follow-up.
Codex, Hermes Agent and OpenClaw
OpenAI Codex, Hermes Agent and OpenClaw can each spawn a stdio MCP server, so
kagura setup points them at the same refresh-aware kagura-mcp proxy Claude
Code uses — log in once, and no API key goes anywhere. That entry stays the
default. memory-cloud's OAuth dynamic client registration accepts the three
harnesses' own clients on a loopback redirect only from 0.77.0
(memory-cloud#1657), and
rejects them before that. From 0.77.0 the opt-in --url-form --oauth form
(below) writes an entry with no key, which the harness then signs in to itself.
From memory-cloud 0.78.0
(memory-cloud#1671), Hermes can also sign in with
its device flow, which needs no loopback callback.
kagura auth login --profile default
kagura setup codex --profile default      # or: hermes, openclaw
kagura setup codex --profile default --dry-run   # show what it would do, change nothing
Each harness passes a filtered environment to the servers it starts, so the
entry names kagura-mcp by its absolute path (resolved when setup runs) and
always passes --profile; it never depends on PATH, KAGURA_PROFILE or the
default profile. Re-run setup after moving the SDK to another environment.
Setup changes a harness's config only through that harness's own CLI. Without
the CLI on PATH (or, for Hermes and for Codex with --oauth, without a
terminal or with -y), it prints the block and the file to add it to and edits
nothing. When Hermes's
config.yaml already has a top-level mcp_servers: key, it prints the entry
alone, indented to go under that key: a second mcp_servers: key would replace
the first, and every server under it. An entry of the same name
stops setup unless you pass --force; setup says what kind of entry it is
(stdio, URL with a bearer from an environment variable, URL with OAuth) and
never prints its values. Setup asks questions only with a terminal and without
-y; run from an agent's shell or CI, it behaves as with -y and never stops
at a prompt.
The connection check, the context lookup and the AGENTS.md export use the
--profile login alone, even when KAGURA_API_KEY is set, because that is the
only credential the entry's kagura-mcp uses (kagura setup claude does the
same).
| Codex | Hermes Agent | OpenClaw | |
|---|---|---|---|
| Config | ~/.codex/config.toml ($CODEX_HOME) |
~/.hermes/config.yaml ($HERMES_HOME, or the active Hermes profile's) |
~/.openclaw/openclaw.json ($OPENCLAW_STATE_DIR/openclaw.json, or OPENCLAW_CONFIG_PATH) |
| Written with | codex mcp add (--force: the same command, which replaces the entry) |
hermes mcp add, attached to your terminal: it probes the server and asks which tools to enable |
openclaw mcp add, which probes first (--force: openclaw mcp set) |
| Check it | codex mcp get kagura-memory |
hermes mcp test kagura-memory |
openclaw mcp doctor kagura-memory --probe |
| Guardrails | MCP instructions: --context-id (or --guardrails <uuid>) adds --guardrails to the proxy |
get_context_info (on by default), plus the opt-in AGENTS.md export |
same as Hermes |
Guardrails. Codex reads the server's MCP instructions, so with
--context-id <uuid> the entry runs kagura-mcp --guardrails <uuid> and Codex
receives that context's tool guardrail digest at every connect (server
v0.74.0+). Use a context whose editor list you control: every editor's guardrail
summaries reach the model. The server falls back to its base text, silently,
when the entry's credential cannot read the context, the context has no
guardrails, or the deployment turns the digest off; setup prints the
kagura guardrails digest <uuid> --target instructions command that previews
what Codex receives. Hermes and OpenClaw do not read instructions: they
see guardrails in the guardrails block of get_context_info, which
?guardrails=off would remove, so --guardrails off is refused for them (exit 2)
and a context id is never written into their entry: a ?guardrails=<uuid>
already in --mcp-url is dropped with a warning (a ?guardrails=off the server
would read is kept, alone and with a warning).
Tool view. --tool-profile <name> and --add-tools <name>[,<name>…] work as
for setup claude (above): on the stdio entry they
become kagura-mcp --tool-profile/--add-tools, and with --url-form they go on the
URL as ?profile= / ?add_tools=, where a value already in --mcp-url is kept
when the flag is absent. Without either, memory-cloud 0.93.0+ lists the core
tools; full lists every tool. For Codex, the --guardrails preview carries the entry's view, so its
truncation note names a tool the entry lists. With --url-form --oauth, Codex keys
its token on the URL, so changing them later means signing in again.
AGENTS.md export (opt-in; server v0.74.0+). --agents-md [PATH] writes a
snapshot of the context's tool guardrails — the same block as
kagura guardrails digest --out — into a file the harness loads every session:
for Hermes the context file it loads from the current directory, found as Hermes
finds it, so the user's own file keeps loading. Hermes loads only the first type
that has text: the nearest .hermes.md / HERMES.md from here up to the git root
(an empty one ends that search), then the AGENTS.override.md / AGENTS.md /
agents.md chain from the git root down, then CLAUDE.md / claude.md, then
Cursor rules. The block goes into the loaded .hermes.md / HERMES.md, else this
directory's loaded AGENTS file (a new AGENTS.md when the chain loads only from
parent directories), else the loaded CLAUDE.md, else a new AGENTS.md. When only
.cursorrules / .cursor/rules/*.mdc load, a new AGENTS.md would stop them
loading: setup makes no offer, and --agents-md needs a PATH. The Hermes gateway
and cron start from terminal.cwd instead of the current directory, so pass
--agents-md PATH for them. For OpenClaw
AGENTS.md in its default workspace, found as OpenClaw finds it:
$OPENCLAW_WORKSPACE_DIR, else workspace in $OPENCLAW_STATE_DIR, else
~/.openclaw/workspace (setup does not read an agents.defaults.workspace set in
openclaw.json: pass that path to --agents-md); for Codex $CODEX_HOME/AGENTS.md (~/.codex),
or AGENTS.override.md there when it exists, since Codex reads it instead —
rarely needed, as the digest already arrives in instructions. An interactive
Hermes or OpenClaw run offers it (default no) and lists the profile's contexts;
without a terminal or with -y, pass --context-id. Only the text between the
kagura-memory:guardrails markers changes. A context with no guardrails this
credential can see writes nothing, and removes an earlier block, as
guardrails digest --out does, so the harness stops loading guardrails the server
no longer serves. Setup prints the command that refreshes the block.
Codex and the kagura-memory plugin's hooks. memory-cloud's Codex plugin
reads the credential for its guardrail hooks only from a URL entry with a bearer
(bearer_token_env_var, env_http_headers or http_headers), so a stdio entry,
or an --oauth one, turns them into no-ops. When the hooks are turned on for the
entry being written (their config.json's mcp_server, kagura-memory by
default, equals --name), setup says so and suggests --url-form with an API
key; an interactive run asks before writing the stdio or --oauth entry.
URL form. With a long-lived API key, and no wish to run the proxy on the
harness host, --url-form --mcp-url https://memory.kagura-ai.com/mcp/w/<workspace-id>
writes a URL entry instead. The key never passes through setup: the entry
references an environment variable, and you put the key there yourself.
--profile is optional here: it only lists contexts and fetches the AGENTS.md
export, so it must be a login on the --mcp-url server (exit 2 otherwise).
Without it, the export uses the usual kagura credential chain, which must
point at that server too (KAGURA_MCP_URL for KAGURA_API_KEY).
| The entry sends | Where the key goes | |
|---|---|---|
| Codex | bearer_token_env_var = "KAGURA_API_KEY" (--api-key-env to rename; ?guardrails=off while the plugin's hooks are on) |
export KAGURA_API_KEY=… in the shell profile that starts Codex (the kagura CLI also ranks this variable above OAuth profiles) |
| Hermes | Authorization: Bearer ${MCP_KAGURA_MEMORY_API_KEY} (the name Hermes derives from the server name) |
hermes mcp add --auth header asks for it and stores it in Hermes's .env; when setup prints the block, add it there yourself |
| OpenClaw | Authorization: Bearer ${KAGURA_API_KEY}, always with transport: "streamable-http" (a URL entry defaults to SSE) |
~/.openclaw/.env ($OPENCLAW_STATE_DIR/.env); the entry is added with --no-probe, so run openclaw mcp doctor kagura-memory --probe once the key is there |
OAuth URL form (memory-cloud 0.77.0+). From 0.77.0 memory-cloud's dynamic
client registration accepts the three harnesses' own OAuth clients on a loopback
redirect (memory-cloud#1657), so
--url-form --oauth --mcp-url https://memory.kagura-ai.com/mcp/w/<workspace-id>
writes a URL entry with no key, no header and no key variable: the harness
registers its own client, signs in itself and keeps the token in its own store.
Setup never sees the token, and never offers this form on its own. Before it
detects, runs or writes anything, a real run sends one unauthenticated
GET /api/v1/system/info to the --mcp-url server and stops (exit 1) unless it
reports 0.77.0 or later; a version setup cannot read (no answer, not a 200,
unparseable) stops it too. --dry-run sends no request. --oauth needs
--url-form and --mcp-url and refuses --api-key-env (exit 2); --profile
keeps its URL-form meaning.
kagura setup codex --url-form --oauth --mcp-url https://memory.kagura-ai.com/mcp/w/<workspace-id>
| The entry | Written with | Sign in | The harness keeps the token in | |
|---|---|---|---|---|
| Codex | url only (Codex's auth defaults to OAuth) |
codex mcp add <name> --url <url>, which saves the entry and then starts Codex's browser sign-in, so setup runs it attached to your terminal, and only with a terminal and without -y; otherwise it prints the table and edits nothing (--force: the same add, which signs in again) |
codex mcp login <name> (--no-browser when the browser cannot reach the callback: it prints the URL and takes the callback URL pasted back) |
the OS keyring (Codex MCP Credentials; on Windows, Codex's encrypted secrets store in ~/.codex), else ~/.codex/.credentials.json ($CODEX_HOME), keyed on the entry's URL |
| Hermes Agent | url + auth: oauth |
hermes mcp add <name> --url <url> --auth oauth --connect-timeout 315, attached: its probe runs the browser sign-in, which the probe's default 30 s bound would cut short, so setup gives it the bound hermes mcp login uses. Hermes keeps it as the entry's connect_timeout (default 60 s), which also bounds later connects; hermes config set mcp_servers.<name>.connect_timeout 60 lowers it once signed in. An entry Hermes saves without auth: oauth (it offers to continue without authentication when it cannot set up OAuth) counts as not saved, and one it saves disabled (enabled: false, after the sign-in did not finish) stops setup with the command that turns it on |
hermes mcp login <name> (the browser flow, which also takes the redirect URL pasted at its prompt), or on memory-cloud 0.78.0+ hermes mcp login <name> --flow device (a code entered at the server's /device page; no loopback callback, memory-cloud#1671) |
~/.hermes/mcp-tokens/<name>.json ($HERMES_HOME, or the active Hermes profile's) |
| OpenClaw | url, transport: "streamable-http", auth: "oauth" |
openclaw mcp add <name> --url <url> --transport streamable-http --auth oauth, which saves an OAuth entry without probing (--force: openclaw mcp set) |
openclaw mcp login <name> (--code <code> when the browser cannot reach the callback), then openclaw mcp doctor <name> --probe |
its state database, ~/.openclaw/state/openclaw.sqlite ($OPENCLAW_STATE_DIR/state/) |
Each sign-in redirects the browser to the harness's loopback callback on the
harness host (the Sign in column names each harness's way round a browser that
cannot reach it), and memory-cloud's consent screen shows the client name the
harness sends, which nothing verifies. For Codex, --context-id or --guardrails
goes on the URL as ?guardrails=; Codex keys its token on the URL, so changing it
later means signing in again. With the plugin's hooks on, an --oauth entry does
not get ?guardrails=off (the hooks cannot read it), and setup prints the hooks
warning. The --guardrails preview runs on the kagura CLI's own credential:
what Codex receives depends on the account it signed in with. Without
--profile, it uses the CLI's usual credential only when that is on the
--mcp-url server; otherwise it names the stored profiles on that server and
runs on the first, or, when there is none, prints the kagura auth login --server to run first and the command on that login.
What has been checked: memory-cloud 0.77.0 accepts these harnesses' client
registration on a loopback redirect. On 2026-09-25 each harness signed in end to
end on a /mcp/w/<workspace-id> URL against memory-cloud 0.78.0, through entries
kagura setup … --url-form --oauth wrote, and reached tools/list: Codex
0.157.0, Hermes Agent v2026.9.24 (the browser sign-in and hermes mcp login --flow device) and OpenClaw 2026.9.6, on a WSL2 host with the browser on
Windows (#284).
memory-cloud's protected-resource metadata names only <FRONTEND_URL>/mcp, which
the three accept for a /mcp/w/<workspace-id> URL. OpenClaw asks for every
scope the server lists, memory:admin and memory:delete included.
stdio or OAuth? The stdio entry stays the default:
stdio kagura-mcp (default) |
--url-form --oauth |
|
|---|---|---|
| Sign-in | One kagura auth login (device flow, which works over SSH) serves every harness and the CLI |
One browser sign-in per harness, each registering its own DCR client. The browser is redirected to the loopback callback on the harness host; when it cannot reach it, use Codex mcp login --no-browser, paste the redirect URL at Hermes's prompt (hermes mcp login <name>), or use OpenClaw mcp login --code. On memory-cloud 0.78.0+, Hermes's mcp login <name> --flow device needs no callback at all (memory-cloud#1671) |
| Server | Any supported server (0.17.1+) | 0.77.0+ |
| Harness host | Needs kagura-memory installed. The entry holds the absolute path, so re-run setup after moving the SDK | Needs only the harness |
| Codex guardrails lane | kagura-mcp --guardrails <ctx>; changing it needs no new sign-in |
?guardrails=<ctx> on the URL. Codex keys the token on the URL, so changing it means running codex mcp login again |
| Codex plugin hooks | No-ops | No-ops (they need --url-form with an API key) |
| Token | ~/.kagura/credentials.json, refreshed by the proxy |
The harness's own store (table above) |
API Coverage
| Operation | SDK Client | Protocol | Auth |
|---|---|---|---|
| Memory (remember/recall/forget/explore/reference/update_memory) | KaguraClient |
MCP | API Key |
| Provenance / trust_tier recall filter | KaguraClient |
MCP | API Key |
| Deterministic delivery (load_pinned + delivery_mode pin-on-write) | KaguraClient |
MCP | API Key |
| Time Memory (recall_upcoming) | KaguraClient |
MCP | API Key |
WHERE axis (recall_nearby + details.location) |
KaguraClient |
MCP | API Key |
WHERE-axis list filter (list_memories lat_min/lat_max/lon_min/lon_max bbox + item location) |
KaguraClient |
REST | API Key |
| HOW-MUCH axis — measurement lane (record_measurement / recall_series) | KaguraClient |
MCP | API Key |
Tag vocabulary + faceted drill-down (list_tags, with_tags over GET /api/v1/contexts/{id}/tags) |
KaguraClient |
MCP + REST | API Key |
Supersede / memory history (remember supersedes=, recall include_superseded=, update_memory dismiss_supersede_candidate= / accept_supersede_candidate=, supersede_candidate.acceptance on reference and recall rows) |
KaguraClient |
MCP | API Key |
Partial edits and optimistic concurrency (update_memory add_tags / remove_tags / details_patch / expected_version → KaguraVersionConflictError, reference version= / content_offset=) |
KaguraClient |
MCP | API Key |
Event time (remember / update_memory observed_at=, recall observed_after / observed_before filters, list_memories item observed_at) |
KaguraClient |
MCP + REST | API Key |
Write options (remember dedupe= / tags_normalize= / verbose=) and plan headroom notices (plan_headroom) |
KaguraClient |
MCP | API Key |
| Retrieval feedback (feedback) | KaguraClient |
MCP | API Key |
Agent session-state lane (set_state/get_state, TTL; list mode paged with cursor / limit / max_chars) |
KaguraClient |
MCP | API Key |
| Agent bootstrap (get_agent_bootstrap — one-call session-start rehydration) | KaguraClient / AgentsClient |
MCP + REST | API Key |
| Session start + deterministic lanes (bootstrap, changes_since, list_matching) | KaguraClient |
MCP | API Key |
Batch writes and deletes (remember_batch, forget memory_ids=) |
KaguraClient |
MCP | API Key |
| Revision log and session rollback (list_revisions, rollback_session) | KaguraClient |
MCP | API Key |
| Tool discovery and manual (describe_tools, guide) | KaguraClient |
MCP | API Key |
| Agent registry + context bindings (register/list/update/delete, bind/unbind — owner/admin) | KaguraClient / AgentsClient |
MCP + REST | API Key |
Tool guardrails (load_guardrails, remember/update_memory tool_trigger=, get_context_info guardrails) |
KaguraClient / MemoryClient |
MCP + REST | API Key |
Guardrail digest (AGENTS.md export block / server-instructions preview) |
MemoryClient |
REST | API Key |
Context (create/update/list/delete/get_context_info; list_contexts paged with cursor / limit) |
KaguraClient |
MCP | API Key |
| Workspace (get_usage) | KaguraClient |
MCP | API Key |
| Workspace operation history (list_operation_history — owner/admin, Pro/Max) | WorkspaceClient |
REST API | Web session |
Search config (update_search_config, incl. content_chunks_enabled / llm_selector_enabled) |
KaguraClient |
MCP | API Key |
Server info (get_server_info — version, deployment feature flags, search_defaults, terms_version) |
KaguraClient |
REST | None (public endpoint) |
| Embedding status (get_embedding_status) | KaguraClient |
REST | API Key |
| Memory stats (get_memory_stats) | KaguraClient |
REST | API Key |
| Duplicate detection (find_duplicates) | KaguraClient |
REST | API Key |
| Sleep Maintenance (history / report / rollback) | KaguraClient |
MCP | API Key |
| Resource Token (create/list/update/revoke) | ResourceClient |
REST API | API Key |
| Resource Event ingestion | ResourceClient |
REST API | Resource Token |
| Resource Impact (stats) | ResourceClient |
REST API | API Key |
| Resource Schema | ResourceClient |
REST API | API Key |
| File upload (optional context binding) / download-url / delete / list | FilesClient |
REST + presigned PUT | API Key |
| Secret pubkey registry (register/list/me/approve/revoke) | SecretClient |
REST API | API Key / OAuth |
| Secret put / fetch / list / revoke-grant / delete / audit-verify | SecretClient |
REST API (age, local decrypt) | API Key / OAuth |
| Account erasure (GDPR Art.17 / APPI) | — | Web UI only | Session |
Context deletion is a soft delete available via KaguraClient.delete_context() and kagura context delete (the CLI prompts for confirmation). Account erasure (GDPR Art.17 / APPI) is intentionally Web UI only — it is irreversible and requires session authentication and confirmation. kagura sleep rollback runs over the MCP API Key but is itself destructive (reverses edge creation, merges, importance updates, promotions, and archives) and the CLI requires --yes to skip the interactive confirmation. The server commits per-action without a Saga, so a 5xx response after partial success means SOME actions may have been reversed before the error surfaced — re-run kagura sleep report to inspect the post-failure state.
Development
git clone https://github.com/kagura-ai/kagura-memory-python-sdk.git
cd kagura-memory-python-sdk
uv sync --dev
uv run ruff check src/ tests/   # Lint
uv run ruff format src/ tests/  # Format
uv run pyright src/              # Type check
uv run pytest tests/ -v          # Test
Development with Claude Code
This project is developed with Claude Code:
/quality                # Run lint, format, type check, tests
/simplify               # Review for reuse, quality, efficiency
/self-review            # Pre-PR self-review
/self-maint             # Audit .claude/ config against codebase
/test                   # Run the test suite
/release <level>        # Bump version, tag, push, create GitHub Release
/kagura-memory:guide    # SDK usage reference (kagura-memory plugin)
Typical flow: Issue → Branch → Implement → /quality → /simplify → /self-review → PR → Merge → /release
Links
- Kagura Memory Cloud — the server this SDK connects to
- Releases — changelogs
- Compatibility — the memory-cloud release each SDK release needs, per surface
- Issues — bug reports & feature requests
License
MIT License — see LICENSE for details.
1 maintainer

Metadata
1 maintainer
Release files for kagura-memory 0.46.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| kagura_memory-0.46.0.tar.gz | 2.0 MB | With provenance | Details for kagura_memory-0.46.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| kagura_memory-0.46.0-py3-none-any.whl | Python 3 | none | any | Details for kagura_memory-0.46.0-py3-none-any.whl |
Total release size: 2.5 MB
Release files / kagura_memory-0.46.0.tar.gz
| Download URL | kagura_memory-0.46.0.tar.gz |
|---|---|
| Size | 2.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8e5c8e6b307252093409b4911f839d38b62506306b55a6db236605fca65bed9e
|
|
BLAKE2b-256 checksum How to use checksums |
ac3204cafb9ea3c6a7e3ba538df1b5df6a2cb7ef152a9323e6cb7b05783d5a7f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 10, 2026.
Transparency logRelease files / kagura_memory-0.46.0-py3-none-any.whl
| Download URL | kagura_memory-0.46.0-py3-none-any.whl |
|---|---|
| Size | 468.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8b2891400c193c33fe8650c02a852dc139d1411be5bfa023157f765949e0fbf7
|
|
BLAKE2b-256 checksum How to use checksums |
daa1eabb265ede3da34b7d49facc2491a66e78a4821f3dc91afa53c889ef9277
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 10, 2026.
Transparency logSecurity for kagura-memory 0.46.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for kagura_memory-0.46.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 10, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














