
LLMRig
Autopilot for local AI.
Give LLMRig a model and a machine. It plans the evidenced local execution path, changes nothing without permission, applies the approved setup, verifies reality, and records what happened.


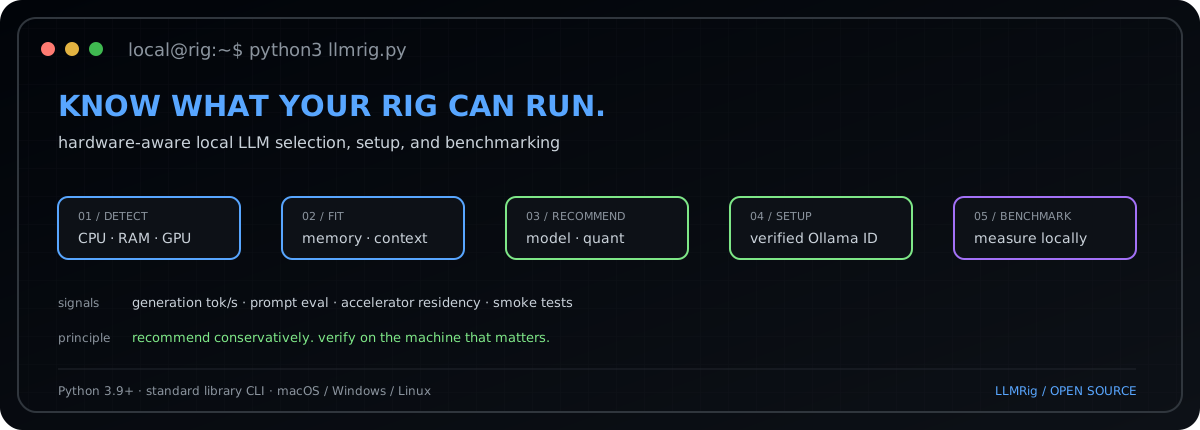
LLMRig sits above local inference runtimes. oMLX, Ollama, MLX-LM, and llama.cpp are execution paths; LLMRig decides what the current evidence supports for this model on this machine.
It deliberately keeps facts separate:
unknown != false
compatible != local
local != executable
executable != measurable
measurable != measured
measured != recommended
measured performance != model quality
discovery metadata != installation trust
The v0.9 Autopilot flow
1. Plan — read only
llmrig plan mlx-community/Qwen3.5-27B-4bit
A plan can include:
- machine and exact model identity
- viable runtime/artifact candidates
- artifact format, quantization, and context evidence
- required acquisition/runtime/model-load actions
- blockers and unknowns
- a verification step defined before mutation
- a deterministic plan ID
plan performs no artifact download, runtime start, model load, or inference.
Example shape:
LLMRig Autopilot Plan
=====================
Plan:    plan-...
Machine: Apple M4 Max · 48 GiB
Model:   mlx-community/Qwen3.5-27B-4bit

Runtime       Format          Quant         Local         Executable
------------  --------------  ------------  ------------  ------------
omlx          MLX             4-bit         not_available not_executable
mlx-lm        MLX             4-bit         not_available not_executable

Setup path: omlx · MLX

Planned actions
1. Acquire the selected artifact [changes local state]
2. Load/register it with the runtime [changes local state]
3. Verify with the deterministic workload [verification]

No action has been taken.
If multiple setup paths remain valid, LLMRig stays inconclusive rather than inventing a winner.
2. Apply — explicit intent
llmrig apply mlx-community/Qwen3.5-27B-4bit \
  --plan-id plan-...
LLMRig recomputes the plan immediately before apply. If current evidence no longer produces the approved plan ID, apply fails closed with plan drift detected.
Mutating actions require either interactive approval or an explicit non-interactive approval flag:
llmrig apply MODEL --plan-id plan-... --yes
Exact Hugging Face acquisition is pinned to the repository revision returned by the Hub. Generic discovery metadata never becomes installation trust.
Approved Hugging Face acquisition uses the bundled huggingface_hub dependency and pins downloads to the exact repository revision resolved by the Hub.
3. Verify — measure current reality
Apply includes measured verification when the selected runtime is executable. You can also re-observe and re-verify a prior receipt:
llmrig verify
llmrig verify receipt-...
verify does not trust an old success record. It recomputes current evidence, requires the exact runtime/artifact candidate to remain uniquely evidenced, refuses any mutation, and then runs the deterministic measurement workload.
Unavailable metrics remain unknown. LLMRig never synthesizes missing throughput from incomparable timing data.
4. Run — the convenience workflow
llmrig run MODEL
run is the product shortcut for plan → explicit approval → apply → verify. It does not bypass the approval boundary. For automation, intent must still be explicit:
llmrig run MODEL --yes
Action receipts
Every applied workflow produces a privacy-safe receipt containing:
plan ID
receipt ID
model / artifact / runtime identity
actions attempted
status and public evidence
verification measurements
public endpoint when applicable
timestamps
Private filesystem locators, API keys, session cookies, and secrets are not serialized into receipts.
RigGraph — local evidence that can learn from reality
Successful measured verification is persisted locally as graph-shaped evidence across:
machine
  × model
  × artifact
  × quantization
  × runtime
  × context
  × measurement
Prediction and measurement are separate facts. Calibration deltas are computed only when the same metric exists on both sides.
prediction: generation_tps = unknown
measurement: generation_tps = 31.2
calibration: generation_tps_delta = unknown
No anonymous/community upload occurs by default in v0.9.
Runtime intelligence
llmrig runtimes
llmrig runtimes --json
The adapter registry currently covers:
| Runtime | Readiness detection | LLMRig execution / measurement | Primary artifact evidence |
|---|---|---|---|
| oMLX | Yes | Yes, for provenance-backed local models | MLX |
| Ollama | Yes | Yes | Ollama-managed artifacts |
| MLX-LM | Yes | Yes, for explicit/evidenced local artifacts | MLX |
| llama.cpp | Yes | Yes, for explicit/evidenced local artifacts | GGUF |
Runtime probing remains read-only. Mutation support is adapter-specific and unsupported actions remain explicit blockers rather than being silently emulated.
Solve — inspect evidence without Autopilot actions
llmrig solve MODEL
llmrig solve MODEL --json
llmrig solve MODEL --context 32768
solve constructs orthogonal evidence dimensions for each candidate:
discovery
compatibility
runtime availability
local availability
execution
measurement capability
measurement
recommendation
A candidate can therefore be compatible but not local, local but not executable, executable but not measured, or measured without being recommendable.
Explicit local artifacts
LLMRig does not scan arbitrary directories for native model files. Supply a locator explicitly when you want a native local artifact considered:
llmrig solve MODEL --local-artifact llama.cpp=/path/to/model.gguf
llmrig solve MODEL --local-artifact mlx-lm=/path/to/model-directory
The private locator stays at the execution seam and is excluded from public solve output.
Hugging Face-native resolution
Exact owner/repository identifiers are resolved through read-only Hub metadata. LLMRig may read the repository's small config.json when needed for structured format, quantization, or context evidence; it does not download weights during resolution.
Evidence rules include:
.ggufestablishes GGUF packaging; filename quantization is accepted only when exactly one recognized token is present- generic
.safetensorsdoes not itself establish MLX/oMLX compatibility - an
mlxtag/path hint alone is not proof of MLX packaging - MLX packaging requires stronger structured evidence such as explicit
library_name=mlxor an MLX hint backed by the MLX-LM quantization contract - conflicting context, quantization, provenance, or incomplete shard groupings fail closed
oMLX
LLMRig can associate an API-visible oMLX model with an exact Hugging Face repository only when provenance is defensible: exact runtime source metadata, or an exact completed-download record whose mapping is unique and unambiguous.
Authenticated local endpoints are supported through:
export OMLX_API_KEY="..."
llmrig runtimes
The API key, admin-session cookie, filesystem model path, and private execution locator are never serialized into public results.
Measurement and comparison
Existing measured-analysis commands remain available:
| Command | Purpose |
|---|---|
solve --verify |
verify a comparable solve candidate set |
race |
compare local configurations |
choose |
explain one measured objective |
optimize |
expose an unranked noise-aware Pareto frontier |
bench |
full Ollama benchmark |
Performance measurement does not establish model quality. Results inside the configured 5% race threshold remain inconclusive.
Minimal Python SDK
import llmrig

result = llmrig.solve("mlx-community/Qwen3.5-27B-4bit")
print(result.plan.recommendation_status)
Stable entry point:
llmrig.solve(
    model,
    *,
    context=None,
    local_artifacts=(),
    verify=False,
) -> llmrig.SolveResult
The SDK prints nothing and never exits the process. SolveResult and SolveCandidate are deliberate public contracts; _llmrig remains private implementation.
Installation
pipx is recommended:
pipx install llmrig
llmrig --version
Upgrade:
pipx upgrade llmrig
Or use a virtual environment:
python3 -m venv .venv
source .venv/bin/activate
python -m pip install llmrig
Windows PowerShell:
python -m venv .venv
.venv\Scripts\Activate.ps1
python -m pip install llmrig
LLMRig supports Python 3.9+ on macOS, Linux, and Windows. Hugging Face Hub support is included for exact, revision-pinned artifact acquisition.
Architecture
                     LLMRig
                  ┌───────────┐
                  │ RigGraph  │
                  └─────┬─────┘
                        │
             ┌──────────┴──────────┐
             │   Autopilot Engine  │
             └──────────┬──────────┘
                        │
     ┌──────────┬───────┼───────┬──────────┐
     ↓          ↓       ↓       ↓          ↓
   oMLX       Ollama  MLX-LM llama.cpp   future
The north star is Detect → Decide → Configure → Run → Verify, with explicit intent at every mutation boundary.
See ROADMAP_V1.md.
Project docs
CHANGELOG.md— canonical release historyROADMAP_V1.md— product directionRELEASING.md— GitHub Release and PyPI processSECURITY.md— security policy and trust boundariesCONTRIBUTING.md— contribution guide
License
MIT
1 maintainer

Release files for llmrig 0.9.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| llmrig-0.9.0.tar.gz | 167.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| llmrig-0.9.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 296.1 kB
Release files / llmrig-0.9.0.tar.gz
| Download URL | llmrig-0.9.0.tar.gz |
|---|---|
| Size | 167.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
886d566c010802db14787329f938f13709567f528013c36d52ee3c11b3e86f00
|
|
BLAKE2b-256 checksum How to use checksums |
abbcab58834119d2731fb101f0b4f4b815bbe694d9e634abc1f07a9f04449f96
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency logRelease files / llmrig-0.9.0-py3-none-any.whl
| Download URL | llmrig-0.9.0-py3-none-any.whl |
|---|---|
| Size | 128.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a3ac4c89ba0fceb646f4227eb87b1e0b04132019575f8b2f26ec45ace9c402dc
|
|
BLAKE2b-256 checksum How to use checksums |
c84e99c83de12ccdf07d52490c4efa379bf036a2381efdc2f7aa0367c68a859c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 24, 2026.
Transparency log













