
This release is a pre-release and may not be stable for production use.


Overview
Speculators is a unified library for building, training and storing speculative decoding algorithms for large language model (LLM) inference, including in frameworks like vLLM. Speculative decoding is a lossless technique that speeds up LLM inference by using a smaller, faster draft model (i.e "the speculator") to propose tokens, which are then verified by the larger base model, reducing latency without compromising output quality. The speculator intelligently drafts multiple tokens ahead of time, and the base model verifies them in a single forward pass. This approach boosts performance without sacrificing output quality, as every accepted token is guaranteed to match what the main model would have generated on its own.
Speculators standardizes this process by providing a productionized end-to-end framework to train draft models with reusable formats and tools. Trained models can seamlessly run in vLLM, enabling the deployment of speculative decoding in production-grade inference servers.

💬 Join us on the vLLM Community Slack and share your questions, thoughts, or ideas in:
#speculators#feat-spec-decode
🎥 Watch our Office Hours presentation: Video | Slides
Key Features
- Draft Model Training Support: E2E training support of single and multi-layer draft models. Training is supported for MoE, non-MoE, and Vision-Language models.
- Standardized, Extensible Format: Provides a Hugging Face-compatible format for defining speculative models, with tools to convert from external research repositories into a standard speculators format for easy adoption.
- Seamless vLLM Integration: Built for direct deployment into vLLM, enabling low-latency, production-grade inference with minimal overhead.
Supported Models
The following table summarizes the models that have been trained end-to-end by our team as well as others in the roadmap:
| Verifier Architecture | Verifier Size | Training Support | vLLM Deployment Support |
|---|---|---|---|
| Llama | 8B-Instruct | EAGLE-3 ✅ | ✅ |
| 70B-Instruct | EAGLE-3 ✅ | ✅ | |
| Qwen3 | 8B | EAGLE-3 ✅ | ✅ |
| 14B | EAGLE-3 ✅ | ✅ | |
| 32B | EAGLE-3 ✅ | ✅ | |
| gpt-oss | 20b | EAGLE-3 ✅ | ✅ |
| 120b | EAGLE-3 ✅ | ✅ | |
| Qwen3 MoE | 30B-Instruct | EAGLE-3 ✅ | ✅ |
| 235B-Instruct | EAGLE-3 ✅ | ✅ | |
| 235B | EAGLE-3 ✅ | ✅ | |
| Qwen3-VL | 235B-A22B | EAGLE-3 ✅ | ✅ |
| Mistral 3 Large | 675B-Instruct | EAGLE-3 ⏳ | ⏳ |
✅ = Supported, ⏳ = In Progress, ❌ = Not Yet Supported
vLLM Inference
Models trained through Speculators can run seamlessly in vLLM using a simple vllm serve <speculator_model> command. This will run the model in vLLM using default arguments, defined in the speculator_config of the model's config.json.
vllm serve RedHatAI/Qwen3-8B-speculator.eagle3
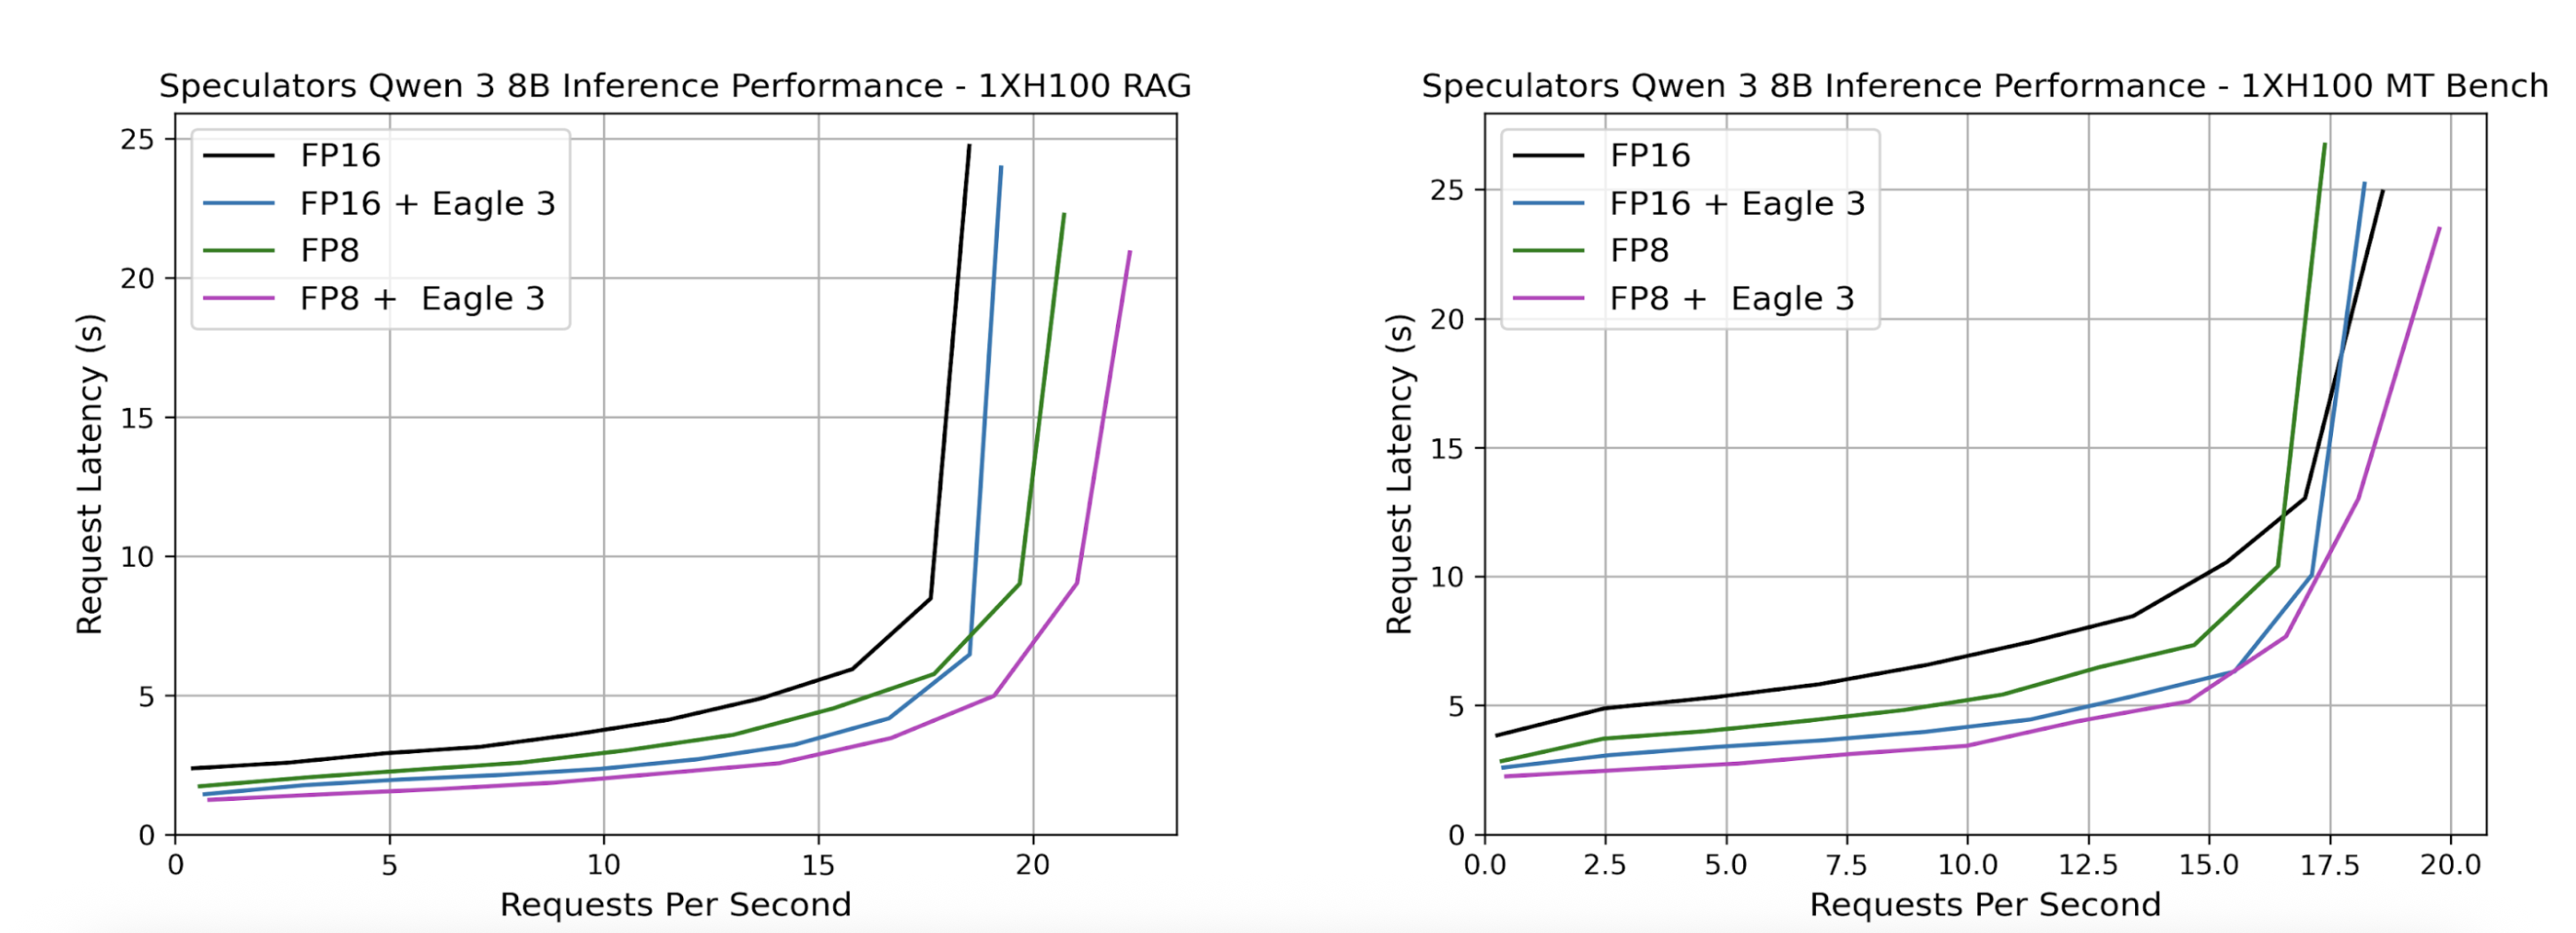
Served models can then be benchmarked using GuideLLM. Below, we show sample benchmark results where we compare our speculator with its dense counterpart. We also additionally compare quantization to explore additional performance improvements by swapping the dense verifier, Qwen/Qwen3-8B with the quantized FP8 model, RedHatAI/Qwen3-8B-FP8-dynamic in the speculator_config.
Getting Started
Installation
Prerequisites
Before installing, ensure you have the following:
- Operating System: Linux or macOS
- Python: 3.10 or higher
- Package Manager: pip (recommended) or conda
Install from PyPI (Recommended)
Install the latest stable release from PyPI:
pip install speculators
Install from Source
For the latest development version or to contribute to the project:
git clone https://github.com/vllm-project/speculators.git
cd speculators

pip install -e .
For development with additional tools:
pip install -e ".[dev]"
Verify Installation
You can verify your installation by checking the version:
speculators --version
Or by importing the package in Python:
import speculators
print(speculators.__version__)
License
Speculators is licensed under the Apache License 2.0.
Cite
If you find Speculators helpful in your research or projects, please consider citing it:
@misc{speculators2025,
  title={Speculators: A Unified Library for Speculative Decoding Algorithms in LLM Serving},
  author={Red Hat},
  year={2025},
  howpublished={\url{https://github.com/vllm-project/speculators}},
}
1 maintainer

Metadata
1 maintainer
Release files for speculators 0.4.0a2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| speculators-0.4.0a2.tar.gz | 79.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| speculators-0.4.0a2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 167.2 kB
Release files / speculators-0.4.0a2.tar.gz
| Download URL | speculators-0.4.0a2.tar.gz |
|---|---|
| Size | 79.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b5a067028c5698efd28184f6d47b074321e781f782043151ab3eb4b755bb0264
|
|
BLAKE2b-256 checksum How to use checksums |
52500ff18678c293a305830bb5d0050ae85cb8daba6a3595d3f7e285dbe03617
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.22
|
Release files / speculators-0.4.0a2-py3-none-any.whl
| Download URL | speculators-0.4.0a2-py3-none-any.whl |
|---|---|
| Size | 87.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6dabbab706ff3457a9042f4ce7c86c717b7fc38a0ee6e77065c840e81c86a08e
|
|
BLAKE2b-256 checksum How to use checksums |
aa03795de08fc142a9f1b7faf1601f5431d365fc964625c9ac3a765376b2ae77
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.22
|














