
LLMRig
Plan it. Run it. Verify it.
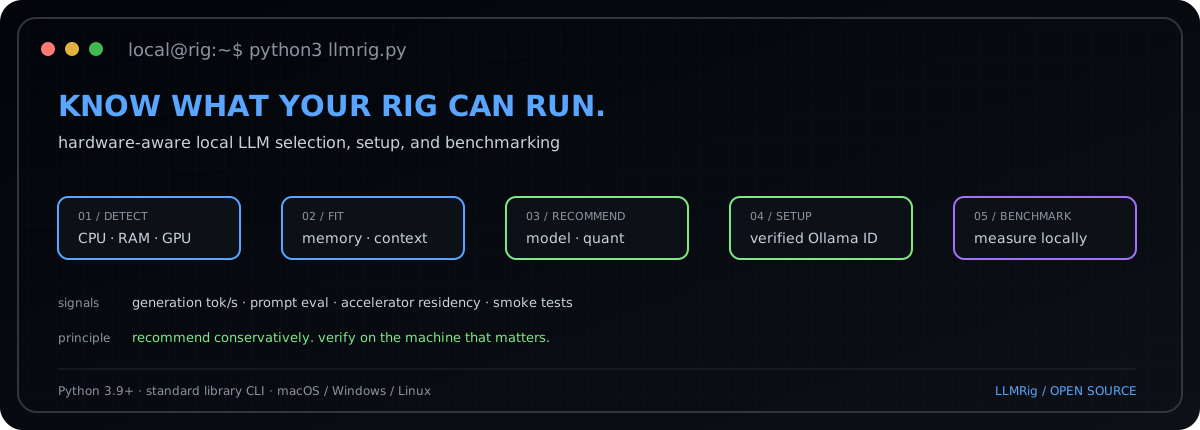
LLMRig helps you choose an evidence-backed local AI setup, understand what is blocked, approve supported actions, and verify what actually ran. Works across Ollama, oMLX, MLX-LM and llama.cpp where the exact path is supported.


Start here
Install LLMRig v0.10.0 using isolated pipx.
See the installation guide for platform-specific setup.
pipx install llmrig
llmrig --help
llmrig runtimes
llmrig doctor mlx-community/Qwen3-0.6B-4bit
llmrig plan mlx-community/Qwen3-0.6B-4bit
llmrig run mlx-community/Qwen3-0.6B-4bit
Only run is an execution request. Review its plan before approving
downloads, starts or other changes. oMLX must be installed and ready
for the tested small-model setup; a different machine may select a
different path or report a blocker.
The new doctor command is read-only and explains the next step when a runtime or model is blocked. run previews the planned actions and asks permission before downloading, installing, or starting anything. If evidence does not support an executable path, LLMRig stops and explains why. It never pretends a model ran.
After an actual successful verification, share only the approved public facts from the latest local receipt:
llmrig report --share
llmrig report --share --output rig-report.md
llmrig report --json --output rig-report.json
Reports do not upload or publish anything automatically. They omit local private paths, secrets, endpoints, and unrecorded hardware details. They are self-reported measurements, not independent attestations.
Actual end-to-end examples: We verified the complete Autopilot flow on an Apple M4 Max (48 GiB) with oMLX + Qwen3 0.6B (two measured runs, 0.29 s reported latency, no recorded throughput) and Ollama + qwen3.8:27b-mlx (two runs, 49.93 generation tokens/s, 2.5861 s reported latency). These are different models and workloads, not a speed comparison. See the reproducible field-run notes for exact tags, provenance, missing metrics and setup blockers.
Earlier independent LLMRig race-v2 measurements of
mlx-community/Qwen3-0.6B-4bit on MLX-LM also recorded
560.85 generation tokens/s. These observations describe their own
configuration only and are not predictions for your machine.
Learn more in the installation guide, first-run guide, verified Autopilot field runs, and validation matrix.
Installation broken? See Troubleshooting for recovery from stale virtual environments and missing installed package metadata.
Want a visual card? Open the offline Rig Report viewer locally in your browser and load the JSON report. The viewer runs entirely on your machine with no upload or third-party scripts.
Want to compare candidate evidence visually? Save a plan with llmrig plan OWNER/MODEL --json > plan.json, then open the offline Plan Explorer locally and load that JSON file. This is a viewer for actual planner evidence, not a live machine simulator.
Verified local execution
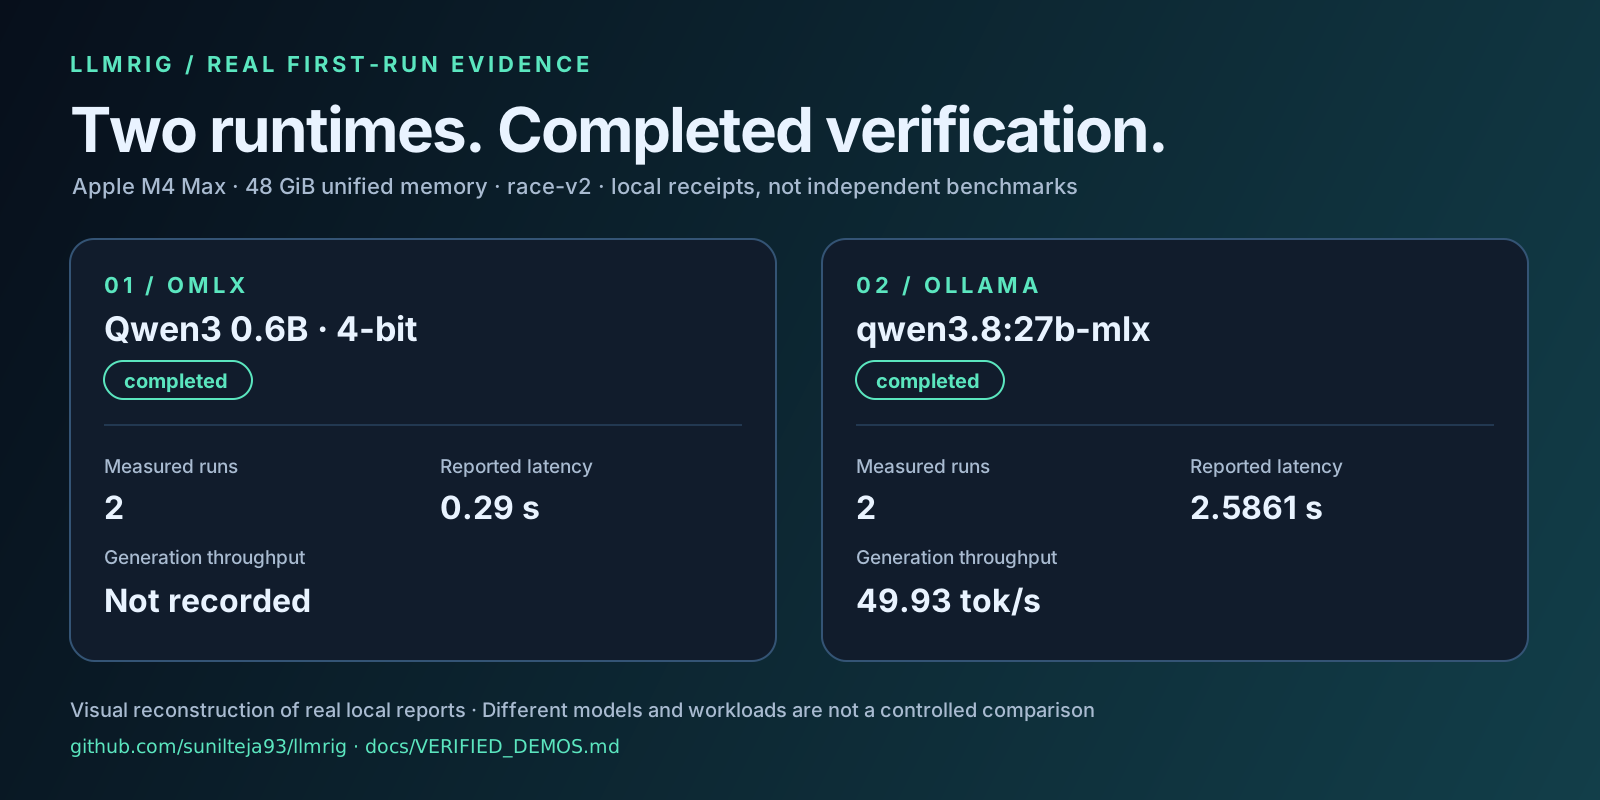
Illustration reconstructed from measured local reports, not a raw screenshot or independent attestation. Missing metrics are not estimated. The two models cannot be compared as a controlled runtime speed test.
The offline Rig Report viewer renders real
user-generated JSON reports locally. After your own successful
llmrig run, generate llmrig report --json --output rig-report.json,
open the viewer in a local browser and click View report to produce
a shareable, inspectable card.
Why LLMRig
Running models locally still involves too much guesswork:
- Large weights can be downloaded before you discover the intended setup is not viable on your machine.
- Runtime, format, context, and quantization advice is fragmented across model cards, forums, and machine-specific anecdotes.
- oMLX, Ollama, MLX-LM, and llama.cpp expose different artifacts and capabilities, so a model name alone is not an execution plan.
Ollama runs models. LLMRig sits above runtimes and determines what the current evidence supports for this model on this machine — then, with approval, it can apply the supported setup and verify what actually happened.
And when the evidence is not there, LLMRig says unknown instead of converting absence into certainty:
unknown != false
compatible != local
local != executable
executable != measurable
measurable != measured
measured != recommended
measured performance != model quality
discovery metadata != installation trust
Quickstart
pipx install llmrig
llmrig runtimes              # inspect which local runtimes are ready
llmrig plan MODEL            # build a deterministic read-only plan
llmrig run MODEL             # approve supported actions, then verify
For a fully reproducible test, use the pinned Git commit or published package version documented in INSTALL.md.
solve and plan are read-only. Downloads, runtime starts, model loads, and other mutations require explicit approval. For non-interactive automation, use --yes only when that intent is deliberate.
Measured, not guessed
Planning evidence and measured performance are separate facts. Before verification, unavailable performance stays unknown.
These are real v0.9 Apple Silicon observations recorded by LLMRig's race-v2 verification workload:
| Machine | Model | Runtime | Quant | Generation tok/s | Prompt tok/s | Latency |
|---|---|---|---|---|---|---|
| Apple M4 Max · 48 GiB | mlx-community/Qwen3-0.6B-4bit |
MLX-LM | 4-bit | 560.85 | 1629.77 | 0.2639 s |
| Apple M4 Max · 48 GiB | mlx-community/Qwen3-0.6B-4bit |
MLX-LM | 4-bit | 560.23 | 1687.91 | 0.2630 s |
Both rows are genuine measured observations from the same model/runtime/hardware setup, with two measured runs per observation. The first observation predates context-token persistence, so LLMRig does not backfill the missing context value.
More privacy-safe measurements are available in the Benchmark Passports dataset. These numbers describe those exact measured executions; they are not a leaderboard or a claim about model quality.
The Autopilot flow
Four commands, one principle: explicit intent at every mutation boundary.
1. Plan — read only
llmrig plan mlx-community/Qwen3-0.6B-4bit
Produces a deterministic plan ID covering machine identity, viable runtime/artifact candidates, required actions, blockers, and a verification step defined before anything changes. Downloads nothing, starts nothing.
If several setup paths stay valid, LLMRig stays inconclusive rather than inventing a winner.
2. Apply — explicit intent
llmrig apply mlx-community/Qwen3-0.6B-4bit --plan-id plan-... --yes
LLMRig recomputes the plan immediately before applying. If the evidence no longer reproduces the approved plan ID, apply fails closed with plan drift detected. Hugging Face downloads are pinned to the exact repository revision resolved by the Hub.
3. Verify — measure current reality
llmrig verify
llmrig verify receipt-...
Recomputes evidence from scratch, refuses any mutation, and runs the deterministic measurement workload. Old success records are never trusted; missing metrics stay unknown — never synthesized.
4. Run — the convenience workflow
llmrig run MODEL --yes
Plan → approval → apply → verify in one shortcut. It does not bypass the approval boundary.
Action receipts
Every applied workflow emits a privacy-safe receipt: plan ID, receipt ID, model/artifact/runtime identity, actions attempted, status, verification measurements, and timestamps. Filesystem paths, API keys, cookies, and secrets are never serialized.
RigGraph — evidence that learns from reality
Verified measurements persist locally as graph-shaped evidence across machine × model × artifact × quantization × runtime × context × measurement. Predictions and measurements are stored as separate facts; calibration deltas are computed only when the same metric exists on both sides. No community upload happens by default.
Runtime intelligence
llmrig runtimes
llmrig runtimes --json
| Runtime | Readiness detection | LLMRig execution / measurement | Primary artifact evidence |
|---|---|---|---|
| oMLX | Yes | Yes, for provenance-backed local models | MLX |
| Ollama | Yes | Yes | Ollama-managed artifacts |
| MLX-LM | Yes | Yes, for explicit/evidenced local artifacts | MLX |
| llama.cpp | Yes | Yes, for explicit/evidenced local artifacts | GGUF |
Runtime probing is read-only. Unsupported actions surface as explicit blockers, never silent emulation.
LLMRig resolves exact owner/repository identifiers through read-only Hugging Face Hub metadata (no weight downloads during resolution), with strict evidence rules — e.g. an mlx tag alone is not proof of MLX packaging, and conflicting context, quantization, or provenance evidence fails closed.
For split GGUF repositories, LLMRig collapses a complete shard set into one logical artifact, sums the verified shard sizes for machine-fit reasoning, and excludes auxiliary imatrix calibration files from runnable model candidates.
Hugging Face
- LLMRig Autopilot Space — evidence-first walkthrough of the Autopilot flow
- Benchmark Passports dataset — privacy-safe RigGraph measurement samples
- LLMRig collection — Space, dataset, and referenced model grouped together
- Launch discussion — reproducible launch notes and evidence
The Space is intentionally a static explainer: it does not inspect a visitor's machine. Run LLMRig locally for real discovery, planning, execution, and verification.
Measurement and comparison
| Command | Purpose |
|---|---|
solve --verify |
verify a comparable solve candidate set |
race |
compare local configurations |
choose |
explain one measured objective |
optimize |
expose an unranked noise-aware Pareto frontier |
bench |
full Ollama benchmark |
Measurement never establishes model quality, and results inside the configured 5% race threshold stay inconclusive.
Minimal Python SDK
import llmrig

result = llmrig.solve("mlx-community/Qwen3-0.6B-4bit")
print(result.plan.recommendation_status)
llmrig.solve(
    model,
    *,
    context=None,
    local_artifacts=(),
    verify=False,
) -> llmrig.SolveResult
The SDK prints nothing and never exits the process. SolveResult and SolveCandidate are the public contracts; _llmrig stays private.
Installation
For LLMRig v0.10.0, use the published package via
pipx or a clean virtual environment:
pipx install llmrig
llmrig --help
llmrig runtimes
After a new PyPI release is published, an existing pipx install can
upgrade with pipx upgrade llmrig. To select unreleased GitHub code
instead, pin an exact source commit as documented in
the install guide.
For macOS, Linux, Windows PowerShell, PATH issues and safe local API-key setup, see the full installation guide.
Architecture
                     LLMRig
                  ┌───────────┐
                  │ RigGraph  │
                  └─────┬─────┘
                        │
             ┌──────────┴──────────┐
             │   Autopilot Engine  │
             └──────────┬──────────┘
                        │
     ┌──────────┬───────┼───────┬──────────┐
     ↓          ↓       ↓       ↓          ↓
   oMLX       Ollama  MLX-LM llama.cpp   future
The north star is Detect → Decide → Configure → Run → Verify, with explicit intent at every mutation boundary. See ROADMAP_V1.md.
Project docs
CHANGELOG.md— canonical release historyROADMAP_V1.md— product directiondocs/INSTALL.md— clean install and source/release distinctiondocs/VERIFIED_DEMOS.md— real oMLX and Ollama verification transcriptsRELEASING.md— GitHub Release and PyPI processSECURITY.md— security policy and trust boundariesCONTRIBUTING.md— contribution guide
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for llmrig 0.10.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| llmrig-0.10.0.tar.gz | 183.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| llmrig-0.10.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 321.3 kB
Release files / llmrig-0.10.0.tar.gz
| Download URL | llmrig-0.10.0.tar.gz |
|---|---|
| Size | 183.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a23a6136042925109f810ce41c8ed15f13c2e3a2d58c65a510b8d7e769942847
|
|
BLAKE2b-256 checksum How to use checksums |
4ef412c89c0837b3b1064453e5d5b40f6a3030eb14caaae45b6434aca873e6a9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / llmrig-0.10.0-py3-none-any.whl
| Download URL | llmrig-0.10.0-py3-none-any.whl |
|---|---|
| Size | 137.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
03d86cc2dc69016245980eec4fed29e49c42bcf65cd9dd7032709a4f2f340f24
|
|
BLAKE2b-256 checksum How to use checksums |
c522bf0a76b651ed2dad6417dc06d69e46d7080fe19360938f15765653166640
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency log













