


👋 join us on Twitter, Discord and WeChat
News 🎉
- [2023/09] TurboMind supports InternLM-20B
- [2023/09] TurboMind supports all features of Code Llama: code completion, infilling, chat / instruct, and python specialist. Click here for deployment guide
- [2023/09] TurboMind supports Baichuan2-7B
- [2023/08] TurboMind supports flash-attention2.
- [2023/08] TurboMind supports Qwen-7B, dynamic NTK-RoPE scaling and dynamic logN scaling
- [2023/08] TurboMind supports Windows (tp=1)
- [2023/08] TurboMind supports 4-bit inference, 2.4x faster than FP16, the fastest open-source implementation🚀. Check this guide for detailed info
- [2023/08] LMDeploy has launched on the HuggingFace Hub, providing ready-to-use 4-bit models.
- [2023/08] LMDeploy supports 4-bit quantization using the AWQ algorithm.
- [2023/07] TurboMind supports Llama-2 70B with GQA.
- [2023/07] TurboMind supports Llama-2 7B/13B.
- [2023/07] TurboMind supports tensor-parallel inference of InternLM.
Introduction
LMDeploy is a toolkit for compressing, deploying, and serving LLM, developed by the MMRazor and MMDeploy teams. It has the following core features:
-
Efficient Inference Engine (TurboMind): Based on FasterTransformer, we have implemented an efficient inference engine - TurboMind, which supports the inference of LLaMA and its variant models on NVIDIA GPUs.
-
Interactive Inference Mode: By caching the k/v of attention during multi-round dialogue processes, it remembers dialogue history, thus avoiding repetitive processing of historical sessions.
-
Multi-GPU Model Deployment and Quantization: We provide comprehensive model deployment and quantification support, and have been validated at different scales.
-
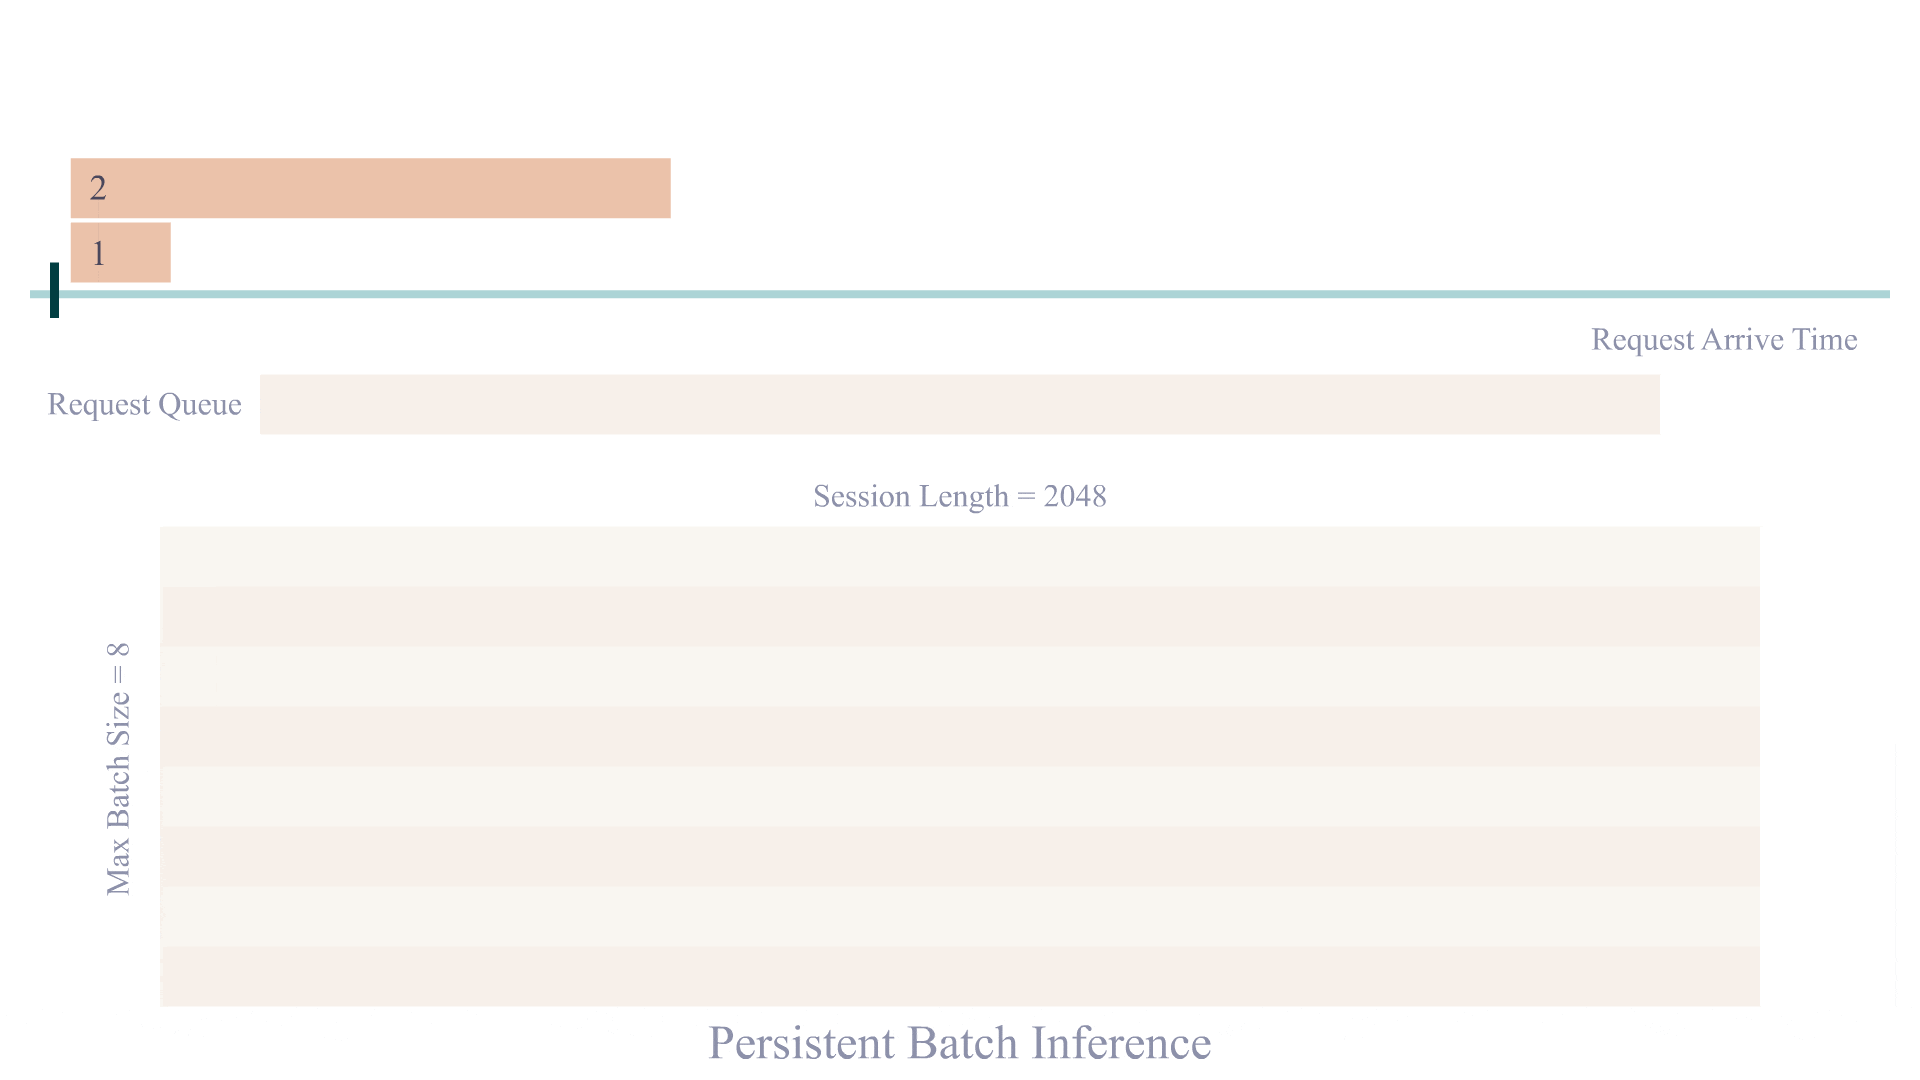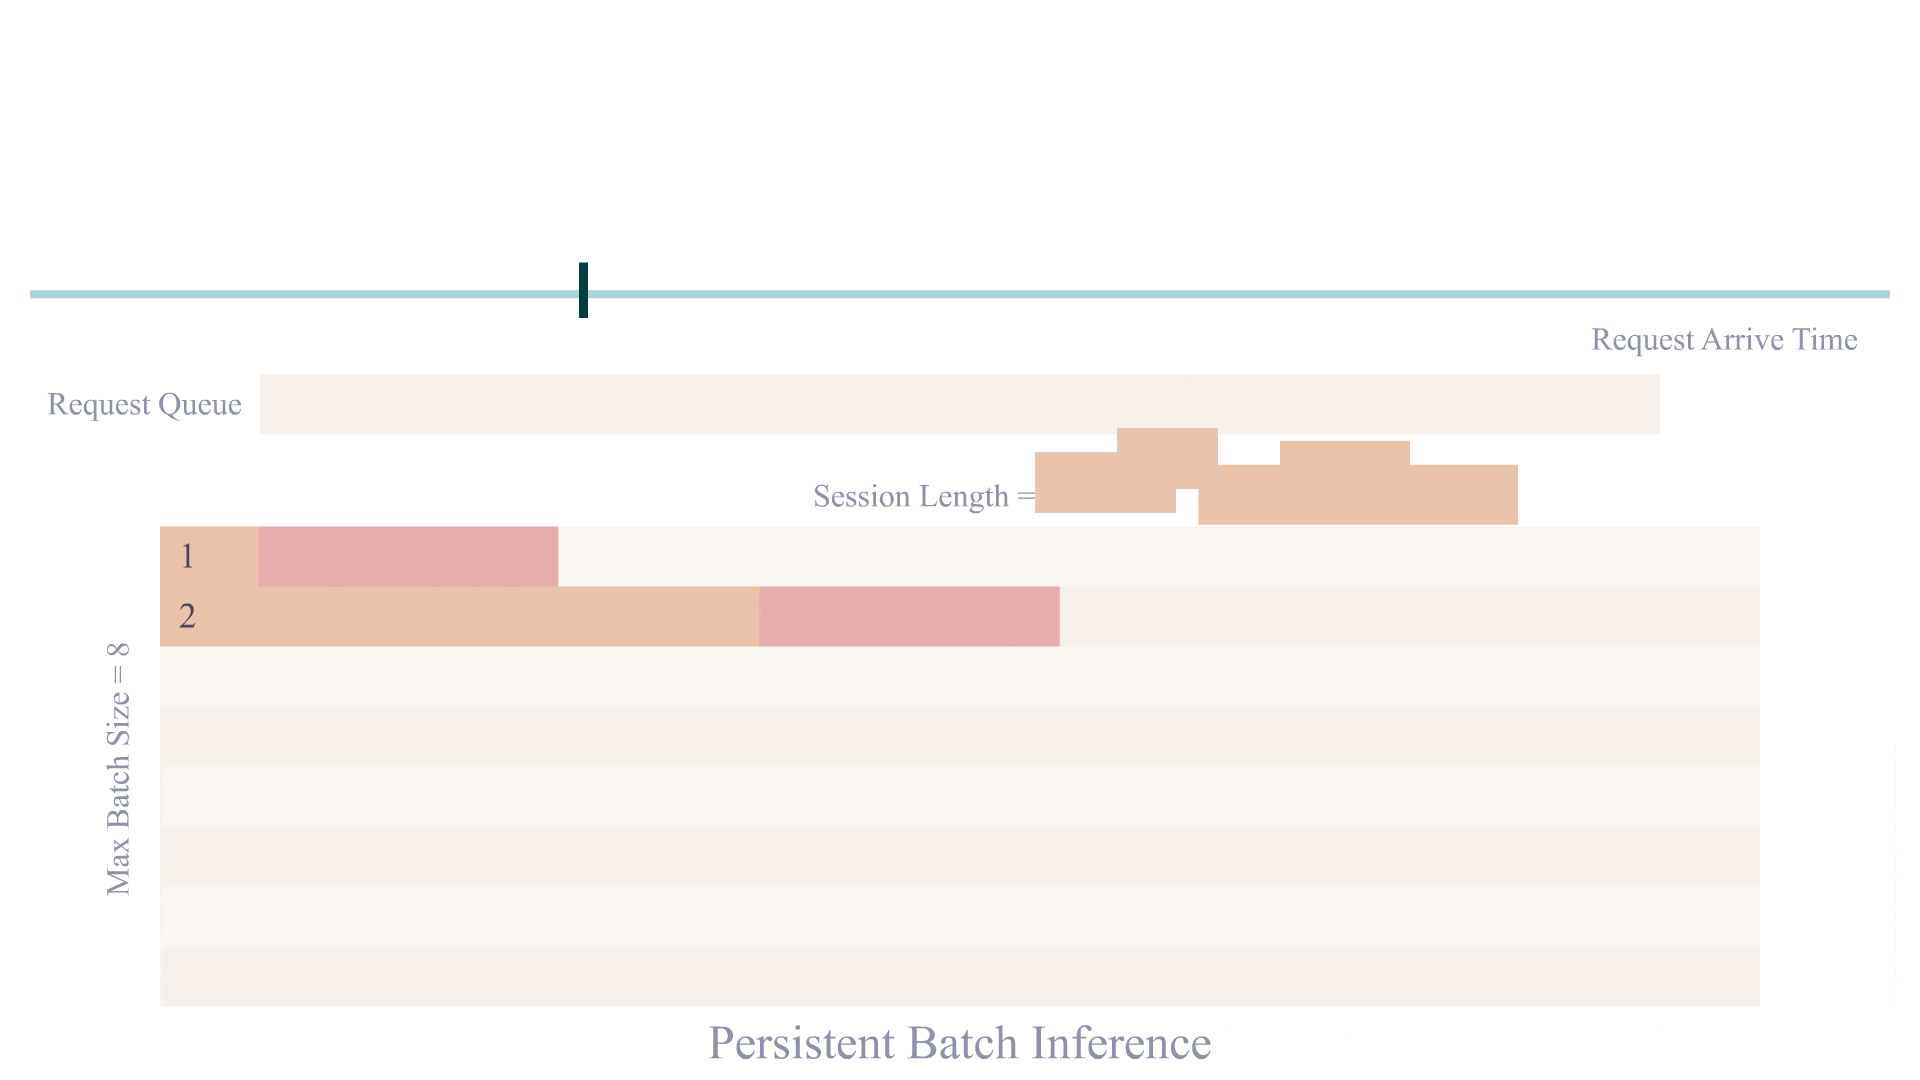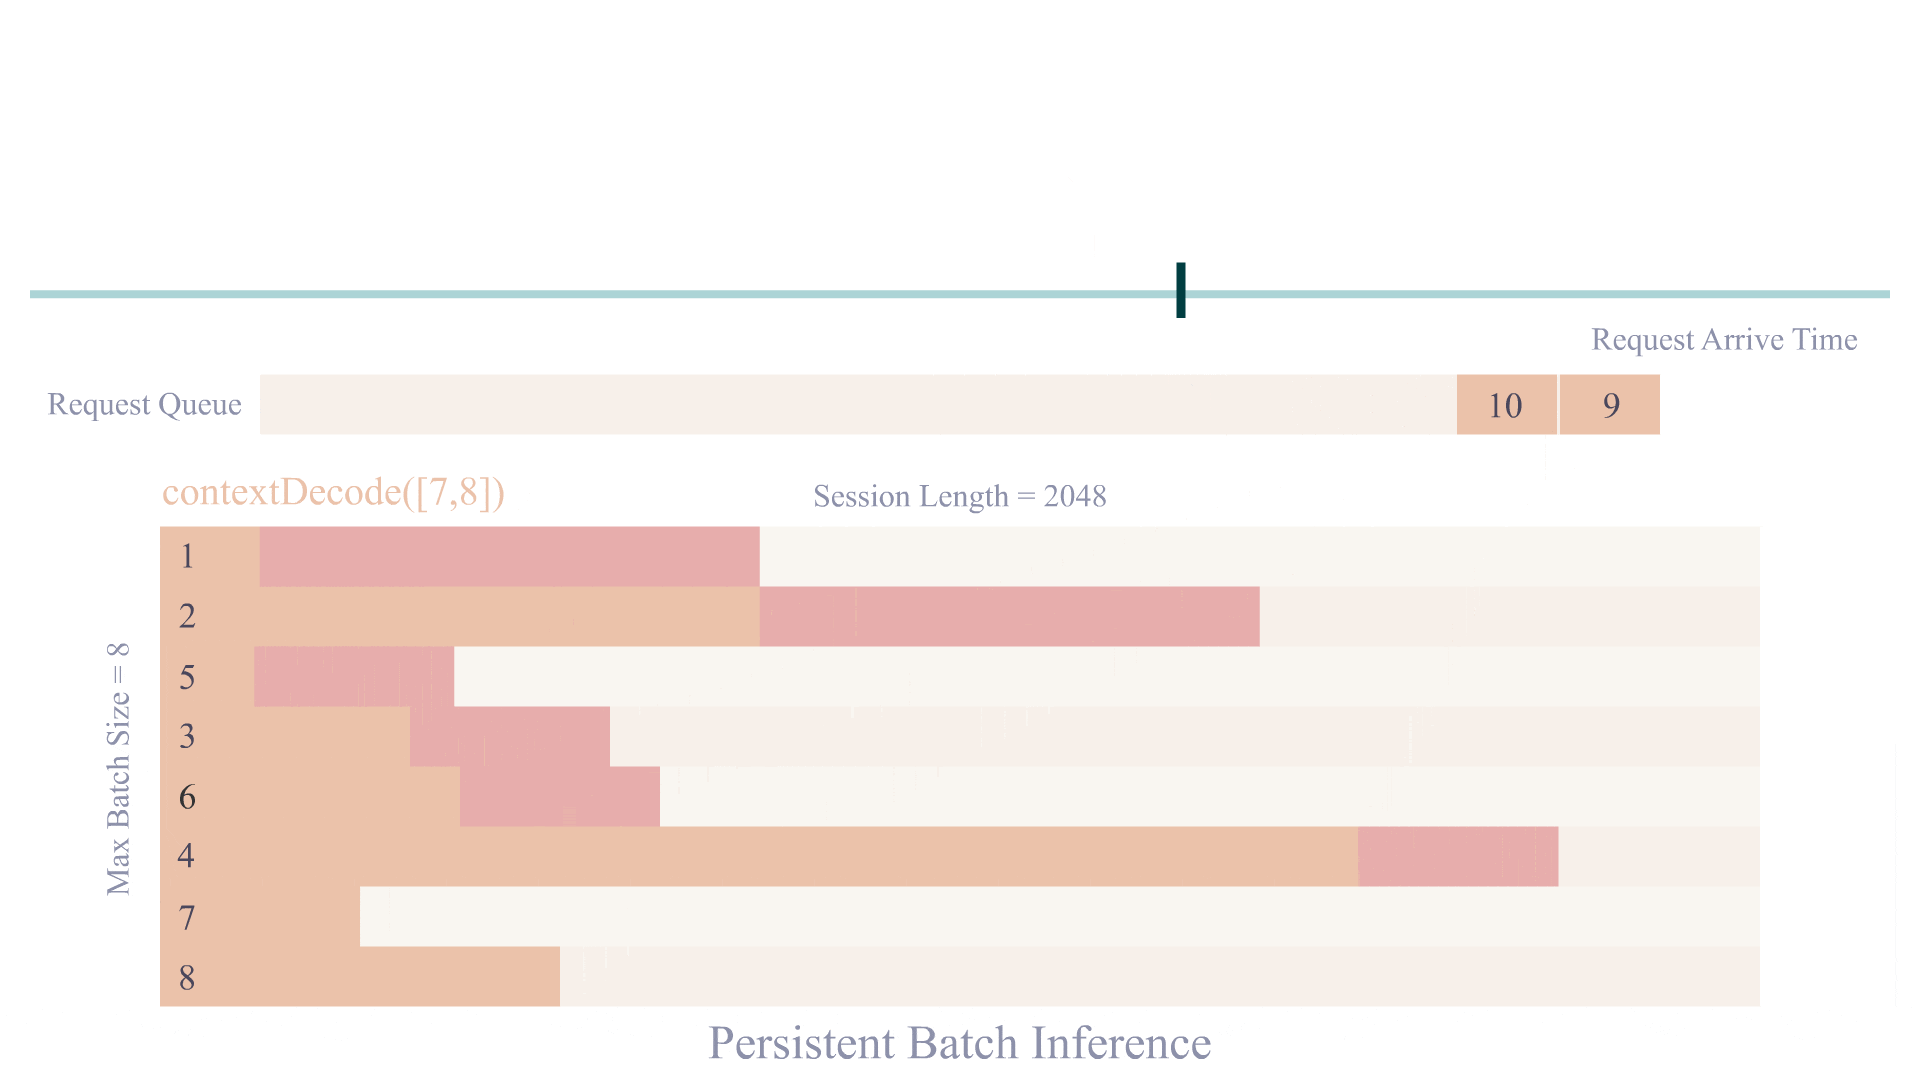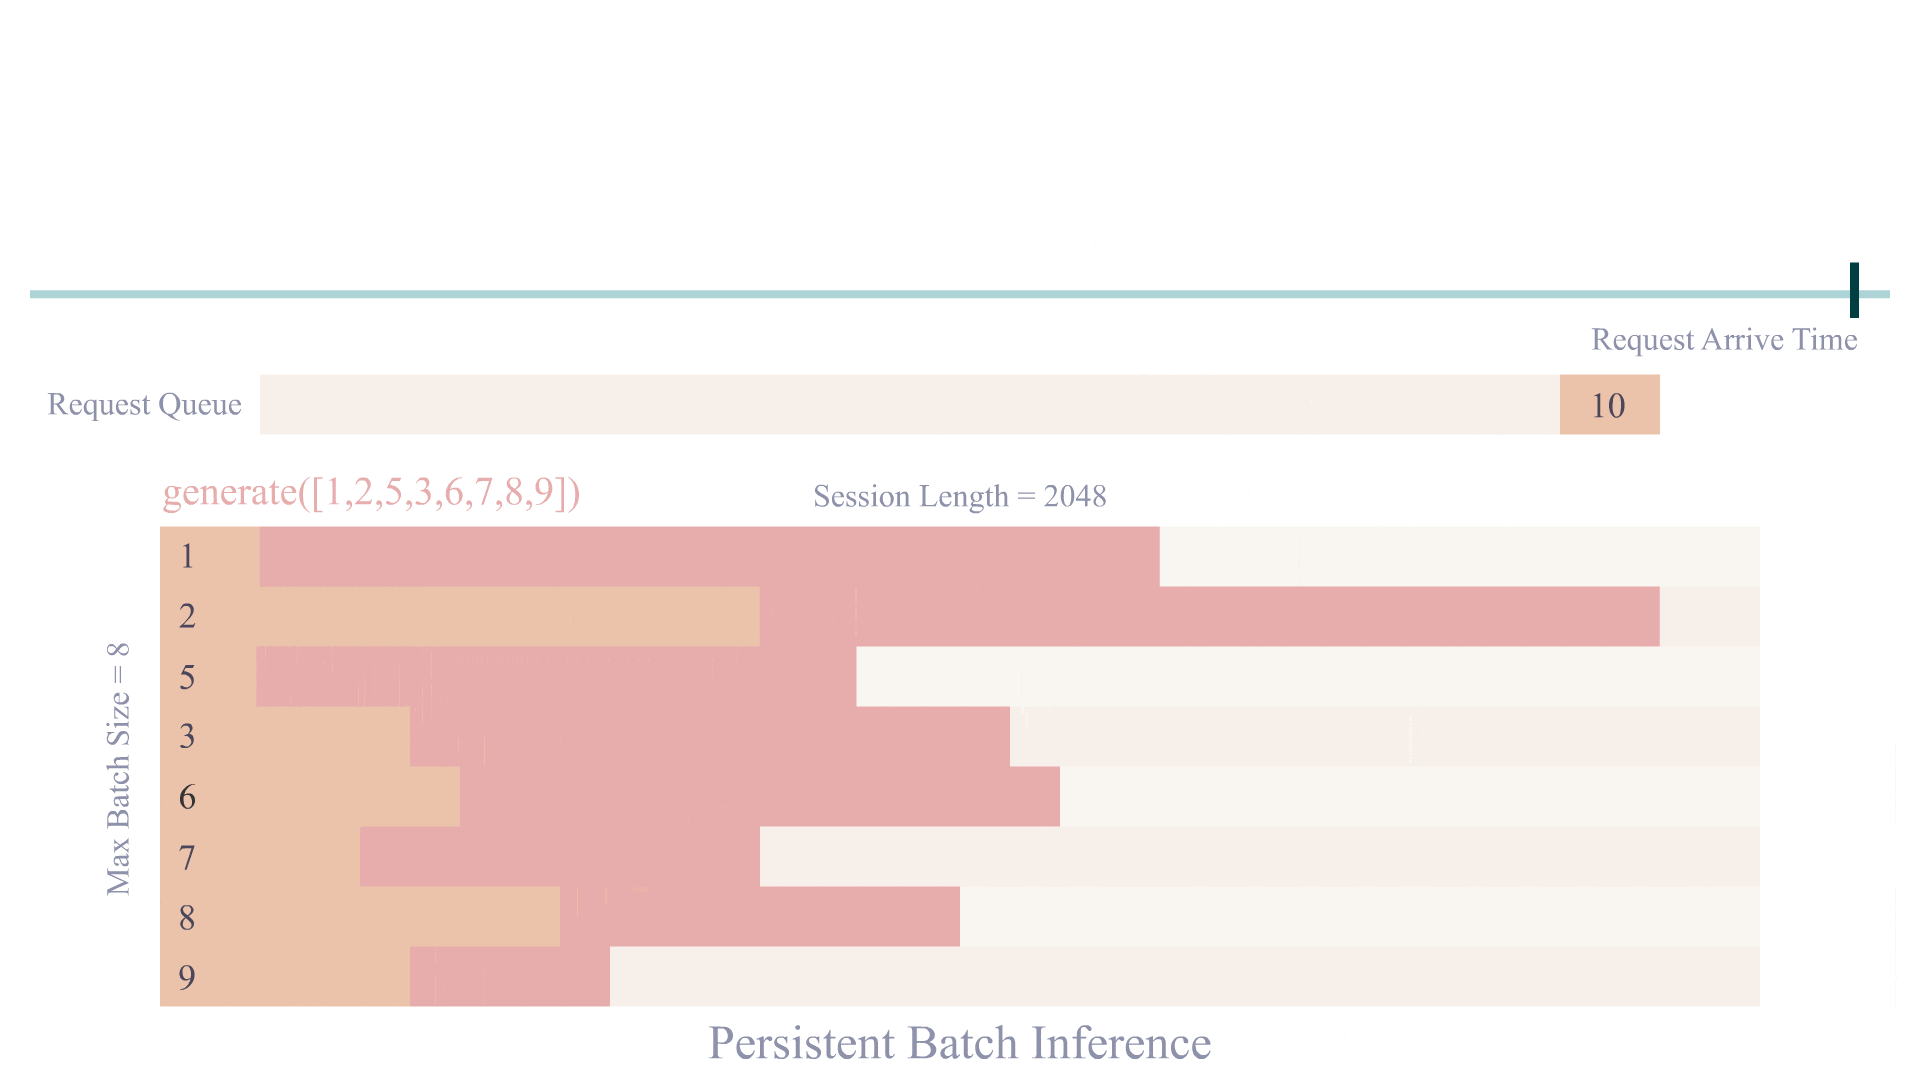
Persistent Batch Inference: Further optimization of model execution efficiency.
Supported Models
LMDeploy has two inference backends, Pytorch and TurboMind.
TurboMind
Note
W4A16 inference requires Nvidia GPU with Ampere architecture or above.
| Models | Tensor Parallel | FP16 | KV INT8 | W4A16 | W8A8 |
|---|---|---|---|---|---|
| Llama | Yes | Yes | Yes | Yes | No |
| Llama2 | Yes | Yes | Yes | Yes | No |
| InternLM-7B | Yes | Yes | Yes | Yes | No |
| InternLM-20B | Yes | Yes | Yes | Yes | No |
| QWen-7B | Yes | Yes | Yes | No | No |
| Baichuan-7B | Yes | Yes | Yes | Yes | No |
| Baichuan2-7B | Yes | Yes | No | No | No |
| Code Llama | Yes | Yes | No | No | No |
Pytorch
| Models | Tensor Parallel | FP16 | KV INT8 | W4A16 | W8A8 |
|---|---|---|---|---|---|
| Llama | Yes | Yes | No | No | No |
| Llama2 | Yes | Yes | No | No | No |
| InternLM-7B | Yes | Yes | No | No | No |
Performance
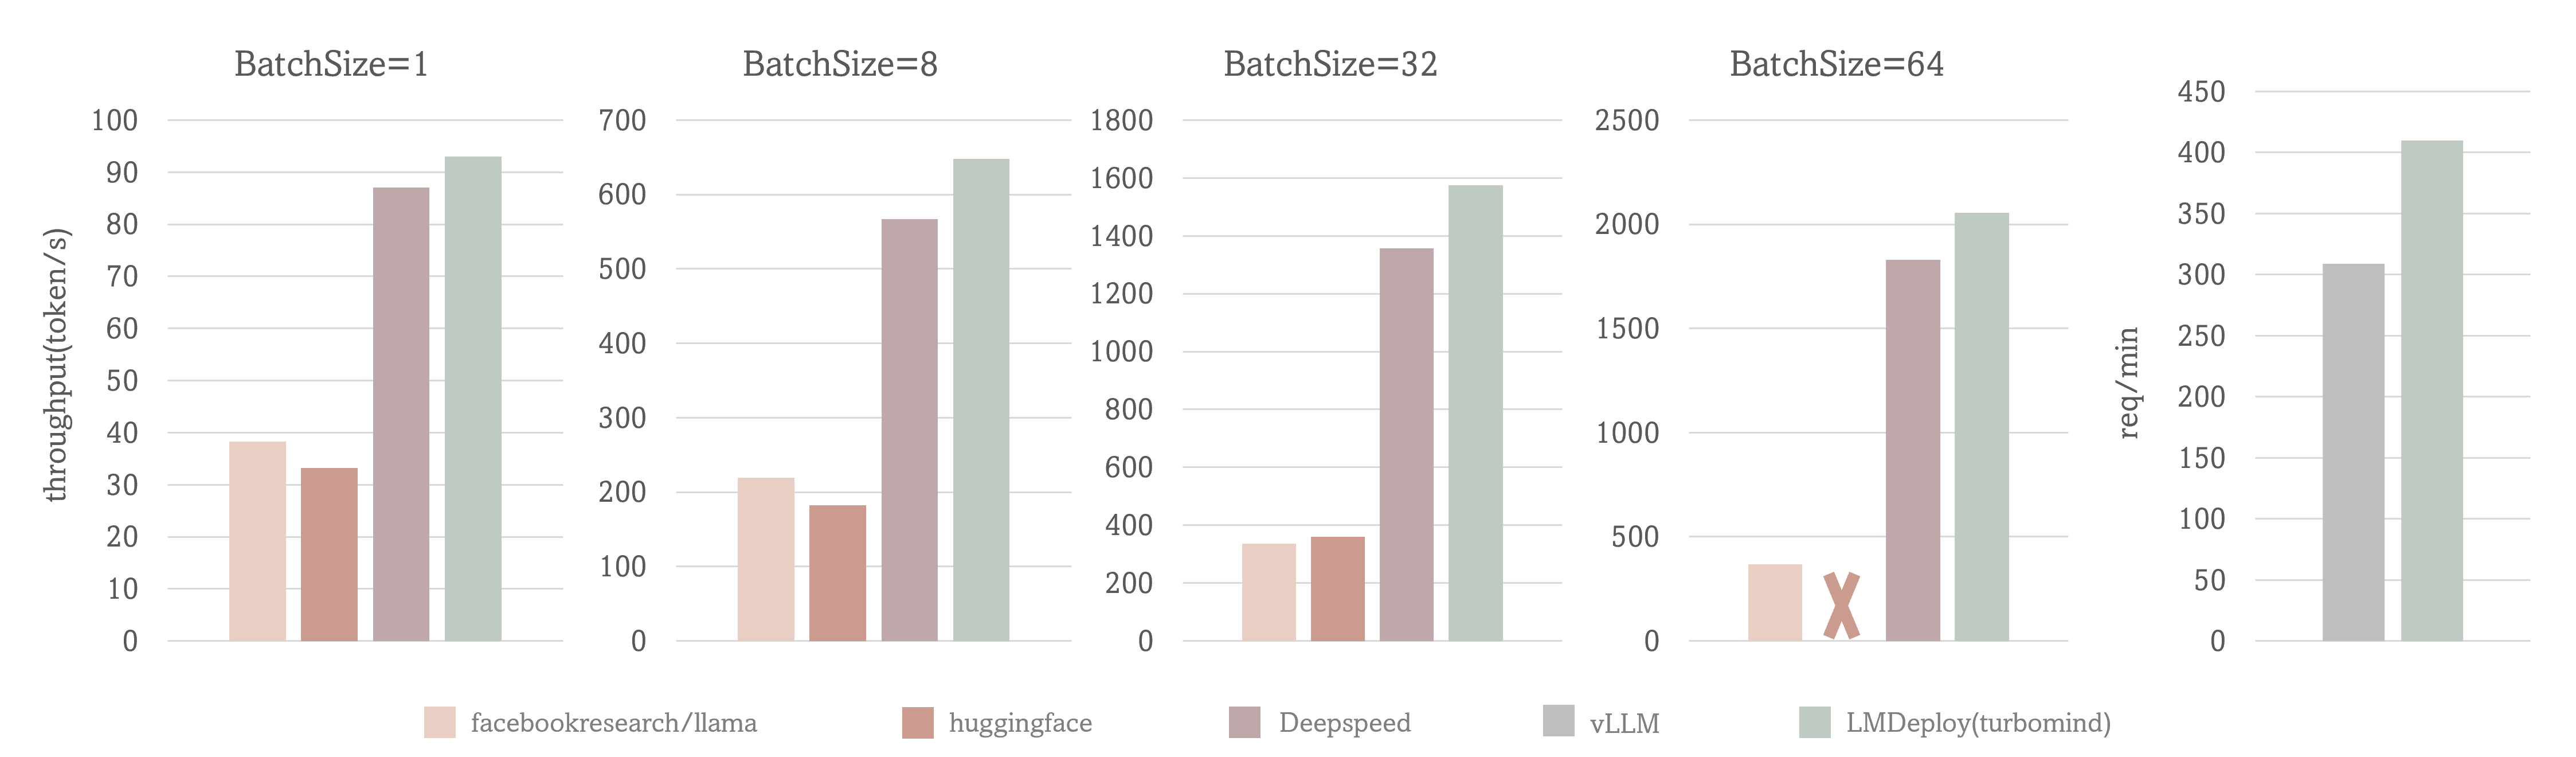
Case I: output token throughput with fixed input token and output token number (1, 2048)
Case II: request throughput with real conversation data
Test Setting: LLaMA-7B, NVIDIA A100(80G)
The output token throughput of TurboMind exceeds 2000 tokens/s, which is about 5% - 15% higher than DeepSpeed overall and outperforms huggingface transformers by up to 2.3x. And the request throughput of TurboMind is 30% higher than vLLM.
Quick Start
Installation
Install lmdeploy with pip ( python 3.8+) or from source
pip install lmdeploy
Deploy InternLM
Get InternLM model
# 1. Download InternLM model

# Make sure you have git-lfs installed (https://git-lfs.com)
git lfs install
git clone https://huggingface.co/internlm/internlm-chat-7b /path/to/internlm-chat-7b

# if you want to clone without large files – just their pointers
# prepend your git clone with the following env var:
GIT_LFS_SKIP_SMUDGE=1

# 2. Convert InternLM model to turbomind's format, which will be in "./workspace" by default
python3 -m lmdeploy.serve.turbomind.deploy internlm-chat-7b /path/to/internlm-chat-7b
Inference by TurboMind
python -m lmdeploy.turbomind.chat ./workspace
Note
When inferring with FP16 precision, the InternLM-7B model requires at least 15.7G of GPU memory overhead on TurboMind.
It is recommended to use NVIDIA cards such as 3090, V100, A100, etc. Disable GPU ECC can free up 10% memory, trysudo nvidia-smi --ecc-config=0and reboot system.
Note
Tensor parallel is available to perform inference on multiple GPUs. Add--tp=<num_gpu>onchatto enable runtime TP.
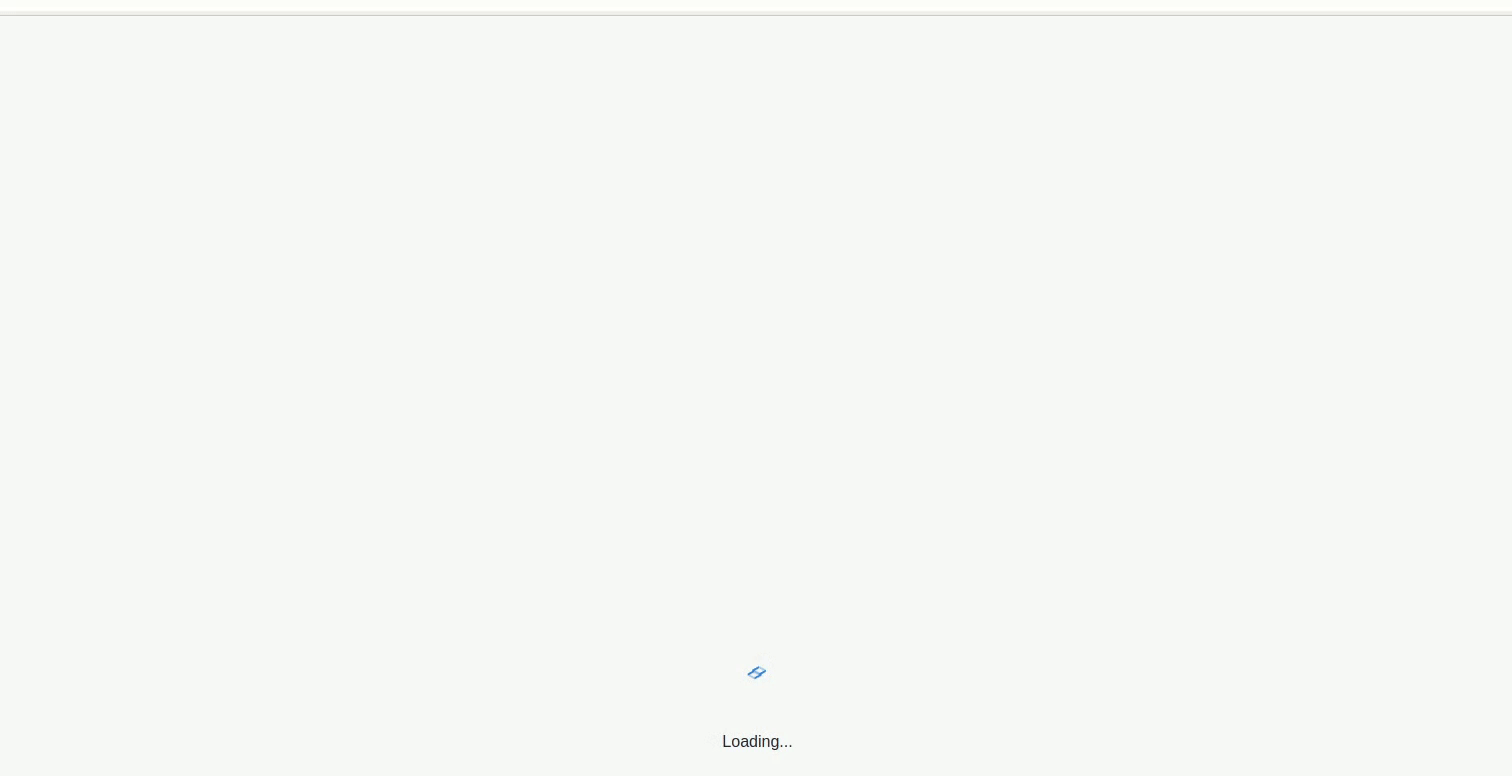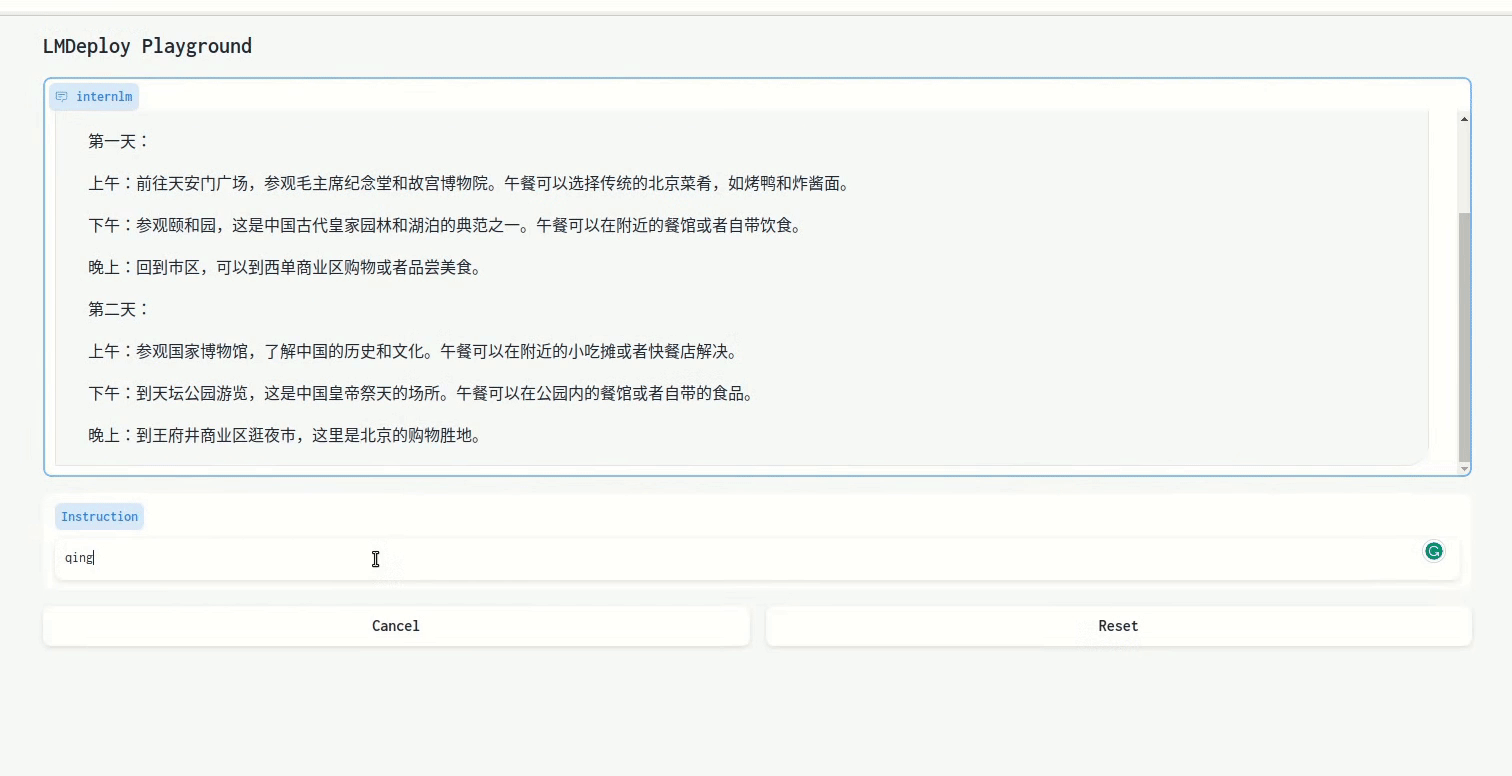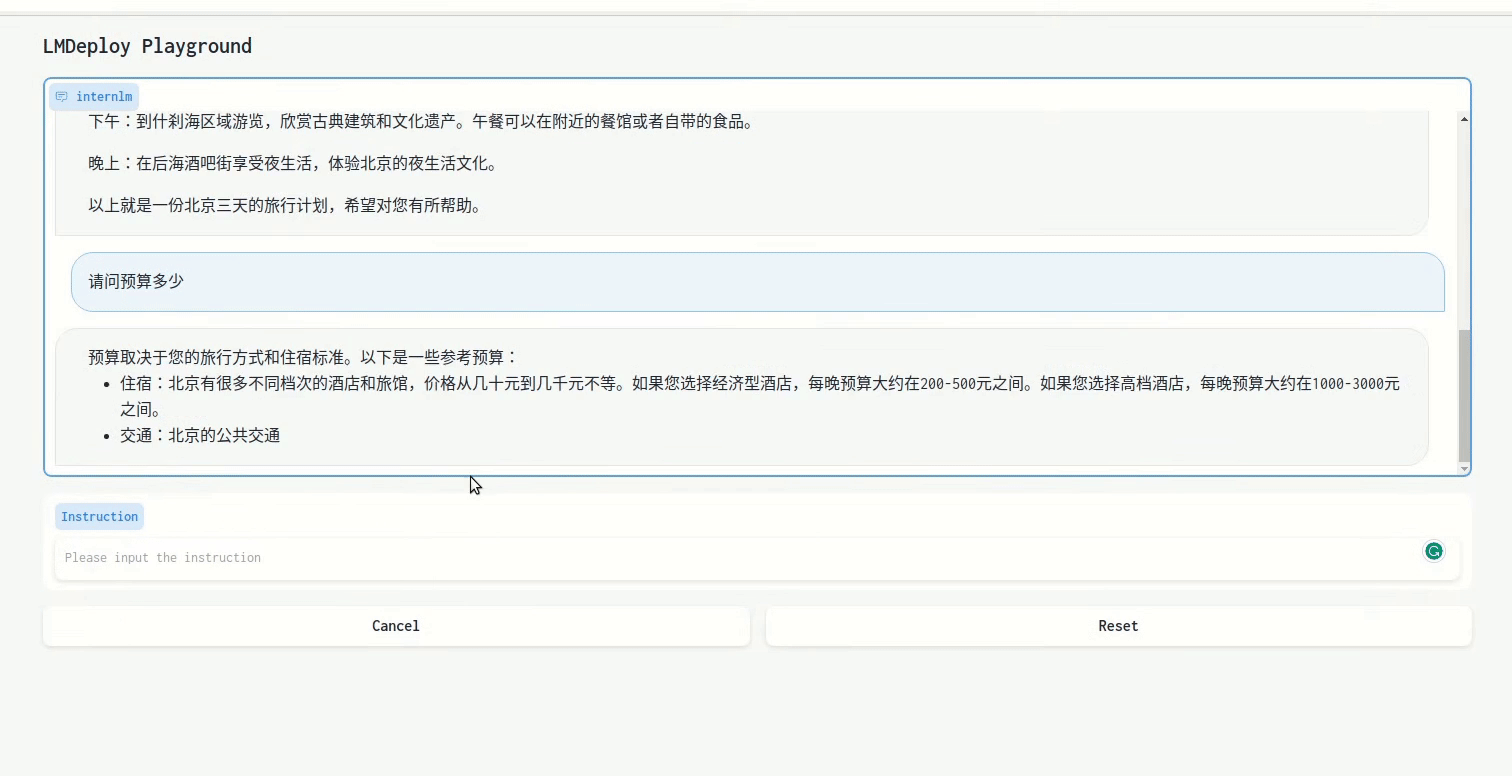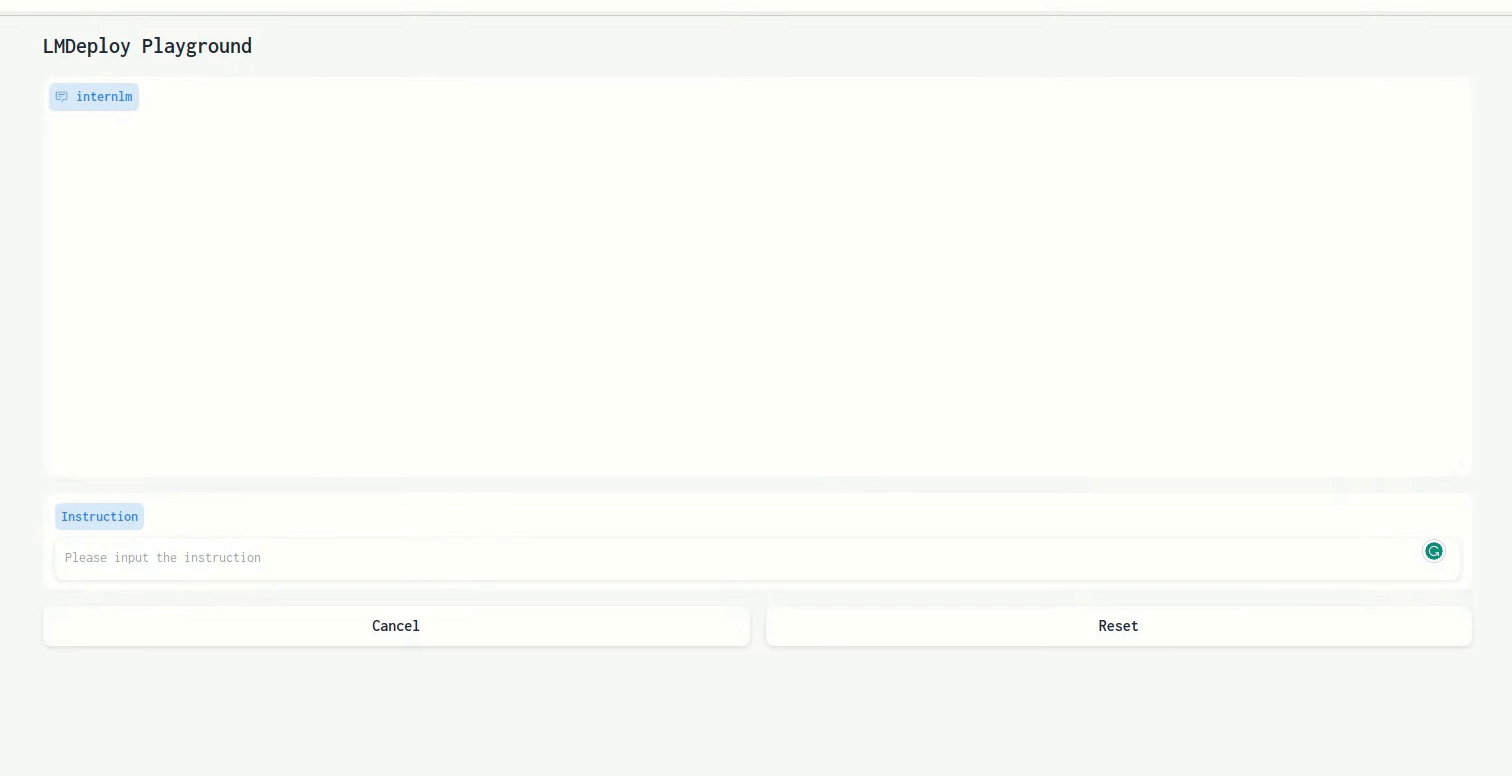
Serving with gradio
python3 -m lmdeploy.serve.gradio.app ./workspace
Serving with Restful API
Launch inference server by:
python3 -m lmdeploy.serve.openai.api_server ./workspace server_ip server_port --instance_num 32 --tp 1
Then, you can communicate with it by command line,
# restful_api_url is what printed in api_server.py, e.g. http://localhost:23333
python -m lmdeploy.serve.openai.api_client restful_api_url
or webui,
# restful_api_url is what printed in api_server.py, e.g. http://localhost:23333
# server_ip and server_port here are for gradio ui
# example: python -m lmdeploy.serve.gradio.app http://localhost:23333 localhost 6006 --restful_api True
python -m lmdeploy.serve.gradio.app restful_api_url server_ip --restful_api True
Refer to restful_api.md for more details.
Serving with Triton Inference Server
Launch inference server by:
bash workspace/service_docker_up.sh
Then, you can communicate with the inference server by command line,
python3 -m lmdeploy.serve.client {server_ip_addresss}:33337
or webui,
python3 -m lmdeploy.serve.gradio.app {server_ip_addresss}:33337
For the deployment of other supported models, such as LLaMA, LLaMA-2, vicuna and so on, you can find the guide from here
Inference with PyTorch
For detailed instructions on Inference pytorch models, see here.
Single GPU
python3 -m lmdeploy.pytorch.chat $NAME_OR_PATH_TO_HF_MODEL \
    --max_new_tokens 64 \
    --temperture 0.8 \
    --top_p 0.95 \
    --seed 0
Tensor Parallel with DeepSpeed
deepspeed --module --num_gpus 2 lmdeploy.pytorch.chat \
    $NAME_OR_PATH_TO_HF_MODEL \
    --max_new_tokens 64 \
    --temperture 0.8 \
    --top_p 0.95 \
    --seed 0
You need to install deepspeed first to use this feature.
pip install deepspeed
Quantization
Weight INT4 Quantization
LMDeploy uses AWQ algorithm for model weight quantization
Click here to view the test results for weight int4 usage.
KV Cache INT8 Quantization
Click here to view the usage method, implementation formula, and test results for kv int8.
Warning
runtime Tensor Parallel for quantized model is not available. Please setup--tpondeployto enable static TP.
Contributing
We appreciate all contributions to LMDeploy. Please refer to CONTRIBUTING.md for the contributing guideline.
Acknowledgement
License
This project is released under the Apache 2.0 license.
1 maintainer

Metadata
1 maintainer
Release files for lmdeploy 0.0.10
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distributions (wheels)
Total release size: 641.7 MB
Release files / lmdeploy-0.0.10-cp311-cp311-win_amd64.whl
| Download URL | lmdeploy-0.0.10-cp311-cp311-win_amd64.whl |
|---|---|
| Size | 55.8 MB |
| Tags | CPython 3.11 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
bf4a1c39dbe246cbcc263c6b3b717edd035efaa1961fb4c0ac5c188d9de958ab
|
|
BLAKE2b-256 checksum How to use checksums |
60a867a0c3904b866eb7a7ee15f4e44b8785d55ede14d8d3f3f426f7a8d80112
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Release files / lmdeploy-0.0.10-cp311-cp311-manylinux2014_x86_64.whl
| Download URL | lmdeploy-0.0.10-cp311-cp311-manylinux2014_x86_64.whl |
|---|---|
| Size | 104.7 MB |
| Tags | CPython 3.11 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
ed8408bf7d3b13c981316ca1a4b0d096cabc1e92b2697cc72378e2cb5b7a1ae4
|
|
BLAKE2b-256 checksum How to use checksums |
ece38bf5ea5b110ebaf418992f7f828aa4c139f88d8be082cae41d669388d93e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Release files / lmdeploy-0.0.10-cp310-cp310-win_amd64.whl
| Download URL | lmdeploy-0.0.10-cp310-cp310-win_amd64.whl |
|---|---|
| Size | 55.8 MB |
| Tags | CPython 3.10 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
60a98f7003c7c5c21cd8438b51c77d444ba8aae08e506e615dceaa1417719498
|
|
BLAKE2b-256 checksum How to use checksums |
25ea80bc9578bc453ece91408e031d4983f88e169ab023aac126a0ab5718175c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Release files / lmdeploy-0.0.10-cp310-cp310-manylinux2014_x86_64.whl
| Download URL | lmdeploy-0.0.10-cp310-cp310-manylinux2014_x86_64.whl |
|---|---|
| Size | 104.7 MB |
| Tags | CPython 3.10 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
c3e23c4a8dca8889d5b2531392d5bd80d64f2c7f25c955f284014b28f16bfc9b
|
|
BLAKE2b-256 checksum How to use checksums |
c1f3f44acca9d2b97d3a4572314681263f9b53786de0b05c77c62743deab0d3b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Release files / lmdeploy-0.0.10-cp39-cp39-win_amd64.whl
| Download URL | lmdeploy-0.0.10-cp39-cp39-win_amd64.whl |
|---|---|
| Size | 55.8 MB |
| Tags | CPython 3.9 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
8cf57a4faae8cf8bd7d4495052bacf6031f27fc5fe619f8ae7de58471756b8e6
|
|
BLAKE2b-256 checksum How to use checksums |
e2236d414e8512a7bf94905f8f17c8b937991ff32edff6fde3dacbd65aa8f9ac
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Release files / lmdeploy-0.0.10-cp39-cp39-manylinux2014_x86_64.whl
| Download URL | lmdeploy-0.0.10-cp39-cp39-manylinux2014_x86_64.whl |
|---|---|
| Size | 104.7 MB |
| Tags | CPython 3.9 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
28ebc97762a92c709ace7b71fe30873ee6189064a61ca97ee48097e9ec1282e3
|
|
BLAKE2b-256 checksum How to use checksums |
303c6c604a8608d5fad62ff55013a3eb723677c6f74d779734565f7eb35b6ed4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Release files / lmdeploy-0.0.10-cp38-cp38-win_amd64.whl
| Download URL | lmdeploy-0.0.10-cp38-cp38-win_amd64.whl |
|---|---|
| Size | 55.8 MB |
| Tags | CPython 3.8 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
4f69189c1be3b99bf42bf6201a6c97a538ab683eb1f4c15434ed9c99a8058296
|
|
BLAKE2b-256 checksum How to use checksums |
24ab3e1357894eb8770805da931a0c05287a8ac2afd2948dd611ef2f3cfb9d24
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Release files / lmdeploy-0.0.10-cp38-cp38-manylinux2014_x86_64.whl
| Download URL | lmdeploy-0.0.10-cp38-cp38-manylinux2014_x86_64.whl |
|---|---|
| Size | 104.7 MB |
| Tags | CPython 3.8 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
98efe27e5b99416a1762a0b2e038e556a1b09e9c96bb183a655994d7459da274
|
|
BLAKE2b-256 checksum How to use checksums |
afc35b834ff970640457908a1d287e42955b5da2d804fc3e62e8c7e06c5d1de3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.8.18
|
Security for lmdeploy 0.0.10
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














