




Latest News 🎉
2026
- [2026/02] Support Qwen3.5
- [2026/02] Support vllm-project/llm-compressor 4bit symmetric/asymmetric quantization. Refer here for detailed guide
2025
- [2025/09] TurboMind supports MXFP4 on NVIDIA GPUs starting from V100, achieving 1.5x the performmance of vLLM on H800 for openai gpt-oss models!
- [2025/06] Comprehensive inference optimization for FP8 MoE Models
- [2025/06] DeepSeek PD Disaggregation deployment is now supported through integration with DLSlime and Mooncake. Huge thanks to both teams!
- [2025/04] Enhance DeepSeek inference performance by integration deepseek-ai techniques: FlashMLA, DeepGemm, DeepEP, MicroBatch and eplb
- [2025/01] Support DeepSeek V3 and R1
2024
- [2024/11] Support Mono-InternVL with PyTorch engine
- [2024/10] PyTorchEngine supports graph mode on ascend platform, doubling the inference speed
- [2024/09] LMDeploy PyTorchEngine adds support for Huawei Ascend. See supported models here
- [2024/09] LMDeploy PyTorchEngine achieves 1.3x faster on Llama3-8B inference by introducing CUDA graph
- [2024/08] LMDeploy is integrated into modelscope/swift as the default accelerator for VLMs inference
- [2024/07] Support Llama3.1 8B, 70B and its TOOLS CALLING
- [2024/07] Support InternVL2 full-series models, InternLM-XComposer2.5 and function call of InternLM2.5
- [2024/06] PyTorch engine support DeepSeek-V2 and several VLMs, such as CogVLM2, Mini-InternVL, LlaVA-Next
- [2024/05] Balance vision model when deploying VLMs with multiple GPUs
- [2024/05] Support 4-bits weight-only quantization and inference on VLMs, such as InternVL v1.5, LLaVa, InternLMXComposer2
- [2024/04] Support Llama3 and more VLMs, such as InternVL v1.1, v1.2, MiniGemini, InternLMXComposer2.
- [2024/04] TurboMind adds online int8/int4 KV cache quantization and inference for all supported devices. Refer here for detailed guide
- [2024/04] TurboMind latest upgrade boosts GQA, rocketing the internlm2-20b model inference to 16+ RPS, about 1.8x faster than vLLM.
- [2024/04] Support Qwen1.5-MOE and dbrx.
- [2024/03] Support DeepSeek-VL offline inference pipeline and serving.
- [2024/03] Support VLM offline inference pipeline and serving.
- [2024/02] Support Qwen 1.5, Gemma, Mistral, Mixtral, Deepseek-MOE and so on.
- [2024/01] OpenAOE seamless integration with LMDeploy Serving Service.
- [2024/01] Support for multi-model, multi-machine, multi-card inference services. For usage instructions, please refer to here
- [2024/01] Support PyTorch inference engine, developed entirely in Python, helping to lower the barriers for developers and enable rapid experimentation with new features and technologies.
2023
- [2023/12] Turbomind supports multimodal input.
- [2023/11] Turbomind supports loading hf model directly. Click here for details.
- [2023/11] TurboMind major upgrades, including: Paged Attention, faster attention kernels without sequence length limitation, 2x faster KV8 kernels, Split-K decoding (Flash Decoding), and W4A16 inference for sm_75
- [2023/09] TurboMind supports Qwen-14B
- [2023/09] TurboMind supports InternLM-20B
- [2023/09] TurboMind supports all features of Code Llama: code completion, infilling, chat / instruct, and python specialist. Click here for deployment guide
- [2023/09] TurboMind supports Baichuan2-7B
- [2023/08] TurboMind supports flash-attention2.
- [2023/08] TurboMind supports Qwen-7B, dynamic NTK-RoPE scaling and dynamic logN scaling
- [2023/08] TurboMind supports Windows (tp=1)
- [2023/08] TurboMind supports 4-bit inference, 2.4x faster than FP16, the fastest open-source implementation. Check this guide for detailed info
- [2023/08] LMDeploy has launched on the HuggingFace Hub, providing ready-to-use 4-bit models.
- [2023/08] LMDeploy supports 4-bit quantization using the AWQ algorithm.
- [2023/07] TurboMind supports Llama-2 70B with GQA.
- [2023/07] TurboMind supports Llama-2 7B/13B.
- [2023/07] TurboMind supports tensor-parallel inference of InternLM.
Introduction
LMDeploy is a toolkit for compressing, deploying, and serving LLM, developed by the MMRazor and MMDeploy teams. It has the following core features:
-
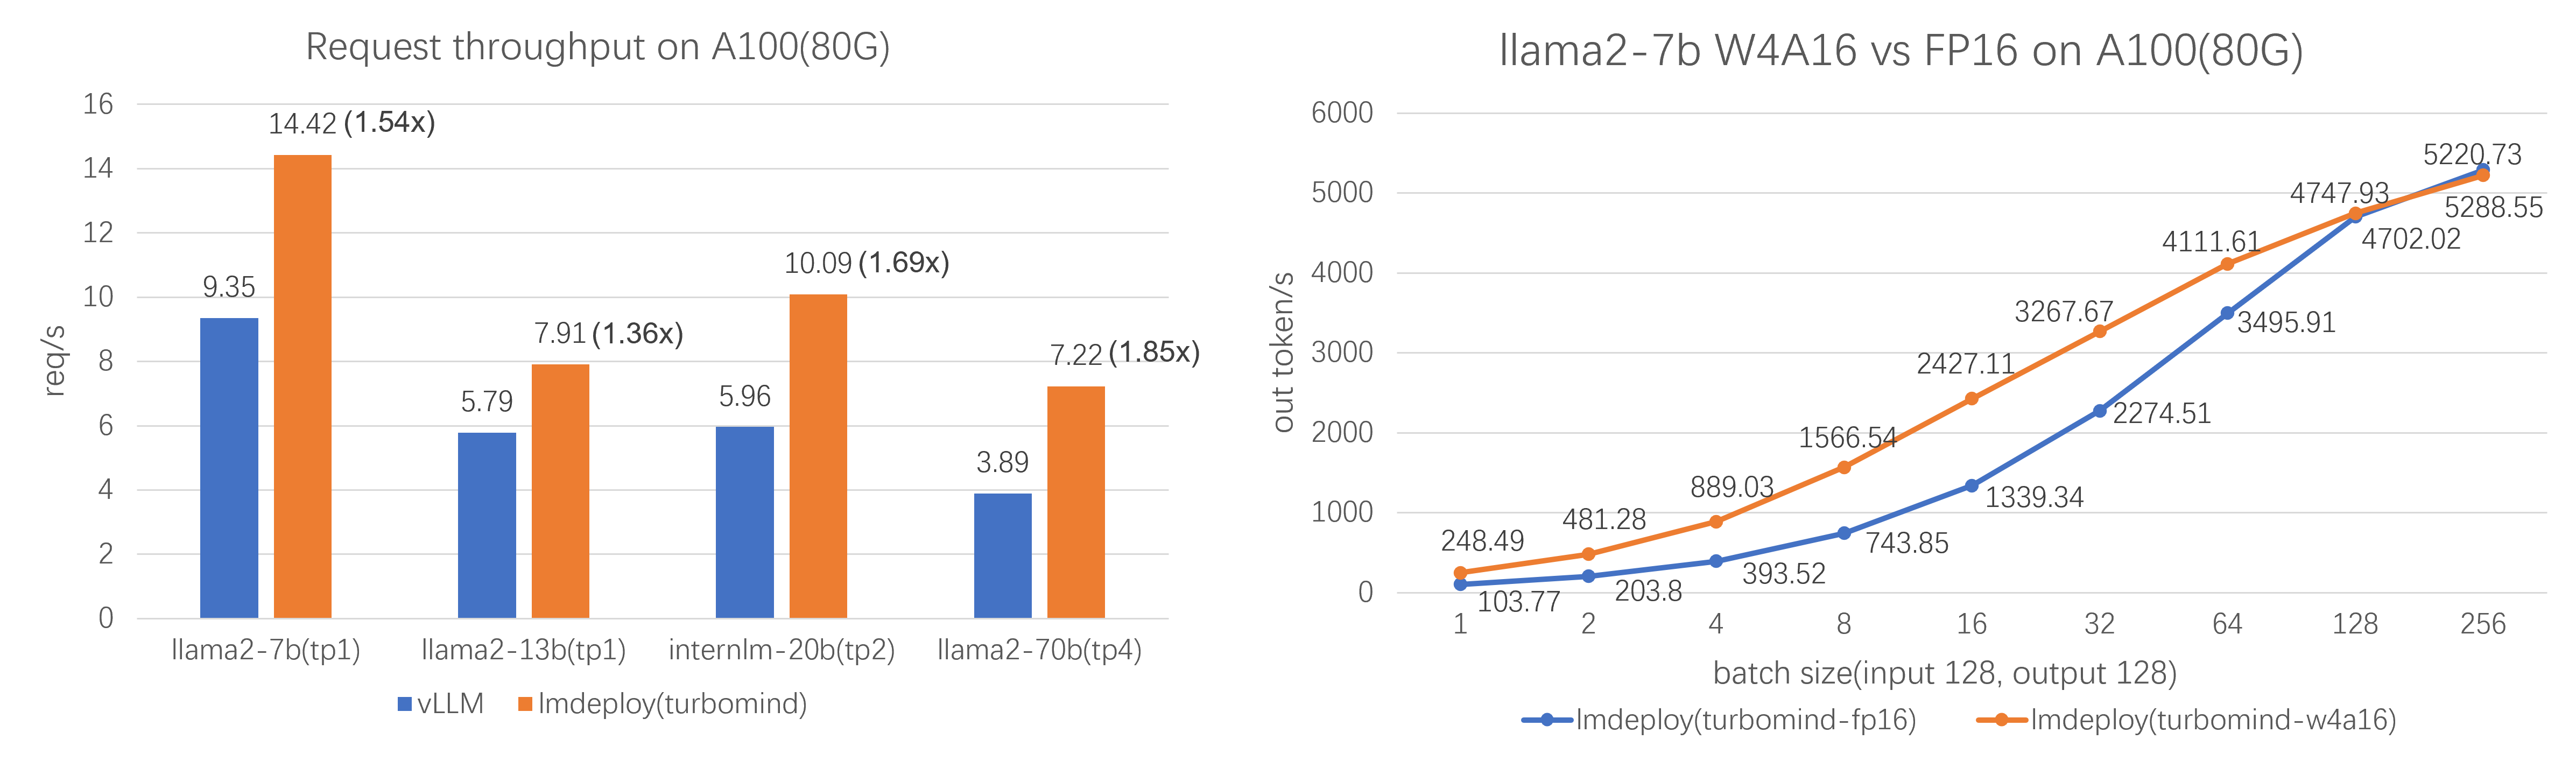
Efficient Inference: LMDeploy delivers up to 1.8x higher request throughput than vLLM, by introducing key features like persistent batch(a.k.a. continuous batching), blocked KV cache, dynamic split&fuse, tensor parallelism, high-performance CUDA kernels and so on.
-
Effective Quantization: LMDeploy supports weight-only and k/v quantization, and the 4-bit inference performance is 2.4x higher than FP16. The quantization quality has been confirmed via OpenCompass evaluation.
-
Effortless Distribution Server: Leveraging the request distribution service, LMDeploy facilitates an easy and efficient deployment of multi-model services across multiple machines and cards.
-
Excellent Compatibility: LMDeploy supports KV Cache Quant, AWQ and Automatic Prefix Caching to be used simultaneously.
Performance
Supported Models
| LLMs | VLMs |
|
|
LMDeploy has developed two inference engines - TurboMind and PyTorch, each with a different focus. The former strives for ultimate optimization of inference performance, while the latter, developed purely in Python, aims to decrease the barriers for developers.
They differ in the types of supported models and the inference data type. Please refer to this table for each engine's capability and choose the proper one that best fits your actual needs.
Quick Start 
Installation
It is recommended installing lmdeploy using pip in a conda environment (python 3.10 - 3.13):
conda create -n lmdeploy python=3.10 -y
conda activate lmdeploy
pip install lmdeploy
The default prebuilt package is compiled on CUDA 12 since v0.3.0.
For the GeForce RTX 50 series, please install the LMDeploy prebuilt package complied with CUDA 12.8
export LMDEPLOY_VERSION=0.12.2
export PYTHON_VERSION=310
pip install https://github.com/InternLM/lmdeploy/releases/download/v${LMDEPLOY_VERSION}/lmdeploy-${LMDEPLOY_VERSION}+cu128-cp${PYTHON_VERSION}-cp${PYTHON_VERSION}-manylinux2014_x86_64.whl --extra-index-url https://download.pytorch.org/whl/cu128
For more information on installing on CUDA 11+ platform, or for instructions on building from source, please refer to the installation guide.
Offline Batch Inference
import lmdeploy
with lmdeploy.pipeline("internlm/internlm3-8b-instruct") as pipe:
    response = pipe(["Hi, pls intro yourself", "Shanghai is"])
    print(response)
[!NOTE] By default, LMDeploy downloads model from HuggingFace. If you would like to use models from ModelScope, please install ModelScope by
pip install modelscopeand set the environment variable:
export LMDEPLOY_USE_MODELSCOPE=TrueIf you would like to use models from openMind Hub, please install openMind Hub by
pip install openmind_huband set the environment variable:
export LMDEPLOY_USE_OPENMIND_HUB=True
For more information about inference pipeline, please refer to here.
Tutorials
Please review getting_started section for the basic usage of LMDeploy.
For detailed user guides and advanced guides, please refer to our tutorials:
- User Guide
- Advance Guide
Third-party projects
-
Deploying LLMs offline on the NVIDIA Jetson platform by LMDeploy: LMDeploy-Jetson
-
Example project for deploying LLMs using LMDeploy and BentoML: BentoLMDeploy
Contributing
We appreciate all contributions to LMDeploy. Please refer to CONTRIBUTING.md for the contributing guideline.
Acknowledgement
Citation
@misc{2023lmdeploy,
    title={LMDeploy: A Toolkit for Compressing, Deploying, and Serving LLM},
    author={LMDeploy Contributors},
    howpublished = {\url{https://github.com/InternLM/lmdeploy}},
    year={2023}
}
@article{zhang2025efficient,
  title={Efficient Mixed-Precision Large Language Model Inference with TurboMind},
  author={Zhang, Li and Jiang, Youhe and He, Guoliang and Chen, Xin and Lv, Han and Yao, Qian and Fu, Fangcheng and Chen, Kai},
  journal={arXiv preprint arXiv:2508.15601},
  year={2025}
}
License
This project is released under the Apache 2.0 license.
1 maintainer

Metadata
1 maintainer
Release files for lmdeploy 0.12.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distributions (wheels)
| File | Actions Reset | |||
|---|---|---|---|---|
| lmdeploy-0.12.2-cp311-cp311-win_amd64.whl | CPython 3.11 | CPython 3.11 | Windows x86-64 | Details for lmdeploy-0.12.2-cp311-cp311-win_amd64.whl |
| lmdeploy-0.12.2-cp311-cp311-manylinux2014_x86_64.whl | CPython 3.11 | CPython 3.11 | Linux glibc 2.17+ x86-64 | Details for lmdeploy-0.12.2-cp311-cp311-manylinux2014_x86_64.whl |
| lmdeploy-0.12.2-cp310-cp310-win_amd64.whl | CPython 3.10 | CPython 3.10 | Windows x86-64 | Details for lmdeploy-0.12.2-cp310-cp310-win_amd64.whl |
| lmdeploy-0.12.2-cp310-cp310-manylinux2014_x86_64.whl | CPython 3.10 | CPython 3.10 | Linux glibc 2.17+ x86-64 | Details for lmdeploy-0.12.2-cp310-cp310-manylinux2014_x86_64.whl |
Total release size: 284.1 MB
Release files / lmdeploy-0.12.2-cp311-cp311-win_amd64.whl
| Download URL | lmdeploy-0.12.2-cp311-cp311-win_amd64.whl |
|---|---|
| Size | 36.1 MB |
| Tags | CPython 3.11 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
da970e511a091e4f720deba2398dee3be21295e7234b9ca6b75af48e5e2e4ce8
|
|
BLAKE2b-256 checksum How to use checksums |
1f2a2409943e62bf3caa3b67de1ed553c3b7de7fc0f18c8451ad9329db9a6f96
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.10.20
|
Release files / lmdeploy-0.12.2-cp311-cp311-manylinux2014_x86_64.whl
| Download URL | lmdeploy-0.12.2-cp311-cp311-manylinux2014_x86_64.whl |
|---|---|
| Size | 106.0 MB |
| Tags | CPython 3.11 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
00ac3cb133ebfd367de8fcc08708dfe1f994cc521eddf7cfab1524c54fcd190f
|
|
BLAKE2b-256 checksum How to use checksums |
63d495afed9b906648dae920576b8e7b22ed30306d6a39430a57ab41f007d15f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.10.20
|
Release files / lmdeploy-0.12.2-cp310-cp310-win_amd64.whl
| Download URL | lmdeploy-0.12.2-cp310-cp310-win_amd64.whl |
|---|---|
| Size | 36.1 MB |
| Tags | CPython 3.10 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
031e46d9be72c98d58dde417d18e1f691fb55b2577f651303f5c8f0918cfc019
|
|
BLAKE2b-256 checksum How to use checksums |
2f6f23db032f01e82810b0b8d1c05a396060e05c2898705fe96c2ccb40d68595
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.10.20
|
Release files / lmdeploy-0.12.2-cp310-cp310-manylinux2014_x86_64.whl
| Download URL | lmdeploy-0.12.2-cp310-cp310-manylinux2014_x86_64.whl |
|---|---|
| Size | 105.9 MB |
| Tags | CPython 3.10 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
20a50c973671e74d9db49cf62435dae1b276d83c2e08754f178464d4fcf78d29
|
|
BLAKE2b-256 checksum How to use checksums |
169913fda9a4dc643f4280e120dfda776f92568bc06d9d122b89dc3f8811af64
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.10.20
|
Security for lmdeploy 0.12.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














