


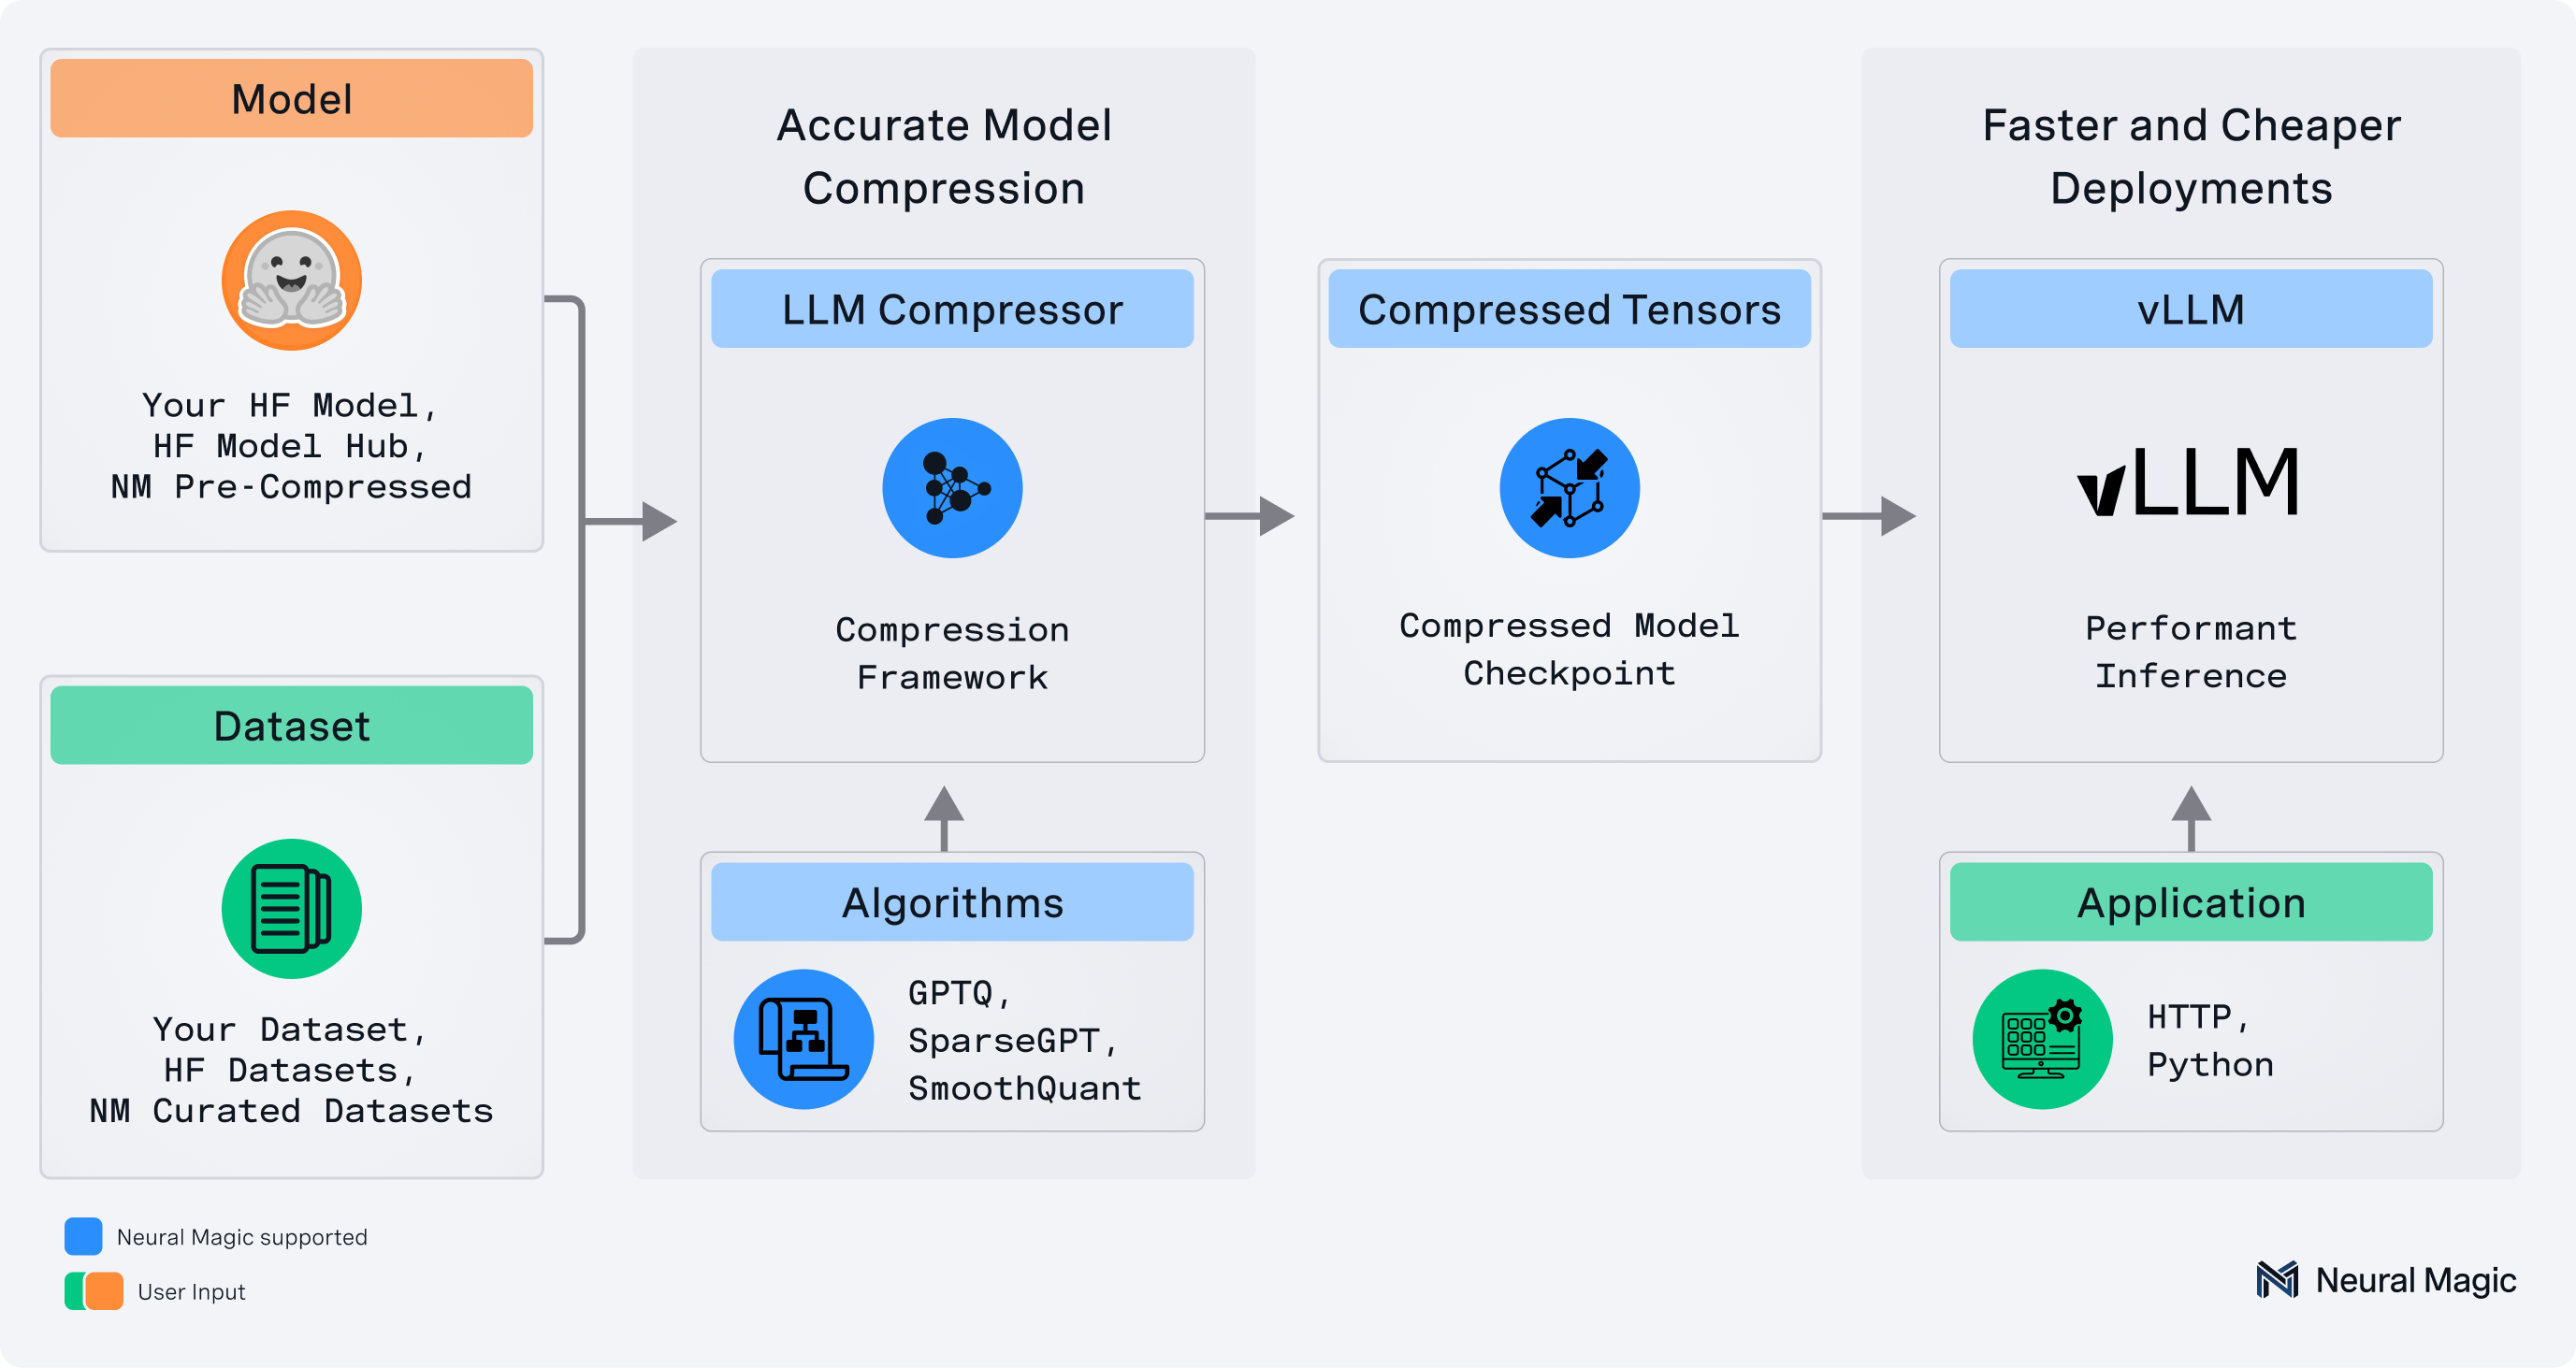
llmcompressor is the fast, efficient, and easy-to-use library for optimizing models for deployment with vLLM, including:
- Comprehensive set of quantization algorithms and transforms for weight, activation, KV cache, and attention quantization
- Seamless integration with Hugging Face models and repositories
- Models saved in the
compressed-tensorsformat, compatible with vLLM - DDP and disk offloading support for compressing very large models with hardware efficiency
✨ Read the announcement blog here! ✨
📊 Help us improve by taking our 1-minute user survey
💬 Join us on the vLLM Community Slack and share your questions, thoughts, or ideas in:
#sig-quantization#llm-compressor
🚀 What's New!
Big updates have landed in LLM Compressor! To get a more in-depth look, check out the LLM Compressor overview.
Since the v0.13.0 release, a number of meaningful improvements have landed:
- Batched GPTQ quantization with a new Triton GPTQ kernel: GPTQ now ships a Triton-based quantization kernel (~15x faster than the previous eager path) together with the ability to batch layers that share the same shape (up to ~1.67x per batch, roughly ~30x end-to-end on MoE workloads). Activation-order (act-order) calibration is supported, hessian offloading has been removed, and the remaining eager path was also sped up by 1.5-2x on its own.
- Expanded MSE and iMatrix observers for FP4: The MSE observer and the iMatrix observer gained a grid-search expansion factor that makes the search a strict superset of fouroversix (which chooses between the full
absmaxandabsmax * 1.5scales for FP4 blocks). These observers outperform GPTQ for NVFP4 on average across our internal perplexity benchmarks. - Triton grid-search kernel for the MSE observer: A Triton kernel now performs the MSE observer's scale grid search using buffered per-qparam patience and adaptive 512-value tiling. It reaches bitwise parity with the eager path when configured for full evaluation, supports INT, FP4, FP8, and FP16/BF16 (with E8M0 scales), and defaults
triton_error_bufferto 100% for FP4 and 30% otherwise.
Model highlights
The Red Hat AI team has been using LLM Compressor to produce a fresh batch of production-ready quantized checkpoints:
- GLM-5.3 MXFP4: An MXFP4 quantized checkpoint for GLM-5.3. The linear operators within the transformer blocks are quantized to MXFP4, while the MoE router, embeddings, DSA indexer, and output head are kept in their original precision to maintain accuracy recovery.
- GLM-5.3-Flash NVFP4: An NVFP4 quantized checkpoint for GLM-5.3-Flash. The expert layers are quantized to NVFP4, while the MTP (multi-token prediction) layers are quantized to per-block FP8.
- Qwen3.8-Flash-Next NVFP4: An NVFP4 quantized checkpoint for Qwen3.8-Flash-Next.
- Qwen3.8-27B INT4, NVFP4, and MXFP4: 4-bit quantized checkpoints for Qwen3.8-27B across three formats — INT4, NVFP4, and MXFP4 — covering a range of hardware and accuracy trade-offs.
- Nemotron 3.5 Lightning FP8: An FP8 quantized checkpoint for Nemotron 3.5 Lightning, created using GPTQ-based FP8 quantization.
- Qwen3.8-2.4T-A95B NVFP4, NVFP4+FP8, and REAP+NVFP4: NVFP4 and NVFP4+FP8 quantized checkpoints for Qwen3.8-2.4T-A95B, along with
REAP-25andREAP-50variants that combine REAP expert pruning (25% and 50% of the least-salient experts pruned prior to quantization) with NVFP4, further reducing VRAM requirements while maintaining accuracy recovery. - Muse-Glimmer-30B FP8, NVFP4, and INT4: FP8, NVFP4, and INT4 checkpoints for Muse-Glimmer-30B, enabling single-GPU deployment of this multimodal model.
- Kimi-K3 NVFP4 and FP8: NVFP4 and per-block FP8 quantized checkpoints for Kimi-K3. A native
KimiK3ForConditionalGenerationmodel definition is now shipped in the library to support quantizing this architecture. - Hy3 NVFP4+FP8: A quantized checkpoint for Hy3 combining NVFP4 quantization of the MoE layers with FP8 quantization of the attention layers, significantly reducing VRAM requirements while maintaining accuracy recovery.
- GLM-5.2 NVFP4+FP8: Mixed-precision quantized checkpoints for GLM-5.2, created with DDP + disk offloading in under 2 hours. NVFP4 quantization of the MoE layers and FP8 quantization of the attention layers reduces the model size by >70% while maintaining state-of-the-art accuracy recovery on GPQA.
Supported Precisions and Types
- Activation Quantization: W8A8 (int8 and fp8), W4AFP8, Microscale (NVFP4, MXFP4, MXFP8)
- Mixed Precision: W4A16, W8A16, MXFP8A16, MXFP4A16, NVFP4A16
- Attention and KV Cache Quantization: FP8, NVFP4
- Low/Arbitrary-bit Quantization: WNA4, WNA8, WNA16
Supported Algorithms
- Simple PTQ
- GPTQ
- AWQ
- SmoothQuant
- AutoRound
- Rotation-based (SpinQuant, QuIP)
- REAP expert pruning
Quantizing your model, step-by-step
Please refer to our step-by-step compression guide for detailed information about selecting quantization schemes, algorithms, and their use cases.
Additional information about LLM Compressor functionality is also available in our User Guides and FAQ.
Installation
pip install llmcompressor
Get Started
End-to-End Examples
Applying quantization with llmcompressor:
Weight and Activation Quantization
- Activation quantization to
int8 - Activation quantization to
fp8 - Activation quantization to MXFP8
- Activation quantization to
fp4(NVFP4) - Activation quantization to
fp4(MXFP4) - Activation quantization to
fp4using AutoRound - Activation quantization to
fp8and weight quantization toint4
Weight Only Quantization
- Weight only quantization to
fp4(NVFP4 format) - Weight only quantization to
fp4(MXFP4 format) - Weight only quantization to
int4using GPTQ - Weight only quantization to
int4using AWQ - Weight only quantization with AutoRound (
wNa16)
Attention and KV Cache Quantization
- KV Cache quantization to
fp8 - KV Cache quantization to
fp8using per-head - Attention quantization to
fp8 - Attention quantization to
NVFP4with SpinQuant (experimental)
Architecture-Specific Quantization
Non-Uniform Quantization
Big Model Quantization Support
Model-Free Definition Quantization
DDP Quantization
Quick Tour
Let's quantize Qwen3-30B-A3B with FP8 weights and activations using the Round-to-Nearest algorithm.
Note that the model can be swapped for a local or remote HF-compatible checkpoint and the recipe may be changed to target different quantization algorithms or formats.
Apply Quantization
Quantization is applied by selecting an algorithm and calling the oneshot API.
from compressed_tensors.offload import dispatch_model
from transformers import AutoModelForCausalLM, AutoTokenizer

from llmcompressor import oneshot
from llmcompressor.modifiers.quantization import QuantizationModifier

MODEL_ID = "Qwen/Qwen3-30B-A3B"

# Load model.
model = AutoModelForCausalLM.from_pretrained(MODEL_ID)
tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)

# Configure the quantization algorithm and scheme.
# In this case, we:
#   * quantize the weights to FP8 using RTN with block_size 128
#   * quantize the activations dynamically to FP8 during inference
recipe = QuantizationModifier(
    targets="Linear",
    scheme="FP8_BLOCK",
    ignore=["lm_head", "re:.*mlp.gate$"],
)

# Apply quantization.
oneshot(model=model, recipe=recipe)

# Confirm generations of the quantized model look sane.
print("========== SAMPLE GENERATION ==============")
dispatch_model(model)
input_ids = tokenizer("Hello my name is", return_tensors="pt").input_ids.to(
    model.device
)
output = model.generate(input_ids, max_new_tokens=20)
print(tokenizer.decode(output[0]))
print("==========================================")

# Save to disk in compressed-tensors format.
SAVE_DIR = MODEL_ID.split("/")[1] + "-FP8-BLOCK"
model.save_pretrained(SAVE_DIR)
tokenizer.save_pretrained(SAVE_DIR)
Inference with vLLM
The checkpoints created by llmcompressor can be loaded and run in vllm:
Install:
pip install vllm
Run:
from vllm import LLM
model = LLM("Qwen/Qwen3-30B-A3B-FP8-BLOCK")
output = model.generate("My name is")
Questions / Contribution
- If you have any questions or requests open an issue and we will add an example or documentation.
- We appreciate contributions to the code, examples, integrations, and documentation as well as bug reports and feature requests! Learn how here.
Citation
If you find LLM Compressor useful in your research or projects, please consider citing it:
@software{llmcompressor2024,
    title={{LLM Compressor}},
    author={Red Hat AI and vLLM Project},
    year={2024},
    month={8},
    url={https://github.com/vllm-project/llm-compressor},
}
1 maintainer

Metadata
1 maintainer
Release files for llmcompressor 0.14.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| llmcompressor-0.14.0.1.tar.gz | 3.1 MB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| llmcompressor-0.14.0.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 3.5 MB
Release files / llmcompressor-0.14.0.1.tar.gz
| Download URL | llmcompressor-0.14.0.1.tar.gz |
|---|---|
| Size | 3.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
073d24101072675c701a646d3aa6daa02d99d501e1a851b975cfd06319eae8b1
|
|
BLAKE2b-256 checksum How to use checksums |
3aa87da1d0c558c45291900ce28420b9cad7cc15d95e2f54e5bce3340f7db8f4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 22, 2026.
Transparency logRelease files / llmcompressor-0.14.0.1-py3-none-any.whl
| Download URL | llmcompressor-0.14.0.1-py3-none-any.whl |
|---|---|
| Size | 394.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fedc804a45bf3e353b84b8181147474c324ffba3356c9ecebceae29dfc3c5f00
|
|
BLAKE2b-256 checksum How to use checksums |
d650acce35ddccaf7571ccb87c947e395905a373a3f64dfe17ede0aa064867e1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 22, 2026.
Transparency logSecurity for llmcompressor 0.14.0.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for llmcompressor-0.14.0.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 22, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














