
This release is a pre-release and may not be stable for production use.
 LLM Compressor
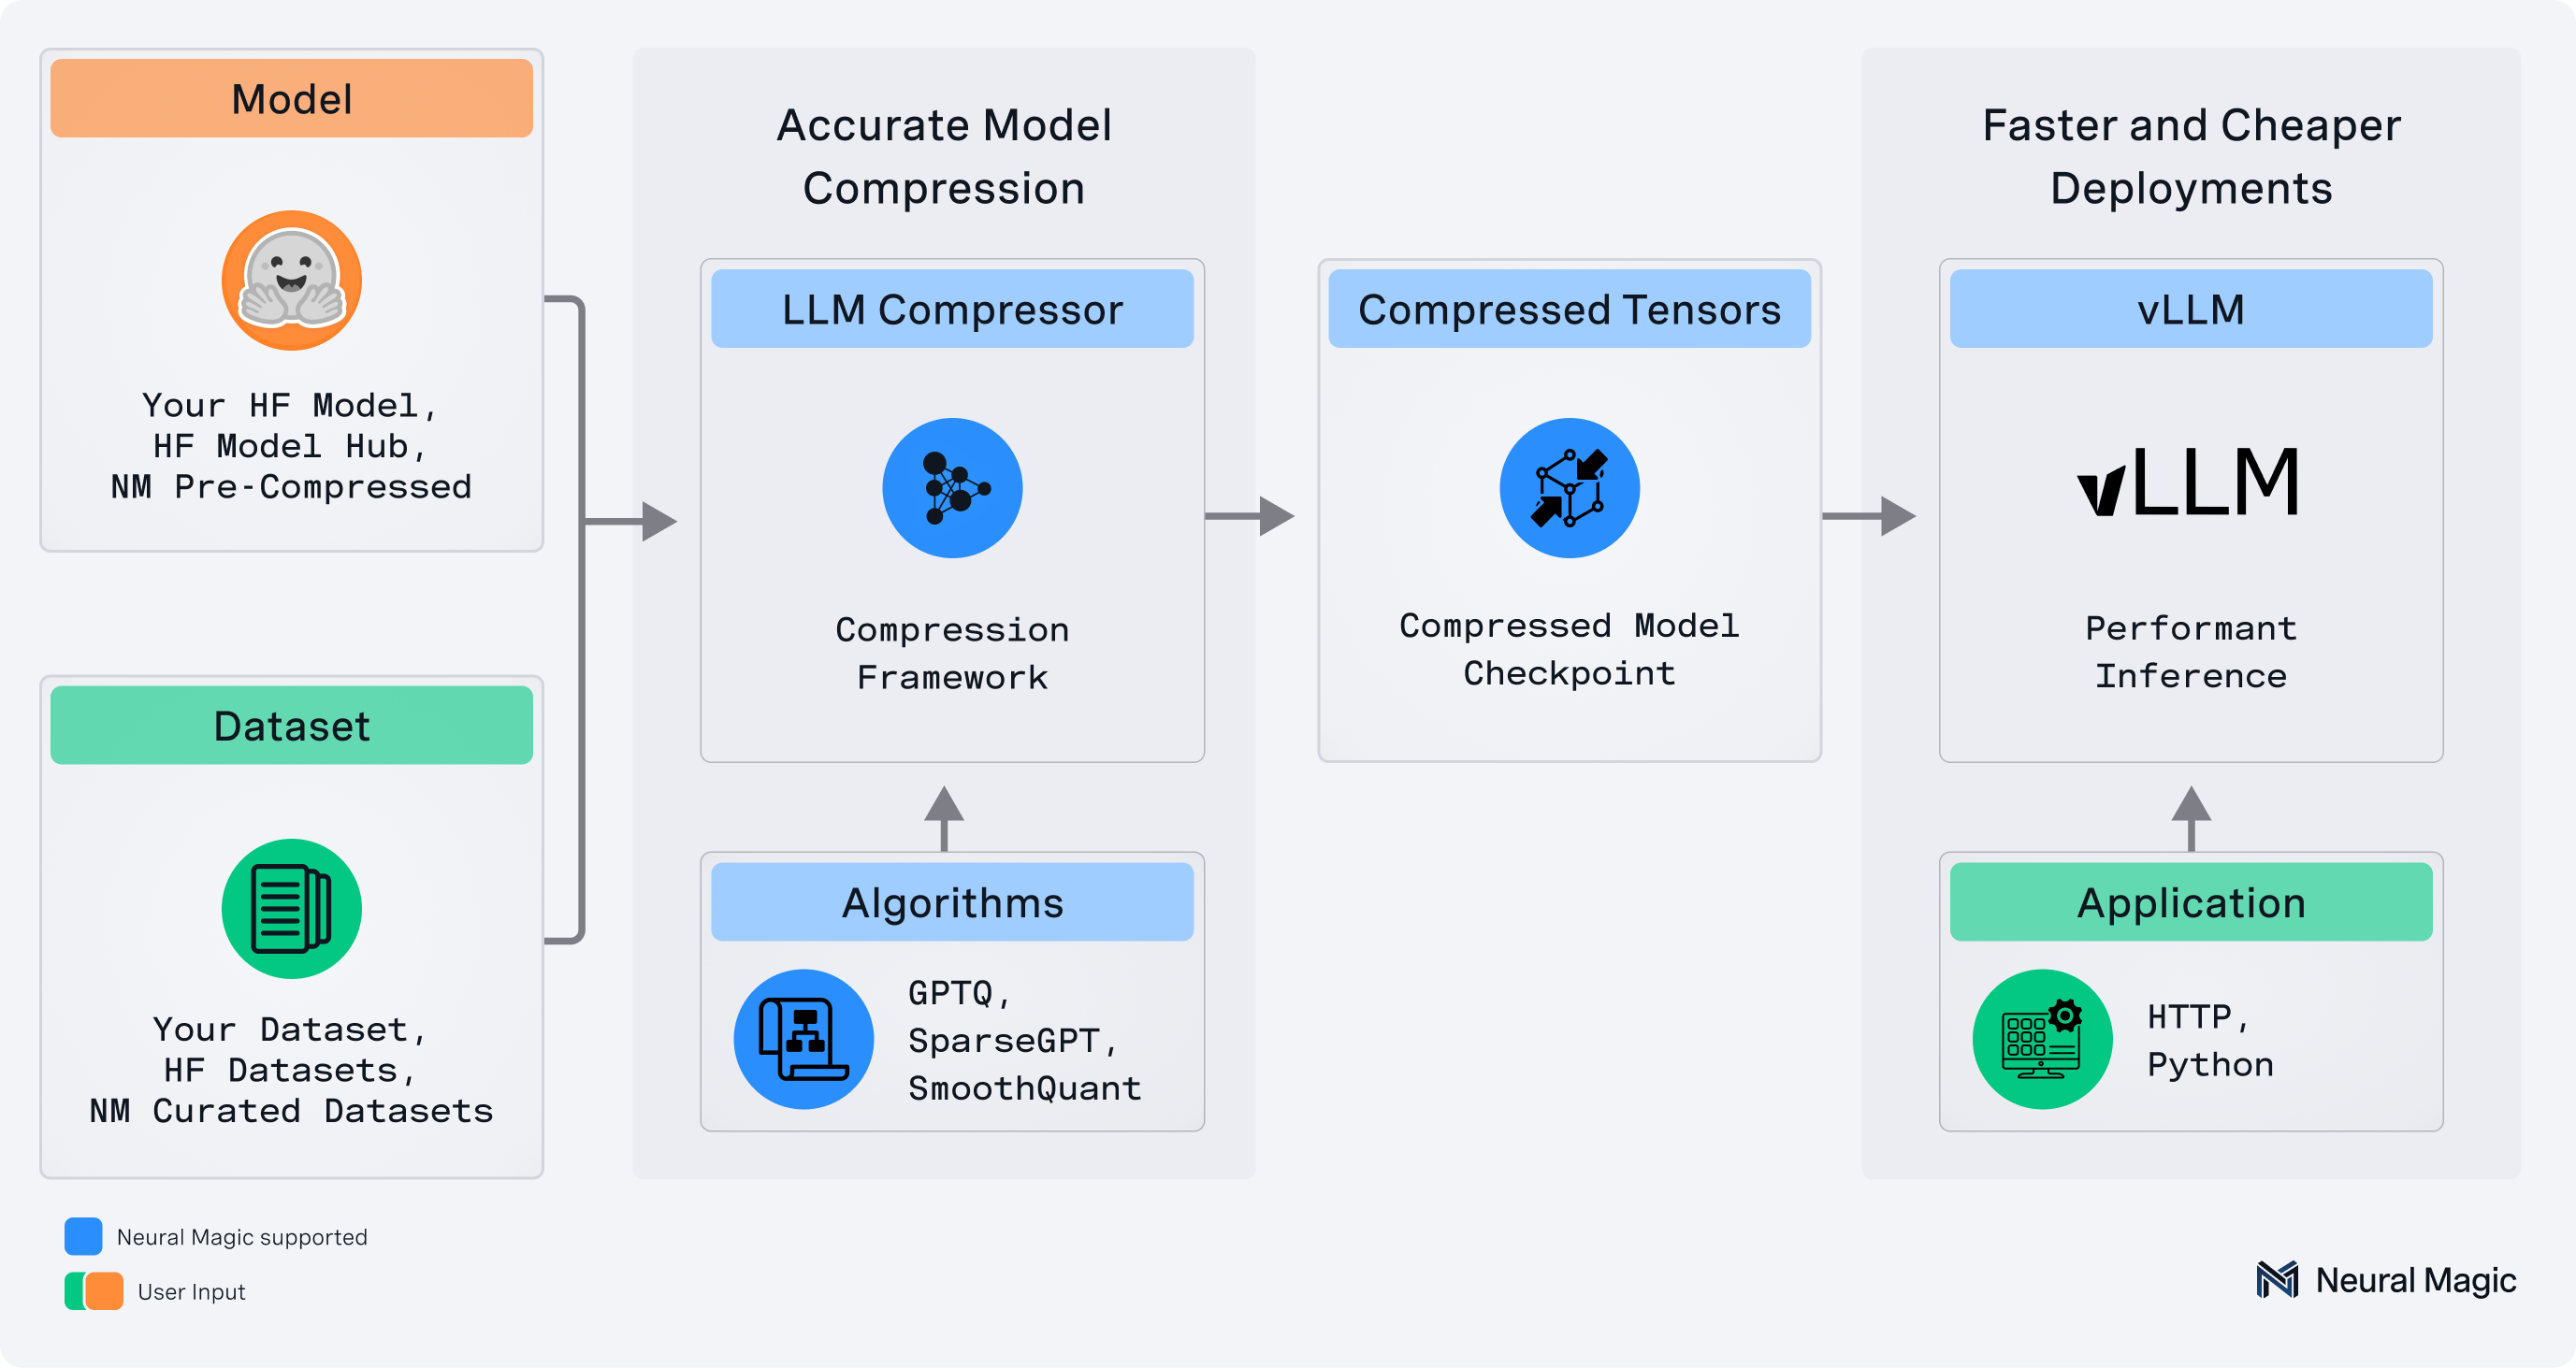
llmcompressor is an easy-to-use library for optimizing models for deployment with vllm, including:
- Comprehensive set of quantization algorithms for weight-only and activation quantization
- Seamless integration with Hugging Face models and repositories
safetensors-based file format compatible withvllm- Large model support via
accelerate
✨ Read the announcement blog here! ✨
Supported Formats
- Activation Quantization: W8A8 (int8 and fp8)
- Mixed Precision: W4A16, W8A16
- 2:4 Semi-structured and Unstructured Sparsity
Supported Algorithms
- Simple PTQ
- GPTQ
- AWQ
- SmoothQuant
- SparseGPT
When to Use Which Optimization
Please refer to docs/schemes.md for detailed information about available optimization schemes and their use cases.
Installation
pip install llmcompressor
Get Started
End-to-End Examples
Applying quantization with llmcompressor:
- Activation quantization to
int8 - Activation quantization to
fp8 - Weight only quantization to
int4using GPTQ - Weight only quantization to
int4using AWQ - Quantizing MoE LLMs
- Quantizing Vision-Language Models
- Quantizing Audio-Language Models
User Guides
Deep dives into advanced usage of llmcompressor:
Quick Tour
Let's quantize TinyLlama with 8 bit weights and activations using the GPTQ and SmoothQuant algorithms.
Note that the model can be swapped for a local or remote HF-compatible checkpoint and the recipe may be changed to target different quantization algorithms or formats.
Apply Quantization
Quantization is applied by selecting an algorithm and calling the oneshot API.
from llmcompressor.modifiers.smoothquant import SmoothQuantModifier
from llmcompressor.modifiers.quantization import GPTQModifier
from llmcompressor import oneshot

# Select quantization algorithm. In this case, we:
#   * apply SmoothQuant to make the activations easier to quantize
#   * quantize the weights to int8 with GPTQ (static per channel)
#   * quantize the activations to int8 (dynamic per token)
recipe = [
    SmoothQuantModifier(smoothing_strength=0.8),
    GPTQModifier(scheme="W8A8", targets="Linear", ignore=["lm_head"]),
]

# Apply quantization using the built in open_platypus dataset.
#   * See examples for demos showing how to pass a custom calibration set
oneshot(
    model="TinyLlama/TinyLlama-1.1B-Chat-v1.0",
    dataset="open_platypus",
    recipe=recipe,
    output_dir="TinyLlama-1.1B-Chat-v1.0-INT8",
    max_seq_length=2048,
    num_calibration_samples=512,
)
Inference with vLLM
The checkpoints created by llmcompressor can be loaded and run in vllm:
Install:
pip install vllm
Run:
from vllm import LLM
model = LLM("TinyLlama-1.1B-Chat-v1.0-INT8")
output = model.generate("My name is")
Questions / Contribution
- If you have any questions or requests open an issue and we will add an example or documentation.
- We appreciate contributions to the code, examples, integrations, and documentation as well as bug reports and feature requests! Learn how here.
1 maintainer

Metadata
1 maintainer
Release files for llmcompressor 0.5.2a20250430
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| llmcompressor-0.5.2a20250430.tar.gz | 325.3 kB | Without provenance | Details for llmcompressor-0.5.2a20250430.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| llmcompressor-0.5.2a20250430-py3-none-any.whl | Python 3 | none | any | Details for llmcompressor-0.5.2a20250430-py3-none-any.whl |
Total release size: 598.7 kB
Release files / llmcompressor-0.5.2a20250430.tar.gz
| Download URL | llmcompressor-0.5.2a20250430.tar.gz |
|---|---|
| Size | 325.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cb34c0b5adbbee722046ae4a9aa5d0304380e308664f2812157a2c4a240f9565
|
|
BLAKE2b-256 checksum How to use checksums |
b2ad4bb67078742efc822a017c91da1f3f8f26705c0c5d99bae9f0540ec93a45
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.12
|
Release files / llmcompressor-0.5.2a20250430-py3-none-any.whl
| Download URL | llmcompressor-0.5.2a20250430-py3-none-any.whl |
|---|---|
| Size | 273.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9c75d1399535da2eeb486e5a72a3ced1971aa7baacebcae8da0a031052cad7e6
|
|
BLAKE2b-256 checksum How to use checksums |
46f2d75da667a2c7f0bd4dfbf5df4a7b2805bbdf30714dbea8e6b11e927d067a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.12
|
Security for llmcompressor 0.5.2a20250430
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














