
This release is a pre-release and may not be stable for production use.
 LLM Compressor
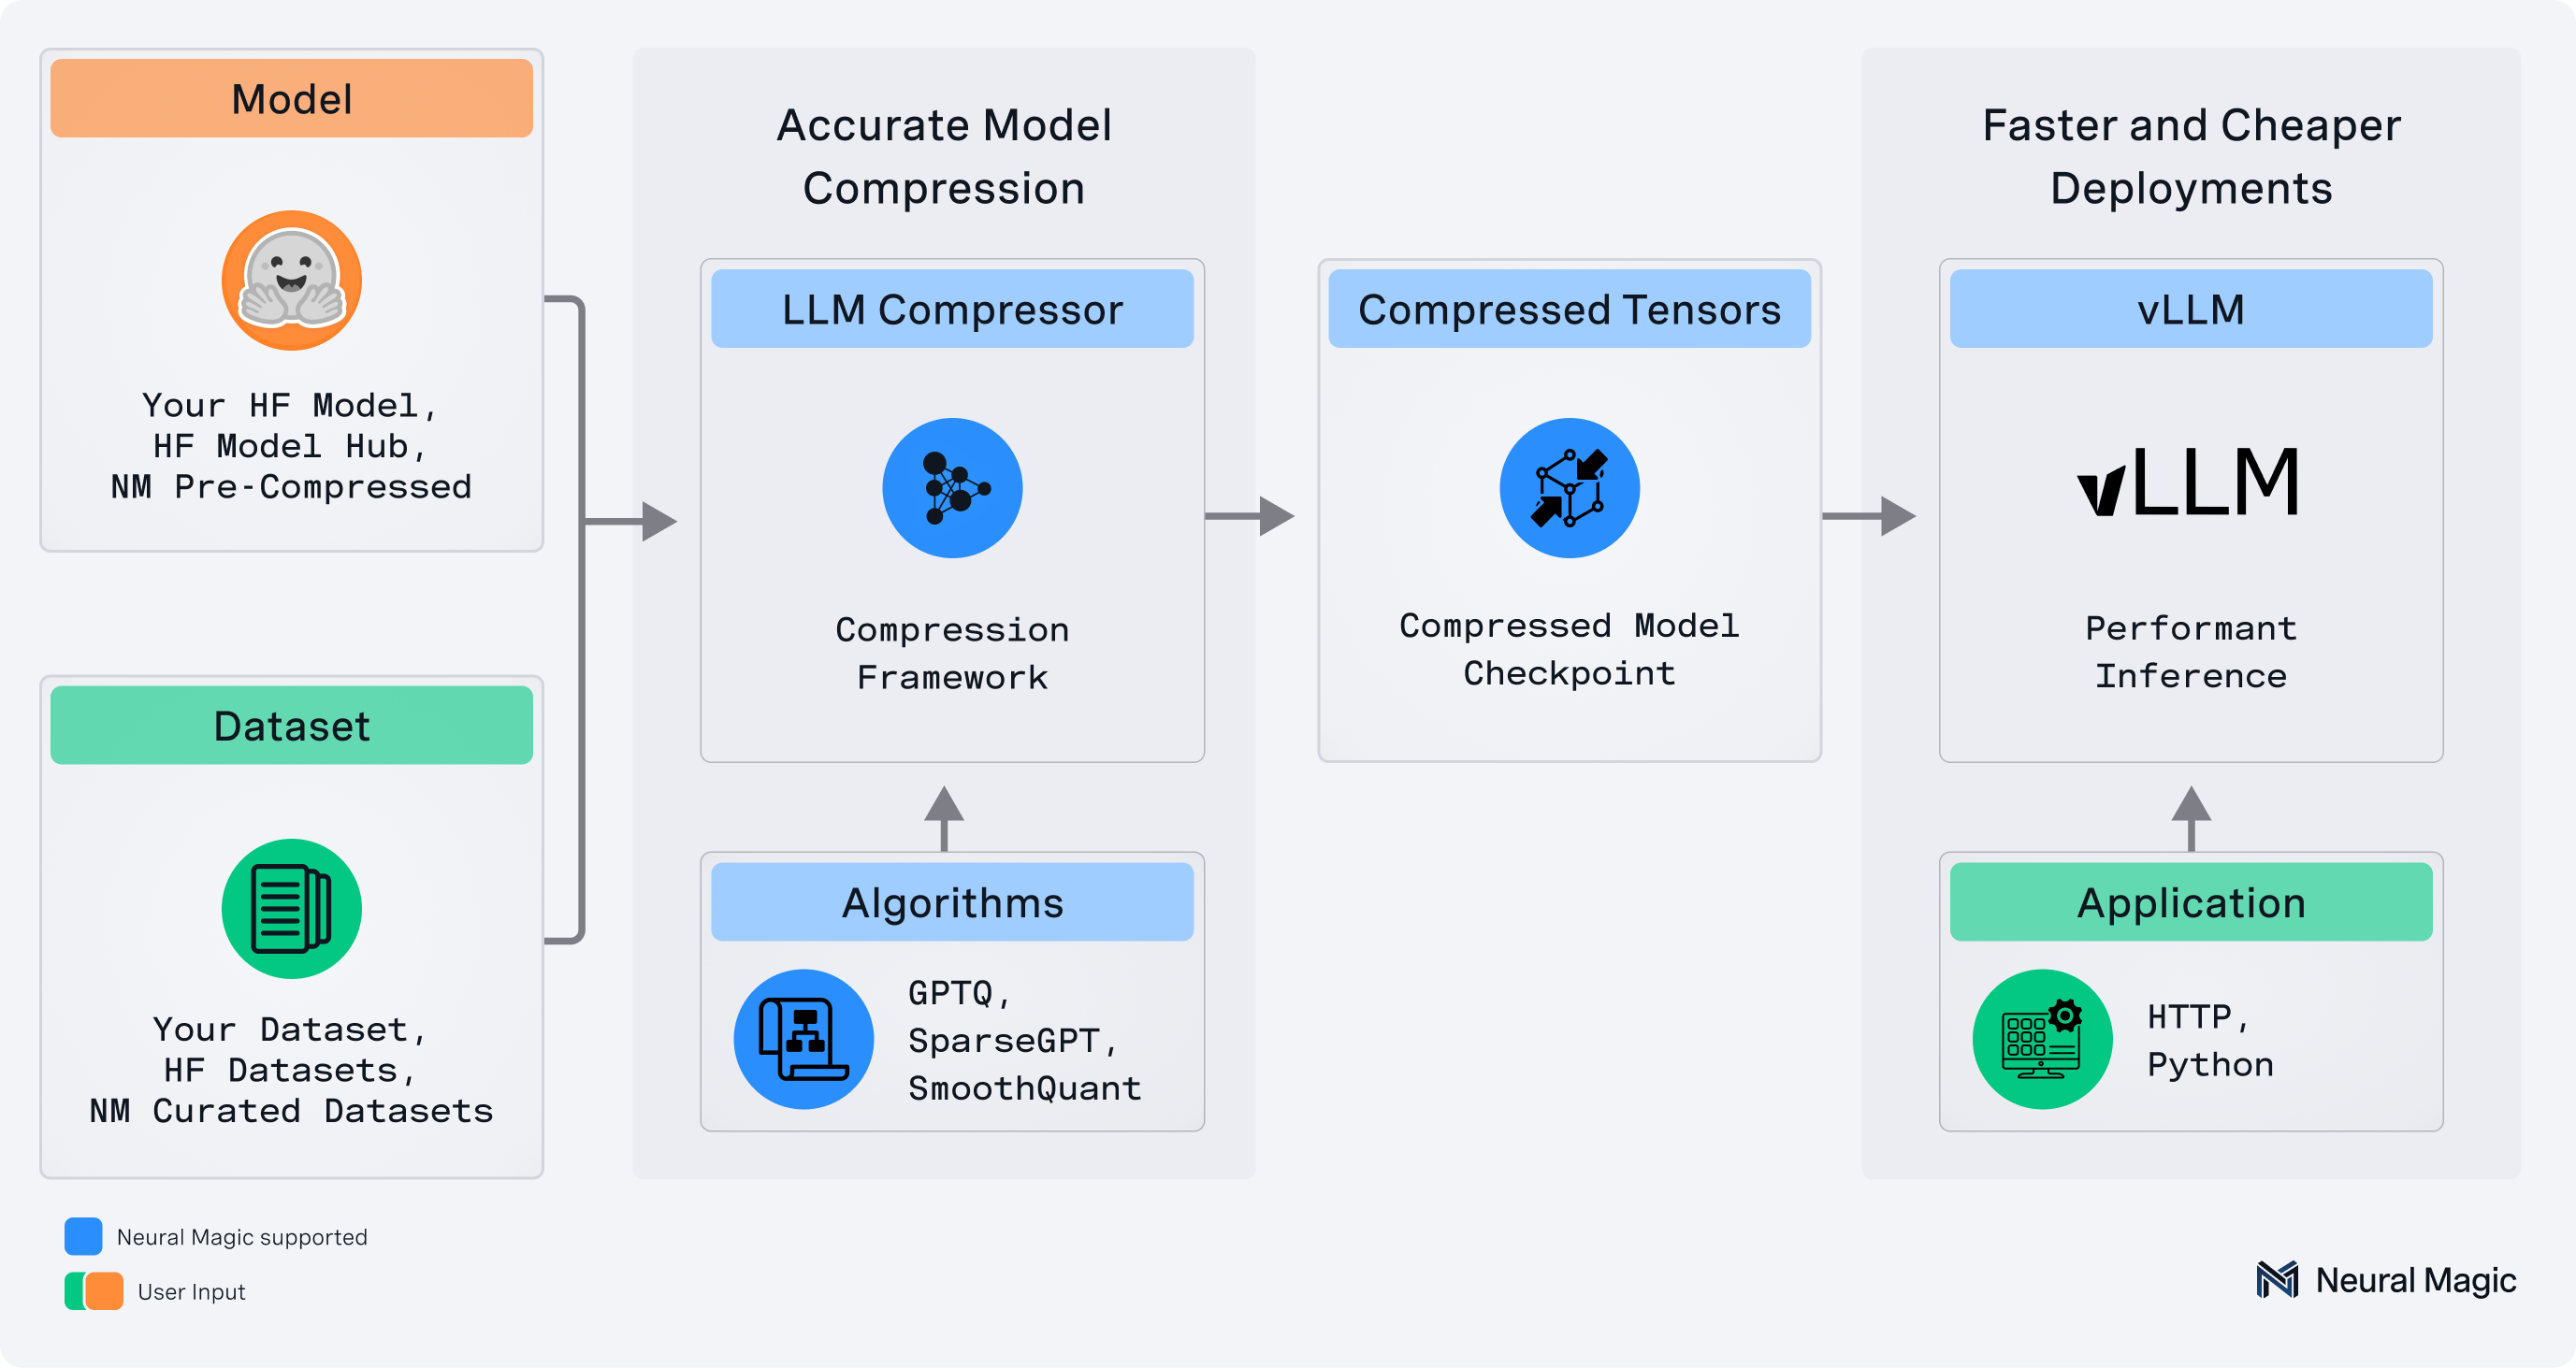
llmcompressor is an easy-to-use library for optimizing models for deployment with vllm, including:
- Comprehensive set of quantization algorithms for weight-only and activation quantization
- Seamless integration with Hugging Face models and repositories
safetensors-based file format compatible withvllm- Large model support via
accelerate
✨ Read the announcement blog here! ✨
Supported Formats
- Activation Quantization: W8A8 (int8 and fp8)
- Mixed Precision: W4A16, W8A16
- 2:4 Semi-structured and Unstructured Sparsity
Supported Algorithms
- Simple PTQ
- GPTQ
- AWQ
- SmoothQuant
- SparseGPT
When to Use Which Optimization
Please refer to docs/schemes.md for detailed information about available optimization schemes and their use cases.
Installation
pip install llmcompressor
Get Started
End-to-End Examples
Applying quantization with llmcompressor:
- Activation quantization to
int8 - Activation quantization to
fp8 - Weight only quantization to
int4using GPTQ - Weight only quantization to
int4using AWQ - Quantizing MoE LLMs
- Quantizing Vision-Language Models
- Quantizing Audio-Language Models
User Guides
Deep dives into advanced usage of llmcompressor:
Quick Tour
Let's quantize TinyLlama with 8 bit weights and activations using the GPTQ and SmoothQuant algorithms.
Note that the model can be swapped for a local or remote HF-compatible checkpoint and the recipe may be changed to target different quantization algorithms or formats.
Apply Quantization
Quantization is applied by selecting an algorithm and calling the oneshot API.
from llmcompressor.modifiers.smoothquant import SmoothQuantModifier
from llmcompressor.modifiers.quantization import GPTQModifier
from llmcompressor import oneshot

# Select quantization algorithm. In this case, we:
#   * apply SmoothQuant to make the activations easier to quantize
#   * quantize the weights to int8 with GPTQ (static per channel)
#   * quantize the activations to int8 (dynamic per token)
recipe = [
    SmoothQuantModifier(smoothing_strength=0.8),
    GPTQModifier(scheme="W8A8", targets="Linear", ignore=["lm_head"]),
]

# Apply quantization using the built in open_platypus dataset.
#   * See examples for demos showing how to pass a custom calibration set
oneshot(
    model="TinyLlama/TinyLlama-1.1B-Chat-v1.0",
    dataset="open_platypus",
    recipe=recipe,
    output_dir="TinyLlama-1.1B-Chat-v1.0-INT8",
    max_seq_length=2048,
    num_calibration_samples=512,
)
Inference with vLLM
The checkpoints created by llmcompressor can be loaded and run in vllm:
Install:
pip install vllm
Run:
from vllm import LLM
model = LLM("TinyLlama-1.1B-Chat-v1.0-INT8")
output = model.generate("My name is")
Questions / Contribution
- If you have any questions or requests open an issue and we will add an example or documentation.
- We appreciate contributions to the code, examples, integrations, and documentation as well as bug reports and feature requests! Learn how here.
1 maintainer

Release files for llmcompressor 0.5.2a20250501
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| llmcompressor-0.5.2a20250501.tar.gz | 323.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| llmcompressor-0.5.2a20250501-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 597.0 kB
Release files / llmcompressor-0.5.2a20250501.tar.gz
| Download URL | llmcompressor-0.5.2a20250501.tar.gz |
|---|---|
| Size | 323.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f2897d23afcd0445602a855b05ff70c87645996a63b085bc983376e153389e25
|
|
BLAKE2b-256 checksum How to use checksums |
efdbfc357cce16433f7a4a56121524ace6d90410d399c1bd0d37c651d070e8f7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.12
|
Release files / llmcompressor-0.5.2a20250501-py3-none-any.whl
| Download URL | llmcompressor-0.5.2a20250501-py3-none-any.whl |
|---|---|
| Size | 273.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
96cfa6eb7c1d724fffab46e365795c0f14e0fa1bc25f0cb33ef1232d99a34515
|
|
BLAKE2b-256 checksum How to use checksums |
53a5976286d6c6f3e23f6f32bcd99f7aee421db473734a1db3a66b8792b86f1e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.12
|














