




Latest News 🎉
2026
- [2026/08] Our paper, “LMDeploy Accelerates Mixed-Precision LLM Inference with TurboMind,” has been accepted to EuroSys 2027.
- [2026/04] PyPI has expanded the storage quota for LMDeploy and wheel uploads have resumed.
v0.12.3is now available on PyPI, so you can install it directly viapip install lmdeploy. - [2026/02] Support Qwen3.5
- [2026/02] Support vllm-project/llm-compressor 4bit symmetric/asymmetric quantization. Refer here for a detailed guide
2025
- [2025/09] TurboMind supports MXFP4 on NVIDIA GPUs starting from V100, achieving 1.5x the performance of vLLM on H800 for openai gpt-oss models!
- [2025/06] Comprehensive inference optimization for FP8 MoE Models
- [2025/06] DeepSeek PD Disaggregation deployment is now supported through integration with DLSlime and Mooncake. Huge thanks to both teams!
- [2025/04] Enhance DeepSeek inference performance by integrating deepseek-ai techniques: FlashMLA, DeepGemm, DeepEP, MicroBatch and eplb
- [2025/01] Support DeepSeek V3 and R1
2024
- [2024/11] Support Mono-InternVL with PyTorch engine
- [2024/10] PyTorchEngine supports graph mode on ascend platform, doubling the inference speed
- [2024/09] LMDeploy PyTorchEngine adds support for Huawei Ascend. See supported models here
- [2024/09] LMDeploy PyTorchEngine achieves 1.3x faster on Llama3-8B inference by introducing CUDA graph
- [2024/08] LMDeploy is integrated into modelscope/swift as the default accelerator for VLMs inference
- [2024/07] Support Llama3.1 8B, 70B and its TOOLS CALLING
- [2024/07] Support InternVL2 full-series models, InternLM-XComposer2.5 and function call of InternLM2.5
- [2024/06] PyTorch engine support DeepSeek-V2 and several VLMs, such as CogVLM2, Mini-InternVL, LlaVA-Next
- [2024/05] Balance vision model when deploying VLMs with multiple GPUs
- [2024/05] Support 4-bit weight-only quantization and inference on VLMs, such as InternVL v1.5, LLaVa, InternLMXComposer2
- [2024/04] Support Llama3 and more VLMs, such as InternVL v1.1, v1.2, MiniGemini, InternLMXComposer2.
- [2024/04] TurboMind adds online int8/int4 KV cache quantization and inference for all supported devices. Refer here for detailed guide
- [2024/04] TurboMind latest upgrade boosts GQA, rocketing the internlm2-20b model inference to 16+ RPS, about 1.8x faster than vLLM.
- [2024/04] Support Qwen1.5-MOE and dbrx.
- [2024/03] Support DeepSeek-VL offline inference pipeline and serving.
- [2024/03] Support VLM offline inference pipeline and serving.
- [2024/02] Support Qwen 1.5, Gemma, Mistral, Mixtral, Deepseek-MOE and so on.
- [2024/01] OpenAOE seamless integration with LMDeploy Serving Service.
- [2024/01] Support for multi-model, multi-machine, multi-card inference services. For usage instructions, please refer to here
- [2024/01] Support PyTorch inference engine, developed entirely in Python, helping to lower the barriers for developers and enable rapid experimentation with new features and technologies.
2023
- [2023/12] Turbomind supports multimodal input.
- [2023/11] Turbomind supports loading hf model directly. Click here for details.
- [2023/11] TurboMind major upgrades, including: Paged Attention, faster attention kernels without sequence length limitation, 2x faster KV8 kernels, Split-K decoding (Flash Decoding), and W4A16 inference for sm_75
- [2023/09] TurboMind supports Qwen-14B
- [2023/09] TurboMind supports InternLM-20B
- [2023/09] TurboMind supports all features of Code Llama: code completion, infilling, chat / instruct, and python specialist. Click here for deployment guide
- [2023/09] TurboMind supports Baichuan2-7B
- [2023/08] TurboMind supports flash-attention2.
- [2023/08] TurboMind supports Qwen-7B, dynamic NTK-RoPE scaling and dynamic logN scaling
- [2023/08] TurboMind supports Windows (tp=1)
- [2023/08] TurboMind supports 4-bit inference, 2.4x faster than FP16, the fastest open-source implementation. Check this guide for detailed info
- [2023/08] LMDeploy has launched on the HuggingFace Hub, providing ready-to-use 4-bit models.
- [2023/08] LMDeploy supports 4-bit quantization using the AWQ algorithm.
- [2023/07] TurboMind supports Llama-2 70B with GQA.
- [2023/07] TurboMind supports Llama-2 7B/13B.
- [2023/07] TurboMind supports tensor-parallel inference of InternLM.
Introduction
LMDeploy is a toolkit for compressing, deploying, and serving LLM, developed by the MMRazor and MMDeploy teams. It has the following core features:
-
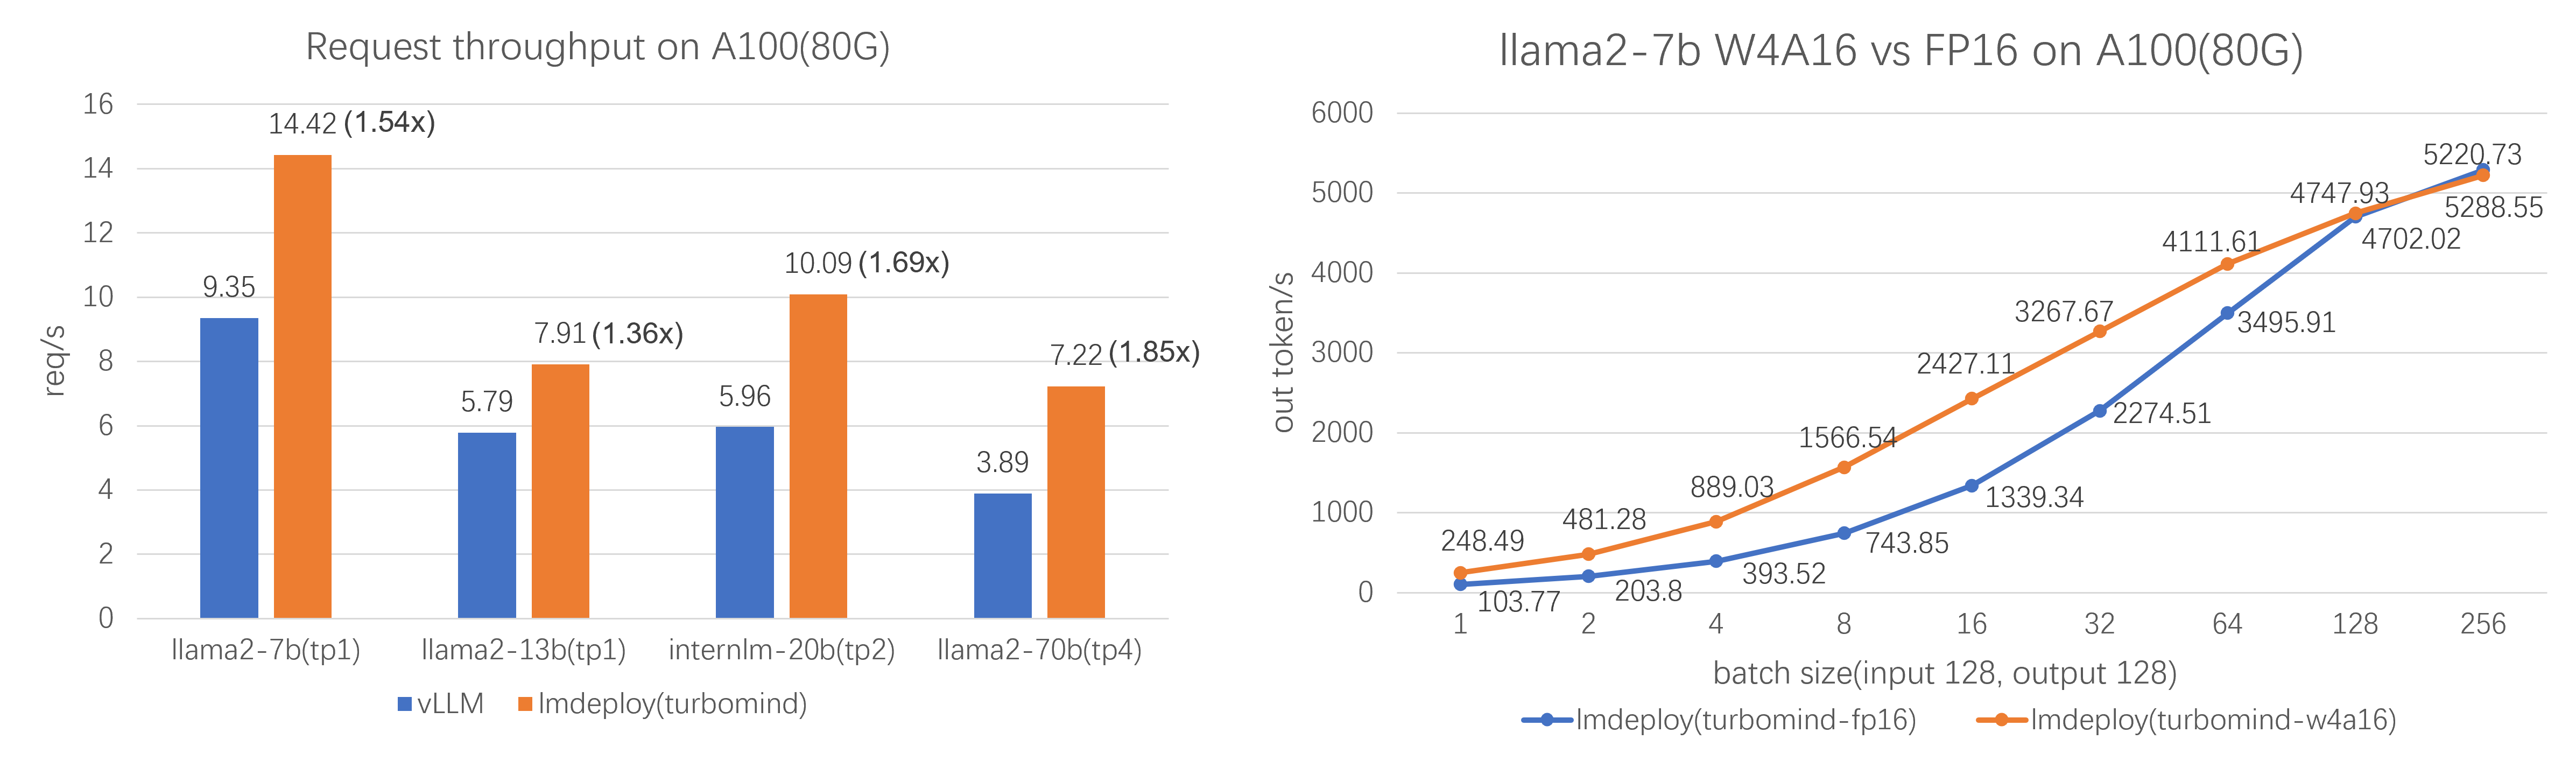
Efficient Inference: LMDeploy delivers up to 1.8x higher request throughput than vLLM, by introducing key features like persistent batch(a.k.a. continuous batching), blocked KV cache, dynamic split&fuse, tensor parallelism, high-performance CUDA kernels and so on.
-
Effective Quantization: LMDeploy supports weight-only and k/v quantization, and the 4-bit inference performance is 2.4x higher than FP16. The quantization quality has been confirmed via OpenCompass evaluation.
-
Effortless Distribution Server: Leveraging the request distribution service, LMDeploy facilitates an easy and efficient deployment of multi-model services across multiple machines and cards.
-
Excellent Compatibility: LMDeploy supports KV Cache Quant, AWQ and Automatic Prefix Caching to be used simultaneously.
Performance
Supported Models
| LLMs | VLMs |
|
|
LMDeploy has developed two inference engines - TurboMind and PyTorch, each with a different focus. The former strives for ultimate optimization of inference performance, while the latter, developed purely in Python, aims to decrease the barriers for developers.
They differ in the types of supported models and the inference data type. Please refer to this table for each engine's capability and choose the proper one that best fits your actual needs.
Quick Start 
Installation
It is recommended to install lmdeploy using pip in a conda environment (python 3.10 - 3.13):
conda create -n lmdeploy python=3.12 -y
conda activate lmdeploy
pip install lmdeploy
Starting from v0.13.0, the default prebuilt wheels published on PyPI are built against CUDA 12.8, so pip install lmdeploy is sufficient for typical setups including GeForce RTX 50 series.
Offline Batch Inference
import lmdeploy
with lmdeploy.pipeline("internlm/internlm3-8b-instruct") as pipe:
    response = pipe(["Hi, pls intro yourself", "Shanghai is"])
    print(response)
[!NOTE] By default, LMDeploy downloads model from HuggingFace. If you would like to use models from ModelScope, please install ModelScope by
pip install modelscopeand set the environment variable:
export LMDEPLOY_USE_MODELSCOPE=TrueIf you would like to use models from openMind Hub, please install openMind Hub by
pip install openmind_huband set the environment variable:
export LMDEPLOY_USE_OPENMIND_HUB=True
For more information about inference pipeline, please refer to here.
Tutorials
Please review getting_started section for the basic usage of LMDeploy.
For detailed user guides and advanced guides, please refer to our tutorials:
- User Guide
- Advanced Guide
Third-party projects
-
Deploying LLMs offline on the NVIDIA Jetson platform by LMDeploy: LMDeploy-Jetson
-
Example project for deploying LLMs using LMDeploy and BentoML: BentoLMDeploy
Contributing
We appreciate all contributions to LMDeploy. Please refer to CONTRIBUTING.md for the contributing guideline.
Acknowledgement
Citation
@misc{2023lmdeploy,
    title={LMDeploy: A Toolkit for Compressing, Deploying, and Serving LLM},
    author={LMDeploy Contributors},
    howpublished = {\url{https://github.com/InternLM/lmdeploy}},
    year={2023}
}
@article{zhang2025lmdeploy,
  title={LMDeploy Accelerates Mixed-Precision LLM Inference with TurboMind},
  author={Zhang, Li and Jiang, Youhe and He, Guoliang and Chen, Xin and Lv, Han and Yao, Qian and Ma, Ningsheng and Fu, Fangcheng and Chen, Kai},
  journal={arXiv preprint arXiv:2508.15601},
  year={2025}
}
License
This project is released under the Apache 2.0 license.
1 maintainer

Release files for lmdeploy 0.17.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distributions (wheels)
Total release size: 820.0 MB
Release files / lmdeploy-0.17.0-cp314-cp314-win_amd64.whl
| Download URL | lmdeploy-0.17.0-cp314-cp314-win_amd64.whl |
|---|---|
| Size | 59.4 MB |
| Tags | CPython 3.14 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
d412b614c1d80f3b9bf389fc69c9f72c71f00edd6729661566f099da58b18eda
|
|
BLAKE2b-256 checksum How to use checksums |
35fb7606d25da4efc81139796358f1f21f16766ea23a02c574f115236bc0a32a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp314-cp314-manylinux_2_28_x86_64.whl
| Download URL | lmdeploy-0.17.0-cp314-cp314-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 104.9 MB |
| Tags | CPython 3.14 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
9043c9eb6dde64cfaa02bcba233f9598e2136b607da5e4774edb09972c3f17b1
|
|
BLAKE2b-256 checksum How to use checksums |
ea91e75ebedf86d630c18e79f49a8422f98f57f3f1e921f36bbb12cfa2e85798
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp313-cp313-win_amd64.whl
| Download URL | lmdeploy-0.17.0-cp313-cp313-win_amd64.whl |
|---|---|
| Size | 59.0 MB |
| Tags | CPython 3.13 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
e4e2d37825bf804c84c29ae1077039abfcc3aed644edb96f1481908583e19af9
|
|
BLAKE2b-256 checksum How to use checksums |
7e293b83bbf5119982a3701532efa00841a1507728faabe1a02617c9f04b1f68
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp313-cp313-manylinux_2_28_x86_64.whl
| Download URL | lmdeploy-0.17.0-cp313-cp313-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 104.9 MB |
| Tags | CPython 3.13 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
7d7b5ce26b652958464c7ee4da16b7b239b90ea8e0f8487abf5c1d6ac75c82cf
|
|
BLAKE2b-256 checksum How to use checksums |
ea25d94a093f7da8f45a1f9aad813e1fb25317db651b4d071929c0991505ac04
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp312-cp312-win_amd64.whl
| Download URL | lmdeploy-0.17.0-cp312-cp312-win_amd64.whl |
|---|---|
| Size | 59.0 MB |
| Tags | CPython 3.12 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
36f19250f273f0a07e1a67ebf8f16342bd47ffcedd261a40d667134ef1b8de95
|
|
BLAKE2b-256 checksum How to use checksums |
aeb4bd8bf041c8fd810ef031c35db8b8d06e9c6294ca4b6144fc4c316a264226
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp312-cp312-manylinux_2_28_x86_64.whl
| Download URL | lmdeploy-0.17.0-cp312-cp312-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 104.9 MB |
| Tags | CPython 3.12 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
291a49d00093a369e2eed54a4718358e533fb845f24e744f4e9c2b6c33fddc14
|
|
BLAKE2b-256 checksum How to use checksums |
b11568bba24034713c11b5bd683c0df8f428f30b017d7349f169806dd5d5e516
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp311-cp311-win_amd64.whl
| Download URL | lmdeploy-0.17.0-cp311-cp311-win_amd64.whl |
|---|---|
| Size | 59.0 MB |
| Tags | CPython 3.11 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
b9499fc21085f817ecf6926147997dc1440c188dcabac753a59990d6d71ed970
|
|
BLAKE2b-256 checksum How to use checksums |
b0375ae6ba915741ddaf39f102865148c0fec38909972131482c90b1078ea781
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp311-cp311-manylinux_2_28_x86_64.whl
| Download URL | lmdeploy-0.17.0-cp311-cp311-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 104.9 MB |
| Tags | CPython 3.11 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
a0eee34fa07f52573f6e253419943dd76b77053326113d915099c856f4569a8f
|
|
BLAKE2b-256 checksum How to use checksums |
2077f99118f3596d5ef0c24e20e4308021684ec45eab3492ac2993a2608a2472
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp310-cp310-win_amd64.whl
| Download URL | lmdeploy-0.17.0-cp310-cp310-win_amd64.whl |
|---|---|
| Size | 59.0 MB |
| Tags | CPython 3.10 Windows x86-64 |
|
SHA-256 checksum How to use checksums |
70b3eb3b847773f54df39c0382b3bb03e686c414b4f6ab372294b0625212aec6
|
|
BLAKE2b-256 checksum How to use checksums |
8ffff5512acc5b6e119c2e320de5189e988b6603fcbff125a27b320fb08cf3e0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|
Release files / lmdeploy-0.17.0-cp310-cp310-manylinux_2_28_x86_64.whl
| Download URL | lmdeploy-0.17.0-cp310-cp310-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 104.9 MB |
| Tags | CPython 3.10 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
0f1ee9c7cf4f94c769854ae24c335be44cfa83946551a58add3583e5962c486c
|
|
BLAKE2b-256 checksum How to use checksums |
5b3849ed9eb30d0f53586f804408ba0ab62ab6d8d5ed75c9f6c39b5392caa82a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.21
|














